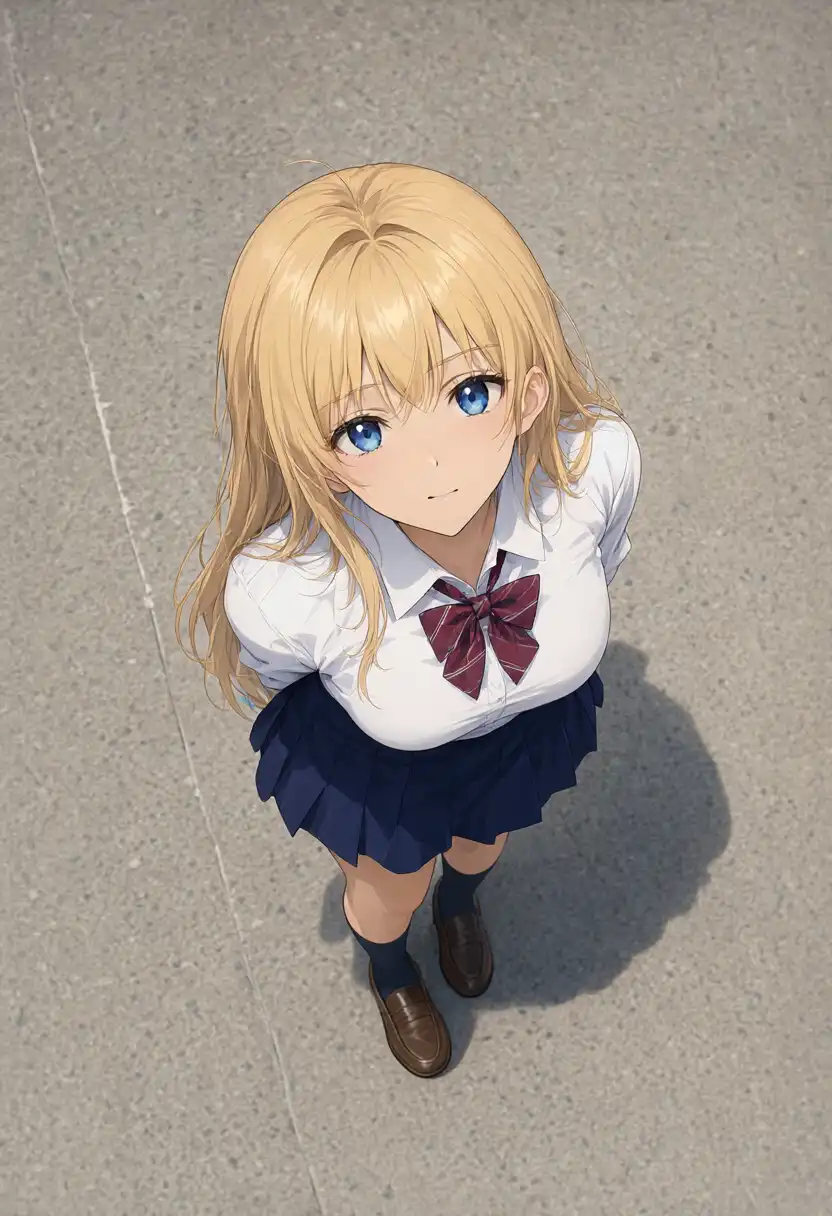
Tested Qwen-Image 2.1 open weights on M1 Max 64GB: overhead shots work locally, ~10 min per 832×1216 image (2x+ Anima), and i2i kept the face. Same prompts as my Anima/WAI tests.
A 100-yen junk ACS ACR1251U-M3 from Akihabara showed up in Windows 11 but refused to detect cards. Step-by-step troubleshooting from drivers and registry to firmware patching and updating a Santek EZ Sign.
Step-by-step physical assembly guide for transplanting an M5Stack CoreS3 into the official StackChan Body. Detaching DIN Base, 4-pin wiring, and initial boot test.
Hands-on evaluation of Qwen-Image 2.1 early access on ModelScope Studio. Testing 10 camera composition presets, 4-member band role assignments, I2I orientation and outfit changes, and where multi-character consistency breaks down.
Tested on an RTX 3050 Ti Laptop: Qwen3.8-Omni-Flash handles audio input directly, shrinking our voice chat server RSS from 1,327MB to 118MB with zero idle warmup lag.
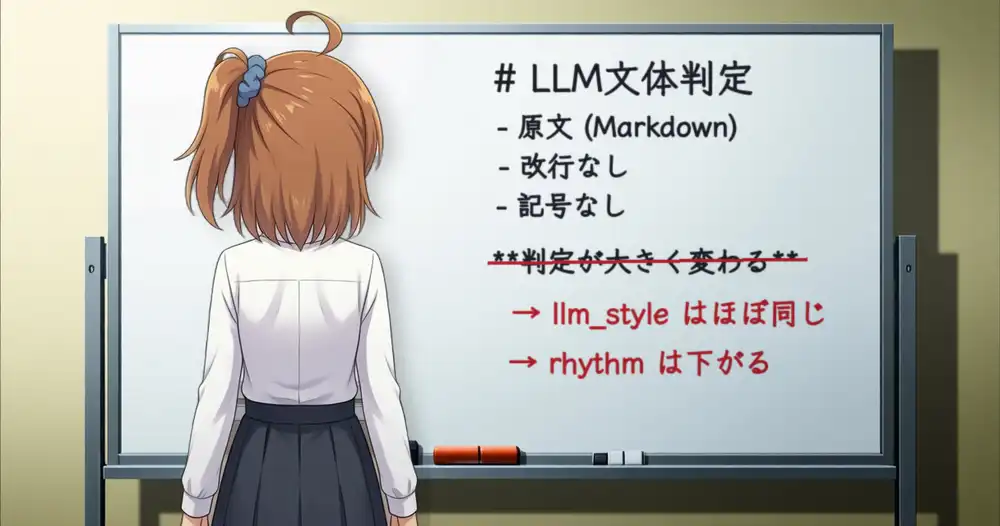
We tested TypeSafe AI's Jev across raw Markdown, stripped newlines, and plain text to examine whether LLM style scores shift. Even across multi-model rubrics from Claude, Gemini, and Qwen, the gap remained remarkably consistent.
Parsed Codex CLI and Claude Code session logs on an M4 Mac mini to track subagent state, time, and tokens. In a 6.5-hour session, the parent waited 68% of the time on children; across 30 days, Codex subagents spent only 5% of active time on tools and 95% waiting on model responses.
Tested with 16 memories and 10 questions: a date bonus on cosine got the 9/9 memory and a 0.441 café-au-lait memory over the 0.45 cutoff, with 0.016 headroom left on hit-free questions.
Ryzen 7 5800HS test before StackChan: subject-less memories got claimed by the character, a 0.45 cosine threshold flipped on a comma, and ModelScope's embedding API vanished mid-test.
Qwen3-Embedding-0.6B on CPU vs ModelScope's API on a Ryzen 7 5800HS voice server. Local embedding adds up to +2.6s per voice turn by competing for CPU; the API adds none.
Tested Qwen3-Embedding-0.6B on CPU and Qdrant's local mode, then checked the 1.5-1.7GB RAM footprint against a Ryzen 7 5800HS voice server with only 4GB VRAM.
Tested on M1 Max 64GB with plain Anima-Base v1.0. A red-to-blue residual direction added to one of Blocks 24-27 flips a flat image, but on a hair mask it paints a blue slab. No hair-only direction found.