Tested on M4 Mac mini: Gemini 4 Argon availability in AGY, pricing comparison, and CLI benchmark runs between GPT-6.1 Sol, Claude Opus 5.5, and Gemini 3.8 Flash.
Tested on M1 Max: Diffusers stretches an 832×1216 reference to 832×1248, making figures 2.7% narrower. Setting output_resolution=1006 cut whole-image drift to about 0.1px.
How do 6 open-source Jev clones compare under code inspection? We examine implementations using ModernBERT, Qwen, and diffusion models across state sharing, question isolation, and scoring trade-offs.
Hands-on evaluation of Qwen-Image 2.1 early access on ModelScope Studio. Testing 10 camera composition presets, 4-member band role assignments, I2I orientation and outfit changes, and where multi-character consistency breaks down.
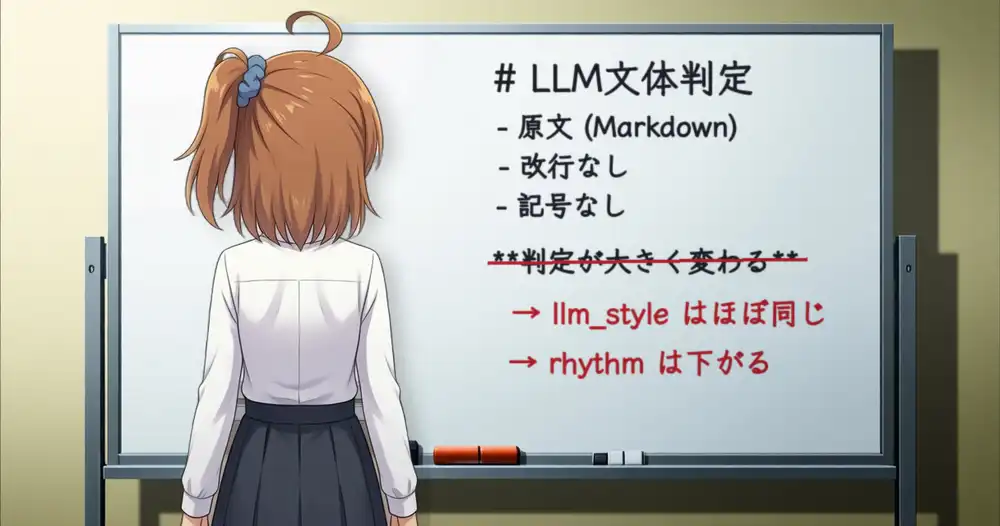
We tested TypeSafe AI's Jev across raw Markdown, stripped newlines, and plain text to examine whether LLM style scores shift. Even across multi-model rubrics from Claude, Gemini, and Qwen, the gap remained remarkably consistent.
Vals AI reported that Claude Fable 5.1 cracked Urquhart's 370-year-old Cyphral Distich. However, primary 1653 texts show the cipher is missing and extraction is impossible.
TypeSafe AI unveiled Jev, a System 1 decision model running single-pass parallel sampling in 70-500ms. $0.042/1M input tokens, free output, and RLCD calibration.
FlyWire's 139,255-neuron Drosophila connectome maps biological wiring into algorithms. Bio-circuits beat LLMs in low-power control, with minimal navis and brian2 code.
MITRE added CWE-1427 for improper neutralization in LLM prompting. Why SQLi-style escaping fails on natural language, and how Dual-LLM and guardrails stop attacks.
OpenAI's Navier–Stokes claim drew questions about credit and whether Buckmaster's Codex prompts influenced it; its September 10 update says prompts in the two months before the September 8 announcement could not affect it.
Tested on M1 Max 64GB with plain Anima-Base v1.0. A red-to-blue residual direction added to one of Blocks 24-27 flips a flat image, but on a hair mask it paints a blue slab. No hair-only direction found.
McCoy, Soulos, Linzen and Smolensky swap every GPT-OSS input-token hidden state for a closed-form tensor product formula; accuracy drops at most 2.36 points and 31 causal interventions average 0.903.