Oxford Internet Institute's Nature 2026 paper found warmth fine-tuning raised error rates 10-30 points when users held wrong beliefs. Shah et al. showed Pearson r = 0.87 between persona agreeableness and sycophancy across 13 open-weight models. Standard benchmarks caught neither effect.
Reading Google's MTP drafter docs, vLLM recipes, and the AI for Developers guide. The 3x claim holds for 31B Dense but 26B A4B MoE stalls at batch 1 because speculative decoding verification loads extra expert weights per candidate token.
Starting from Claude Code's 1.67B token runaway (anthropics/claude-code#4095), this traces why tool responses need is_complete, retryable: false, duplicate detection, and orchestrator-level budget caps. Directly applicable to MCP server design.
Starting from a DEV Community article about taking Synapse mobile with React Native + Expo, this digs into iOS/Android background restrictions, how desktops differ, similar patterns in payments and video uploads, and design options that assume disconnection.
Klein 4B / 9B / Base LoRAs aren't cross-compatible — a 9B NSFW LoRA throws 'lora key not loaded' on mflux's 4B path. The variant map, what mflux runs today, and where the working hands-on test lives.
An arXiv paper reports that fine-tuning GPT-4o, Gemini 2.5 Pro, and DeepSeek-V3.1 on summary-to-text expansion tasks increases verbatim reproduction of copyrighted books.
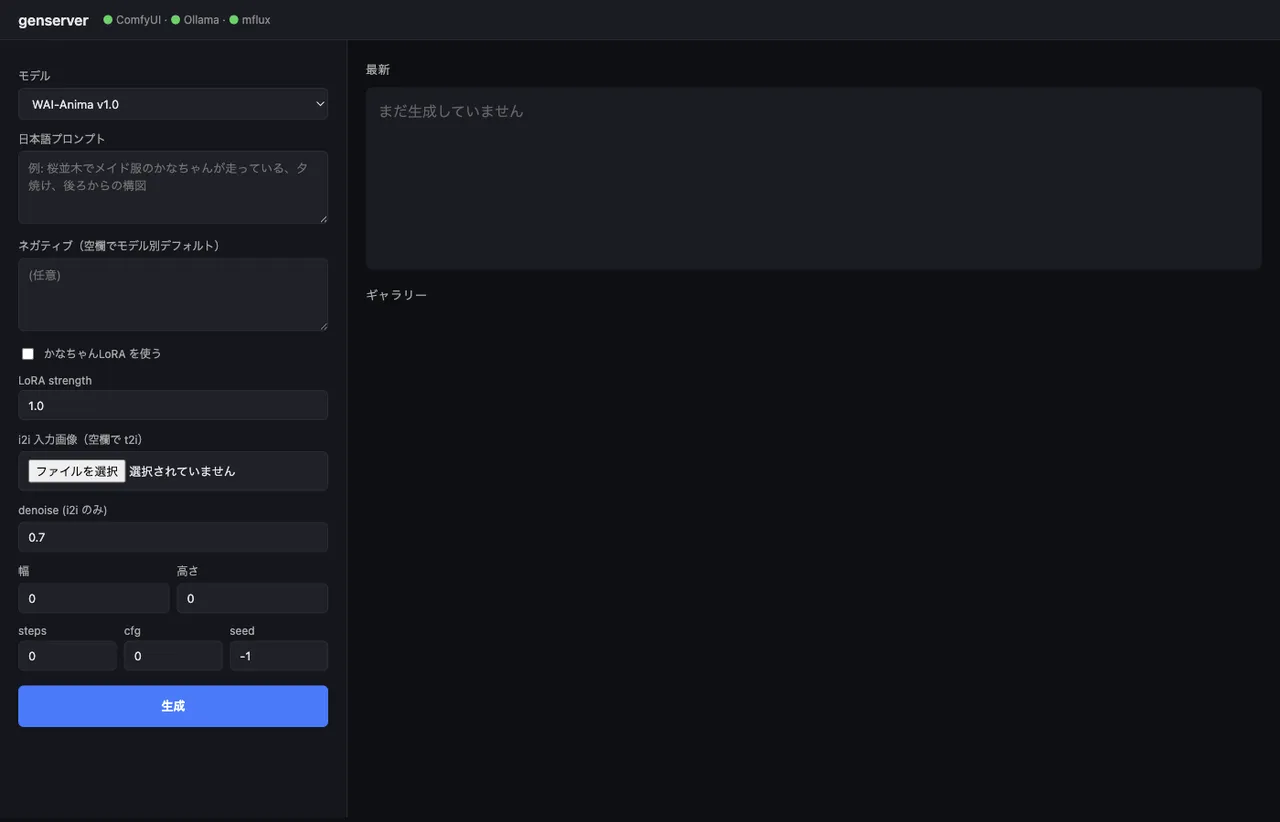
Three local image generation engines (WAI-Anima, WAI-IL/SDXL, FLUX.2 Klein 4B) tied together by a thin FastAPI wrapper that takes Japanese prompts. Ollama (gemma3:12b) handles JP→EN, ComfyUI workflows are built on the fly in Python, FLUX.2 runs as an mflux subprocess, and the whole thing is reachable from an iPhone over Tailscale.
VoteWise AI turns election education into a multilingual chat, voice, and story-mode experience built on Next.js. Notes on designing around Gemini 2.5 Flash's safety filters in a political context.
Hands-on log of building the DEV article's PDF RAG on M1 Max 64GB, extending it with images via CLIP, and pushing through Japanese with bge-m3 + Qwen3.6 35B. Documents the modality gap, the dual inference server crash, and LLM-jp 4-8B's empty chat template silently dropping the system role.
Notes on a DEV Community article that wires up FastAPI as an OpenAI-compatible RAG API layer with llama.cpp, Chroma, and Open WebUI, plus where the architecture fits and what to watch for.