Google's UGC Fresh Data Program allows approved UGC platforms to stream user posts and engagement metrics directly to search via OAuth 2.0 and JSON-LD. Here are the eligibility criteria, timing rules, and differences from the Indexing API.
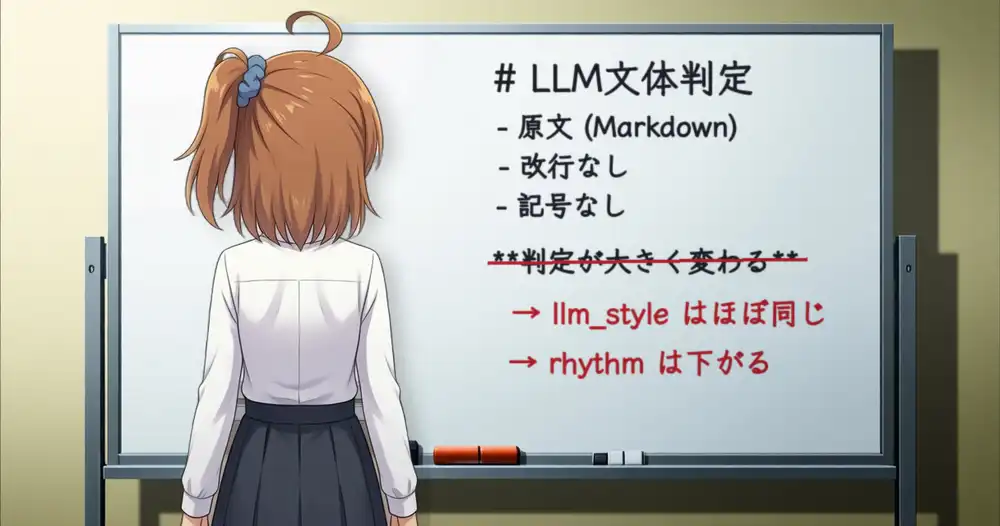
We tested TypeSafe AI's Jev across raw Markdown, stripped newlines, and plain text to examine whether LLM style scores shift. Even across multi-model rubrics from Claude, Gemini, and Qwen, the gap remained remarkably consistent.
TypeSafe AI unveiled Jev, a System 1 decision model running single-pass parallel sampling in 70-500ms. $0.042/1M input tokens, free output, and RLCD calibration.
Tested with 16 memories and 10 questions: a date bonus on cosine got the 9/9 memory and a 0.441 café-au-lait memory over the 0.45 cutoff, with 0.016 headroom left on hit-free questions.
Ryzen 7 5800HS test before StackChan: subject-less memories got claimed by the character, a 0.45 cosine threshold flipped on a comma, and ModelScope's embedding API vanished mid-test.
Qwen3-Embedding-0.6B on CPU vs ModelScope's API on a Ryzen 7 5800HS voice server. Local embedding adds up to +2.6s per voice turn by competing for CPU; the API adds none.
My ModelScope account switched from a monthly API-Inference quota to Magicube coins, so I measured what each call costs. Qwen-Image, Z-Image, Krea-2-Turbo and FLUX worked even though none of them appeared in the /v1/models list I got; of the embedding IDs I tried only Qwen3-Embedding went through; audio paths were 404 and Wan produced no video. In these tests 400s and 404s cost nothing, while a 200 with an empty body was charged.
Tested Qwen3.7/3.8 web search via the OpenAI SDK: enable_search returns no URLs, Responses API web_search does, and reasoning_tokens jump 10x on search turns.
One Application Password per integration, CORS is not authorization, rate limits before PHP: how to harden /wp-json/ for headless and AI-era WordPress.
RFC 10008 makes QUERY a safe, idempotent HTTP method with a body. What it fixes over POST /search, how cache keys work, plus fetch, PHP, and Node.js handlers.
Tested Qwen3.7 Max and Plus proofreading a Japanese novel: both barely fix, split on quote punctuation and names, and the one 'typo' was a character name.