Tested Qwen3-Embedding and Qdrant memory on a StackChan voice chat server. Ramen and guitar were recalled, but weekend plans hovered right at the 0.45 threshold.
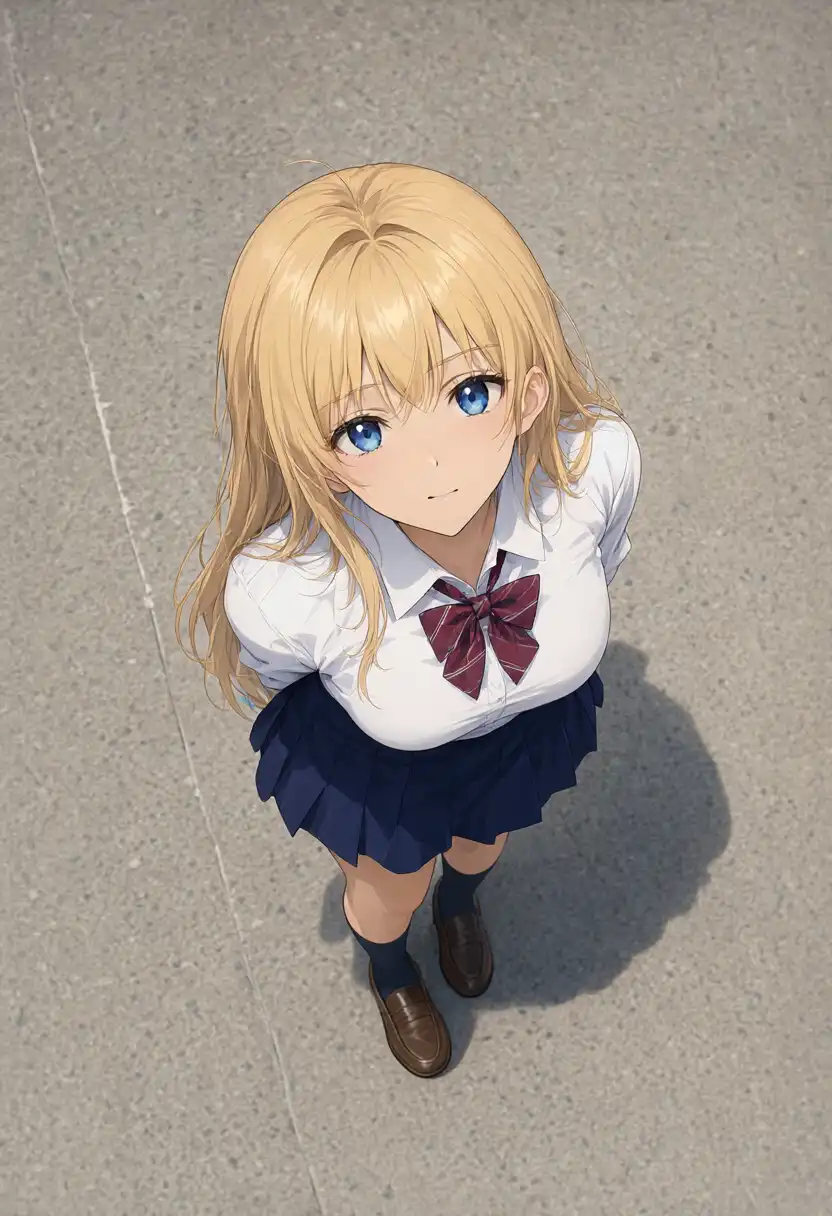
Tested Qwen-Image 2.1 open weights on M1 Max 64GB: overhead shots work locally, ~10 min per 832×1216 image (2x+ Anima), and i2i kept the face. Same prompts as my Anima/WAI tests.
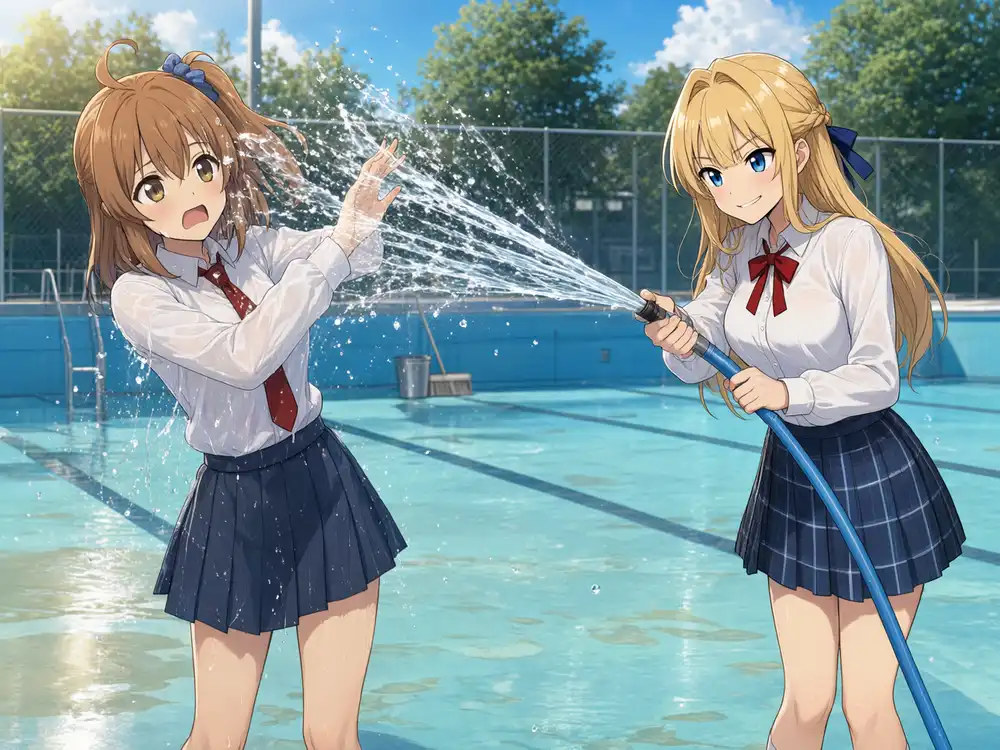
Hands-on evaluation of Qwen-Image 2.1 early access on ModelScope Studio. Testing 10 camera composition presets, 4-member band role assignments, I2I orientation and outfit changes, and where multi-character consistency breaks down.
Tested on an RTX 3050 Ti Laptop: Qwen3.8-Omni-Flash handles audio input directly, shrinking our voice chat server RSS from 1,327MB to 118MB with zero idle warmup lag.
Tested with 16 memories and 10 questions: a date bonus on cosine got the 9/9 memory and a 0.441 café-au-lait memory over the 0.45 cutoff, with 0.016 headroom left on hit-free questions.
Ryzen 7 5800HS test before StackChan: subject-less memories got claimed by the character, a 0.45 cosine threshold flipped on a comma, and ModelScope's embedding API vanished mid-test.
Qwen3-Embedding-0.6B on CPU vs ModelScope's API on a Ryzen 7 5800HS voice server. Local embedding adds up to +2.6s per voice turn by competing for CPU; the API adds none.
My ModelScope account switched from a monthly API-Inference quota to Magicube coins, so I measured what each call costs. Qwen-Image, Z-Image, Krea-2-Turbo and FLUX worked even though none of them appeared in the /v1/models list I got; of the embedding IDs I tried only Qwen3-Embedding went through; audio paths were 404 and Wan produced no video. In these tests 400s and 404s cost nothing, while a 200 with an empty body was charged.