Tested on M4 Mac mini ComfyUI: 8 on/off combos of three actions × 3 seeds on a 4-character Anima LoRA. Roles read at 3/3, but hands and skirts landed on the wrong girl.
Tested on M1 Max 64GB: a 50M resampler predicts Anima's 4-char conditioning from short triggers. Train fits at cos distance 0.005, held-out order breaks; template P3 goes 15/16.
Tested on Anima-Base v1.0: no prompt hit the 512-token cap, cosine similarity moved the wrong way, and only the DiT-side conditioning changed who got drawn.
Tested 11 character combos × 3 seeds on Anima-Base: trigger-only prompts passed 3/33, full prompts 8/11, and copying one training-caption phrase fixed the height gap.
Tested on M1 Max 64GB ComfyUI: v0.24.1 fails to load int8_tensorwise, v0.30.1 hits the missing aten::_int_mm MPS kernel, and a dequantize patch runs slower than bf16.
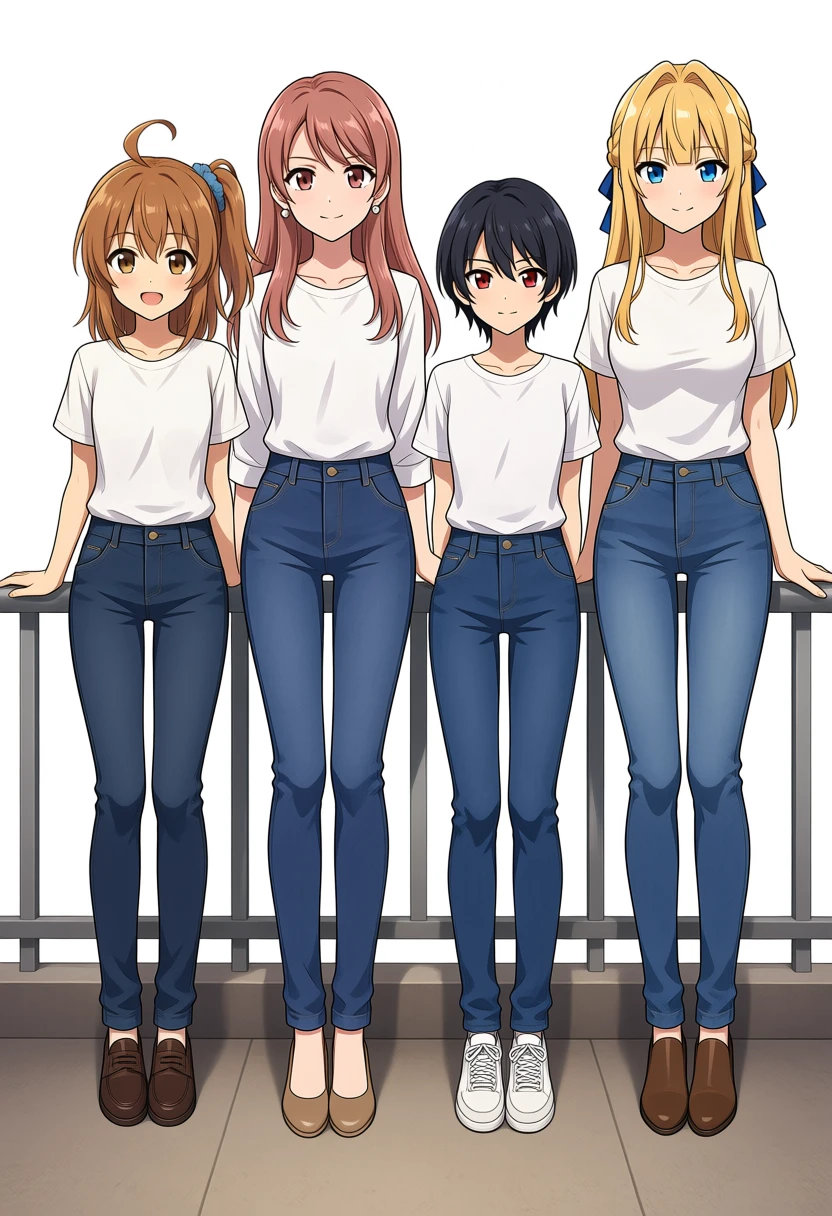
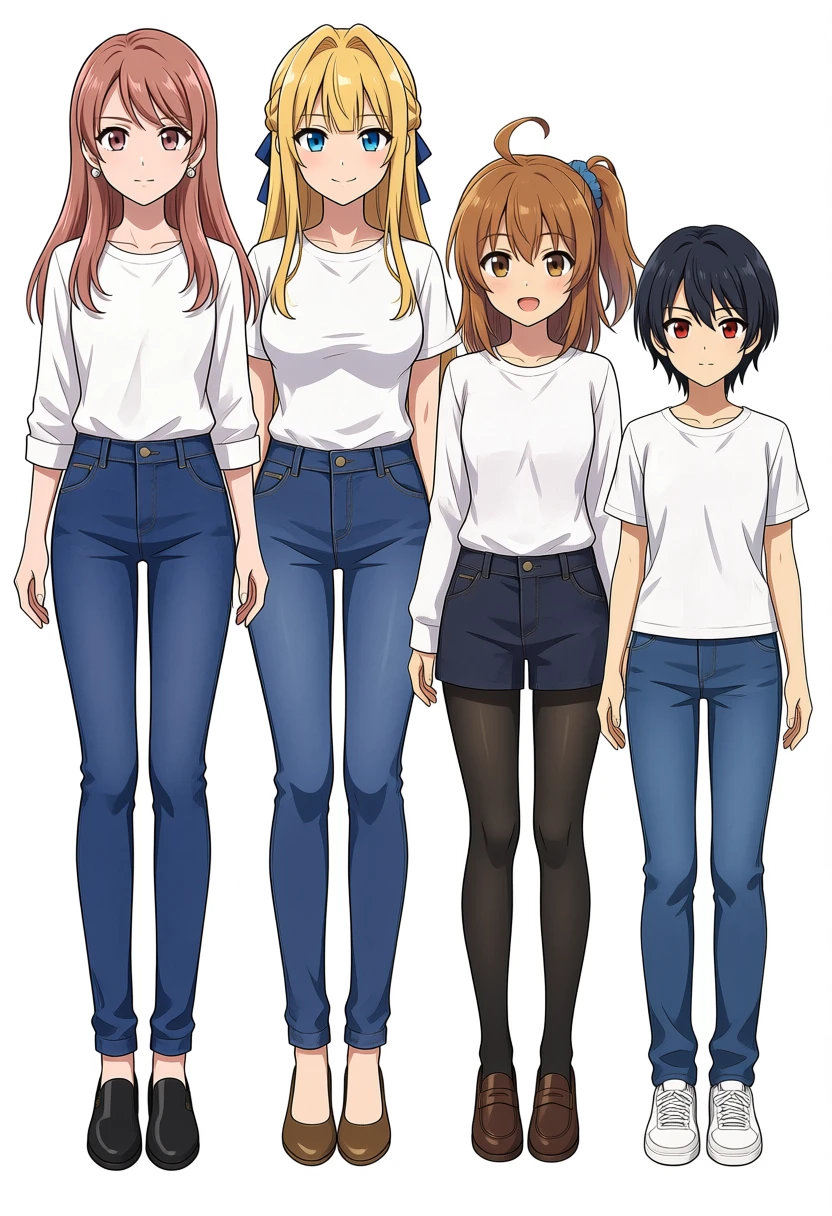
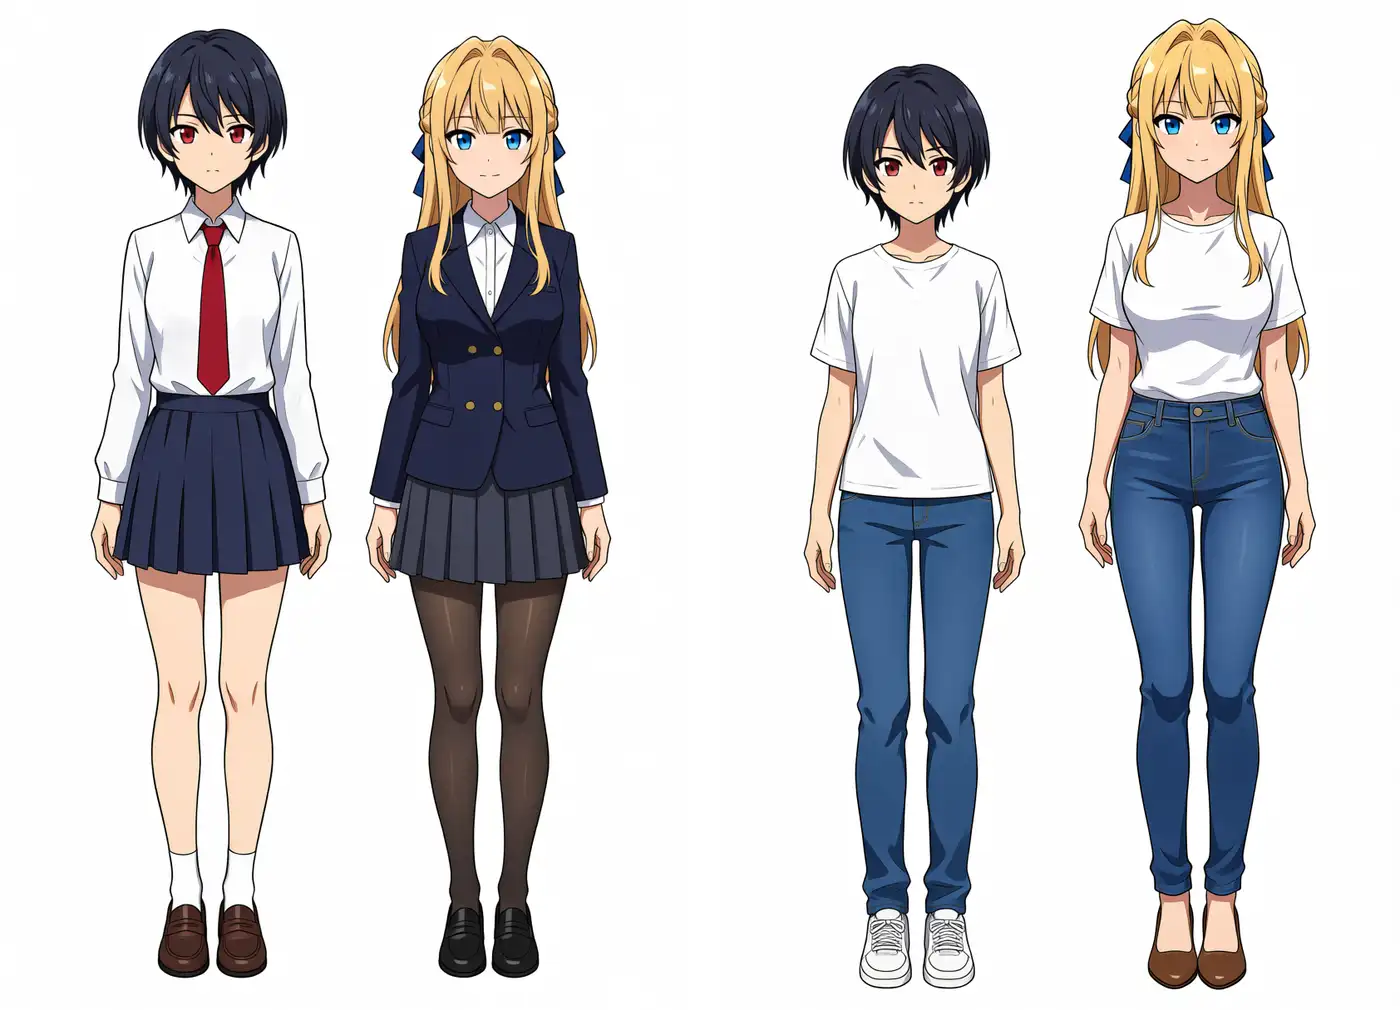
Merged a 4th girl with a makeup toggle into one Anima LoRA (518 images, rank256, 21.5h on RTX 5090). Epoch pick vs design bleed, why makeoff fails in multi-girl prompts, 6/6 one-shot.
Tested over 3 bakes on RunPod RTX 5090: a coined subtractive makeoff tag never fires at cfg 1.0, while additive earrings+makeup tags switch both ways with the face unchanged (ep140).
Measured on M1 Max ComfyUI: QIE 2511's pixel shift comes from the encode node's forced 1MP rescale. Stock ReferenceLatent fixes it; expression, outfit and pose diffs tested.
Three LLMs converted the same 10 Japanese scene briefs into Anima (Qwen-DiT) prompts, generated as 60 fixed-seed images on an M1 Max with a merged 3-character LoRA. The Qwen-to-Qwen affinity hypothesis did not survive; a strict formatter brief with character-count locks is what actually moved the results, and two failure modes survive any prompt.
Merged kei, kana, and koharu into a single Anima (Qwen-DiT) LoRA and ran my first training on Blackwell (RTX 5090, sm_120). Hands-on log: the cu128 / torch2.8 / SDPA stack swap from the 4090, why the weakest character gets absorbed (caption asymmetry, not rank), and how trigger-only prompts separate three close-packed characters at ep143 without ControlNet.
Krea 2 Turbo bf16 renders in ~3.5 min on a Mac (M1 Max 64GB, ComfyUI). fp8 is rejected on MPS, Raw NaNs to black at 47 min, and NSFW behavior gets tested. Working settings and VRAM notes for Apple Silicon.