Running MiniMax-H3-Image GGUF on M1 Max 64GB: 4MP Anime Illustrations in 5 Minutes
 Contents
MiniMax’s text-to-image model MiniMax-H3-Image has 33.1 billion parameters in its image generation core alone.
The official weights are mostly BF16 (with parts like embeddings in FP32) totaling over 66GB, and the text encoder is another 66.7GB, meaning it cannot fit unquantized on a 64GB Mac.
On November 10, community member Abiray published GGUF quantized versions for ComfyUI on Hugging Face. I decided to see if this allows it to run on an M1 Max 64GB.
I also tested the same prompts and source images used in my previous comparison, WAI-Anima v1 vs WAI-Illustrious on M1 Max ComfyUI, to compare the outputs directly against earlier models.
Specifications and Recommended Settings
| Item | Details |
|---|---|
| Model | MiniMax-H3-Image (MiniMax) |
| File Tested | MiniMax-H3-Image-Pruned-Q4_K_M.gguf from Abiray/MiniMax-H3-Image-GGUF |
| GGUF Conversion Source | minimax_h3_image_pruned_bf16.safetensors distributed by Comfy-Org |
| Core Generation Model (DiT) | 33.1B parameters officially. 50 layers, hidden dim 5376, 56 heads |
| Text Encoder | Uses MiniMax-H3’s Qwen3-VL directly, extracting output from the 50th layer |
| VAE | 1/16 spatial scale, 24-channel latent representation. Packed into 2×2, where 1 token corresponds to 32×32 pixels |
| Release | Official repository created November 3, GGUF version on November 10 |
| License | MiniMax-H3-Image Community License. Requires prior permission for commercial revenue over $1,000,000 or third-party hosting services |
The DiT (Diffusion Transformer) is the core architecture that generates images from noise, while the text encoder (Qwen3-VL 32B) interprets the prompt and passes condition embeddings to the DiT.
In the original BF16 format (~2 bytes per parameter), the DiT alone exceeds 66GB and overflows the Mac’s 64GB memory. The community GGUF version quantizes the weights down to ~4-bit precision, shrinking the file size to 11.57GB so it can run locally.
Note that this article involves two distinct Qwen models: Qwen3-VL acting as the text encoder, and Qwen3.5 9B acting as an auxiliary LLM that rewrites user instructions into detailed descriptive captions for image editing.
The recommended settings from the official model card and GGUF documentation are as follows:
| Item | Recommended |
|---|---|
| Steps | 6 (distilled for 6-step sampling) |
| CFG | 1.0 (negative prompt is not used) |
| Sampler / Scheduler | euler / simple or sgm_uniform |
| Resolution | Effective range ~4–20MP, optimal around 16MP (e.g. 4096×4096) |
| Prompting | Comprehensive scene descriptions in English. Short prompts should be rewritten by a prompt expansion LLM before inference |
Distillation trains a model to replicate the quality of multi-step sampling within fewer steps. CFG controls prompt adherence; at 1.0, guidance from negative prompts is completely deactivated.
The “Pruned” label in the GGUF filename originates from Comfy-Org’s release.
Comfy-Org’s BF16 file is 40.2GB, noticeably smaller than the official 66.28GB BF16 release. Checking the tensors in this Q4_K_M GGUF reveals roughly 20.1 billion parameters, sharing the exact same architecture (50 blocks, hidden dim 5376, FFN 14336) as the official model.
Neither Comfy-Org nor Abiray’s README explains what was pruned from the original 33.1B.
M1 Max Test Environment
| Item | Environment Details |
|---|---|
| Hardware | MacBook Pro, Apple M1 Max |
| Memory | 64GB Unified Memory |
| OS | macOS 27.0 |
| ComfyUI | v0.45.2 (installed in an isolated directory separate from daily setups) |
| Python / PyTorch | 3.12 (uv virtualenv) / 2.15.0 with MPS backend |
| ComfyUI-GGUF | Commit 6ea2651 |
| DiT Weight | MiniMax-H3-Image-Pruned-Q4_K_M.gguf (11.57GB) |
| Text Encoder | qwen3vl_32b_minimax_h3-Q4_K_M.gguf (14.58GB, Abiray/MiniMax-H3-GGUF) |
| VAE Weight | minimax_h3_image_vae_fp16.safetensors (1.17GB, Comfy-Org) |
MPS (Metal Performance Shaders) allows PyTorch to utilize Apple Silicon GPU cores.
The GGUF release requires ComfyUI v0.45.0 or higher. Since my existing environments were on v0.30.1 and v0.33.3, I set up v0.45.2 in a dedicated folder.
git clone --depth 1 --branch v0.45.2 https://github.com/comfyanonymous/ComfyUI.git ComfyUI-h3image
cd ComfyUI-h3image
git clone --depth 1 https://github.com/city96/ComfyUI-GGUF.git custom_nodes/ComfyUI-GGUF
uv venv --python 3.12 .venv
uv pip install --python .venv/bin/python -r requirements.txt -r custom_nodes/ComfyUI-GGUF/requirements.txt
Additionally, minimax_h3_image_gguf_fix.py from the GGUF repository was placed into custom_nodes/.
According to its documentation, ComfyUI-GGUF loader does not pass the 6-step sigma schedule (pdd_sigmas) metadata embedded in safetensors. Without this patch, loading fails due to missing pdd_sigmas arguments or latent channel mismatches.
When active, the startup log reports [MiniMax-H3-Image GGUF Fix] Applied 6-step pdd_sigmas & 24-channel latent patch.
The total download for the three core files was approximately 27.3GB. Models were mapped via extra_model_paths.yaml.
The included workflow (image_minimax_h3_image_t2i_gguf.json) includes an optional node setup using Qwen3.5 9B to expand short prompts into detailed English captions. In the JSON, this was set to False by default, so I ran the text-to-image tests without the expansion node.
The workflow was sent via API matching the core node structure:
| Node | Configuration |
|---|---|
| UnetLoaderGGUF | DiT Q4_K_M |
| CLIPLoaderGGUF | Text Encoder Q4_K_M, type minimax |
| MiniMax H3 Image Conditioning | Prompt, width and height (also takes reference images for editing) |
| ConditioningZeroOut | Clears negative conditioning |
| KSampler | euler / simple, 6 steps, CFG 1.0, denoise 1.0 |
Verifying the README Sample
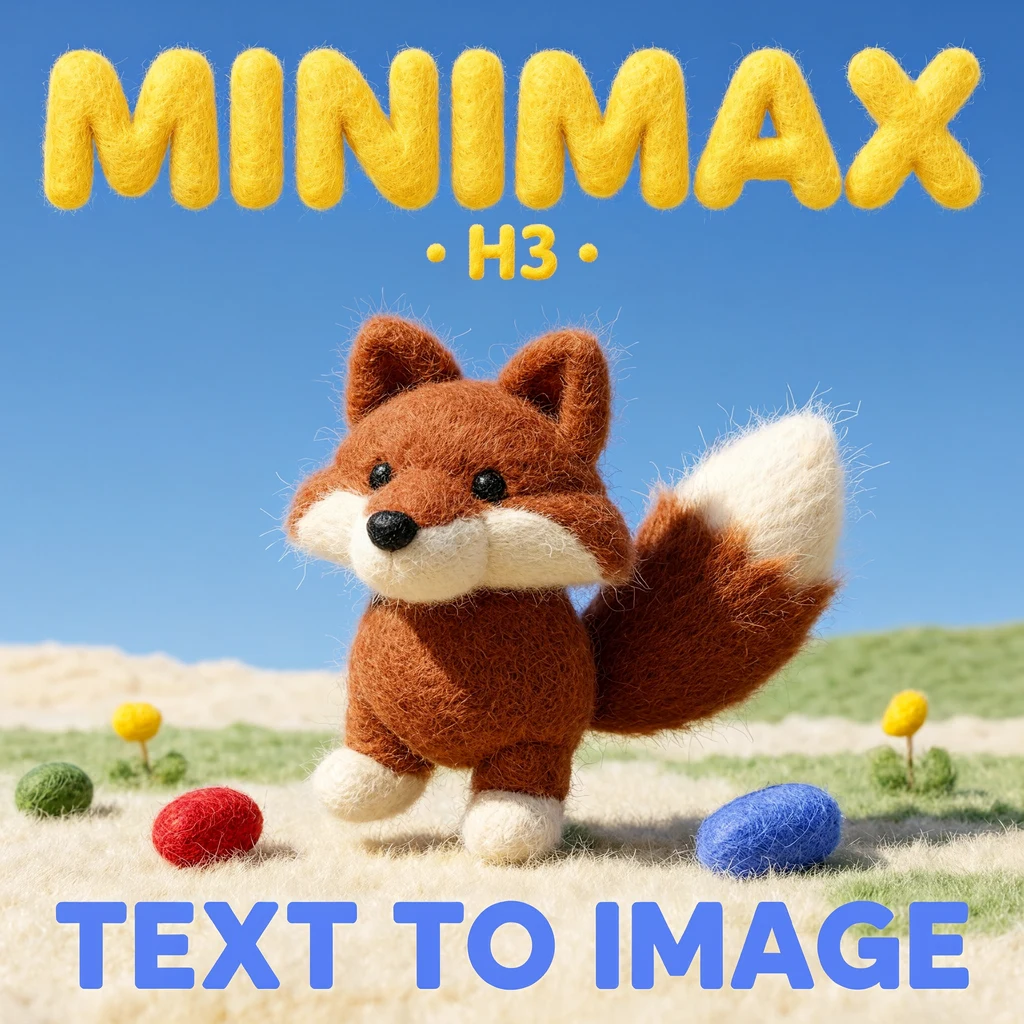
First, I tested the fox plush poster sample prompt from the GGUF README at 2048×2048 with seed 42.
2048×2048 (~4MP) is documented in the ComfyUI nodes as the baseline resolution the model is tuned for, representing the lower boundary of its effective range.
All three text strings (“MINIMAX”, “H3”, “TEXT TO IMAGE”) rendered with exact spelling. The displayed image is scaled down to 1024×1024.
| Metric | Result |
|---|---|
| Total Generation Time (including initial model load) | 339.65s |
| 6-Step Sampling Time | 4m 59s (~49.9s / step) |
| Text Encoder Placement | CPU, FP16, 15,393.81MB |
| DiT Placement | MPS, 11,329.79MB |
Peak ComfyUI Memory Footprint (phys_footprint) | 21.0GB |
| System Swap Usage (Start → End) | 3788.56MB → 3764.56MB |
ComfyUI automatically placed the text encoder on CPU memory.
Memory usage was polled every second using macOS footprint. System swap was around 3.8GB from prior tasks and did not increase during generation.
Japanese Typography Rendering
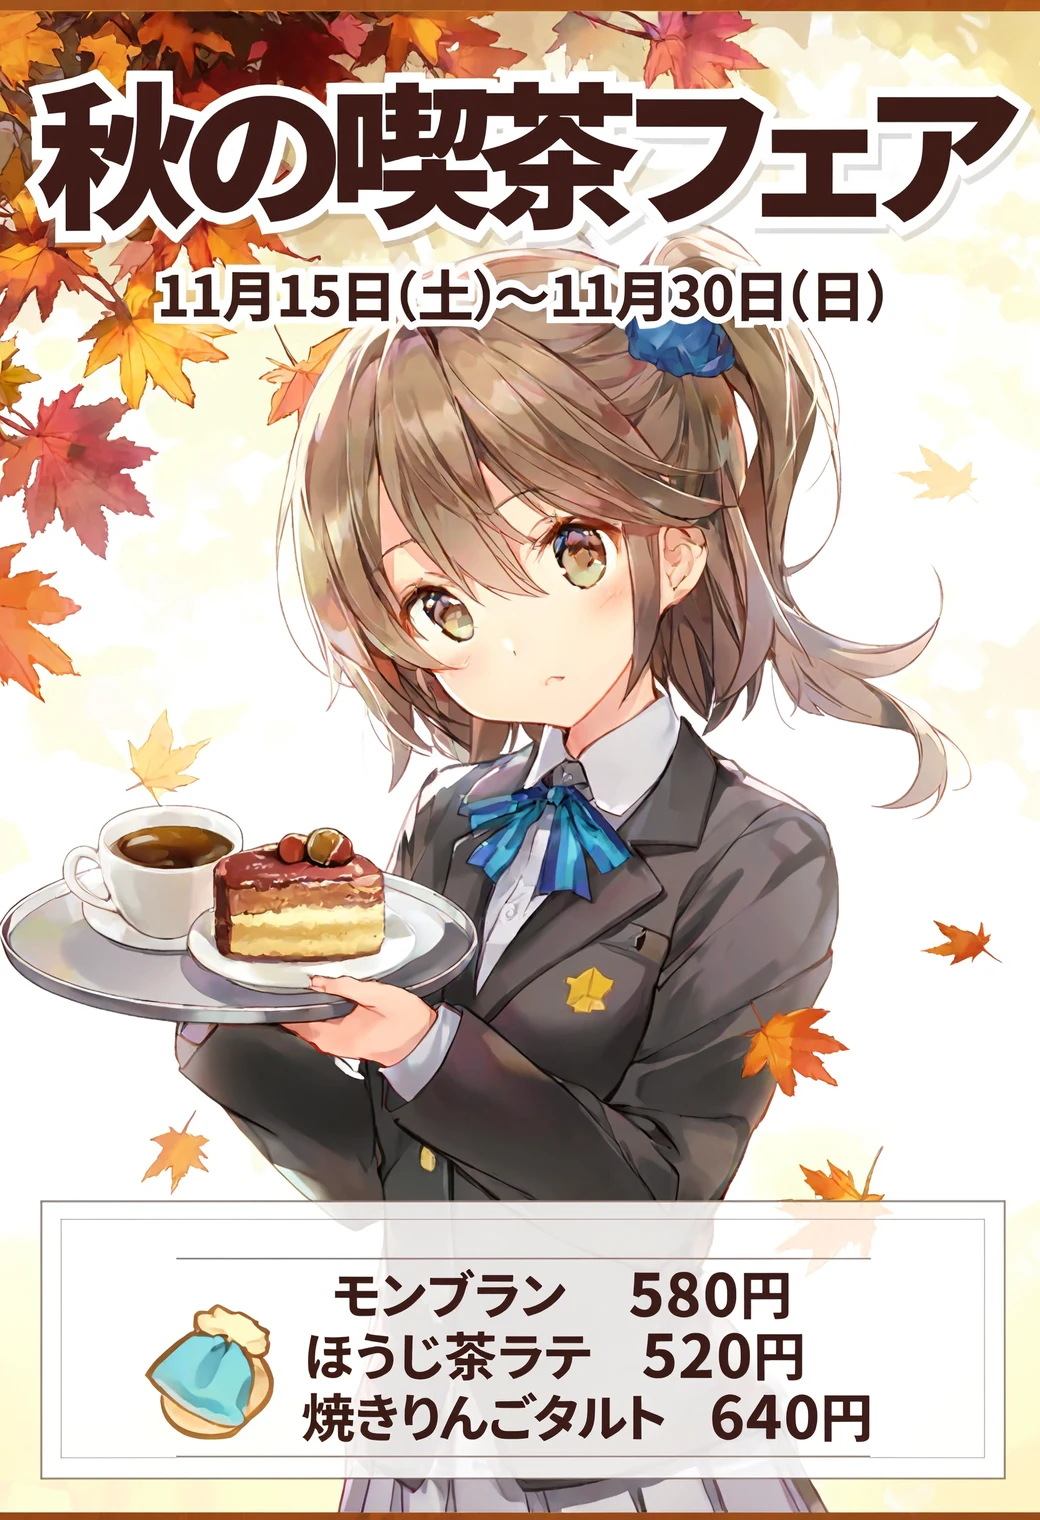
Since the README sample tested English lettering, I tested a vertical poster with Japanese headings, dates, and menu items at 1664×2432 with seed 42. The Japanese text was provided inside quotation marks within the English prompt.
| Specified Text | Result |
|---|---|
| 秋の喫茶フェア | Rendered accurately in bold across the top |
| 11月15日(土)〜11月30日(日) | Rendered accurately, including brackets and wave dash |
| モンブラン 580円 | Rendered accurately |
| ほうじ茶ラテ 520円 | Rendered accurately |
| 焼きりんごタルト 640円 | Rendered accurately |
All five lines rendered Kanji, Hiragana, Katakana, and Arabic numerals without corruption. Complex Kanji characters like “焼” and “喫” remained clear and legible.
An unprompted light-blue pouch motif appeared on the left of the menu box. The girl’s brown side ponytail, blue scrunchie, and uniform were properly drawn. Generation took 307.48s.
Prompt
A vertical anime-style event poster for a small cafe. At the top, large bold Japanese title text reads "秋の喫茶フェア". Below it, a smaller line reads "11月15日(土)〜11月30日(日)". In the center, a girl with brown hair in a side ponytail and a blue scrunchie, wearing a school uniform, holds a tray with a cup of coffee and a slice of chestnut cake. At the bottom, a menu box lists three items in Japanese: "モンブラン 580円", "ほうじ茶ラテ 520円", "焼きりんごタルト 640円". Warm autumn colors with falling maple leaves.Comparison Setup and Generation Parameters
I compared the outputs side by side with the three models tested in my April benchmarks. These past images were kept as-is without regeneration.
Since my custom Kana-chan and Kei-chan character LoRAs were trained for Anima and Illustrious, they cannot be applied to MiniMax-H3-Image. The character LoRA section was replaced with reference image-based character editing.
| Label | Model | Source |
|---|---|---|
| MiniMax-H3-Image | GGUF Q4_K_M | Current test |
| Anima preview3-base | Official Anima | April benchmark |
| WAI-Anima v1 | Anima derivative | April benchmark |
| WAI-Illustrious v160 | Illustrious derivative | April benchmark |
| Parameter | MiniMax-H3-Image | Earlier 3 Models |
|---|---|---|
| Resolution | 1664×2432 (~4.05MP) | 832×1216 (~1MP) |
| Steps / CFG | 6 / 1.0 | Anima series 30 / 4.0, WAI-Illustrious 25 / 5.0 |
| Sampler / Scheduler | euler / simple | Anima series er_sde / simple, WAI-Illustrious euler_ancestral / karras |
| Seed | 42 | 42 |
| Prompt Format | Descriptive English sentences | Danbooru comma-separated tags |
| Negative Prompt | None | None recorded |
Resolution was scaled by 2× in both dimensions compared to the earlier 832×1216, as 832×1216 falls below MiniMax’s effective minimum (~4MP).
Because the text encoder is Qwen3-VL, I converted the Danbooru tags into equivalent English prose, prefixing with An anime illustration. Character, clothing, pose, and background elements were kept identical.
Base Anime Art Style
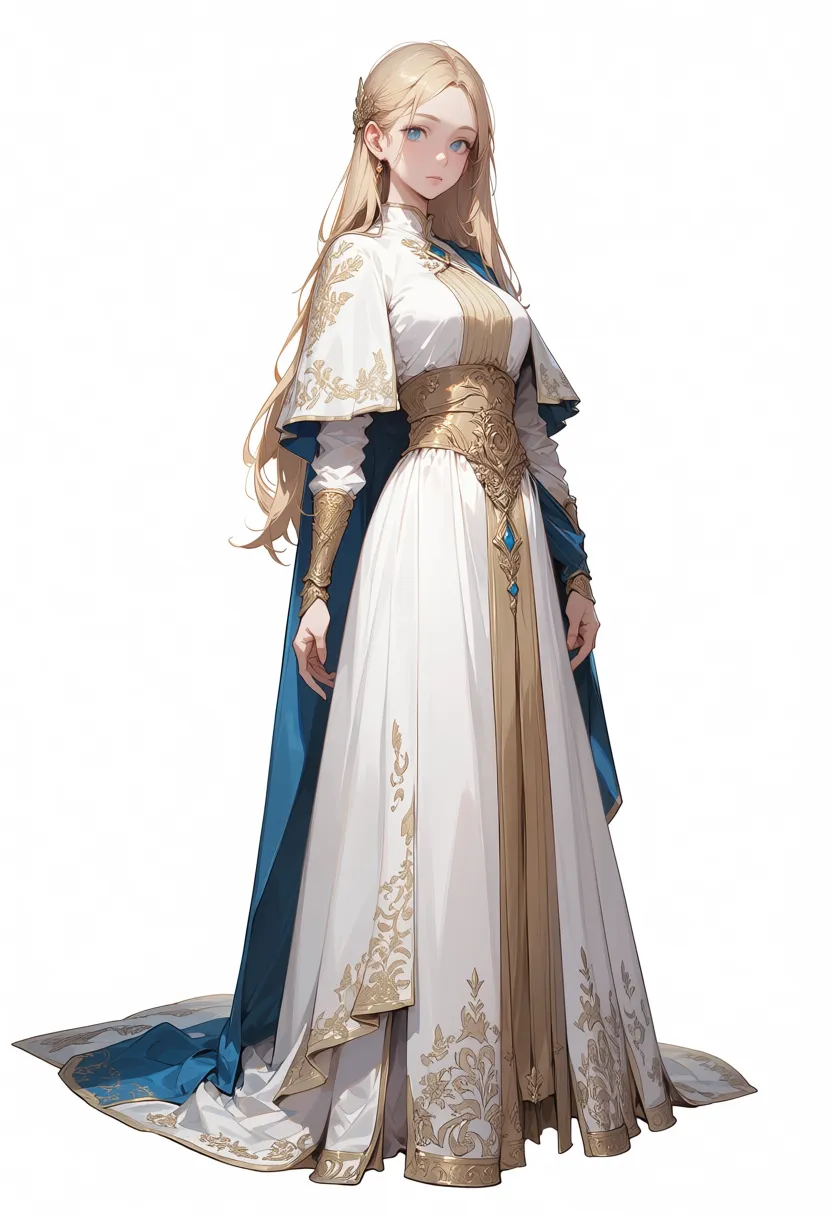
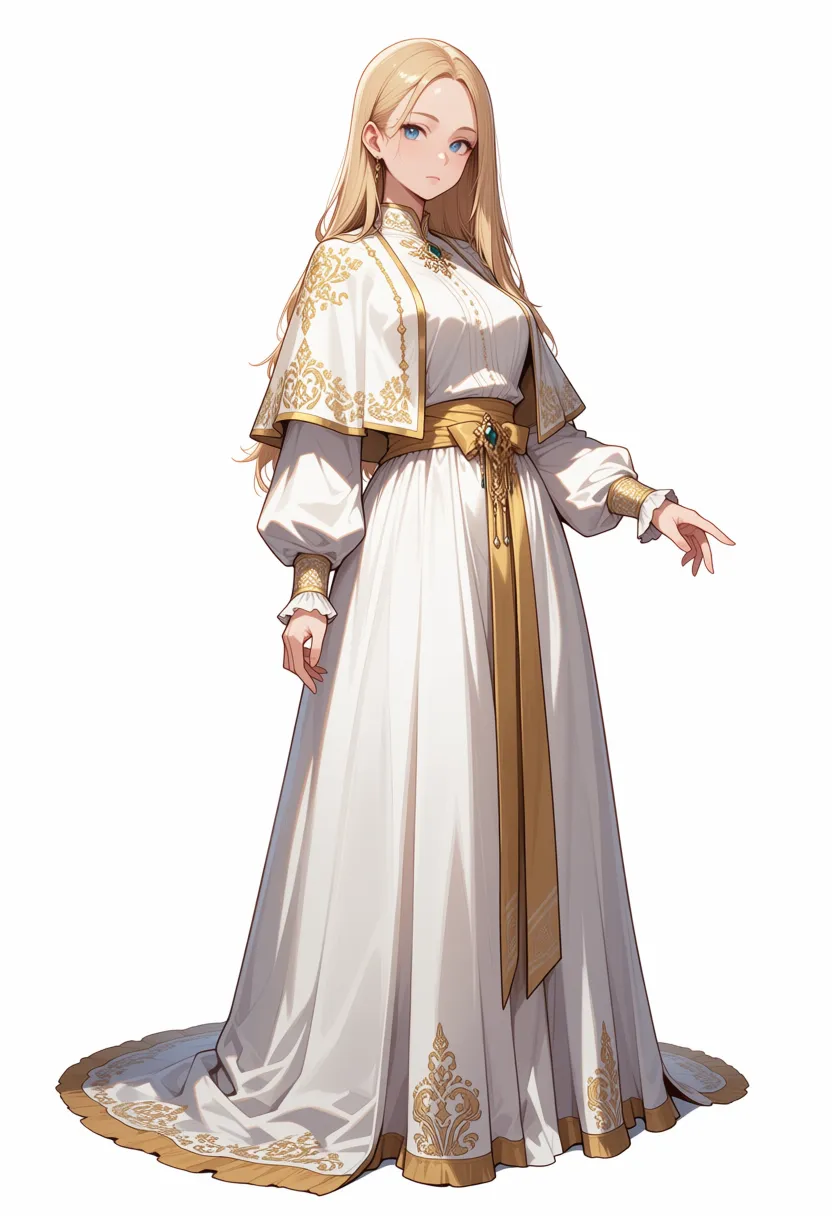
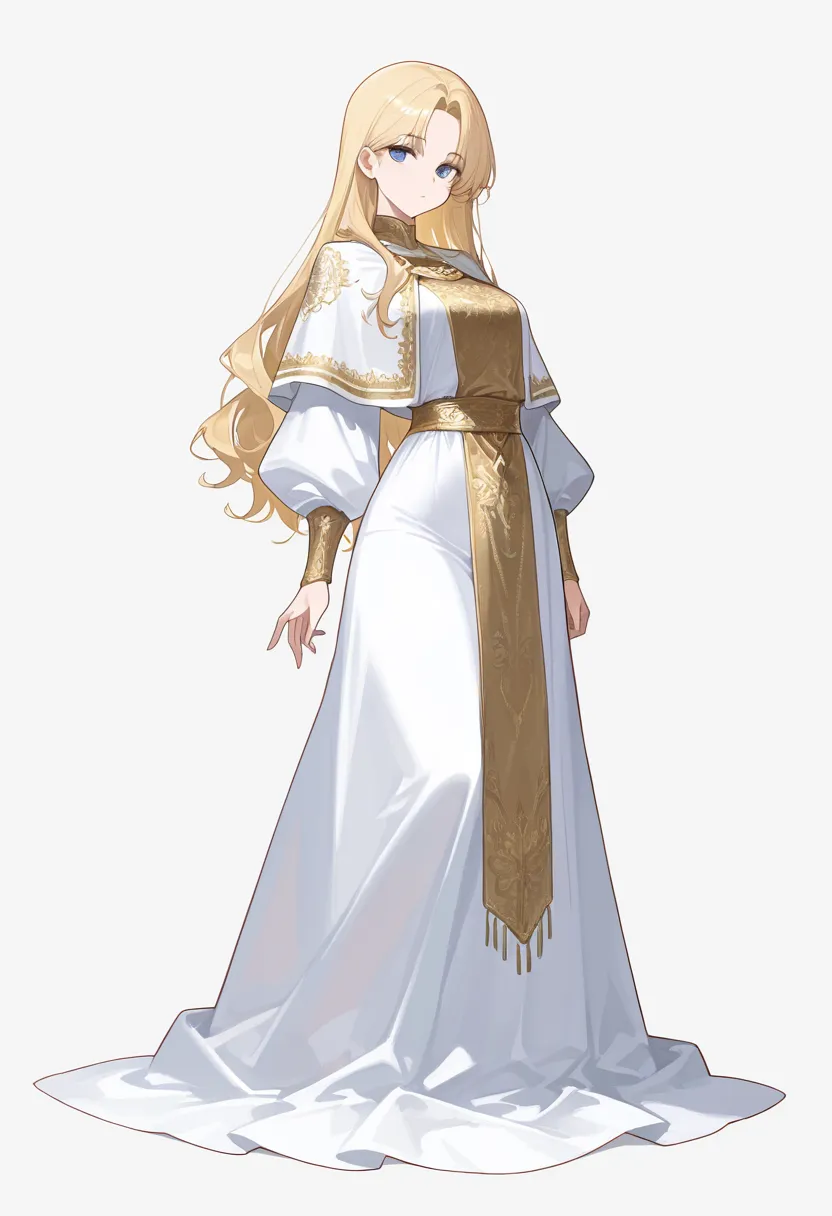
Full-Body Standing on White Background
(Current)
(April)
(April)
(April)
| Model | Image Observations |
|---|---|
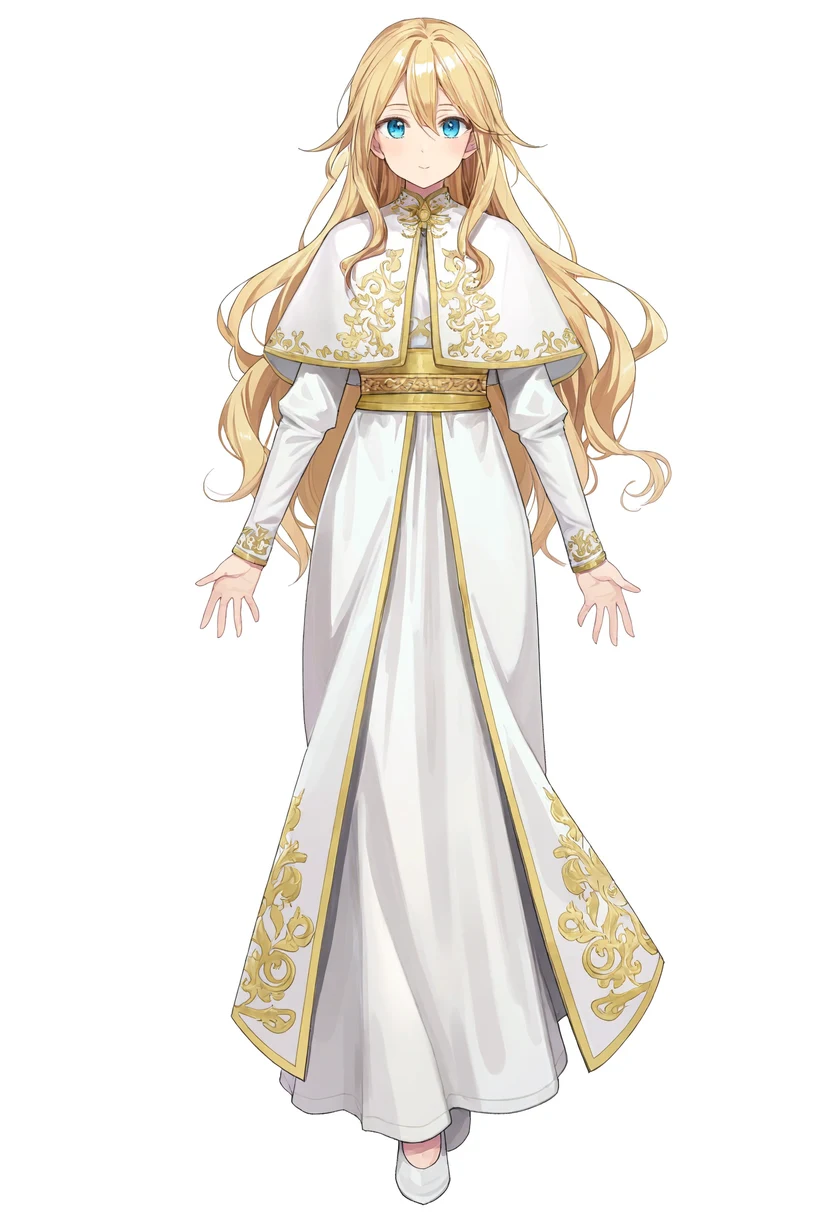
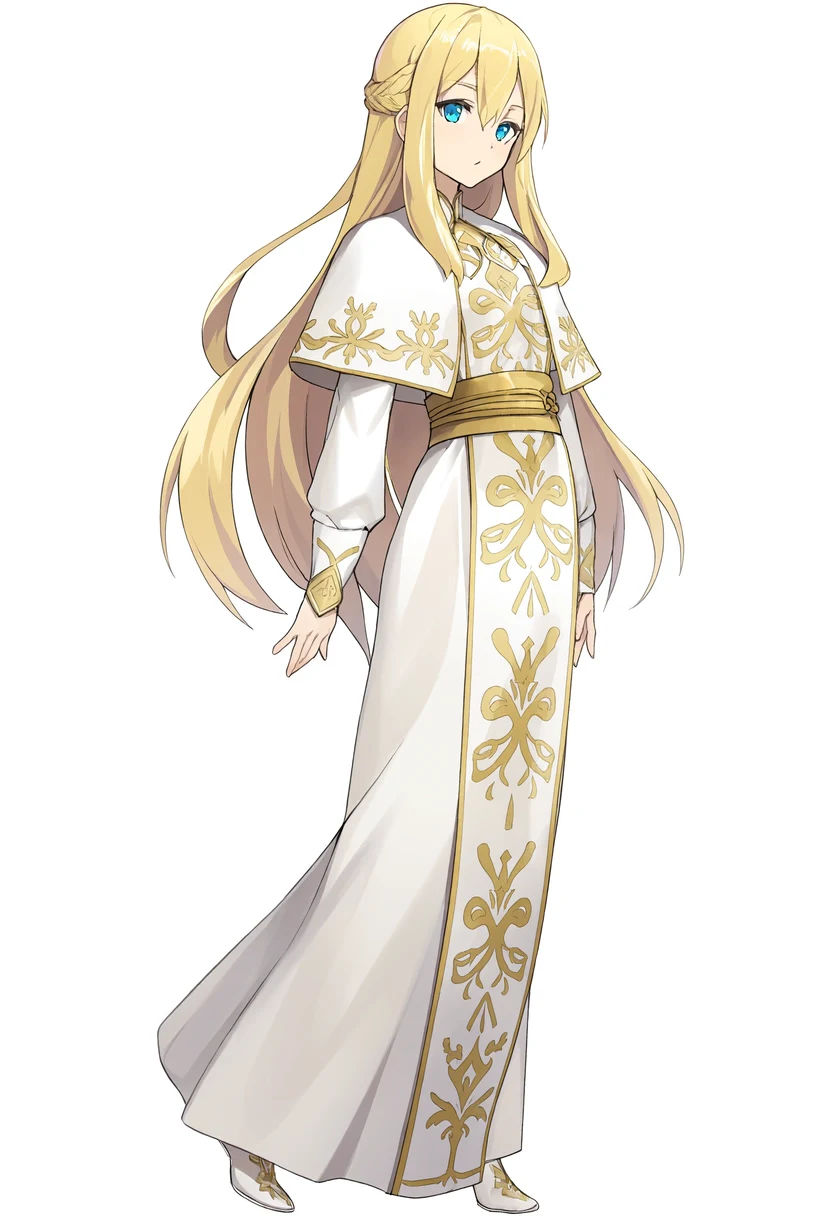
| MiniMax-H3-Image | Clean anime illustration, full-body against white background. Gold arabesque embroidery on capelet, cuffs, and hem. Wide gold sash at waist, white shoes. Open hands by sides. Stray bang over bridge of nose. |
| Anima preview3-base | White and gold outfit with unprompted blue inner lining and hem accents. Intricate gold embroidery and waist ornaments. |
| WAI-Anima v1 | White and gold robe with embroidery on capelet and hem. Blue-green ornamental charms at neck and waist. |
| WAI-Illustrious v160 | White and gold robe with long golden front panel. Broader color blocking with softer shading than Anima. |
MiniMax-H3-Image strictly respected the requested color scheme, producing only white and gold without introducing extraneous colors or accessories. Displayed image is scaled down to 832×1216.
Prompt
Tags used for April models:
1girl, solo, long blonde hair, blue eyes, white robe, gold embroidery, capelet, gold sash, long sleeves, long dress, standing, looking at viewer, full body, white backgroundProse prompt used for MiniMax-H3-Image:
An anime illustration of a single girl with long blonde hair and blue eyes, standing and looking at the viewer, shown in full body from head to toe against a plain white background. She wears a long white robe with gold embroidery, a short capelet over her shoulders, a gold sash at the waist, long sleeves and a long dress.Running Figure with Castle and Sunset Landscape
(Current)
(April)
(April)
(April)
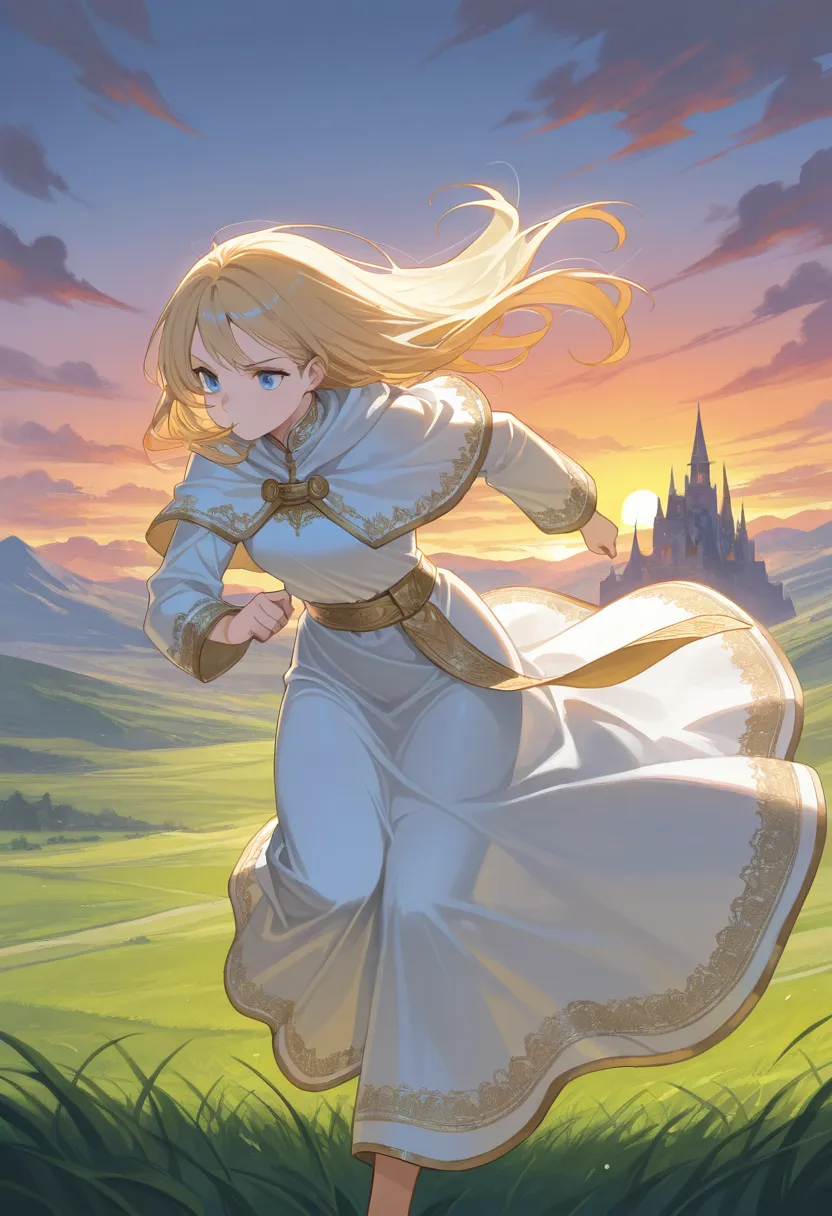
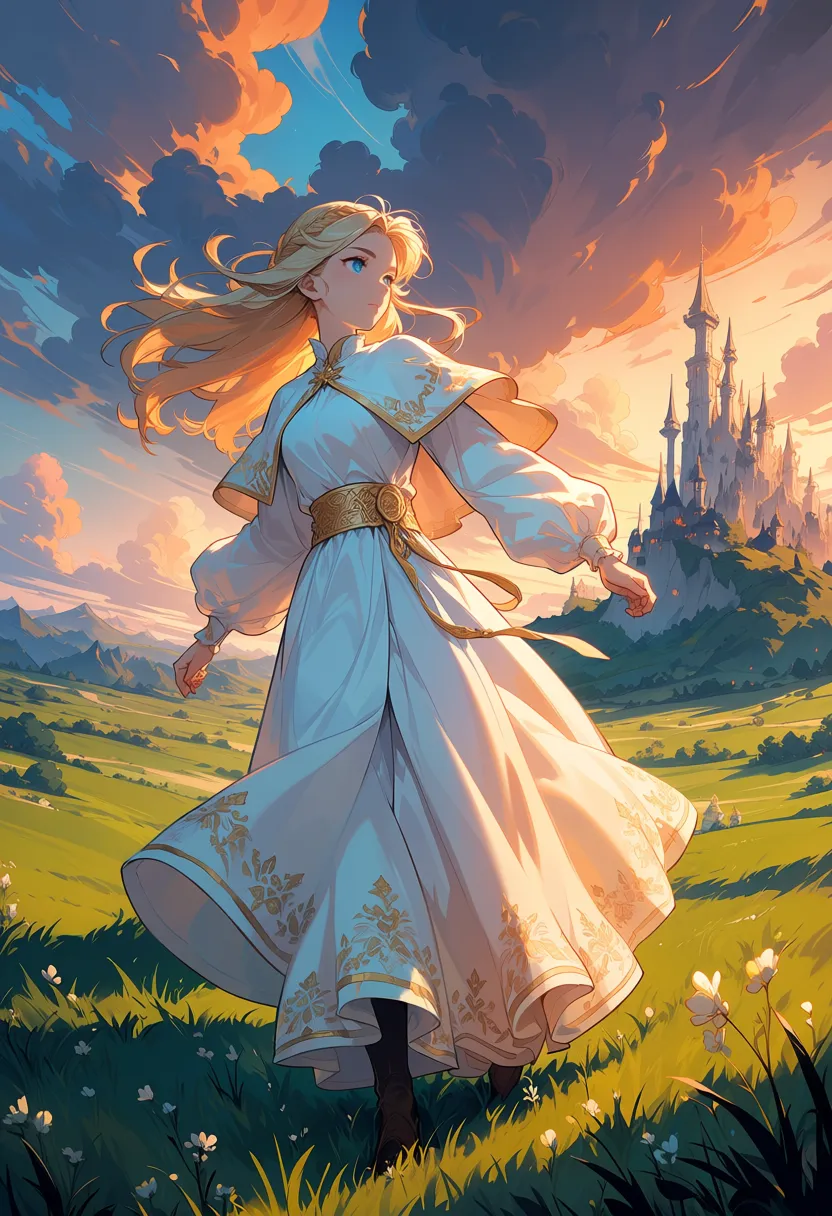
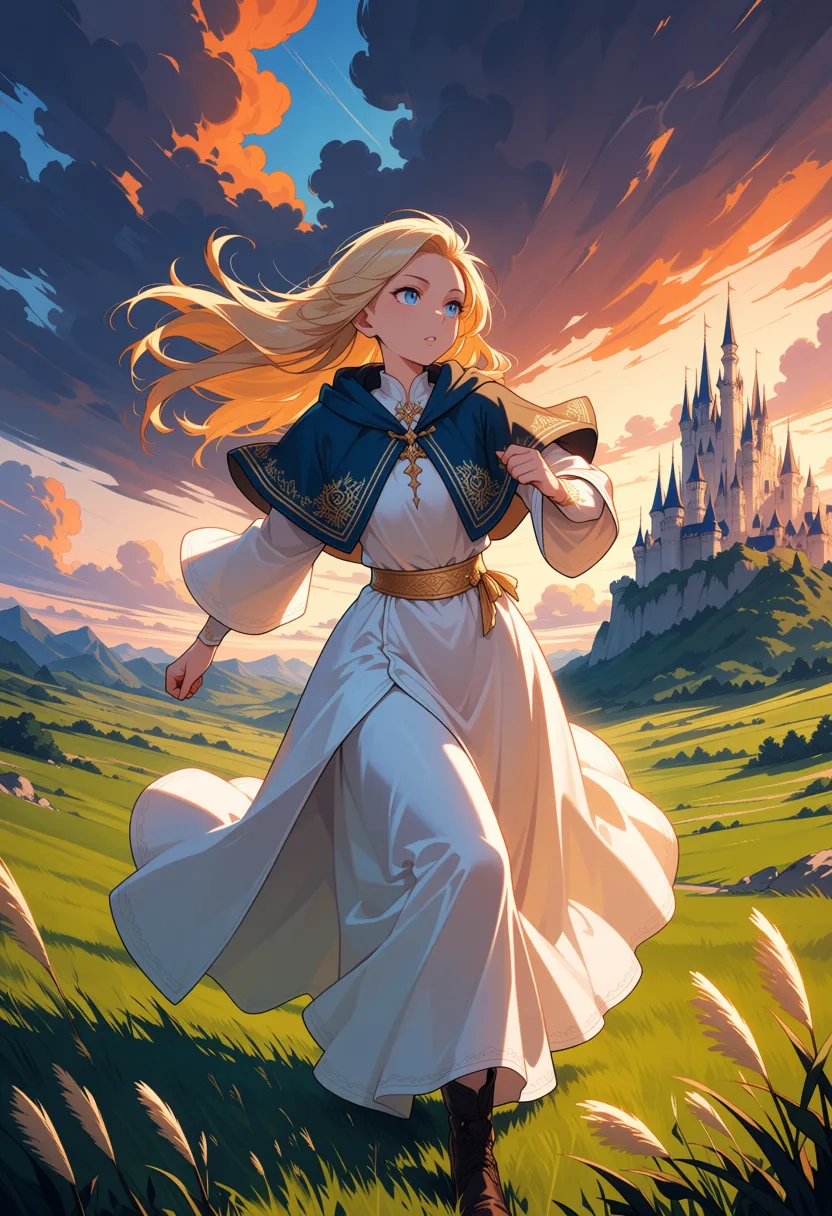
| Model | Image Observations |
|---|---|
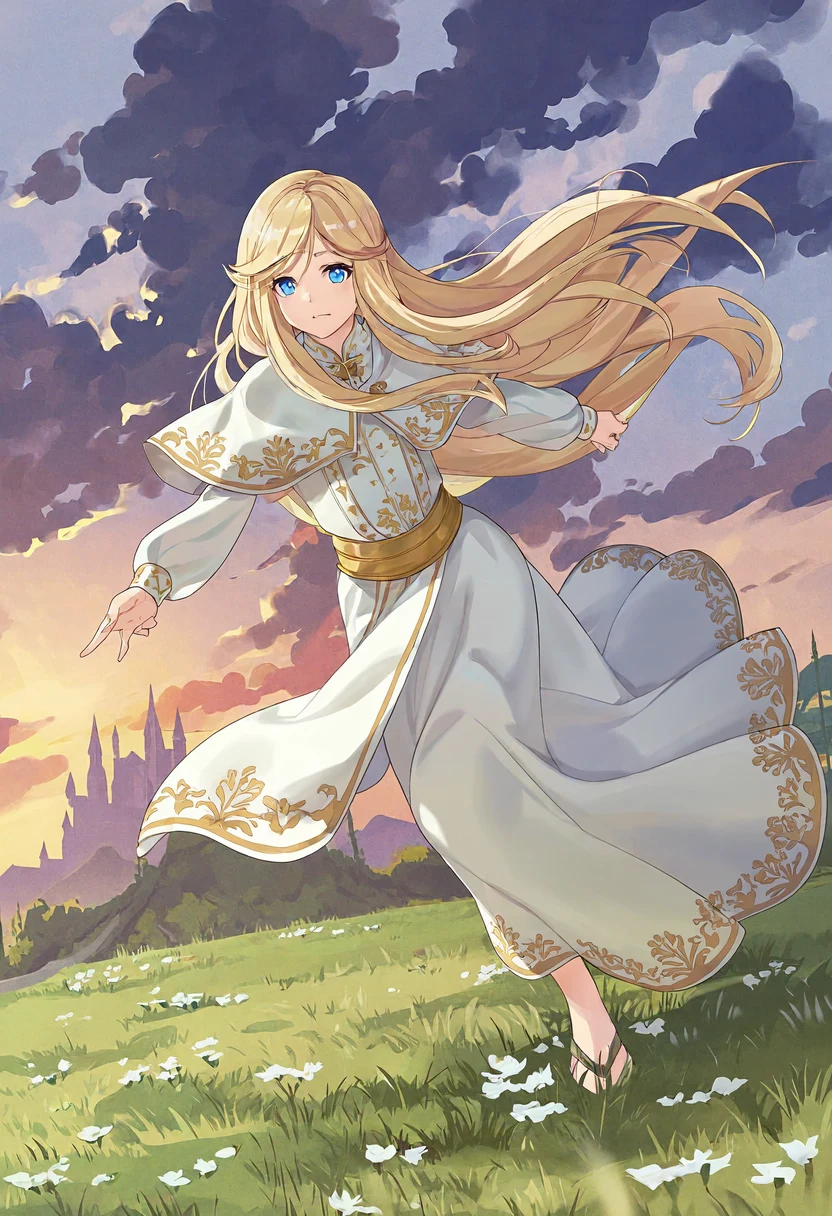
| MiniMax-H3-Image | Leaning forward with one foot planted, hair billowing dynamically. Silhouette of castle in the background, top half filled with dramatic purple clouds and sunset. White flowers in the grass field. |
| Anima preview3-base | Dramatic sunset clouds, undulating terrain, distant castle. Hair and hem flutter, but arms hang straight down, lacking a sense of sprinting momentum. |
| WAI-Anima v1 | Bent arms in a running pose with detailed ground shadows. Capelet color shifted to dark blue. |
| WAI-Illustrious v160 | Forward-leaning running posture with consistent white and gold palette. Large flowing robes and hair, with simpler landscape rendering than Anima. |
MiniMax-H3-Image produced a dynamic forward stride, avoiding the stiff downward-hanging arms observed in Anima preview3-base. The white and gold palette was maintained.
Prompt
Tags used for April models:
1girl, solo, long blonde hair, blue eyes, white robe, gold embroidery, capelet, gold sash, long sleeves, long dress, running, wind, hair blowing, dynamic pose, fantasy landscape, castle in background, sunset sky, dramatic clouds, grass fieldProse prompt used for MiniMax-H3-Image:
An anime illustration of a single girl with long blonde hair and blue eyes, running in a dynamic pose across a grass field while the wind blows her hair. She wears a long white robe with gold embroidery, a short capelet over her shoulders, a gold sash at the waist, long sleeves and a long dress. The background is a fantasy landscape with a castle in the distance under a sunset sky with dramatic clouds.Seed Variation on Standing and Running Prompts
To test output consistency beyond seed 42, I tested seeds 1234 and 9999 using the identical prompts at 1664×2432.
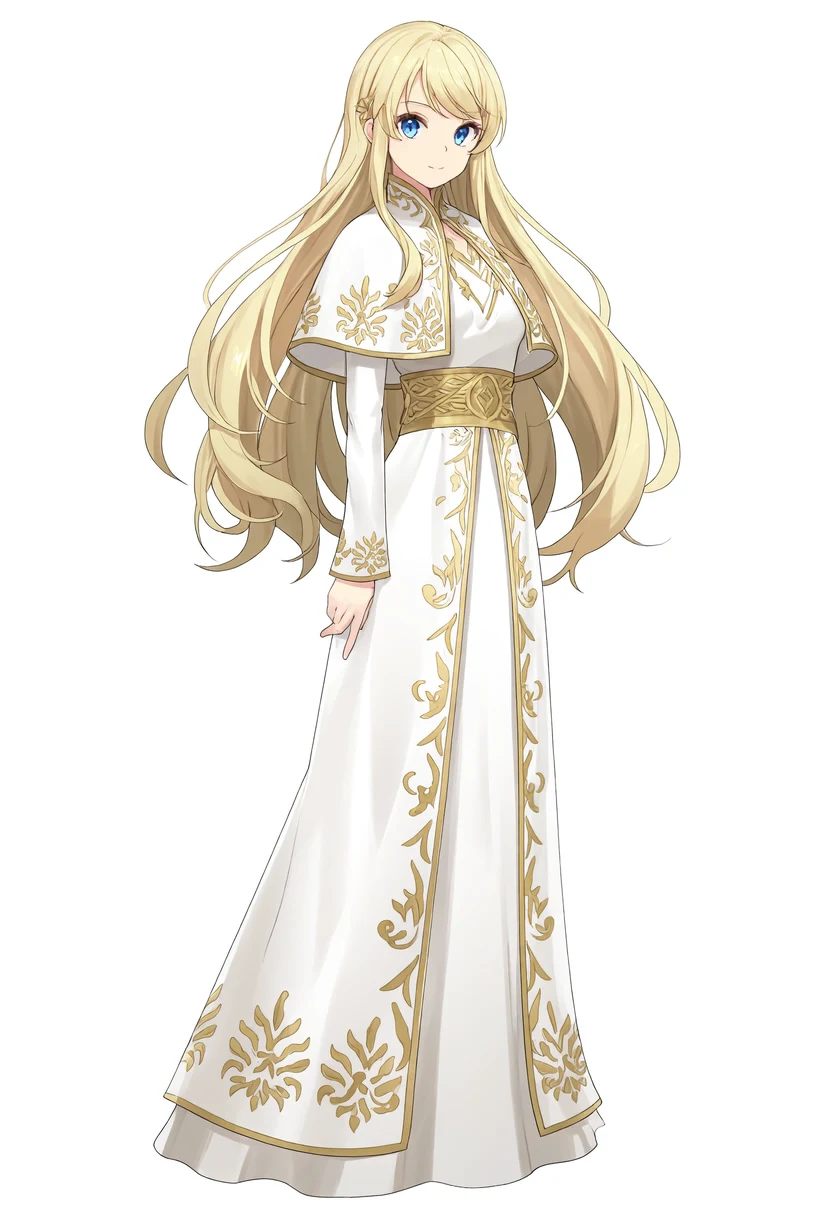
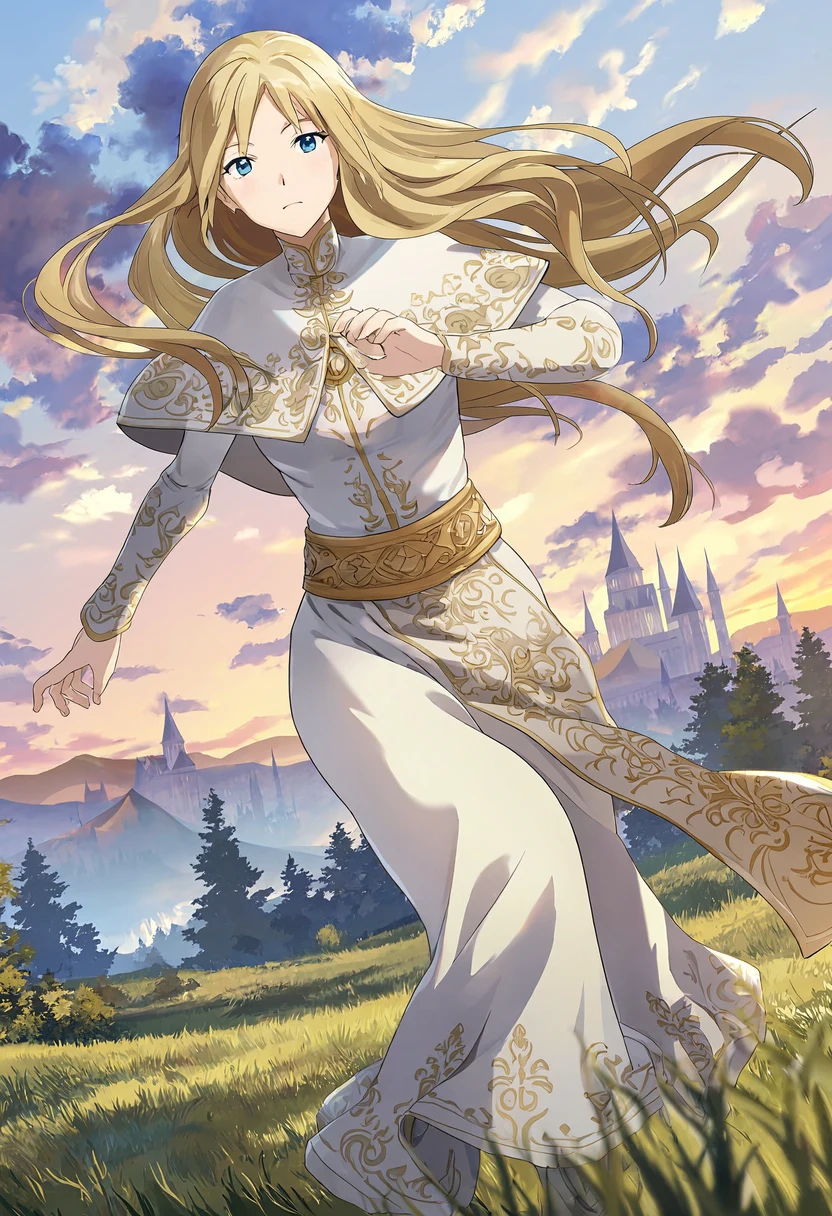
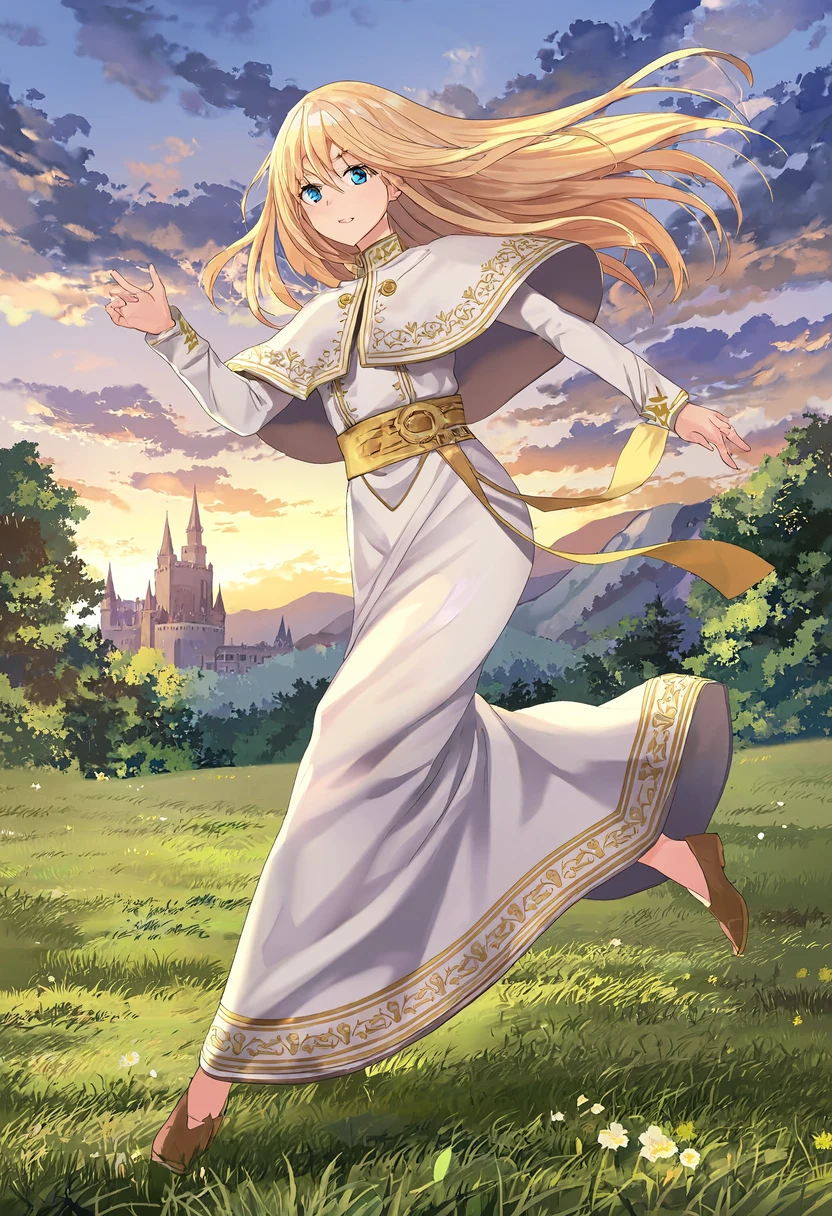
| Image | Image Observations |
|---|---|
| Standing (Seed 42) | Full-body standing against plain white. Gold embroidery along capelet, sleeves, and hem. Wide gold sash |
| Standing (Seed 1234) | Flat shading with minimal cast shadows. Body angled in slight three-quarter view, braided hair accents |
| Standing (Seed 9999) | Angled pose with extensive arabesque embroidery covering capelet, sleeves, and skirt. Knotted cord waist accessory |
| Running (Seed 42) | Forward stride across meadow. Castle and sunset clouds in background with flowing hair and dress |
| Running (Seed 1234) | Background clouds and castle adopt a thick painterly texture; facial features differ from other seeds. One hand resting on chest |
| Running (Seed 9999) | Energetic stride kicking one leg backwards, smiling towards camera. Sash trailing behind, brown shoes |
Across all three seeds, the white and gold palette held without unprompted color contamination.
However, the rendering style varied noticeably across seeds: standing seed 1234 was flat and cel-shaded, while running seed 1234 leaned towards a painterly background. Locking down a consistent aesthetic likely requires explicit stylistic modifiers in the English prompt.
Generation times were consistent across seeds at 297–302 seconds.
Low Resolution Test at 832×1216 (~1MP)
MiniMax recommends resolutions above 4MP. To inspect what happens when dropping to 832×1216, I tested the standing prompt at seed 42.
| Resolution | Total Time | Per-Step Time |
|---|---|---|
| 1664×2432 (~4.05MP) | 299.42s | ~47s |
| 832×1216 (~1MP) | 116.52s | ~16.1s |
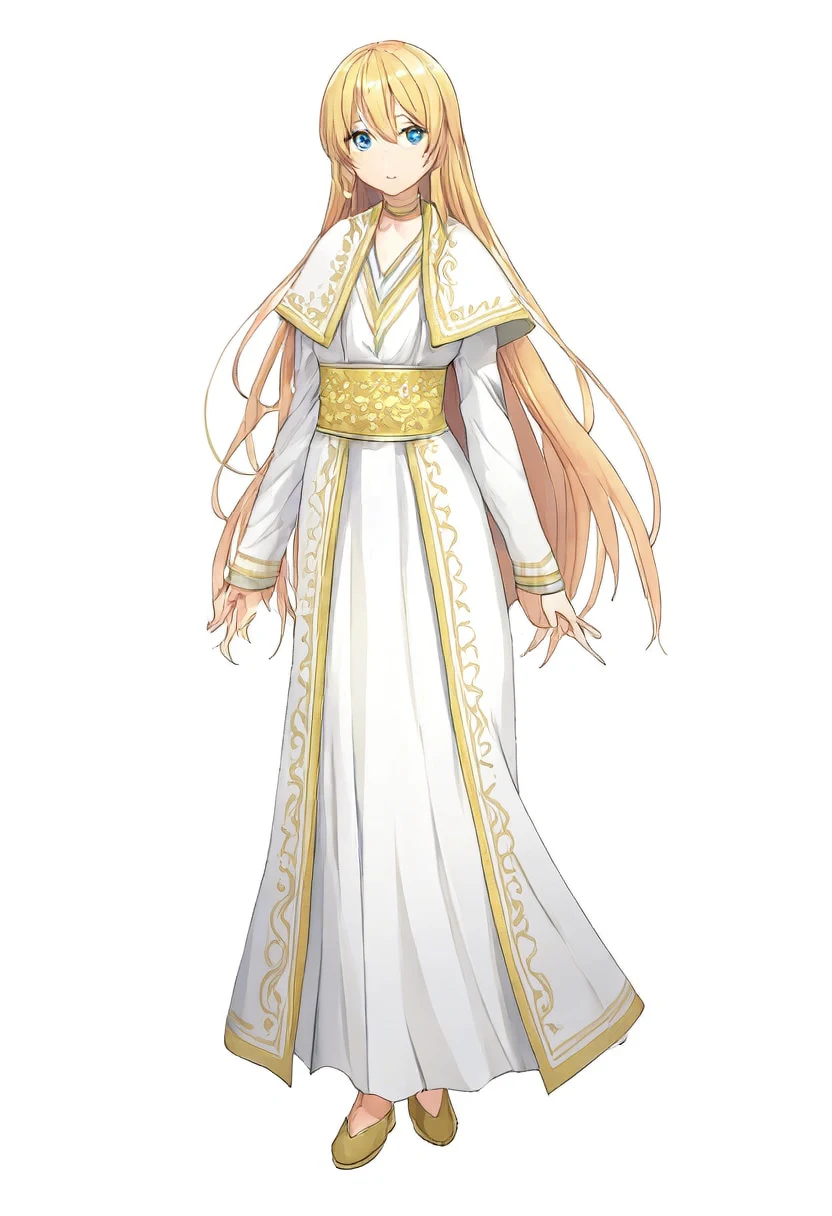
Overall composition remained intact at 832×1216, generating a full-body standing figure. However, details like the capelet embroidery and gold-colored footwear differed from the 4MP render.
Cropping the left hand at identical pixel scale highlights the divergence:
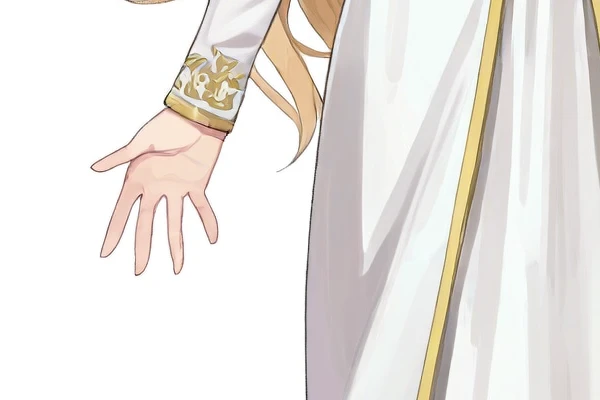
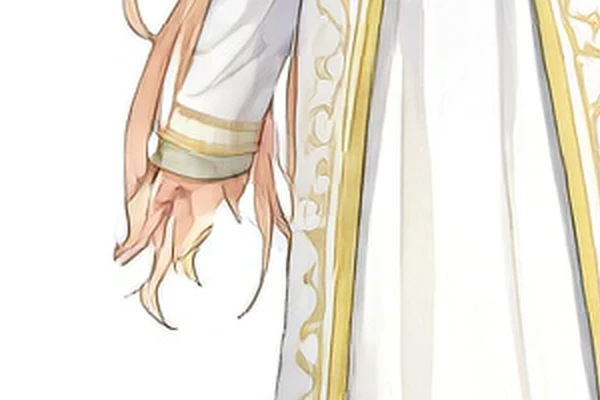
At 4MP, all five fingers are rendered with clean separation. At 832×1216, the fingers elongated and fused with adjacent hair strands.
Reference Image Editing with Kana-chan
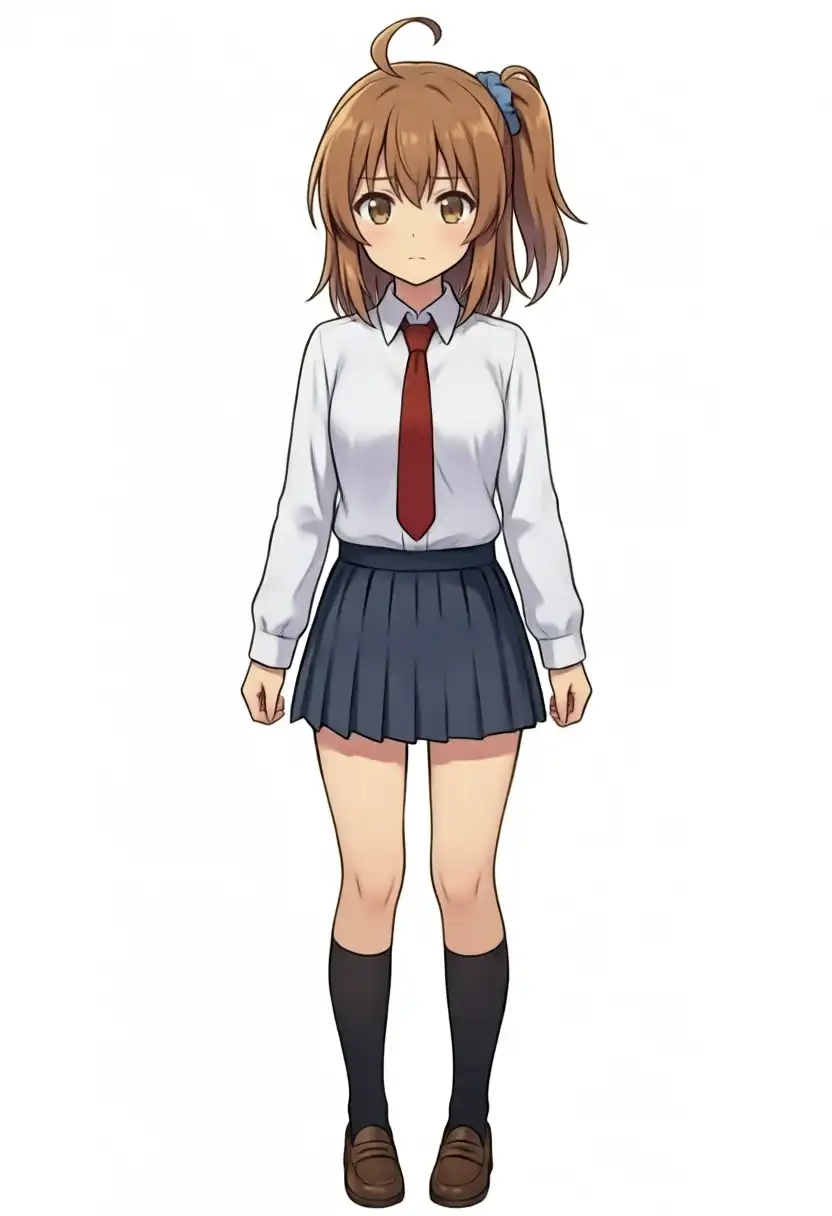
Since custom character LoRAs cannot be directly loaded, I tested reference image editing to reproduce the original character Kana-chan.
The source image was the neutral standing portrait from the Qwen-Image 2.1 benchmark. I tested overhead perspective and five different camera angles and action poses.
Official Editing Template Pipeline
MiniMax-H3-Image’s image editing uses a structured prompt format documented in examples/revised_prompt.edit.txt. It assigns IDs to elements (The girl in <Picture 1> is <Subject 1>.), specifies preserved vs changed attributes (<Subject 1> is partially preserved; 〜 remain, while 〜 change), and concludes with The target image shows 〜.
ComfyUI’s official template image_minimax_h3_image_edit.json uses an LLM to automatically expand short user instructions into this format before passing it to the diffusion model.
The editing pipeline works in three stages:
| Stage | Operation | Setting |
|---|---|---|
| 1 | Resize reference image to ~4MP, snapping dimensions to multiples of 32 | An 832×1216 source becomes 1664×2464 |
| 2 | Feed user instruction and image into Qwen3.5 9B to generate expanded_caption | Official system prompt and sampling settings (8196 max tokens, temperature 1.0, thinking enabled) |
| 3 | Generate output from expanded caption, resized image, and target resolution | 6 steps, CFG 1.0, seed 42 |
The template defaults to qwen3.5_9b_w4a8_gptq, but on Apple Silicon with ComfyUI, inference ran at ~1.9–3.6 seconds per token, estimating several hours per caption. Swapping to the BF16 weights (19.3GB) from Comfy-Org/Qwen3.5 accelerated generation to ~9.2 tokens/second, completing each rewrite in 638–900 seconds.
When Qwen3.5’s reasoning chain hits the 8196 token ceiling, it returns an empty string. This occurred on the right profile and rear shots, requiring a seed change from 0 to 1 to produce a valid caption. Generating with an empty caption defaults to reproducing the reference image.
The Qwen-Image 2.1 comparison images are from the September benchmark (832×1216, 40 steps) without regeneration.
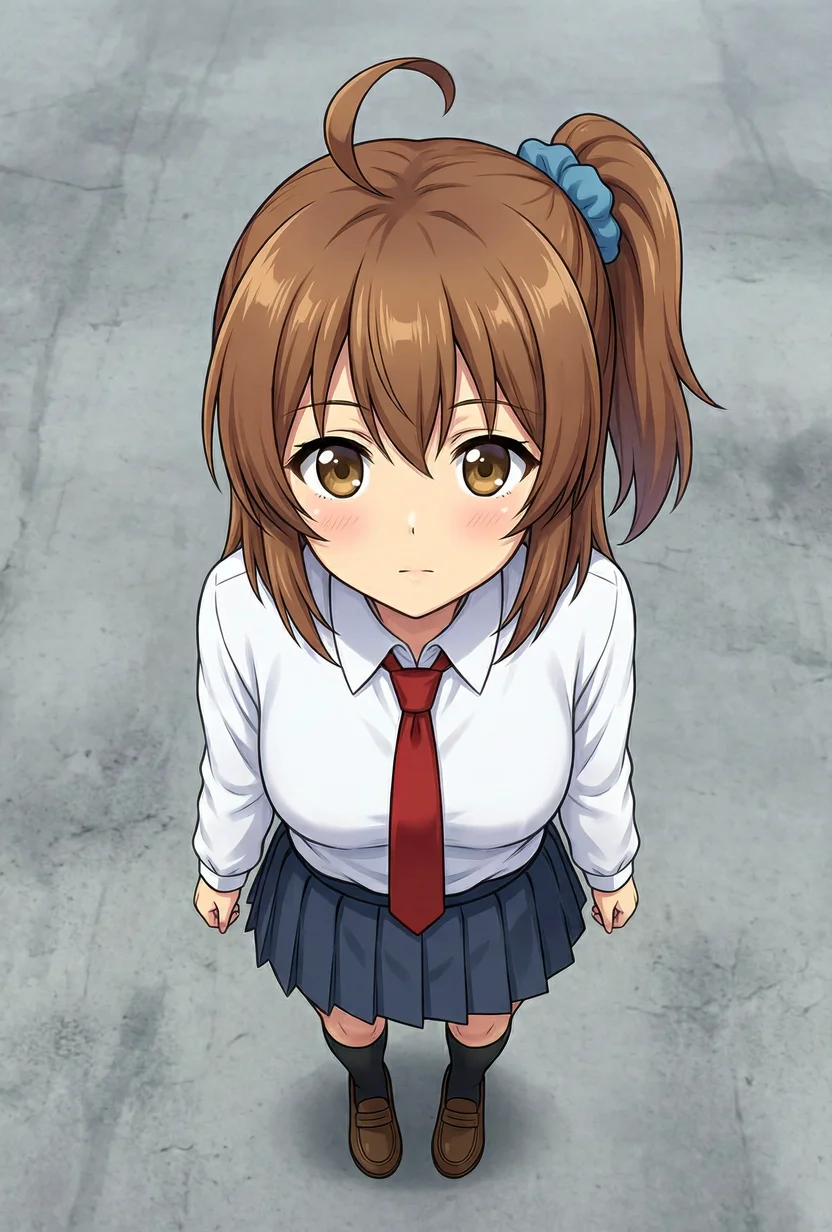
Overhead View
(Current)
(September)
| Model | Image Observations |
|---|---|
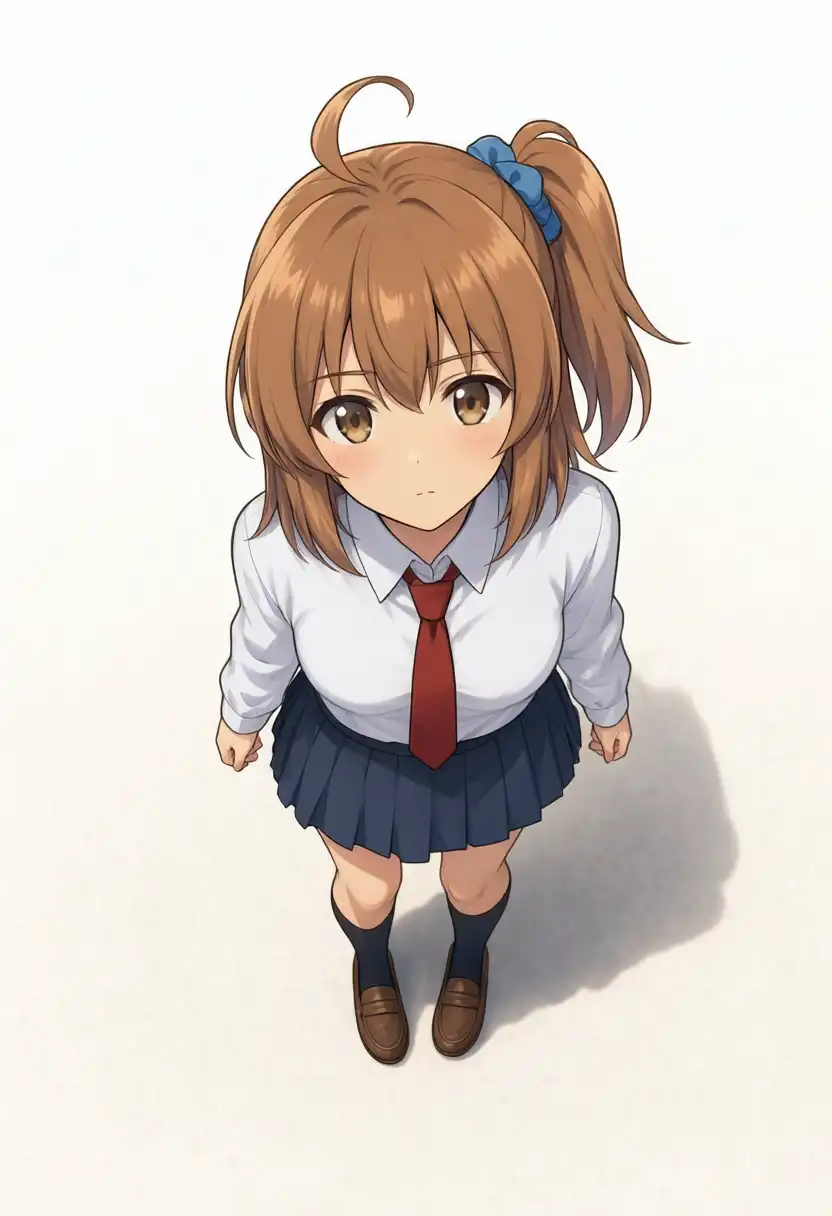
| MiniMax-H3-Image | Steep high-angle view looking down, creating strong perspective with enlarged head and small feet. Grey concrete-like ground. Ahoge, right side ponytail with blue scrunchie, red necktie, navy skirt, high socks, and loafers were cleanly retained. |
| Qwen-Image 2.1 | Downward high angle looking up. Plain white background with grounded shadow. |
Asymmetrical Hairstyle Across Rotations and Poses
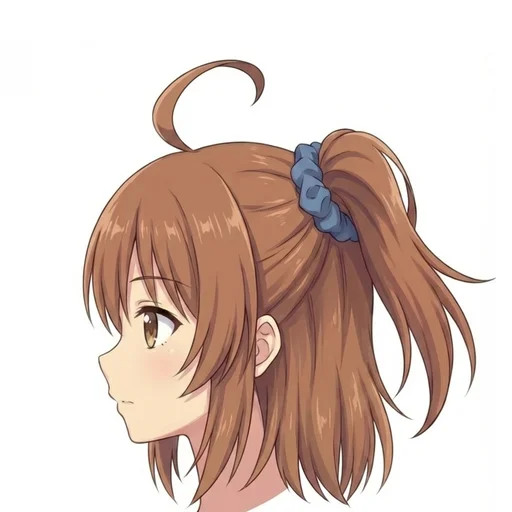
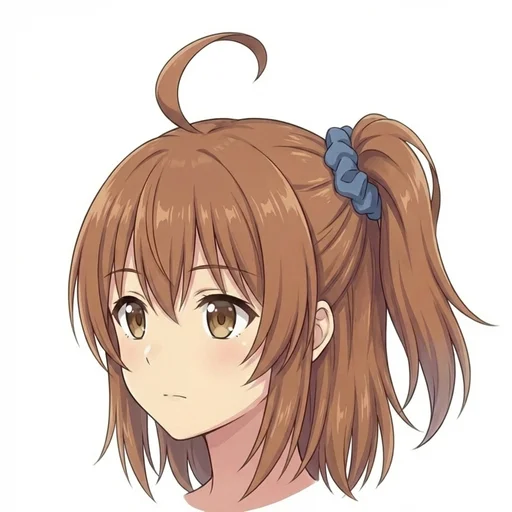
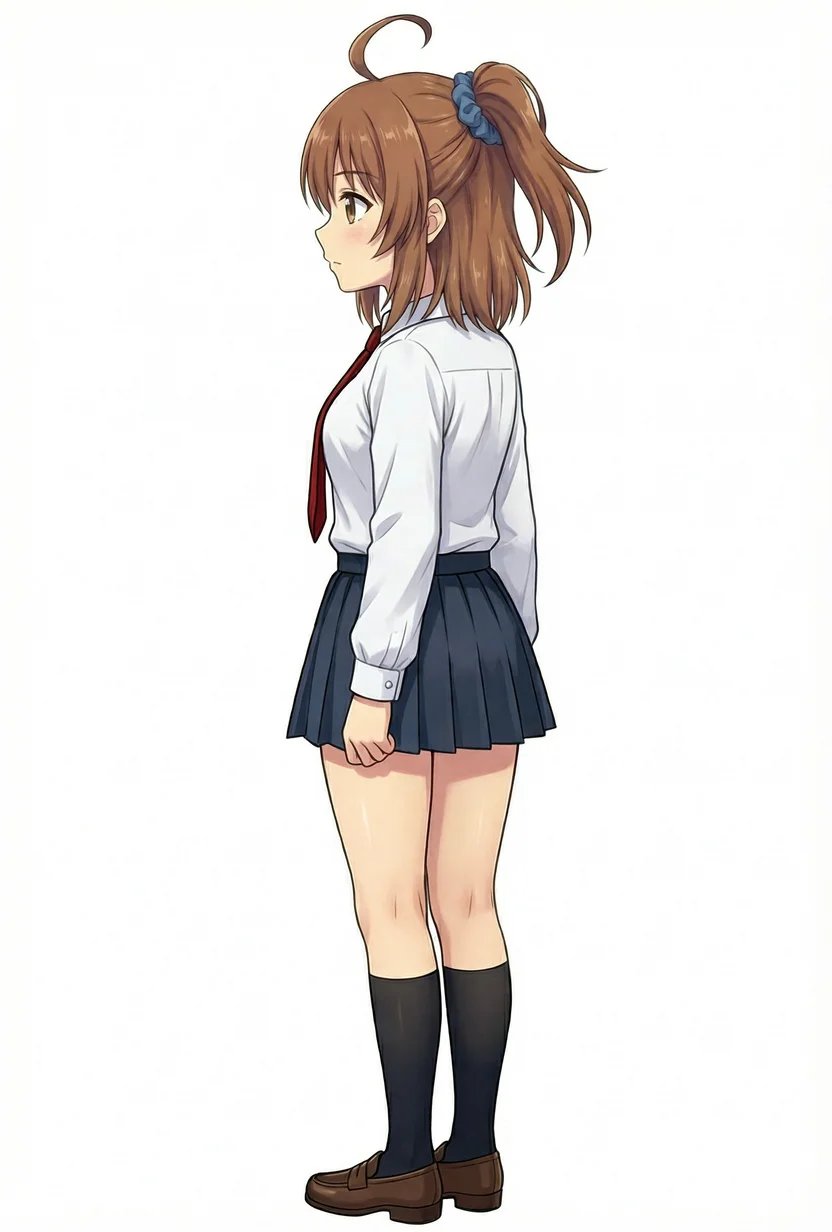
Kana-chan’s hairstyle is asymmetrical: her side ponytail is tied behind her left ear with a blue scrunchie. In the LoRA training dataset (left profile and three-quarter view), the scrunchie sits above and behind her ear. I evaluated whether this spatial relationship held under rotation and action poses.
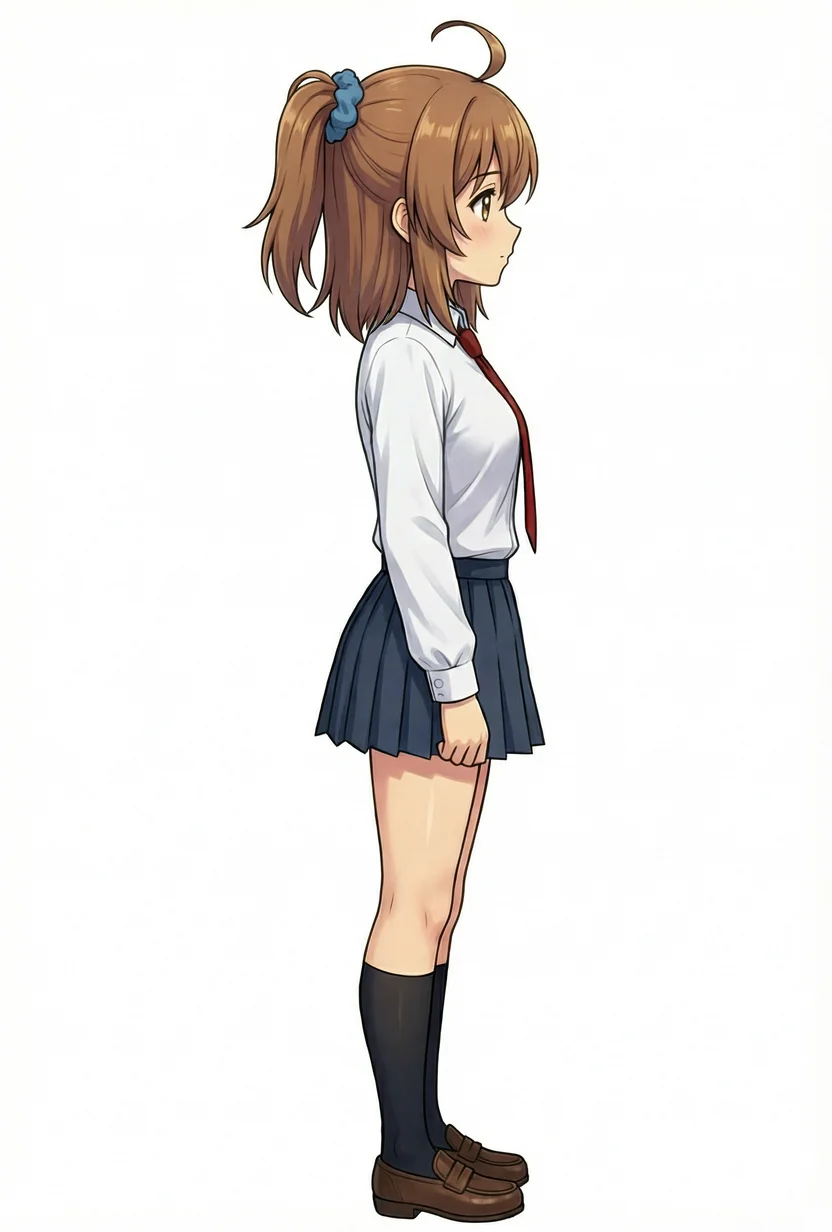
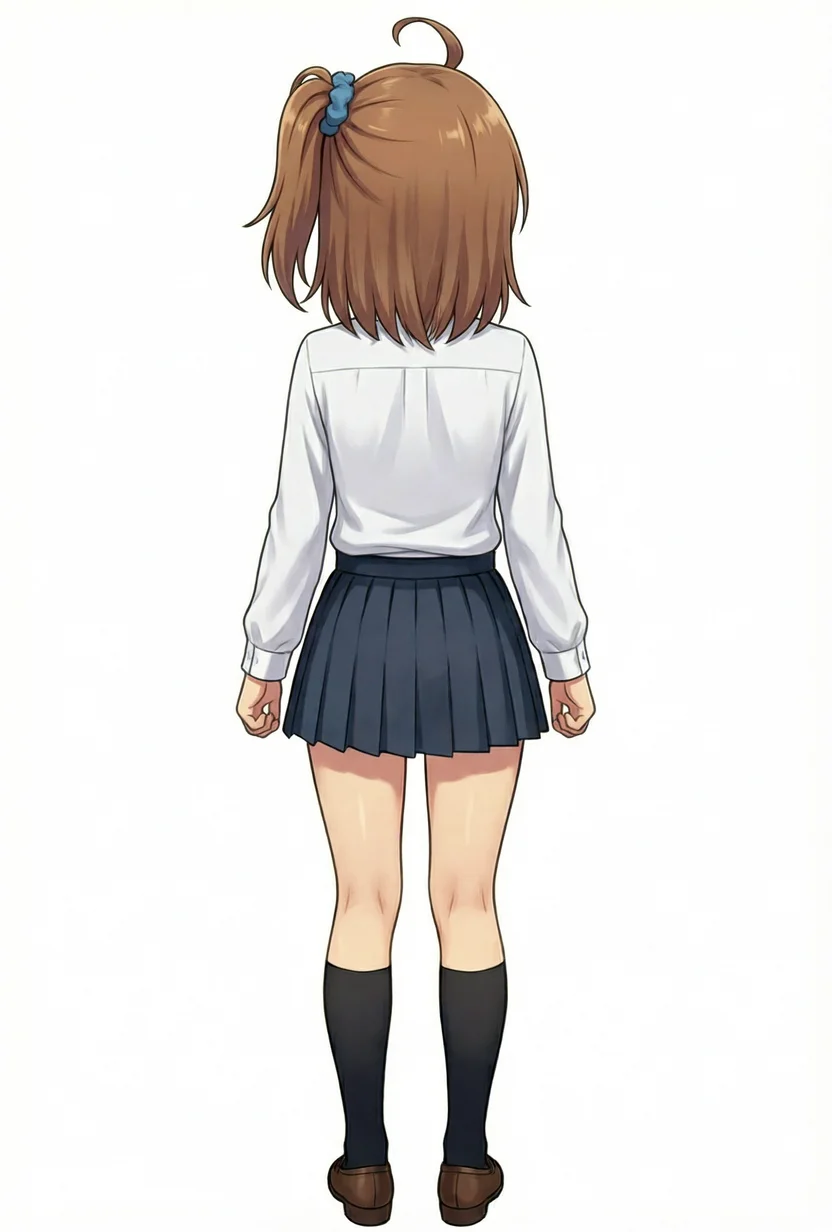
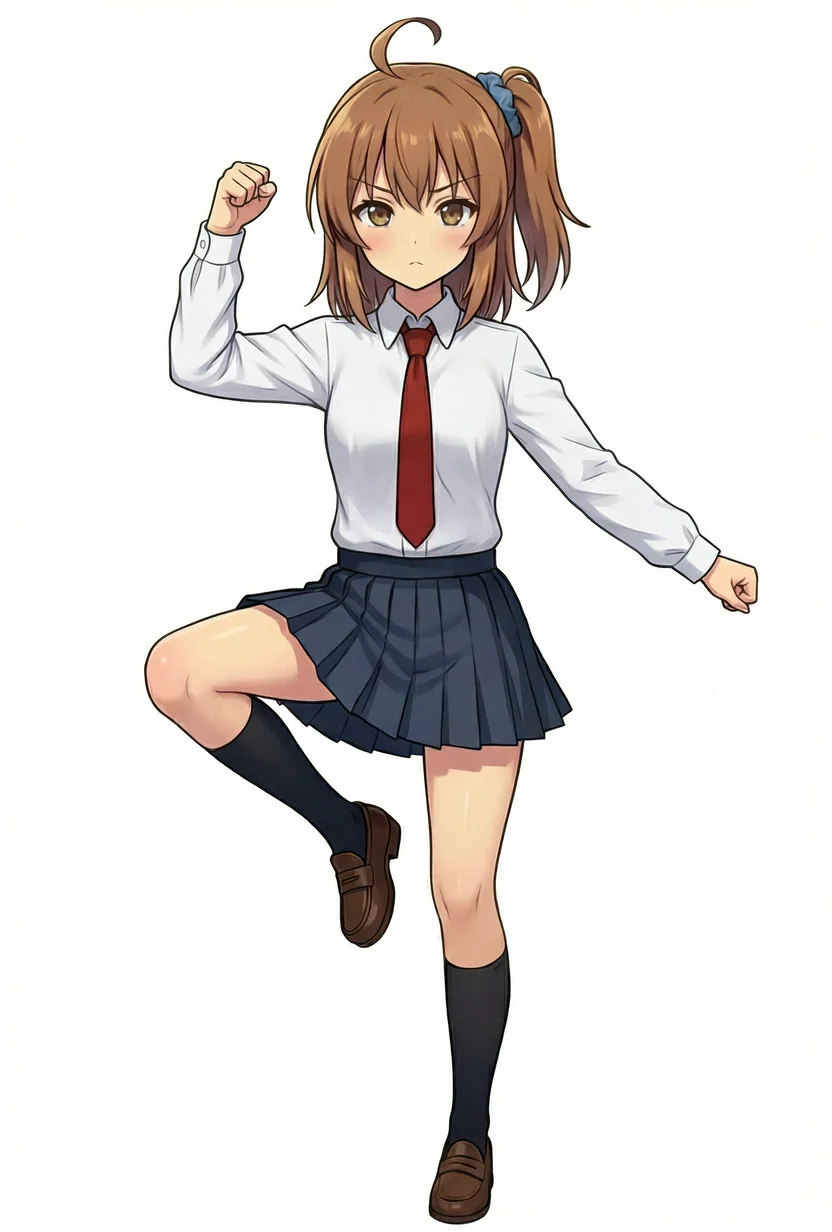
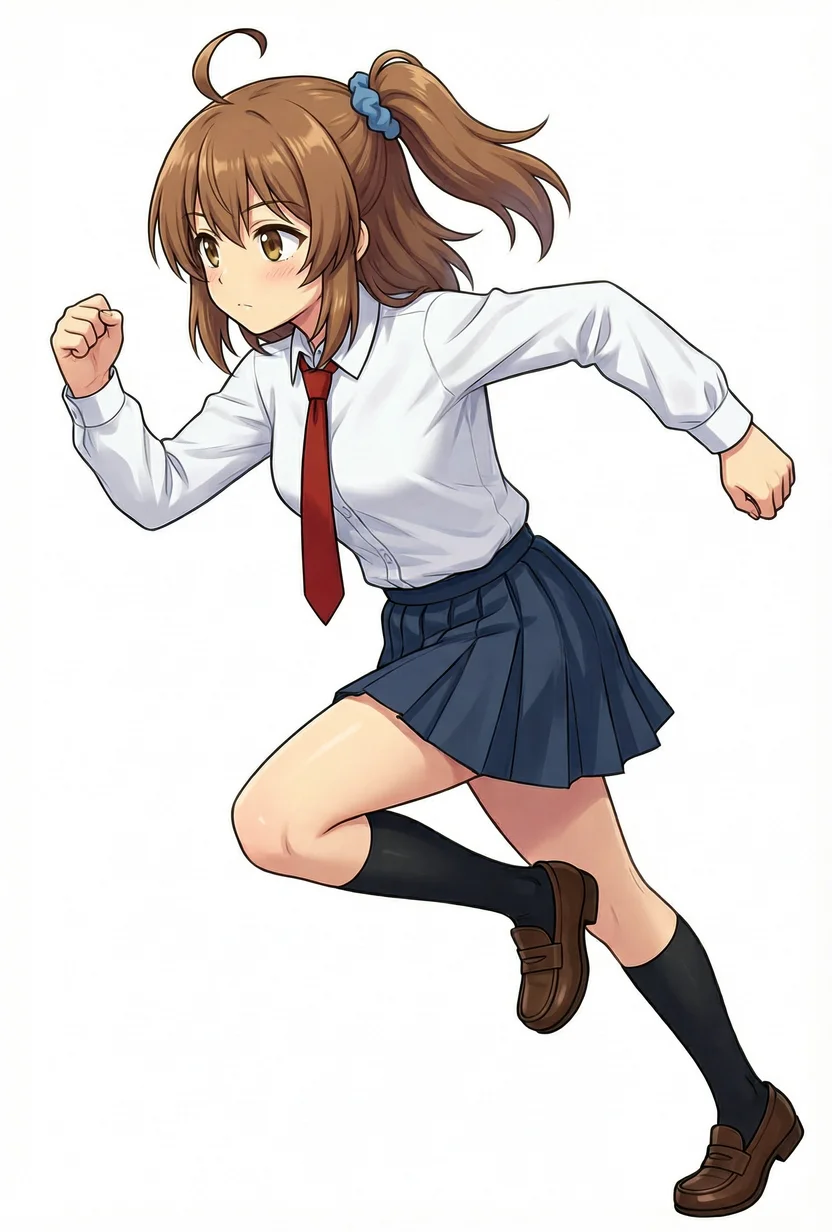
| Modified Condition | MiniMax-H3-Image (Current) | Qwen-Image 2.1 (September) |
|---|---|---|
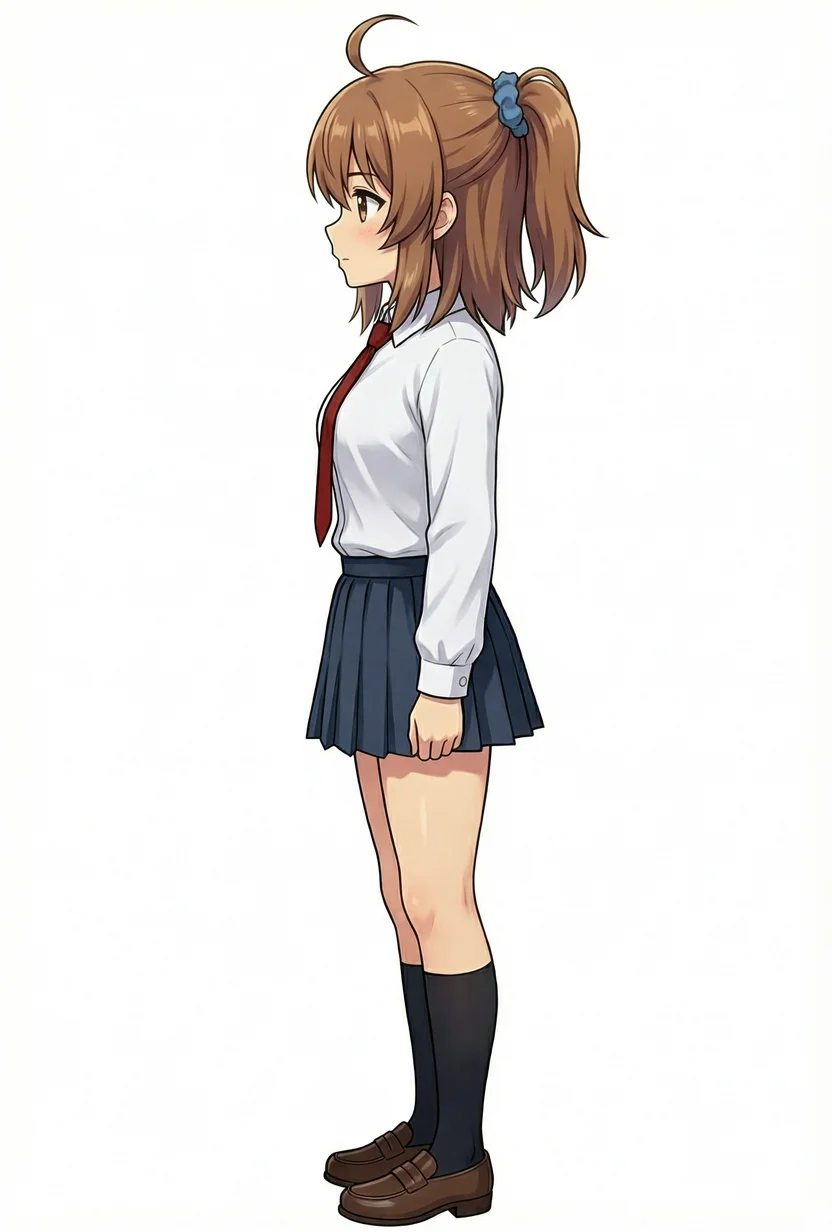
| Left Profile | Clean left profile facing viewer’s left. Scrunchie sits high behind the ear, closely matching the training image. | Knot shifted towards center back, resembling a standard ponytail. |
| Right Profile | Clean right profile facing viewer’s right. Scrunchie peeks over the crown from the far side. Matches logical geometry. | Retained side ponytail shape, but flipped tie position to character’s right side. |
| Rear View | Direct back view with face hidden. Side ponytail and blue scrunchie remain on viewer’s left, maintaining anatomical consistency. | Scrunchie on viewer’s left, anatomically correct. |
| Jump | Right fist and right knee raised, left arm extended outwards. Left foot remained planted, falling short of airborne state. | Knot stayed on viewer’s right. Left arm angled downward, left leg slightly bent. |
| Sprinting (Three-Quarter) | Leaning forward sprinting towards viewer’s left, both feet off the ground. Arm swing inverted compared to instruction. Scrunchie placement matches training data. | Knot shifted rearward. Arm swing was inverted. |
Testing seeds 1234 and 9999 for the sprinting pose with the same expanded prompt produced identical poses, leg postures, and inverted arm swings across all three runs:
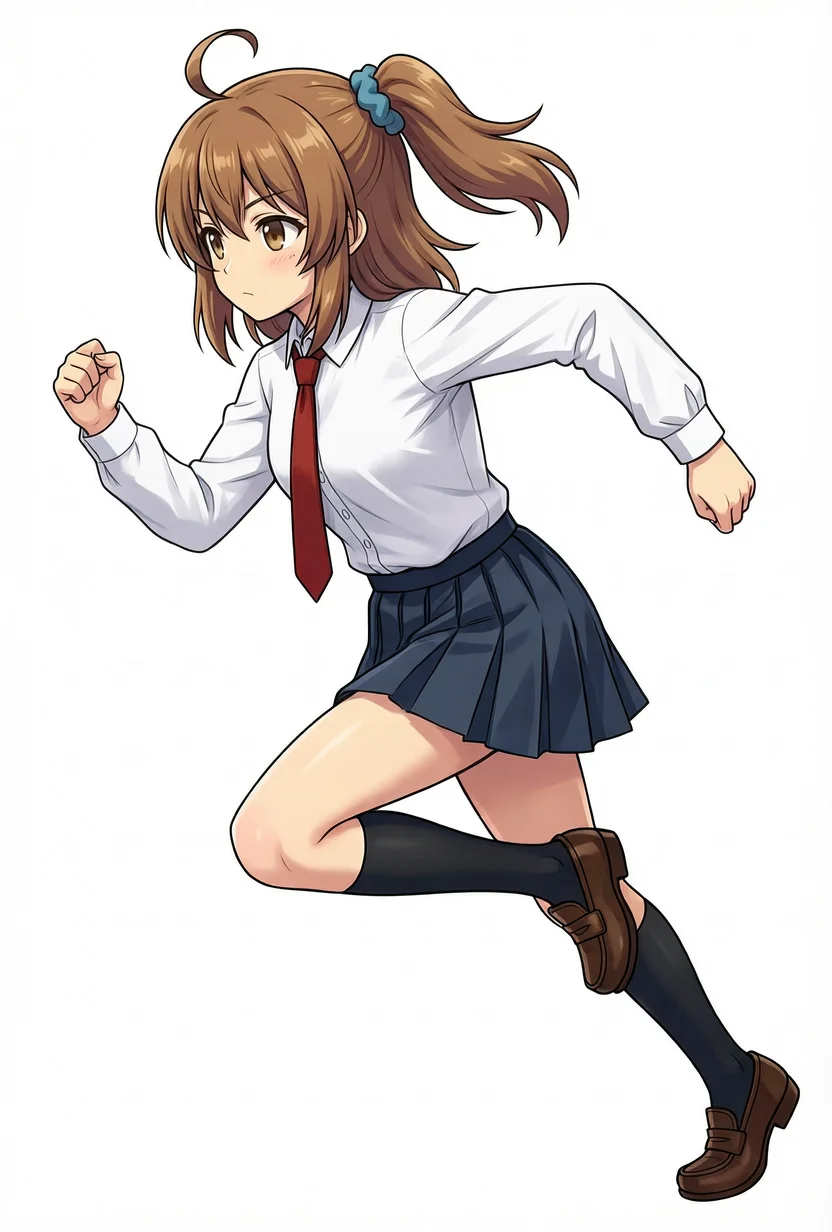
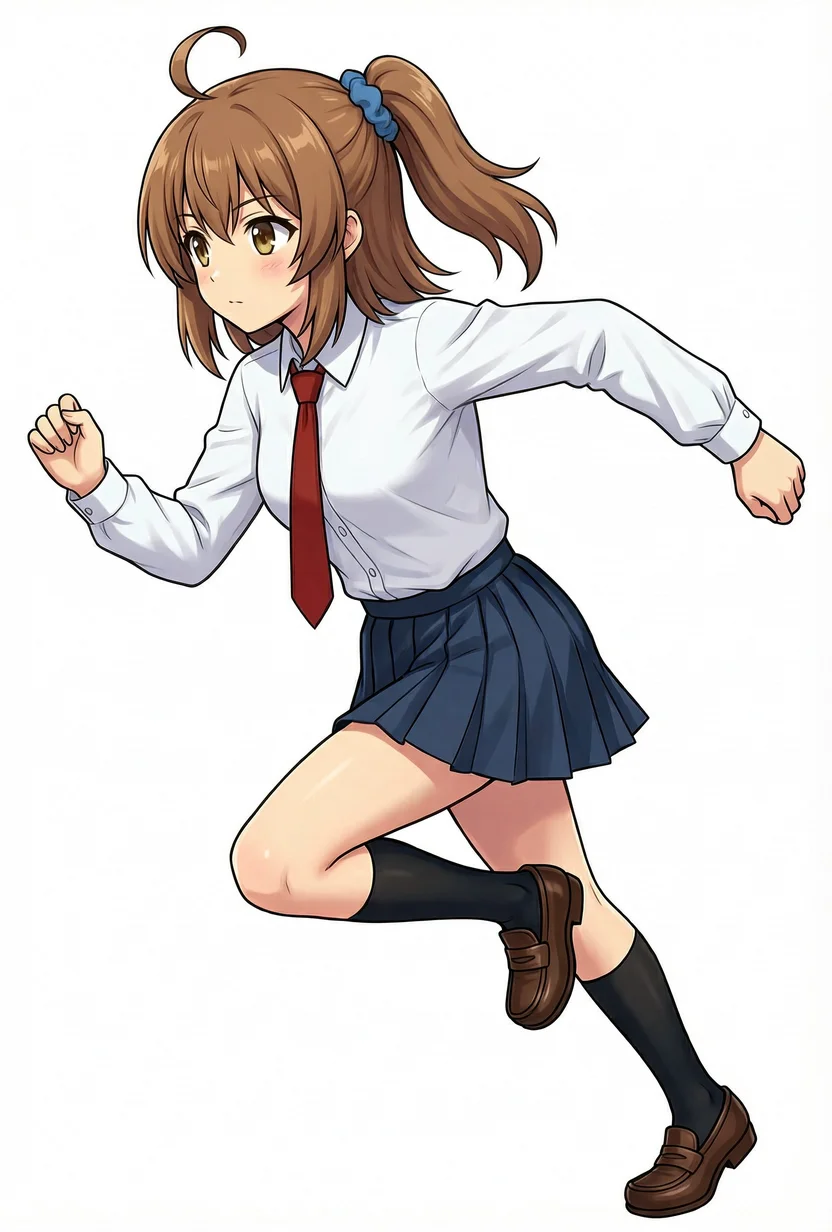
Comparing scrunchie placement against training data confirmed correct 3D spatial consistency across left profile, sprinting, and rear views. Inverting arm swings persisted across all seeds despite the expanded prompt correctly describing arm positions, indicating a diffusion adherence bottleneck rather than caption omission.
Across all six conditions, face geometry, ahoge, uniform, socks, and shoes remained true to the reference.
Multi-Image Reference Conditioning (3 Images)
ComfyUI’s MiniMaxH3ImageConditioning node supports multiple image inputs, linking additional references into both the rewriting LLM and the diffusion pipeline.
I passed the neutral standing portrait as <Picture 1>, and the two training profile images as <Picture 2> and <Picture 3>, re-running the sprinting pose and lateral profile shots.
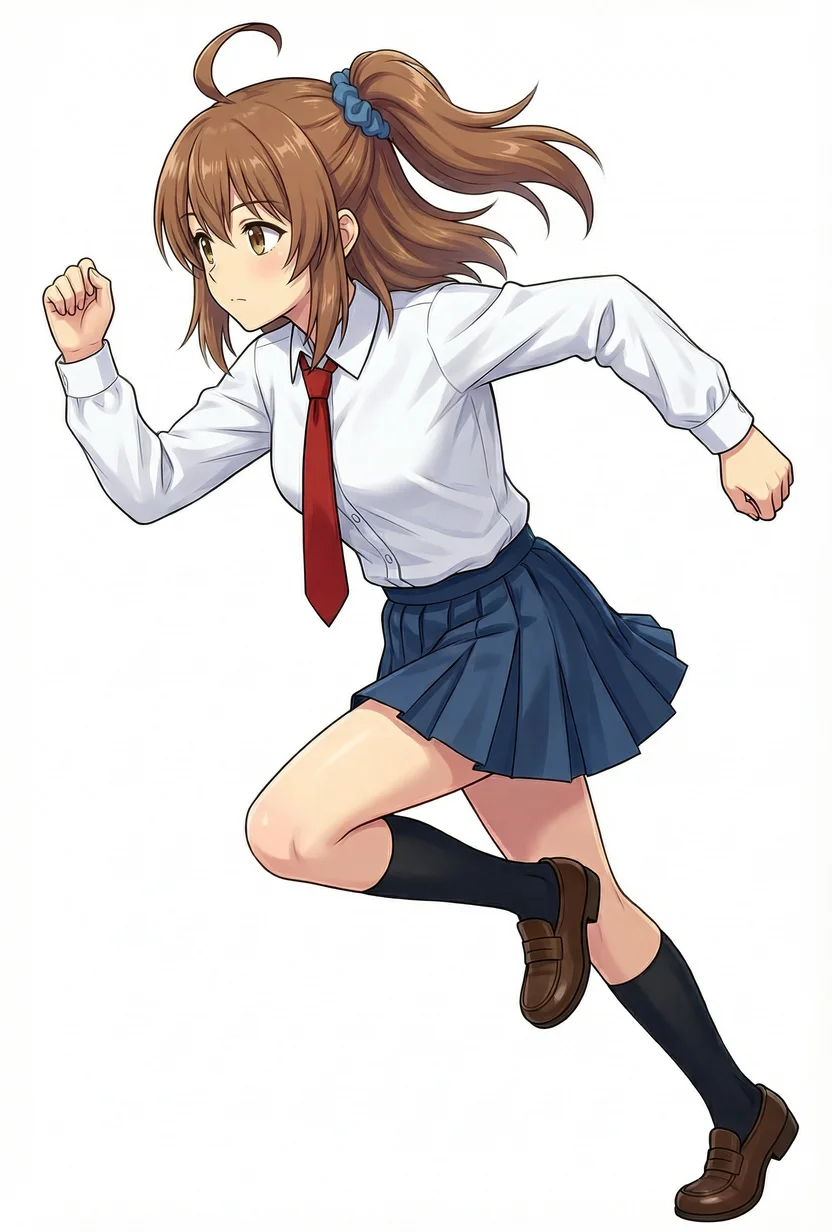
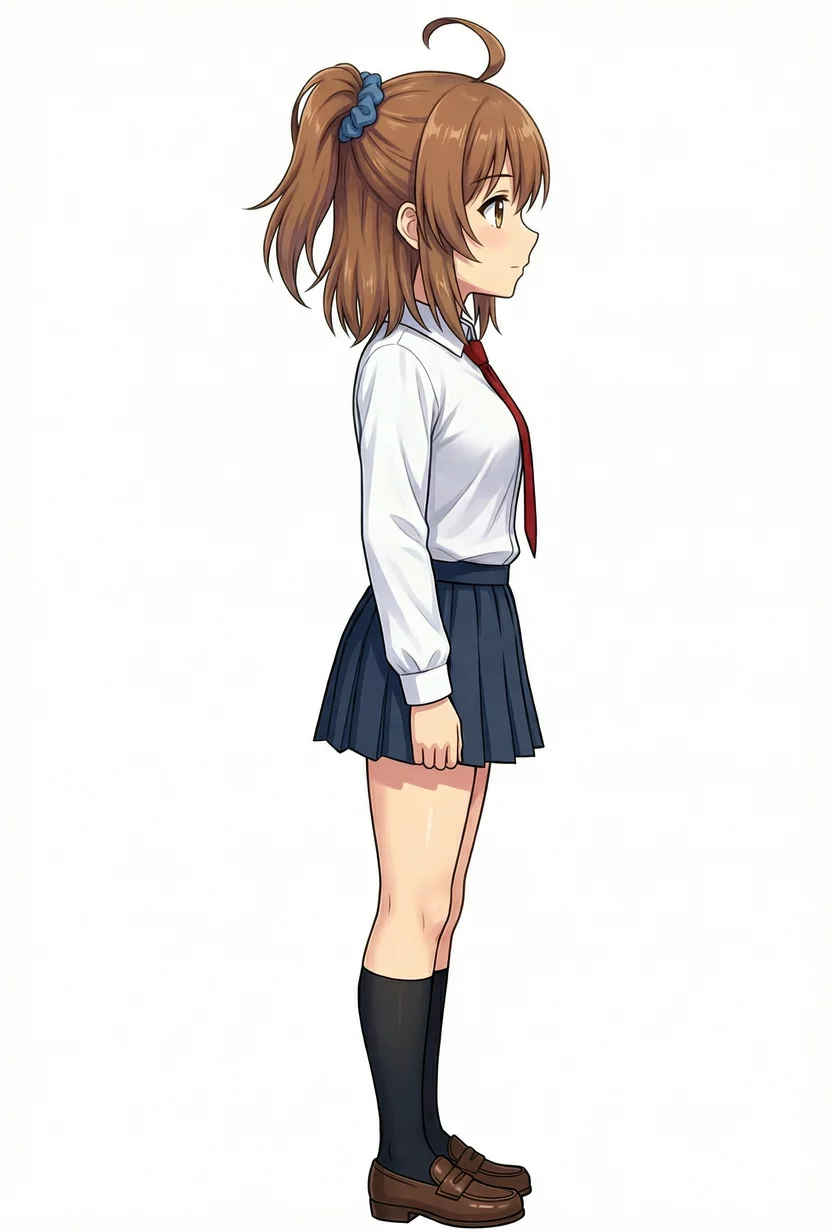
| Condition | Image Observations |
|---|---|
| Sprinting (3 References) | Nearly identical composition to single-reference run; arm swing inversion remained. |
| Right Profile (3 References) | Nearly identical profile; scrunchie visible over crown from far side. |
| Left Profile (3 References) | Same as single reference; scrunchie maintained high position behind ear. |
The expanded prompt adapted by assigning <Subject 2> to the hairstyle in <Picture 2> and <Picture 3>, instructing transfer onto <Subject 1>. The resulting outputs were virtually indistinguishable from single-reference generations.
However, feeding three high-res reference images pushed step latency to ~204 seconds, requiring 1359–1366 seconds for diffusion alone, in addition to 750–776 seconds for caption rewriting.
Rewritten Prompts with 3 Reference Images
Appended instruction:
<Picture 2> and <Picture 3> show the same girl's head from her left side and from a three-quarter left view; use them for where her side ponytail and blue scrunchie sit.Sprinting:
The girl in the white shirt, red tie, and blue pleated skirt in <Picture 1> is <Subject 1>. The left-side ponytail with blue scrunchie and ahoge in <Picture 2> and <Picture 3> is <Subject 2>. The target image shows <Subject 1> sprinting dynamically toward the viewer's left in a three-quarter view with a lean. <Subject 1> is partially preserved; her white shirt, red tie, and blue skirt remain identical while her pose shifts to an athletic run. <Subject 2> is fully preserved on her head; the specific hairstyle is transferred to match the new pose. <Subject 1> leans far forward, driving her right knee up high while her left leg pushes off the ground on her toes, with her left arm swinging forward and right arm swinging back with bent elbows. Her face turns approximately 45 degrees to the viewer's left, showing her profile. The brown hair flows with the motion against a plain white canvas background.Right profile:
The girl in <Picture 1> is <Subject 1>. She is wearing a white collared shirt with a red tie, a dark blue pleated skirt, and black knee-high socks with brown loafers. She has light brown hair with an ahoge on top and a blue scrunchie holding a ponytail. The target image shows the girl in an exact side profile full body shot facing the viewer's right, not looking at the camera. <Subject 1> is partially preserved; her uniform and facial features remain while her pose changes to a side profile. The new pose integrates the head orientation from <Picture 2> and <Picture 3>, placing the blue scrunchie and brown ponytail on the left side of the image, keeping the ahoge prominent on top of her head. Her profile is sharp and not looking at the viewer. The lighting highlights the side of her face and the folds of the skirt, consistent with the reference style.Left profile:
The girl in a white shirt, red tie, dark pleated skirt, and brown loafers in <Picture 1> is <Subject 1>. The side ponytail, blue scrunchie, and ahoge in <Picture 2> and <Picture 3> are <Subject 2>. The target image displays <Subject 1> as a full-body character turned to her left side profile, facing away from the camera. <Subject 1> is partially preserved; her pose shifts from front to profile while her uniform remains unchanged. <Subject 2> is partially preserved; its hairstyle is transferred to the head of <Subject 1>. In the target image, <Subject 1> stands with her left profile facing the viewer's left, her brown hair in a ponytail secured by a blue scrunchie and the characteristic ahoge curling from the top of her head, her gaze directed away from the camera, the side profile revealing the structure of her face and hair against the white background.User Instructions and Qwen3.5 9B Rewrites
Base suffix added to all 6 conditions:
Keep her face, her brown side ponytail tied with a blue scrunchie on her left side, the ahoge and her school uniform the same.Overhead instruction:
Show the girl in <Picture 1> from a strong high-angle overhead view: the camera is high above her looking steeply down, the ground fills the background, and she tilts her face up and looks into the camera.Overhead rewritten caption:
The anime girl with brown hair, a side ponytail with a blue scrunchie, and a school uniform in <Picture 1> is <Subject 1>. The target image depicts <Subject 1> from a strong high-angle overhead view where the ground fills the background. <Subject 1> is partially preserved; her facial features, hairstyle, and school uniform remain the same while her pose changes to tilt her face upward. <Subject 1> tilts her face up and looks directly into the camera from the steep high angle, with the ground filling the background below her. Her brown side ponytail tied with a blue scrunchie on her left side and her ahoge are clearly visible from above.Left profile instruction:
Show the girl in <Picture 1> in an exact side profile seen from her left side, full body, facing the viewer's left, not looking at the camera.Left profile rewritten caption:
The girl with brown hair in <Picture 1> is <Subject 1>. The target image shows <Subject 1> in a full-body side profile facing the viewer's left against a white background. <Subject 1> is partially preserved; her face, hair, and uniform are retained while her pose shifts to a profile view. She faces strictly to the viewer's left, not looking at the camera. Her brown side ponytail with a blue scrunchie on her left side and the ahoge are preserved in the side view. Her school uniform, white shirt with red tie, dark blue skirt, black socks, and brown shoes are kept the same.Right profile instruction:
Show the girl in <Picture 1> in an exact side profile seen from her right side, full body, facing the viewer's right, not looking at the camera.Right profile rewritten caption (seed 1):
The girl in <Picture 1> is <Subject 1>. The target image shows <Subject 1> in a full-body side profile facing the viewer's right with a neutral expression, not looking at the camera. <Subject 1> is partially preserved; her face, ahoge, school uniform, and hair accessories remain consistent in style and detail while her pose shifts to a profile view. In the side profile view, her brown side ponytail tied with a blue scrunchie is positioned on the left side of her head in profile, and the ahoge stands upright on top of her head.Rear view instruction:
Show the girl in <Picture 1> from directly behind, full body, with her face not visible.Rear view rewritten caption (seed 1):
The girl in <Picture 1> is <Subject 1>. The target image shows <Subject 1> from directly behind, full body, with her face not visible. <Subject 1> is partially preserved; her identity, uniform, and hairstyle remain consistent while her orientation changes. The back of her head displays the brown ahoge curling upward. Her brown side ponytail is tied with a blue scrunchie on her left side. Her white long-sleeved shirt is tucked into her dark blue pleated school uniform skirt, and her black knee-high socks and brown loafers are fully visible. A white background surrounds the figure.Jump instruction (with Keep the white background. appended):
Make the girl in <Picture 1> jump in mid-air facing the viewer: both feet off the ground, right knee pulled up high, left leg stretched down, right fist punching straight up and left arm swinging out to the side.Jump rewritten caption:
The girl with brown hair in a side ponytail secured with a blue scrunchie, featuring a curl on top of her head (ahoge), wearing a white long-sleeved shirt, red tie, dark blue pleated skirt, dark knee-high socks, and brown loafers in <Picture 1> is <Subject 1>. The plain white background in <Picture 1> is <Subject 2>. The target image depicts <Subject 1> in a dynamic mid-air jump facing the viewer against the preserved white background. <Subject 2> is fully preserved. <Subject 1> is partially preserved; her facial features, hair style including the blue scrunchie and ahoge, and full school uniform outfit remain unchanged, while her pose changes from standing to a jump. In the modified pose, both feet are suspended off the ground with the right knee pulled up high and the left leg extended downwards. Her right arm forms a fist punching straight up while her left arm swings out to the side.Sprinting instruction (with Keep the white background. appended):
Make the girl in <Picture 1> sprint toward the viewer's left in a three-quarter view, her body and face turned about 45 degrees to the viewer's left so her left side is visible: leaning far forward, right knee driven up high, left leg pushing off behind her on its toes, left arm swinging forward and right arm swinging back with bent elbows.Sprinting rewritten caption:
The girl in <Picture 1> with brown hair in a side ponytail secured with a blue scrunchie, a curly ahoge on top of her head, a white shirt, a red tie, a dark blue pleated skirt, black knee-high socks, and brown loafers is <Subject 1>. The target image shows <Subject 1> in a dynamic sprinting pose on a white background. <Subject 1> is partially preserved; her identity and clothing remain while her pose and orientation change to a forward lunge. She leans far forward facing the viewer's left, her body and face turned about 45 degrees to the viewer's left so her left side is visible. Her right knee is driven up high, her left leg pushes off behind her on its toes. Her left arm swings forward and her right arm swings back with bent elbows. Her face retains its original expression, her brown side ponytail tied with a blue scrunchie on her left side remains, the ahoge is kept, and her school uniform is unchanged. The white background remains.Background Rendering Detail (Cafe Scene)
In previous benchmark articles, Kana-chan was placed seated by a window in a cafe using LoRAs to test background architectural detail.
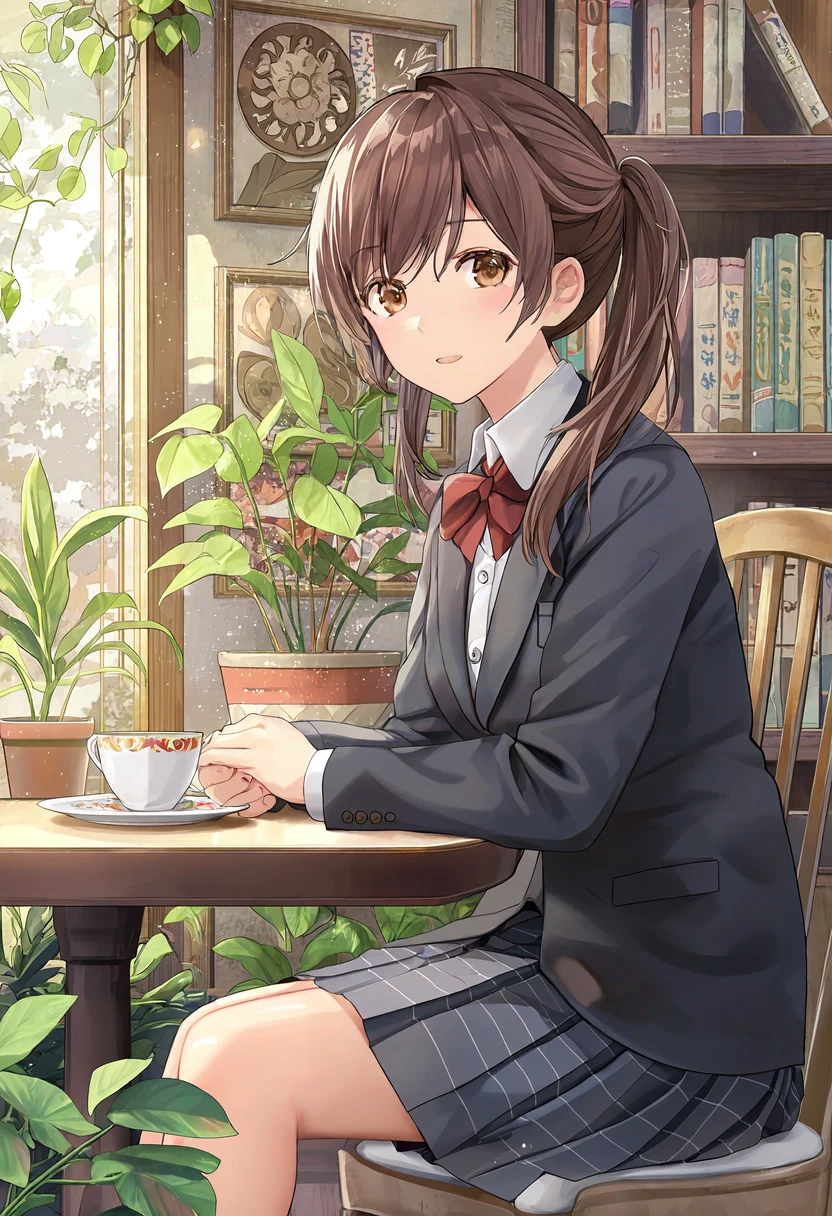
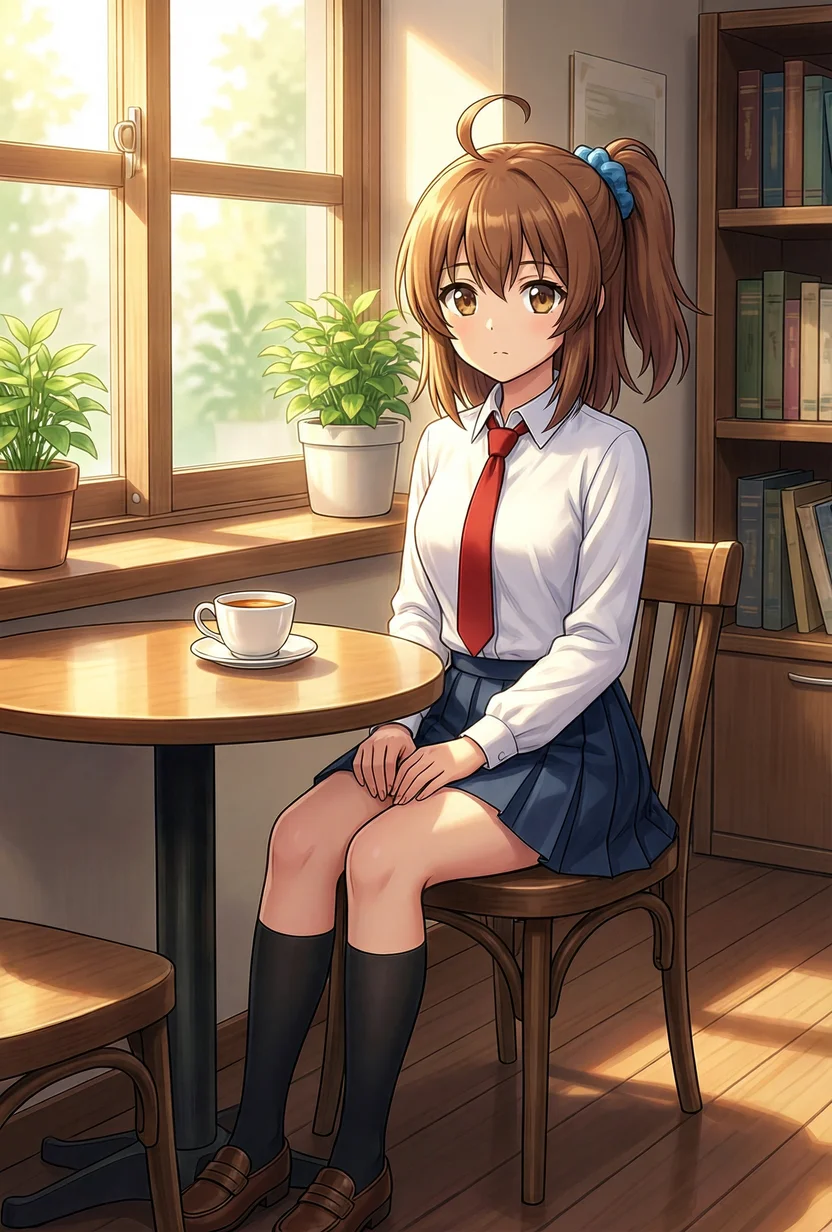
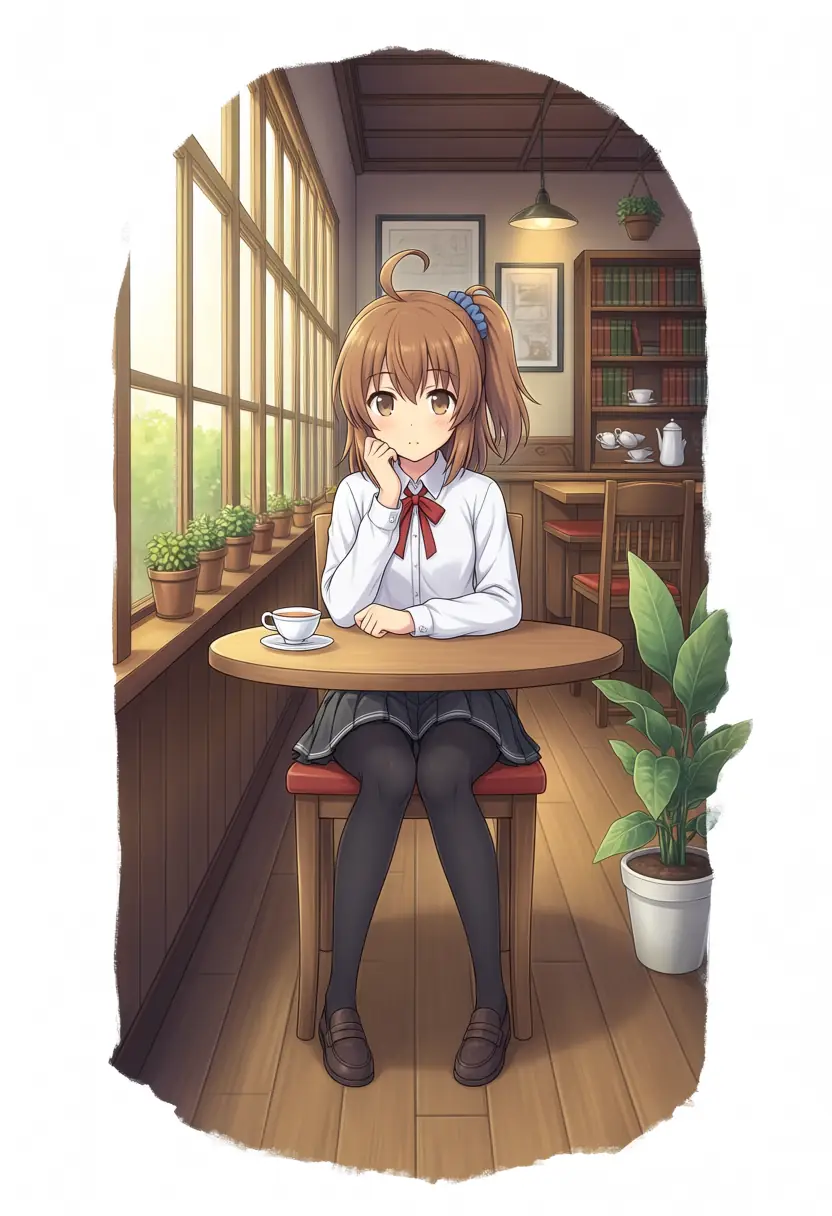
With MiniMax-H3-Image, I ran two tests: one using pure text prompting, and one providing the neutral standing portrait as a reference image through the official editing pipeline. For comparison, I included the Anima base (native steps with Kana-chan LoRA) output from my AMIXA vs Anima benchmark.
Text-Only (Current)
Reference Image (Current)
Kana-chan LoRA (Past Output)
| Output | Image Observations |
|---|---|
| MiniMax-H3-Image (Text-Only) | Seated profile by window with hand on teacup. Bookshelf and frames behind, potted plants framing scene. Outfit is a blazer and plaid skirt with an unprompted red bow tie. |
| MiniMax-H3-Image (Reference Image) | Seated on bentwood chair with hands resting on lap. Round table with cup, windowsill plants, bookshelf on right, sunlight across wooden floor. Scrunchie, tie, socks, and loafers faithfully preserved. |
| Anima base native | Seated at round table resting chin on hand. Potted plants, pendant lights, and distant seating rendered in detail. Frame edges washed out into an elliptical white vignette. |
Both MiniMax-H3-Image outputs rendered edge-to-edge background details without the oval vignette observed in Anima base.
With the reference image, Kana-chan’s character features and school uniform were preserved while correctly composing the window, bookshelf, plants, and teacup. Execution took 295.51s for pure text, while reference editing required 638.3s for prompt rewriting and 856.44s for diffusion.
Prompt
Tags used for Anima base:
masterpiece, best quality, safe, 1girl, solo, kanachan, brown hair, side ponytail, ahoge, brown eyes, school uniform, sitting at a cafe table by the window, potted plants, bookshelf, teacup, warm afternoon sunlight, detailed background, intricate details, looking at viewerMiniMax-H3-Image (Text-Only):
An anime illustration of a single girl with brown hair in a side ponytail and brown eyes, wearing a school uniform, sitting at a cafe table by the window and looking at the viewer. A teacup sits on the table, potted plants and a bookshelf fill the room, and warm afternoon sunlight comes through the window. Detailed background with intricate details.MiniMax-H3-Image (Reference Image Instruction):
Have the girl in <Picture 1> sit at a cafe table by the window and look at the viewer, with a teacup on the table, potted plants, a bookshelf and warm afternoon sunlight, with a detailed background. Keep her face, her brown side ponytail tied with a blue scrunchie on her left side, the ahoge and her school uniform the same.MiniMax-H3-Image (Reference Image Rewritten Caption):
The girl in <Picture 1> is <Subject 1>. The target image shows <Subject 1> seated at a small round cafe table near a large window, maintaining eye contact with the viewer. <Subject 1> is partially preserved; her identity, facial features, brown side ponytail tied with a blue scrunchie, ahoge, and school uniform remain the same, while her pose changes to sitting and the background is replaced with a detailed cafe scene. <Subject 1> sits comfortably on a chair with her legs bent, her hands resting loosely, maintaining her neutral expression. A white porcelain teacup sits on the small wooden table in front of her. The background features a detailed cafe interior with warm afternoon sunlight streaming through the window, illuminating her brown hair and uniform with soft golden highlights. Green potted plants sit on a windowsill behind her, and a wooden bookshelf filled with colorful books stands in the corner of the room. The lighting casts gentle shadows on the table and her legs.Image-to-Image (WAI-IL to MiniMax-H3-Image)
In the April benchmark, a standing illustration generated by WAI-Illustrious v160 with Kana-chan LoRA was passed to Anima models via i2i at denoise 0.5.
Denoise controls how much noise is injected into the latent image before sampling; at 0.5, half of the latent noise schedule is applied.
Since MiniMax-H3-Image supports both reference editing and conventional diffusion latent input, I tested both approaches on the same source image.
| Method | Input | Setup |
|---|---|---|
| Reference Image Editing | Official template flow. Short instruction “redraw as a new illustration” rewritten by Qwen3.5 9B with source passed as <Picture 1> | denoise 1.0, 1664×2464 |
| denoise 0.5 i2i | Encode source into latent space via VAE, sample with descriptive prompt | denoise 0.5, 1664×2432 |
Both used seed 42. The source image is 832×1216, featuring a character standing in front of a large golden circle with a blue scrunchie.
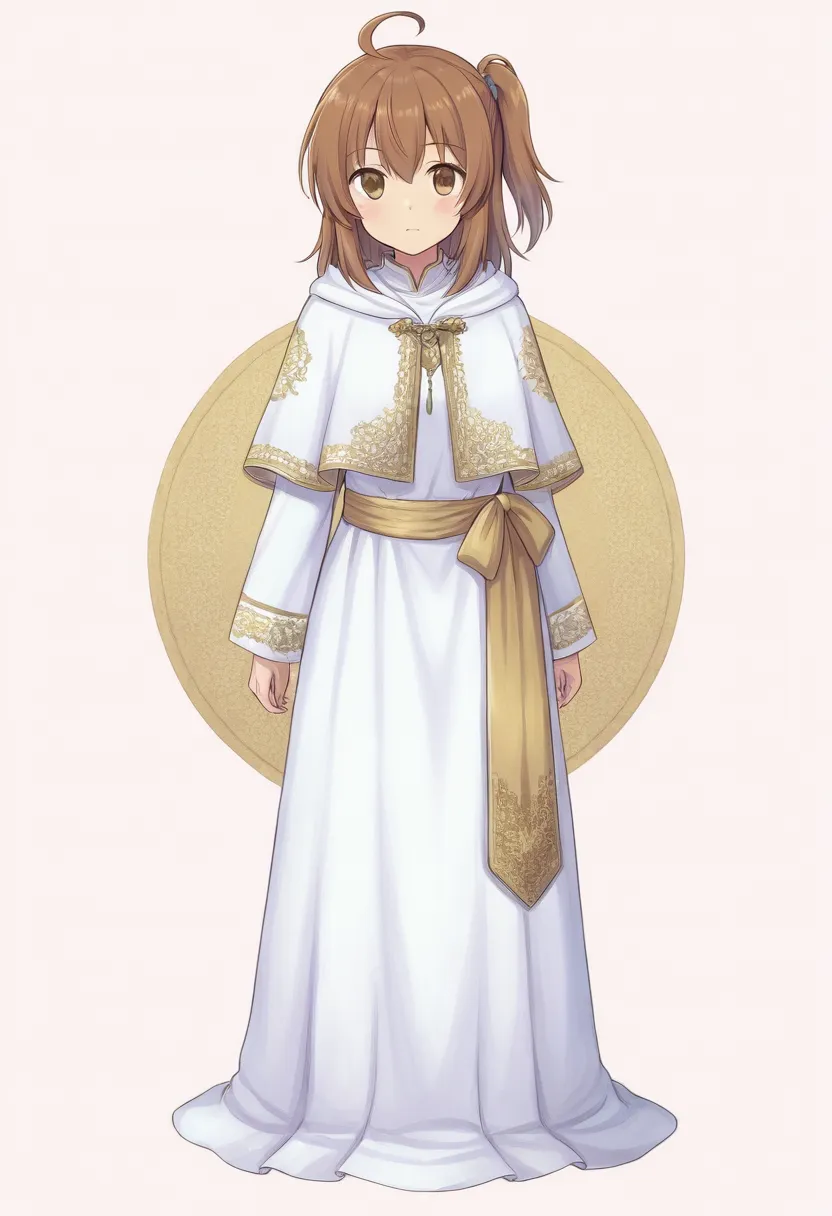
Reference Editing
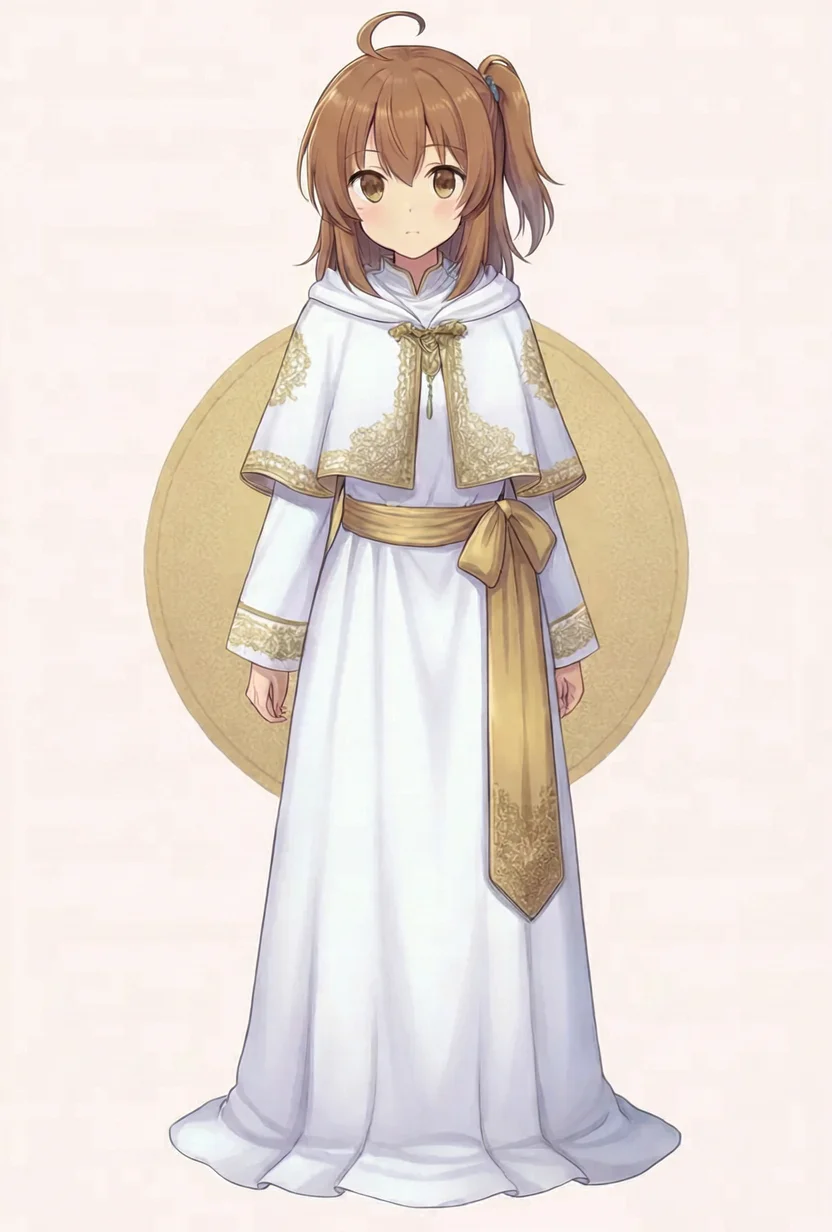
denoise 0.5
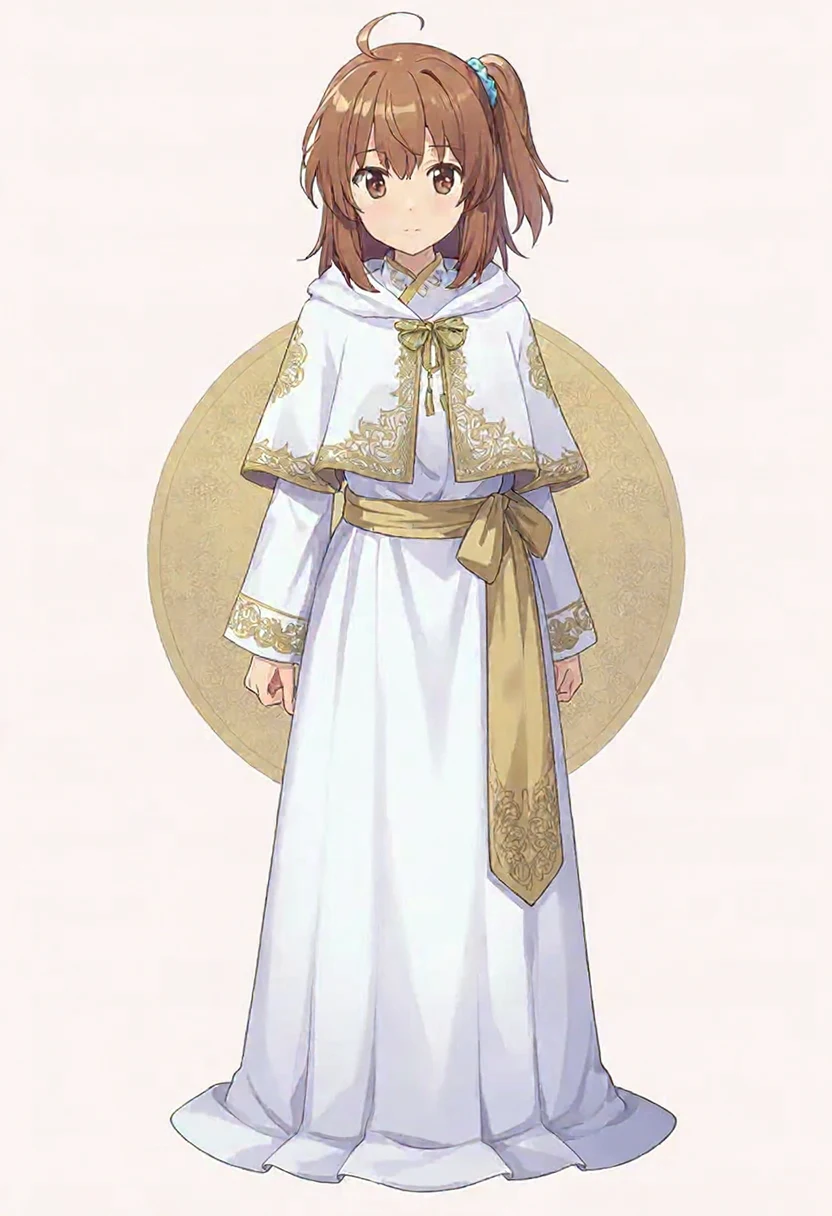
(Past Output)
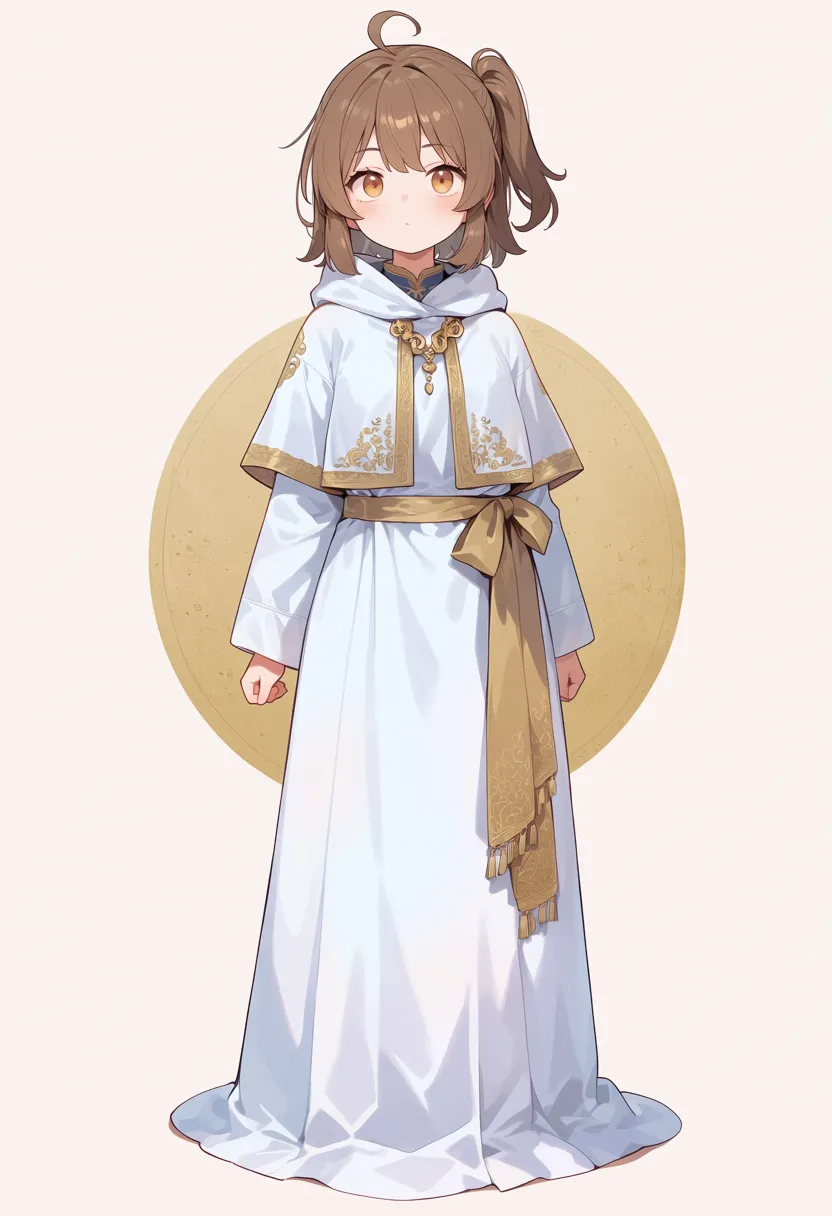
(Past Output)
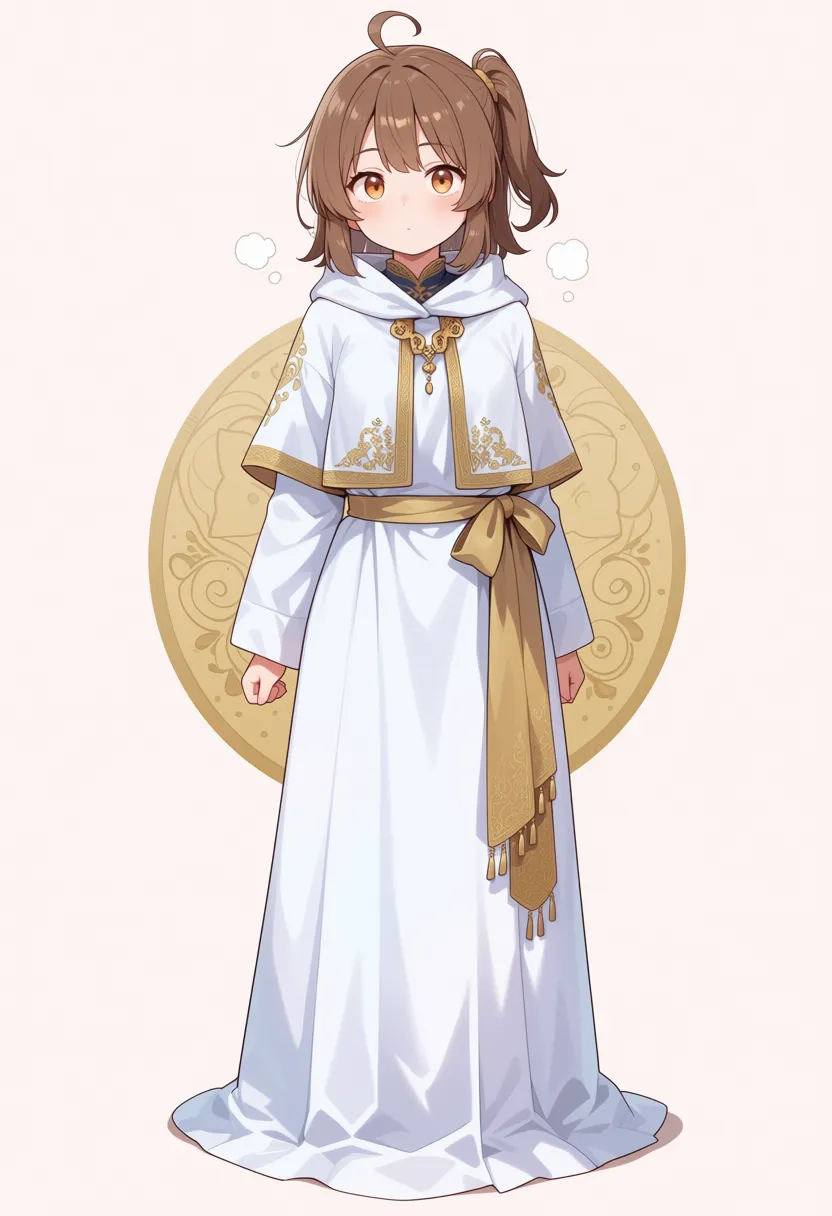
| Model | Image Observations |
|---|---|
| MiniMax-H3-Image (Reference Editing) | Facial structure, brown hair, ahoge, side ponytail, small blue scrunchie, capelet, gold sash knot, and the gold circular background were preserved. Background hue took on a subtle pinkish cast. |
| MiniMax-H3-Image (denoise 0.5) | Overall composition, face, and background circle were preserved almost intact. Collar metal clasp shifted to a ribbon knot, scrunchie turned teal. Lines became crisper with brighter palette. |
| Anima preview3-base | Face became rounder and noticeably younger. Fringes added to sash, scrunchie mostly disappeared. Background circle lost definition. |
| WAI-Anima v1 | Facial geometry rounded similarly to preview3-base. Scrunchie altered color, while the circle gained intricate geometric patterns. White artifact haze appeared beside the mouth. |
MiniMax-H3-Image maintained face proportions under both workflows, avoiding the infantilized rounding seen in Anima models.
In my previous Qwen-Image 2.1 benchmark, reference image editing caused the background circle to vanish, whereas MiniMax-H3-Image preserved it.
Reference editing took 879.2s for prompt rewriting and 854.41s for diffusion. The rewritten caption mistakenly described the hair as twin pigtails, yet the diffusion output adhered to the visual reference and rendered a single side ponytail.
denoise 0.5 completed in 315.41s.
When denoise is below 1.0, ComfyUI’s KSampler schedules steps as steps / denoise (here 12 steps), running only the final 6 steps. MiniMax-H3-Image linearly interpolates between the 6 distillation sigma values.
Calculating the schedule, denoise 1.0 evaluates at σ=1.0, 0.9677, 0.8877, 0.75, 0.5336, 0.2326, 0, aligning with the distillation steps. At denoise 0.5, the schedule shifts to σ=0.75, 0.6418, 0.5336, 0.3824, 0.2326, 0.1169, 0, landing three evaluation points between the distilled checkpoints.
Despite interpolating intermediate sigmas, the image converged cleanly without visual degradation.
Prompts Used for i2i
Reference Image Instruction:
Redraw <Picture 1> as a new illustration, keeping the girl, her face, hairstyle, outfit, pose, the composition and the gold circle background the same.Reference Image Rewritten Caption:
The anime girl with brown hair styled in twin pigtails and a single curl atop her forehead in <Picture 1> is <Subject 1>, featuring large golden-brown eyes and a white hooded robe adorned with intricate gold embroidery on the collar, cuffs, and hood, fastened with a long gold sash tied in a bow at the waist. The large gold circular disk positioned behind her in <Picture 1> is <Subject 2>. The target image presents the same scene redrawn as a fresh illustration while maintaining the original composition. <Subject 1> is fully preserved. <Subject 2> is fully preserved.denoise 0.5 Prose Prompt:
An anime illustration of a girl with brown hair in a side ponytail tied with a blue scrunchie, wearing a white robe with gold embroidery, a capelet and a gold sash, standing in front of a large golden circle.Generation Speed and Memory Usage
Adding MiniMax-H3-Image and Qwen-Image 2.1 to the speed comparison table from April:
| Model | Resolution | Steps | Standing | Running | Per-Step (Standing) |
|---|---|---|---|---|---|
| MiniMax-H3-Image (GGUF Q4_K_M) | 1664×2432 | 6 | 299s | 305s | ~47s |
| MiniMax-H3-Image (GGUF Q4_K_M) | 832×1216 | 6 | 117s | - | ~16s |
| Qwen-Image 2.1 | 832×1216 | 40 | 588s | 584s | ~14.7s |
| Anima preview3-base | 832×1216 | 30 | 275s | 277s | ~9.2s |
| WAI-Anima v1 | 832×1216 | 30 | 277s | 274s | ~9.2s |
| WAI-Illustrious v160 | 832×1216 | 25 | 217s | 337s | ~8.7s |
MiniMax-H3-Image times reflect steady-state runs after the model is loaded, encompassing text encoding, sampling, and VAE decoding.
While per-step computation is much heavier than Anima, 6-step distillation means generating a 4× higher pixel count (4MP) takes comparable wall-clock time to 30-step Anima runs at 1MP.
| Generation Type | Peak Memory (phys_footprint) | System Swap (Start → End) |
|---|---|---|
| README Sample 2048×2048 (Initial Load) | 21.0GB | 3788.56MB → 3764.56MB |
| Standing, Running, NSFW 1664×2432 | 25–27GB | No increase |
| Reference Editing Pipeline 1664×2464 (Post-Rewrite Generation, 15 Runs) | 44–46GB | No per-image increase (~20–25GB baseline) |
Memory polling at 1-second intervals may smooth out transient sub-second allocation spikes.
Text-to-image runs showed no swap growth.
In reference editing, sequentially loading Qwen3.5 9B (BF16) and Qwen3-VL 32B in the same ComfyUI session elevated peak memory to 44–46GB. System swap hovered around 20GB throughout the session and did not grow per generation. All 15 runs finished without crashing.
Editing turnaround took 638–900s for caption rewriting and 842–868s for image generation, totaling 25–30 minutes per finished image. Reusing an existing caption and only changing the generation seed took 786s and 796s.
Practical Use-Case Matrix
Based on observed outputs across tests:
| Use Case | Recommended Model | Rationale |
|---|---|---|
| Strict garment color palette control | MiniMax-H3-Image | White and gold prompts produced no color bleed or unrequested accessory hues. |
| Typography and poster design | MiniMax-H3-Image | Rendered both English lettering and complex Japanese typography (Kanji, Kana, numbers) cleanly. |
| Deriving varied poses from a single portrait | MiniMax-H3-Image | Maintained face, attire, and asymmetrical scrunchie geometry across all 6 angles. Takes 25–30 min/image. |
| Re-rendering without altering facial structure | MiniMax-H3-Image | Preserved face geometry and background elements across both editing and denoise 0.5 workflows. |
| Fast generation of smaller ~1MP images | Anima series / WAI-Illustrious | MiniMax-H3-Image suffered hand deformities when dropped to 832×1216. |
| Leveraging existing anime character LoRAs | Anima series / WAI-Illustrious | Existing LoRAs are trained for SDXL/Anima/Illustrious and are incompatible with MiniMax-H3-Image. |
NSFW Output Evaluation
Test outputs in this section may be sensitive and are blurred for display. Verify locally for unblurred evaluation.
I tested the same two prompts used in the April benchmark, translated into English prose at 1664×2432 with seed 42.
Without NSFW Keyword
Prompting for complete nudity without including explicit keywords like nsfw.
(Current)
(Past Output)
(Past Output)
(Past Output)
| Model | Image Observations |
|---|---|
| MiniMax-H3-Image | Generated in a thick semi-realistic style. Character sits on a rock with feet in water; breasts exposed, groin occluded by pose. |
| Anima preview3-base | Full nudity, but pose occludes breasts and groin. |
| WAI-Anima v1 | Full nudity, but pose occludes breasts and groin. |
| WAI-Illustrious v160 | Full nudity, but pose occludes breasts and groin. |
This prompt omitted style tags (matching the April test). While standing and running prompts included An anime illustration, this run defaulted to a semi-realistic aesthetic. Generation time was ~300s.
Prompt
Tags used for April models:
1girl, solo, long blonde hair, blue eyes, completely nude, naked, bare skin, sitting on edge of spring, feet in water, forest, natural light, serene, full body, looking at viewerMiniMax-H3-Image English prompt:
An illustration of a single girl with long blonde hair and blue eyes, completely nude with bare skin, sitting on the edge of a spring with her feet in the water, in a forest under natural light. The mood is serene. She is shown in full body and looks at the viewer.With NSFW Keyword (Full-Body Frontal)
Explicit prompt with nsfw requesting a frontal standing pose.
(Current)
(Past Output)
(Past Output)
(Past Output)
| Model | Image Observations |
|---|---|
| MiniMax-H3-Image | Anime-leaning semi-realistic standing nude against plain white. Nipples depicted; groin rendered with smooth contour lines. No watermark or lettering. |
| Anima preview3-base | Frontal nude with western comic art style; face and proportions differ from standing prompt. |
| WAI-Anima v1 | Frontal nude resembling character from standing prompt, with enlarged bust and @Pagex.com watermark in lower right. |
| WAI-Illustrious v160 | Frontal nude visually consistent with standing and running outputs. |
Generation time was ~300s. Neither prompt triggered safety filters, black image outputs, or execution crashes.
Prompt
Tags used for April models:
1girl, solo, long blonde hair, blue eyes, completely nude, naked, bare skin, nsfw, straight-on, full body, standing, white backgroundMiniMax-H3-Image English prompt:
An NSFW illustration of a single girl with long blonde hair and blue eyes, completely nude with bare skin, standing and shown in full body from a straight-on front view against a plain white background.Reference Links
- MiniMax-H3-Image (Official Model Card)
- Abiray/MiniMax-H3-Image-GGUF
- Abiray/MiniMax-H3-GGUF (Text Encoder GGUF)
- Comfy-Org/MiniMax-H3-Image
- ComfyUI MiniMax-H3-Image Tutorial
- ComfyUI-GGUF
- MiniMax-H3-Image Editing Prompt Example (revised_prompt.edit.txt)
- MiniMaxAI/MiniMax-H3-Image-PE
- Comfy-Org/Qwen3.5
- Comfy-Org/workflow_templates
- WAI-Anima v1 vs WAI-Illustrious on M1 Max ComfyUI
- Qwen-Image 2.1 Local on M1 Max vs Anima