A full-stack serverless CMS built on Astro 6.0, EmDash tries to solve WordPress's long-running plugin security problem with V8-isolate plugin sandboxing.
How Copilot CLI's `/fleet` command works and how to use it: it automatically splits tasks, dispatches subagents in parallel, and schedules them while respecting dependencies.
Hugging Face's LLM post-training library TRL has reached v1.0. Stable/Experimental tiers, the stabilization of GRPO/DPO/SFT, and a roadmap that includes asynchronous GRPO all point to a more mature stack.
Tested See-through (SIGGRAPH 2026), which decomposes a single anime character image into a 23-layer PSD with front/back hair separation and hidden-area inpainting. What the Live2D prep actually looks like and what still needs manual work.
Adobe CC's WAM component silently adds a detect-ccd.creativecloud.adobe.com entry to the Windows hosts file and uses it to detect installations from the browser. A breakdown of the mechanism and the broader pattern of major software taking control away from the OS and the user.
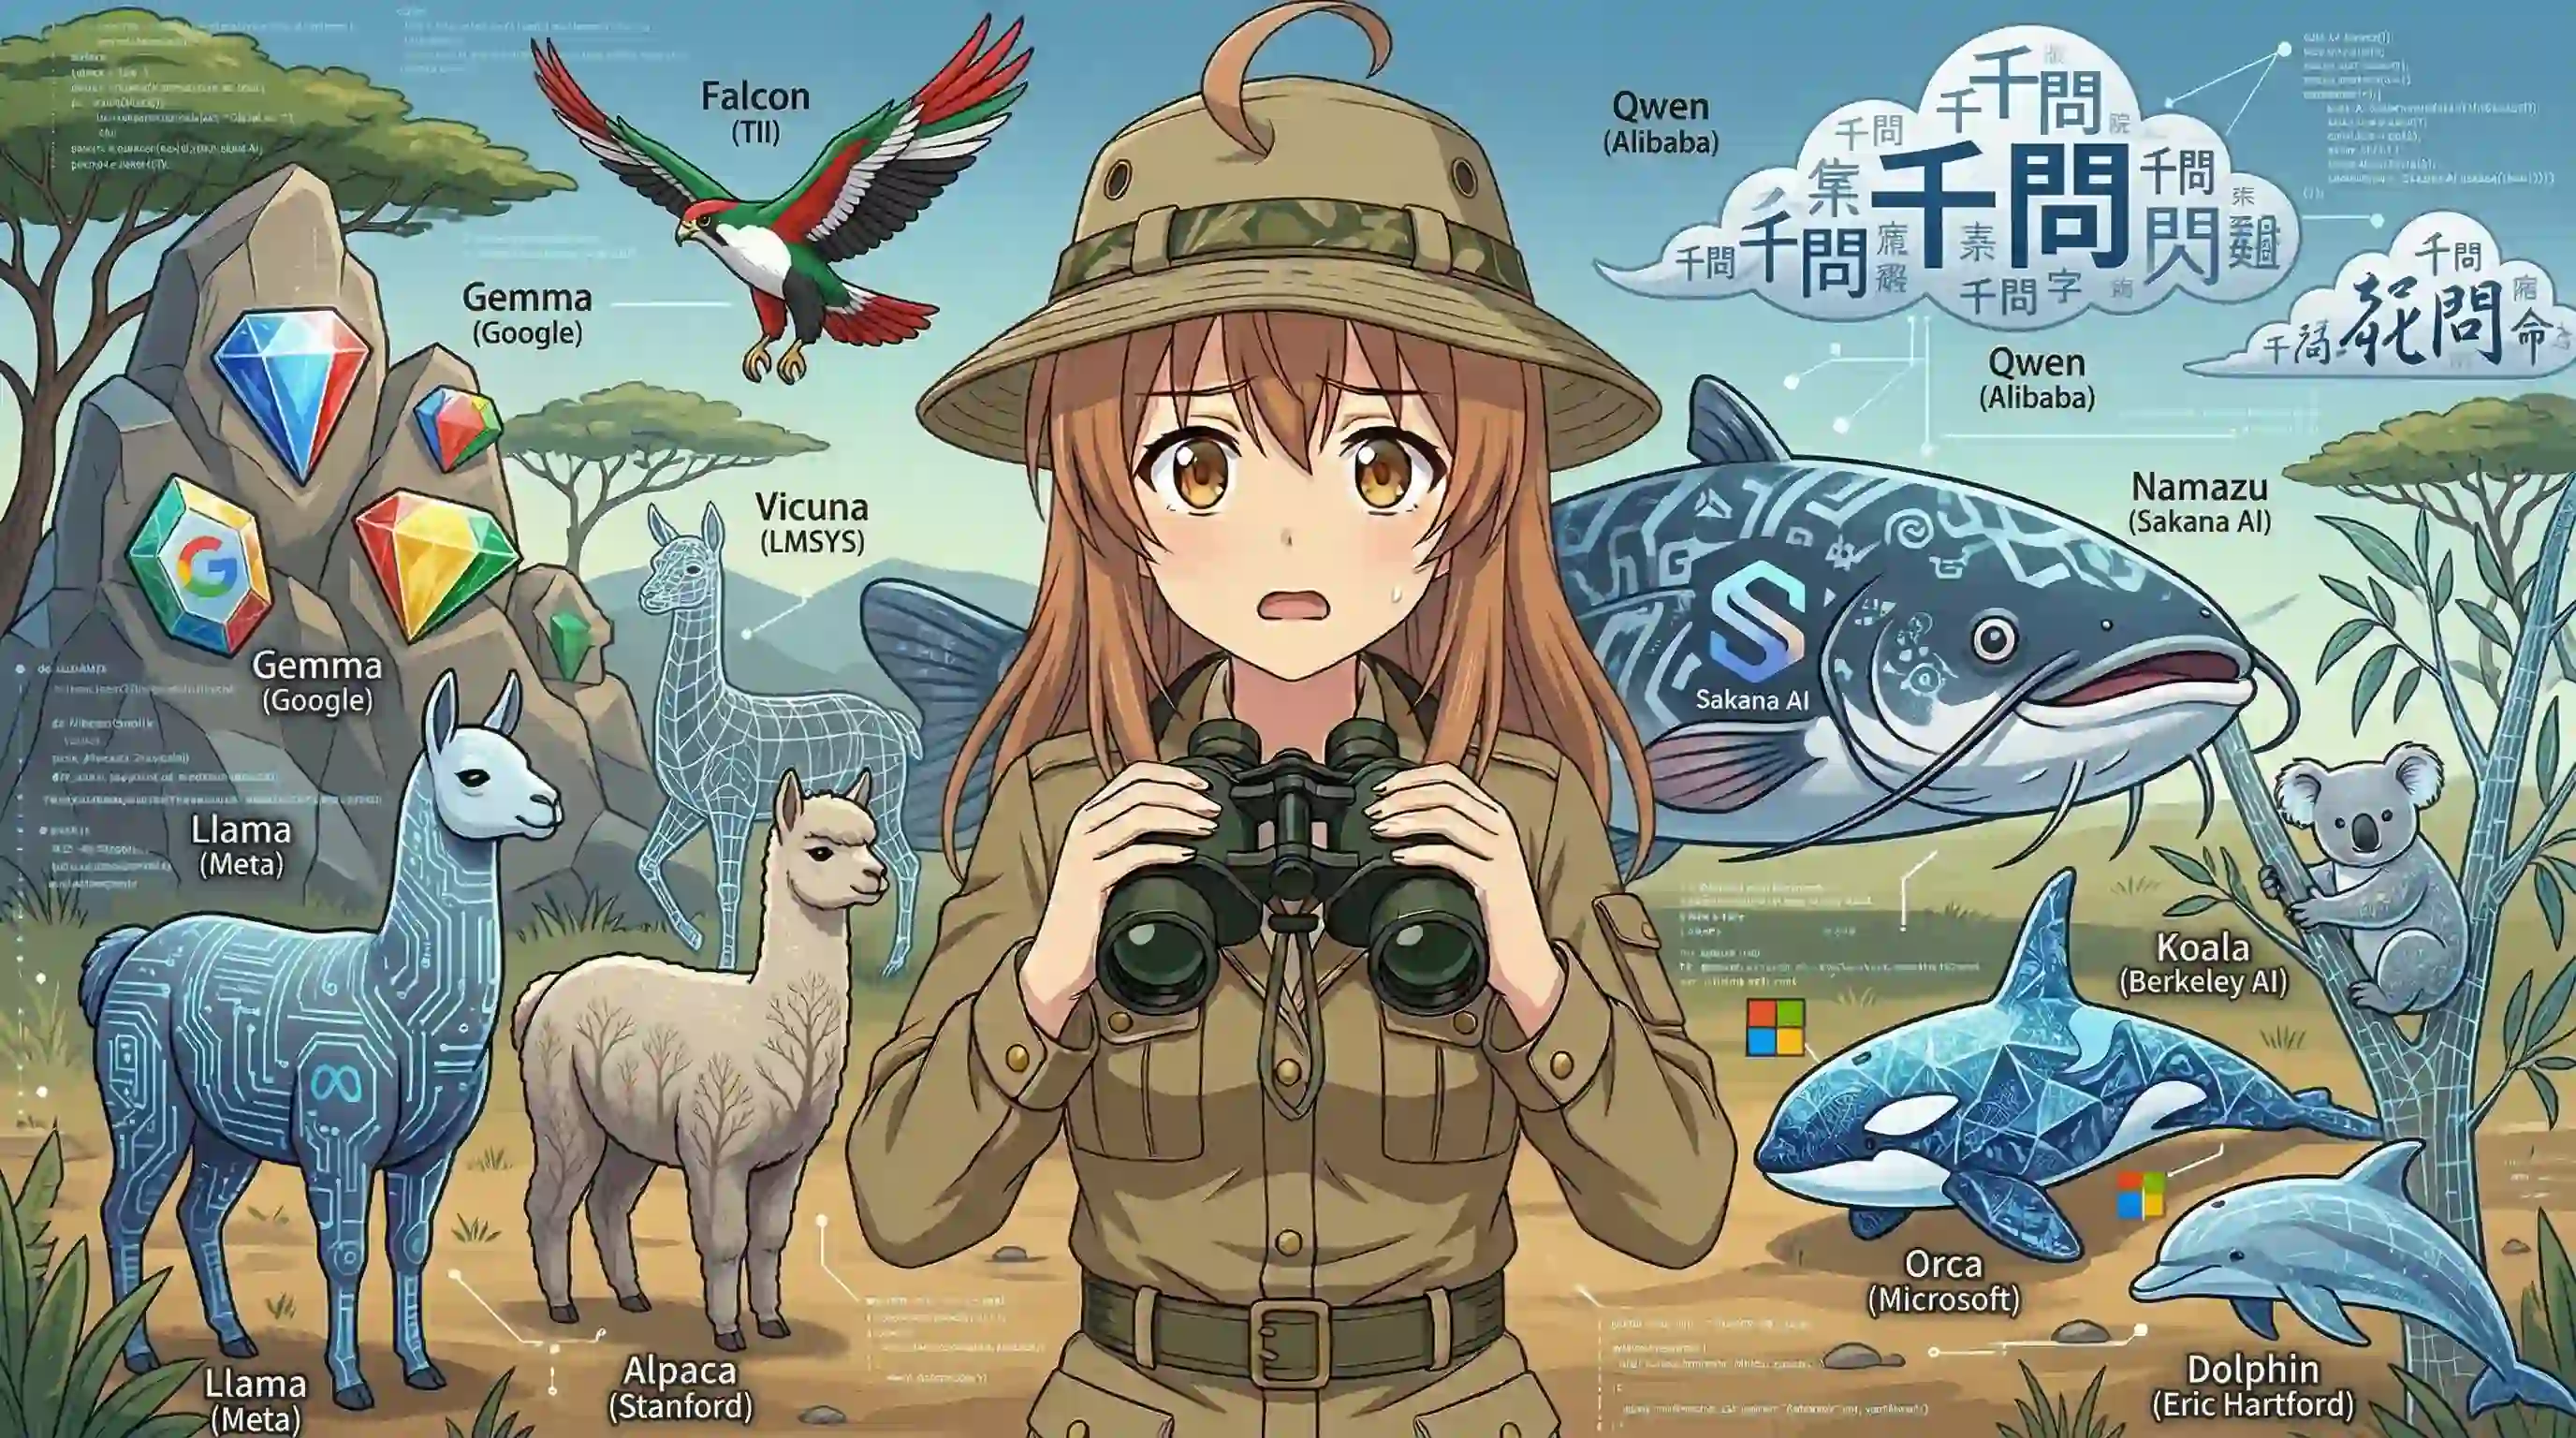
For the generation that hears Sakana AI's Namazu and thinks of the old full-text search engine, this is a collection of cases where software and service names collide with something else entirely.
A summary of how source maps bundled in the Claude Code npm package made over 510k lines of TypeScript visible, and how a branch-name command injection in OpenAI Codex could have allowed theft of GitHub tokens.
Cloudflare added a two-stage GNN+LLM cascade to its client-side malicious script detection, reducing false positives per unique script from 1.39% to 0.007% and opening the formerly paid Advanced features to self-serve customers.
A fake dependency plain-crypto-js was injected into axios 1.14.1 and 0.30.4 to install a RAT dropper via a postinstall hook. Complete attack chain from maintainer account compromise to C2 communication and self-deletion.
Ollama 0.19 switches the Apple Silicon backend to MLX, achieving 1,810 tokens/s prefill and 112 tokens/s decode. NVFP4 quantization support and cache improvements landed at the same time.
Only 10 of 40 layers use KV cache, so raising llama-server ctx-size from 4096 to 65536 cost 800MB VRAM and no throughput. Measured on Ryzen AI Max+ 395.