Hands-on evaluation of Qwen-Image 2.1 early access on ModelScope Studio. Testing 10 camera composition presets, 4-member band role assignments, I2I orientation and outfit changes, and where multi-character consistency breaks down.
Tested on an RTX 3050 Ti Laptop: Qwen3.8-Omni-Flash handles audio input directly, shrinking our voice chat server RSS from 1,327MB to 118MB with zero idle warmup lag.
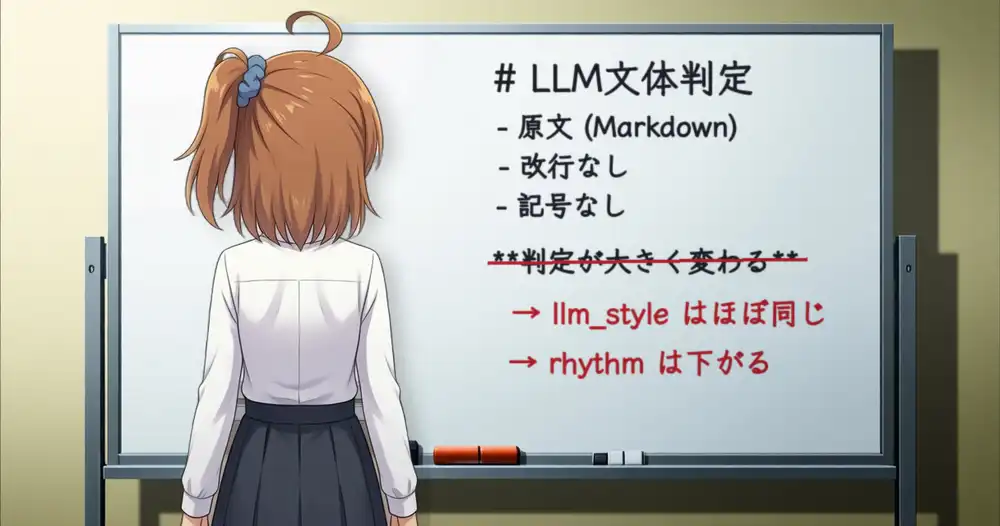
We tested TypeSafe AI's Jev across raw Markdown, stripped newlines, and plain text to examine whether LLM style scores shift. Even across multi-model rubrics from Claude, Gemini, and Qwen, the gap remained remarkably consistent.
Tested with 16 memories and 10 questions: a date bonus on cosine got the 9/9 memory and a 0.441 café-au-lait memory over the 0.45 cutoff, with 0.016 headroom left on hit-free questions.
Ryzen 7 5800HS test before StackChan: subject-less memories got claimed by the character, a 0.45 cosine threshold flipped on a comma, and ModelScope's embedding API vanished mid-test.
Qwen3-Embedding-0.6B on CPU vs ModelScope's API on a Ryzen 7 5800HS voice server. Local embedding adds up to +2.6s per voice turn by competing for CPU; the API adds none.
Tested Qwen3-Embedding-0.6B on CPU and Qdrant's local mode, then checked the 1.5-1.7GB RAM footprint against a Ryzen 7 5800HS voice server with only 4GB VRAM.
Tested on M1 Max 64GB with plain Anima-Base v1.0. A red-to-blue residual direction added to one of Blocks 24-27 flips a flat image, but on a hair mask it paints a blue slab. No hair-only direction found.
A pre-implementation design for adding Qwen3-Embedding and Qdrant memory to an RTX 3050 Ti and CoreS3 voice-chat stack without depending on StackChanWorld's API. It keeps raw logs, searchable memory, persona, and body separate.
My ModelScope account switched from a monthly API-Inference quota to Magicube coins, so I measured what each call costs. Qwen-Image, Z-Image, Krea-2-Turbo and FLUX worked even though none of them appeared in the /v1/models list I got; of the embedding IDs I tried only Qwen3-Embedding went through; audio paths were 404 and Wan produced no video. In these tests 400s and 404s cost nothing, while a 200 with an empty body was charged.
Tested on EVO-X2 (gfx1151) under Windows + ROCm: the official b10666 binary runs it at pp512 159.25 / tg128 23.26, and the earlier crash was my own workaround flag.
Traced across 31 blog posts and 464 Hugging Face repos: Qwen's capybara debuted Oct 11, 2024, hit blog banners in Jan 2025, and its own edit prompts all say 'the bear'.