Testing TinAnima29B 4steps INT8 on M1 Max: 12 Images with No Character Prompt Produced the Same Face
 Contents
On November 13, 2026, a 4-step INT8 model based on Anima 2.9B titled “TinAnima29B_v1_4steps_INT8” was published on Civitai.
Browsing through several sample images, I noticed that despite different hair colors and clothing, the facial features looked remarkably similar.
It felt reminiscent of what was once called the “masterpiece face” back in the SD 1.5 and NovelAI eras—a default face that models drifted toward when quality tags were added.
The official Anima model card highlights flexibility and diversity as key strengths of the Base model.
So, does this derivative produce the exact same face even when no character tags are specified?
Including the negative prompt instructions provided by the author, I first verified that I could reproduce the author’s sample images locally, and then generated outputs using the same test criteria as my article comparing the 2.9B version of One obsession.
Basic Information and Recommended Settings
On November 15, 2026, I checked the model page and Civitai API details.
| Item | Details |
|---|---|
| Model | TinAnima29B_v1_4steps_INT8 2D Effect |
| Author | tin18688783 |
| Release Date (UTC) | November 13, 2026 |
| Base Model | Description says “Anima 2.9B model” (an unofficial layer-expanded version of official Anima 2B). Civitai base model field says “Illustrious” |
| Files | DiT weights only, INT8, 3.33 GB. The text encoder (qwen_3_06b_base) and VAE (qwen_image_vae) are also hosted on the same page |
| Download | Civitai login required. Downloaded via browser and verified SHA256 against listed hashes |
Although Civitai lists the base model as “Illustrious”, inspecting the safetensors header reveals 40 DiT blocks (numbered 0 to 39), identical to Anima-2.9B.
The 2.9B version of One obsession also showed this same display, so I suspect it is simply due to limited base model category choices when registering Anima 2.9B on Civitai.
The accompanying text encoder and VAE have matching SHA256 hashes with the original files distributed by CircleStone Labs, confirming they are unmodified.
The author’s recommended settings gathered from the description and sample metadata:
| Item | Description | Author Samples (88 images) |
|---|---|---|
| Sampler | Euler (ER SDE) | ER SDE: 52 images, Euler: 36 images. All use Simple scheduler |
| Steps / CFG | 4+ / 1+ | All 4 / 1 |
| Resolution | 1024×1536 | All 1024×1536 |
| Positive Prompt | English natural text (like Z-Image) or Danbooru comma-separated tags (like SD 1.5) | All 79 samples with prompts use comma-separated Danbooru tags. Zero samples contain quality tags like masterpiece or score_9 |
| Negative Prompt | worst quality, low quality, score_1, score_2, score_3, artist name (artist name optional) | None (0 samples) |
| Performance / Other | ~5.5s for 1024×1536 4-step on RTX 3060 12GB using Forge Neo | Forge Neo, Shift 1 |
Interestingly, while the description specifies a negative prompt, none of the author’s 88 samples include any negative prompt.
This behavior relates to how CFG 1 operates, which I verified in a later section.
Creation Workflow
ComfyUI workflow metadata was left intact inside the safetensors file:
| Step | Node | Configuration |
|---|---|---|
| 1 | UNETLoader | A5.safetensors |
| 2 | LoraLoaderModelOnly | A15_29B.safetensors at strength 1.0 |
| 3 | LoraLoaderModelOnly | 20260716_TinAnimaCharactersLora_29B.safetensors at strength 0.4 |
| 4 | LoraLoaderModelOnly | 20261103_TinAnimaWomanLora_29B.safetensors at strength 0.4 |
| 5 | ModelSave | Saved as TinAnima29B_v1_4steps |
The same workflow also contained an INT8 save node, but it was left disabled.
I assume the INT8 quantization conversion was performed separately.
What the base model “A5” and strength 1.0 LoRA “A15_29B” actually are is not disclosed on the model page or in any other releases by the author.
The fact that character and woman LoRAs bearing the author’s name were merged at strength 0.4 each is relevant to the facial consistency experiments below.
Why this model can generate complete images in just 4 steps could not be determined from the model page.
Official Anima Turbo LoRA recommends 8 to 12 steps at CFG 1, and community Turbo models for 2.9B recommend 8 steps.
Licensing
The underlying base, Anima-2.9B, is not an official release from CircleStone Labs.
It is an unofficial community derivative where Gazingstars123 expanded official Anima (2B, 28 blocks) to 40 blocks and trained the 12 added blocks. Its license is the same CircleStone Labs Non-Commercial License as official Anima.
| Component | License | Commercial Use |
|---|---|---|
| Anima / Anima-2.9B | CircleStone Labs Non-Commercial License v1.2 | Model non-commercial only. Generated images can be used commercially. Individuals acting independently may sell derivative models |
| Cosmos-Predict2 (Anima upstream base) | NVIDIA Open Model License | Allowed, provided license text and notices are included |
| Qwen3-0.6B-Base, Qwen-Image (VAE) | Apache-2.0 | Allowed |
In contrast, TinAnima’s Civitai license toggles permit everything: selling generated images, generation services on Civitai and third-party platforms, selling the model, selling merges, requiring no attribution, and redistributing under different licenses.
Comparing this against the underlying base license reveals several discrepancies:
| Civitai Display | Underlying Base License |
|---|---|
| Commercial generation services allowed (Rent) | Anima model card explicitly lists hosting the model on commercial generation services as unauthorized |
| Selling the model allowed (Sell, SellMerge) | Sales are limited strictly to individuals acting as independent creators |
| Redistribution under different licenses allowed | Requires including license text and attribution notices; downstream terms cannot conflict with or restrict granted rights |
| No attribution required | Attribution Notice is mandatory. NVIDIA’s upstream license also requires attribution |
Allowing generation on Civitai (RentCivit) matches CircleStone’s own settings on the official Anima Civitai page.
The “no attribution” toggle is also identical on the official Anima Civitai page, reflecting Civitai’s somewhat coarse permission options.
When distributing or using TinAnima, one should rely on the underlying base license text rather than the Civitai display toggles.
Running on M1 Max
Because 40-block models cannot be loaded in my regular ComfyUI environment (v0.30.1), I used the v0.33.3 environment prepared in my article verifying Anima-2.9B LoRA compatibility.
The initial test run stopped immediately during sampler execution:
NotImplementedError: The operator 'aten::_int_mm' is not currently implemented for the MPS device.This INT8 safetensors file contains per-tensor quantization configurations: {"format":"int8_tensorwise","convrot":true,"convrot_groupsize":256}.
ComfyUI’s quantization library (comfy_kitchen) attempts to compute these linear layers using INT8 matrix multiplication (torch._int_mm).
This acceleration path is built for CUDA, and the current PyTorch MPS backend for Apple Silicon GPUs does not implement this operator.
When setting up this environment in August, I had patched around this issue.
However, when comfy_kitchen was updated to 0.2.31 in October, that patch was overwritten.
This time, I added a branch in comfy_kitchen/tensor/int8.py for linear layer processing: if the input tensor device is MPS, dequantize the weights back to bf16 and compute via standard linear layers.
# MPS patch: torch._int_mm is not implemented on MPS -> dequantize, bf16 linear
if input_tensor.device.type == "mps":
    return torch.nn.functional.linear(*dequantize_args(args), **dequantize_args(kwargs))
The dequantization routine also inverts the Hadamard rotation (convrot) applied during quantization.
Under this patch, INT8 matrix multiplication acceleration is unavailable.
On M1 Max, the only benefit is reduced file size and initial memory footprint.
Reproducing Author Samples
To avoid falsely assuming failure due to arbitrary prompt choices, I selected 3 sample images from the author and tested whether identical images were produced using the exact same prompts and seeds.
Settings: ER SDE, Simple scheduler, 4 steps, CFG 1, 1024×1536, no negative prompt.
| Sample | Content | Sampler | Seed |
|---|---|---|---|
| 148870975 | Pink hair twin-tails, blue dress, white background | ER SDE | 567340247 |
| 148870978 | White hair, halo, white dress, bird | ER SDE | 927028728 |
| 148872261 | White-haired maid, cafe | ER SDE | 1054837897 |
The sample metadata specifies “Shift 1”.
ComfyUI defaults Anima’s shift to 3.0, so I generated outputs both at default shift 3.0 and with shift set to 1.0 via ModelSamplingAuraFlow.
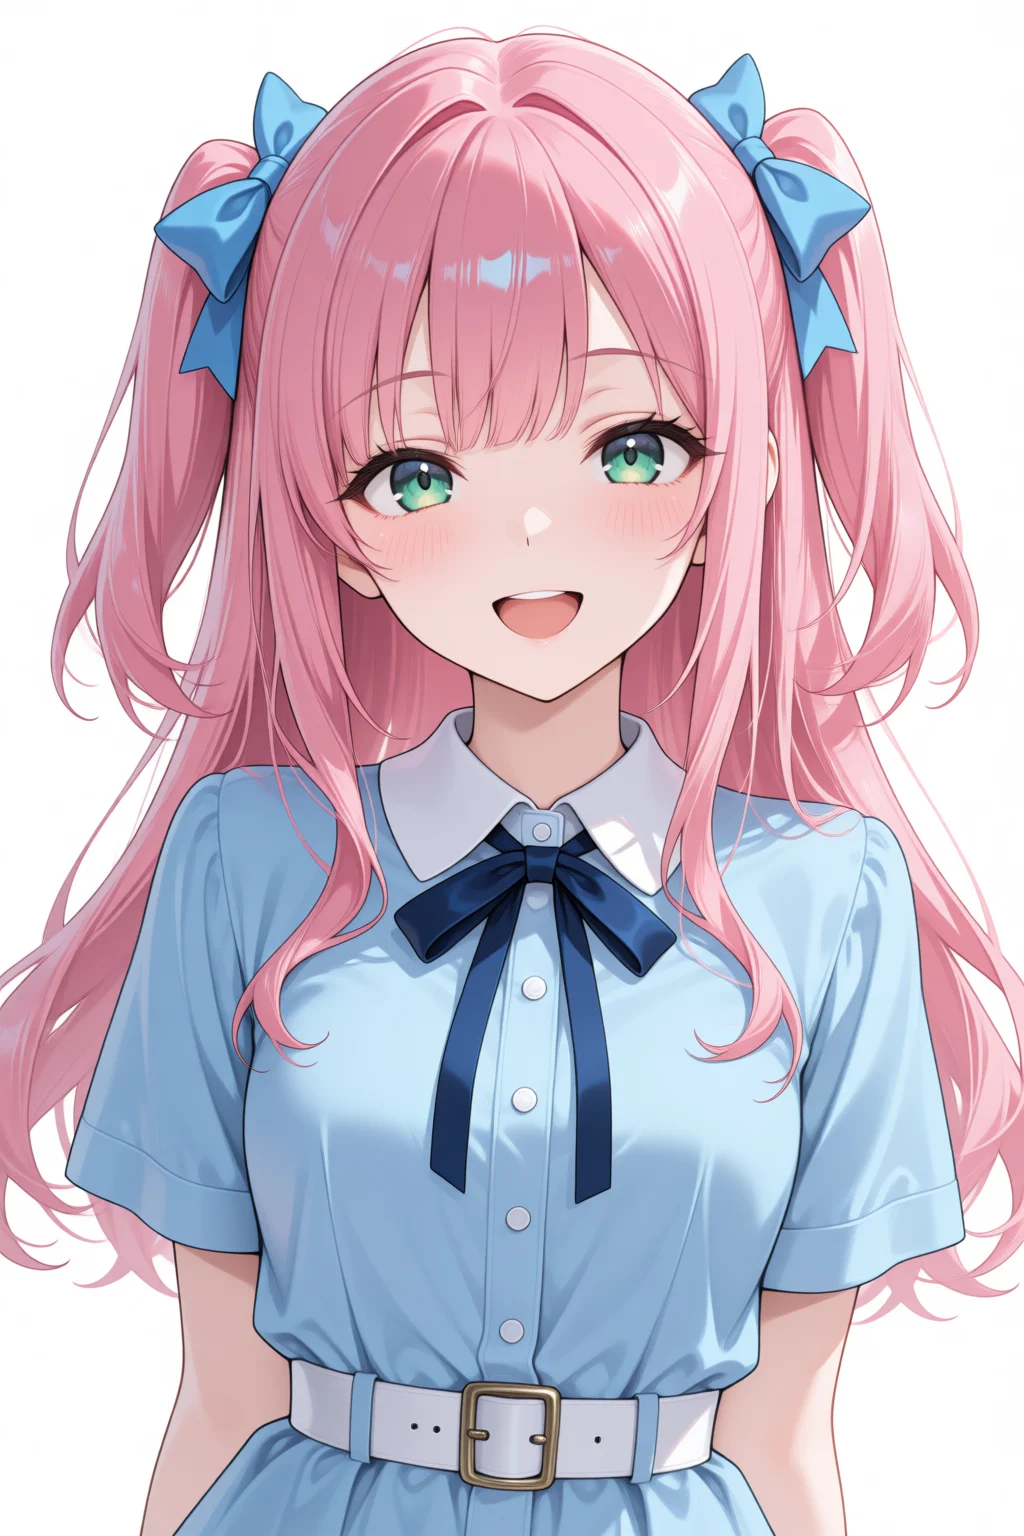
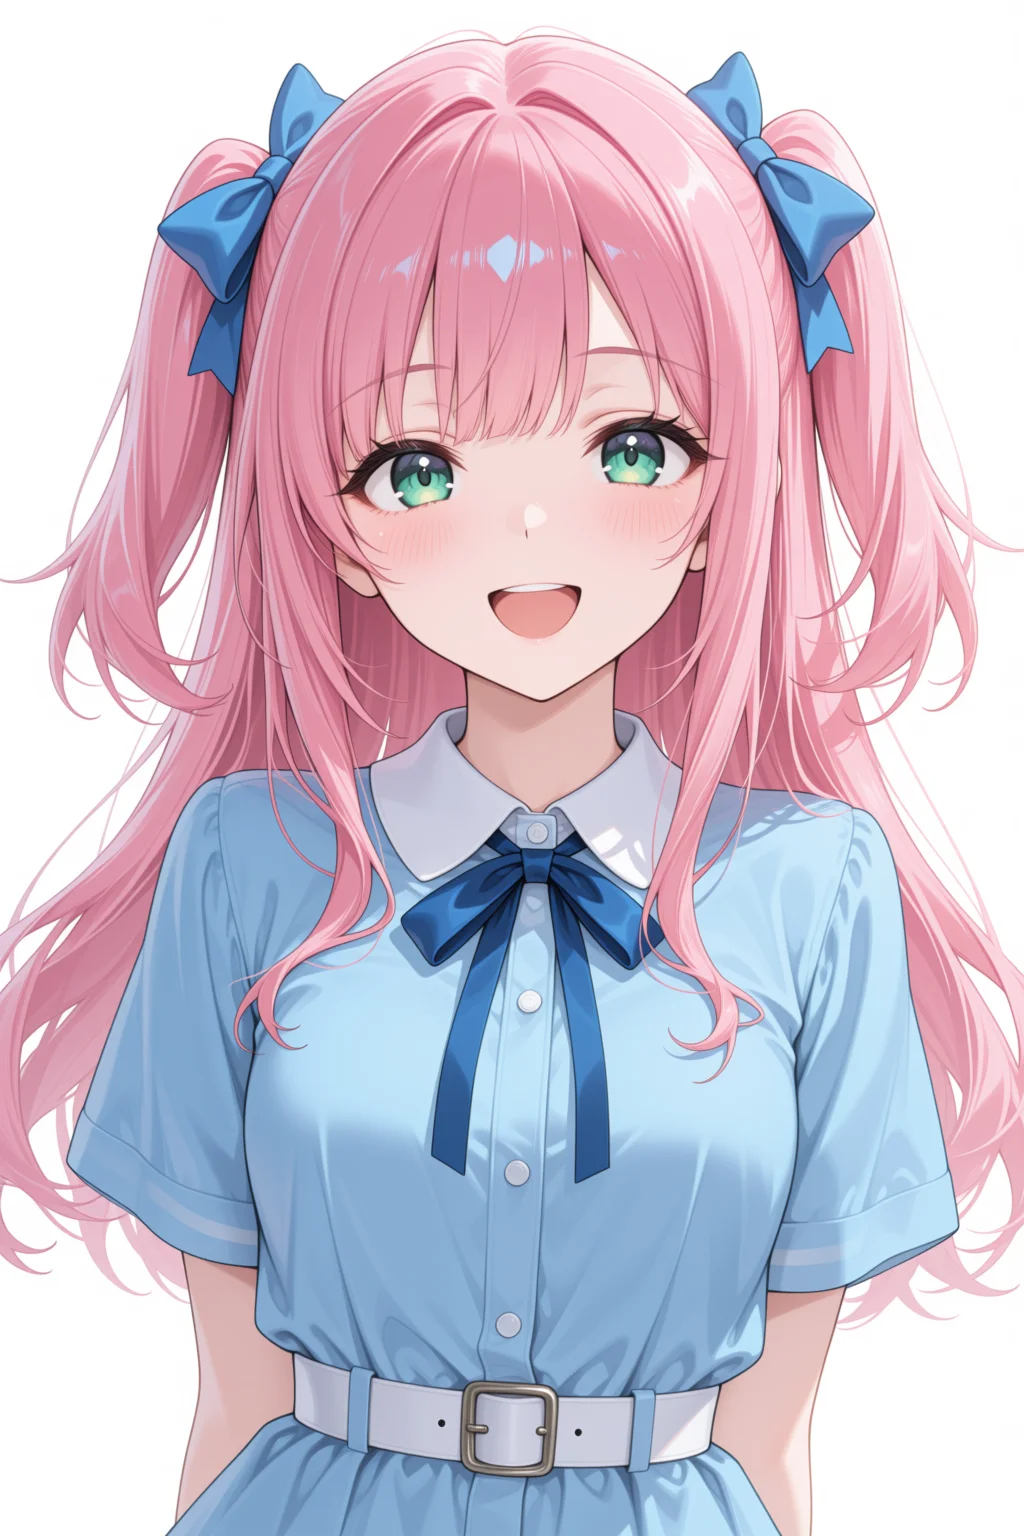
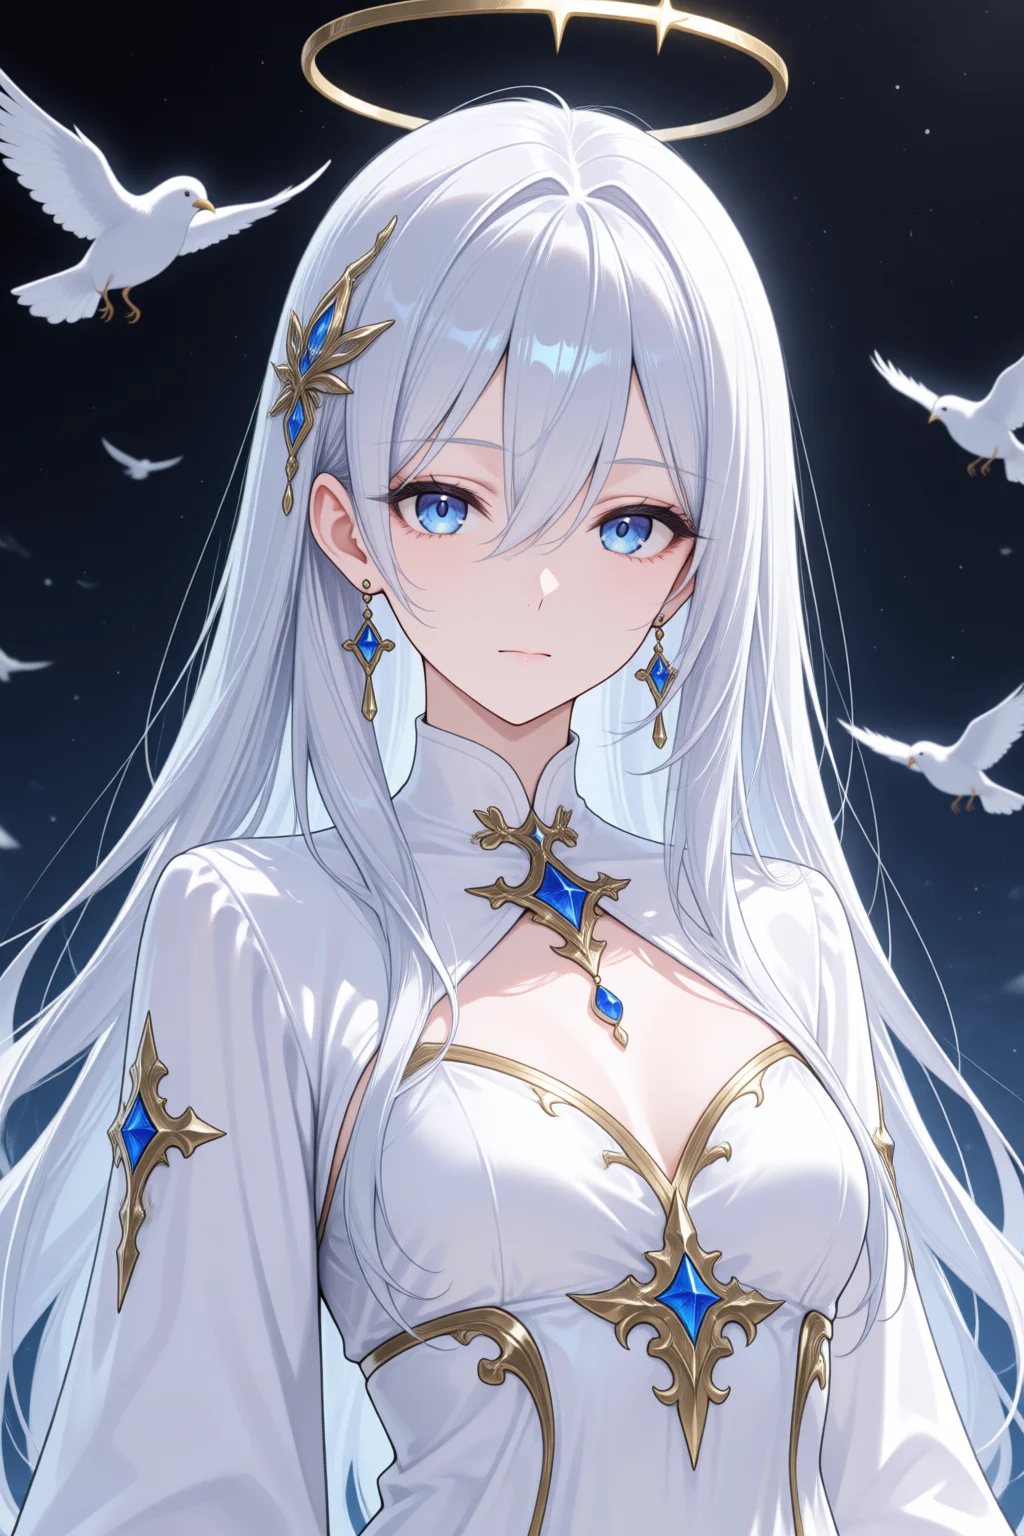
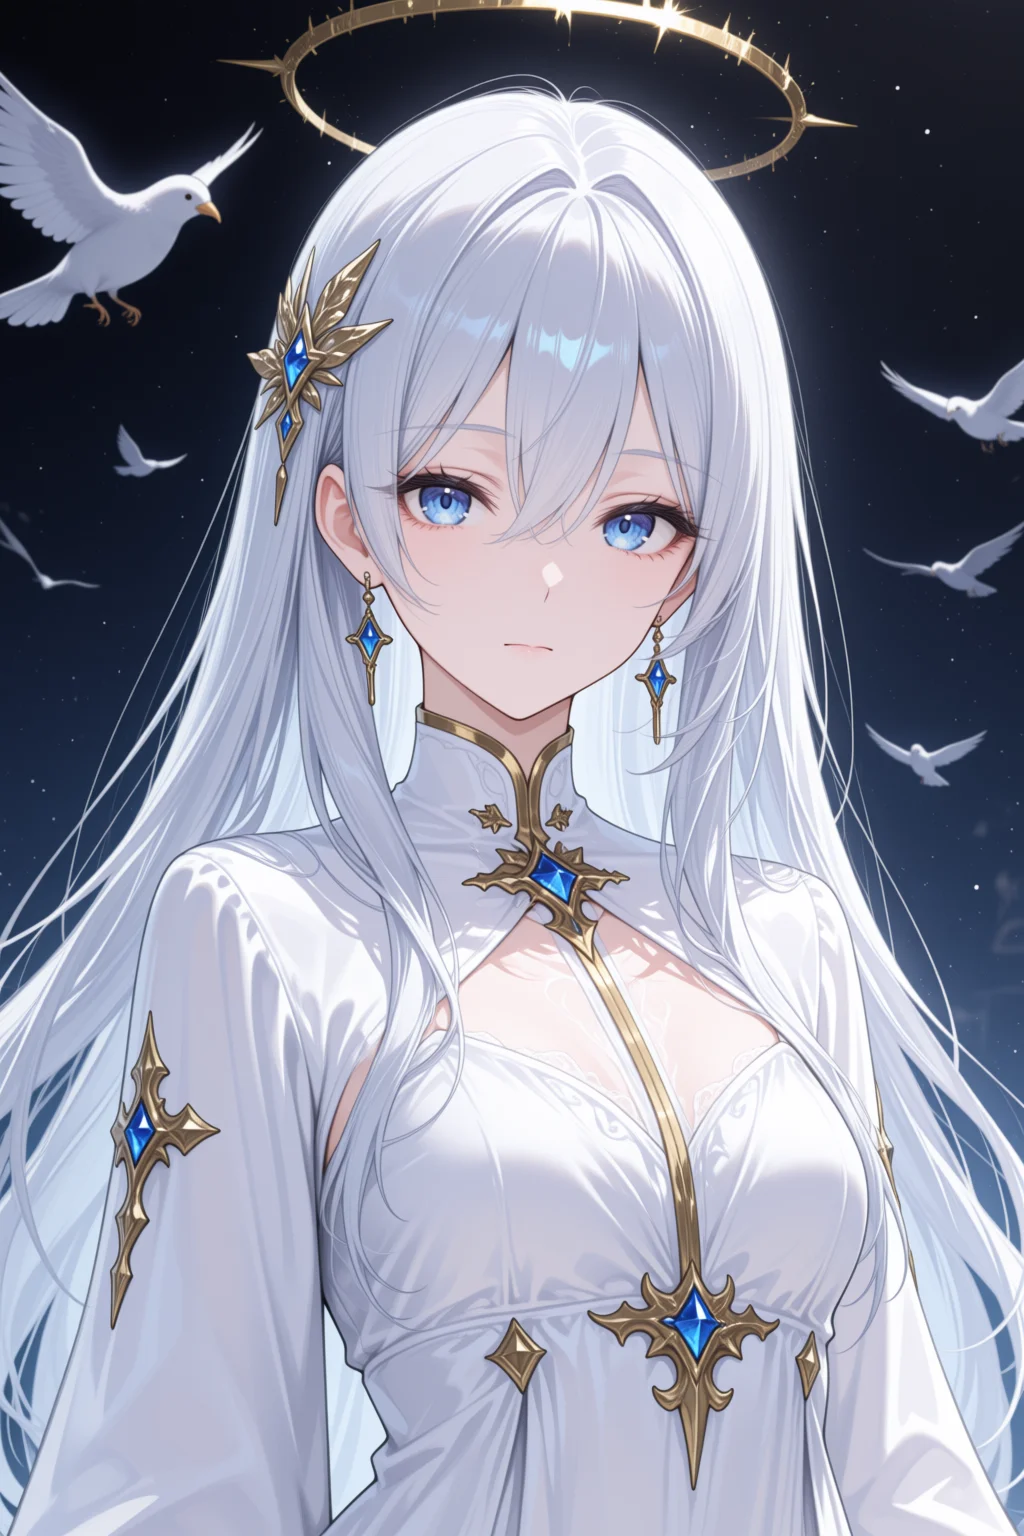
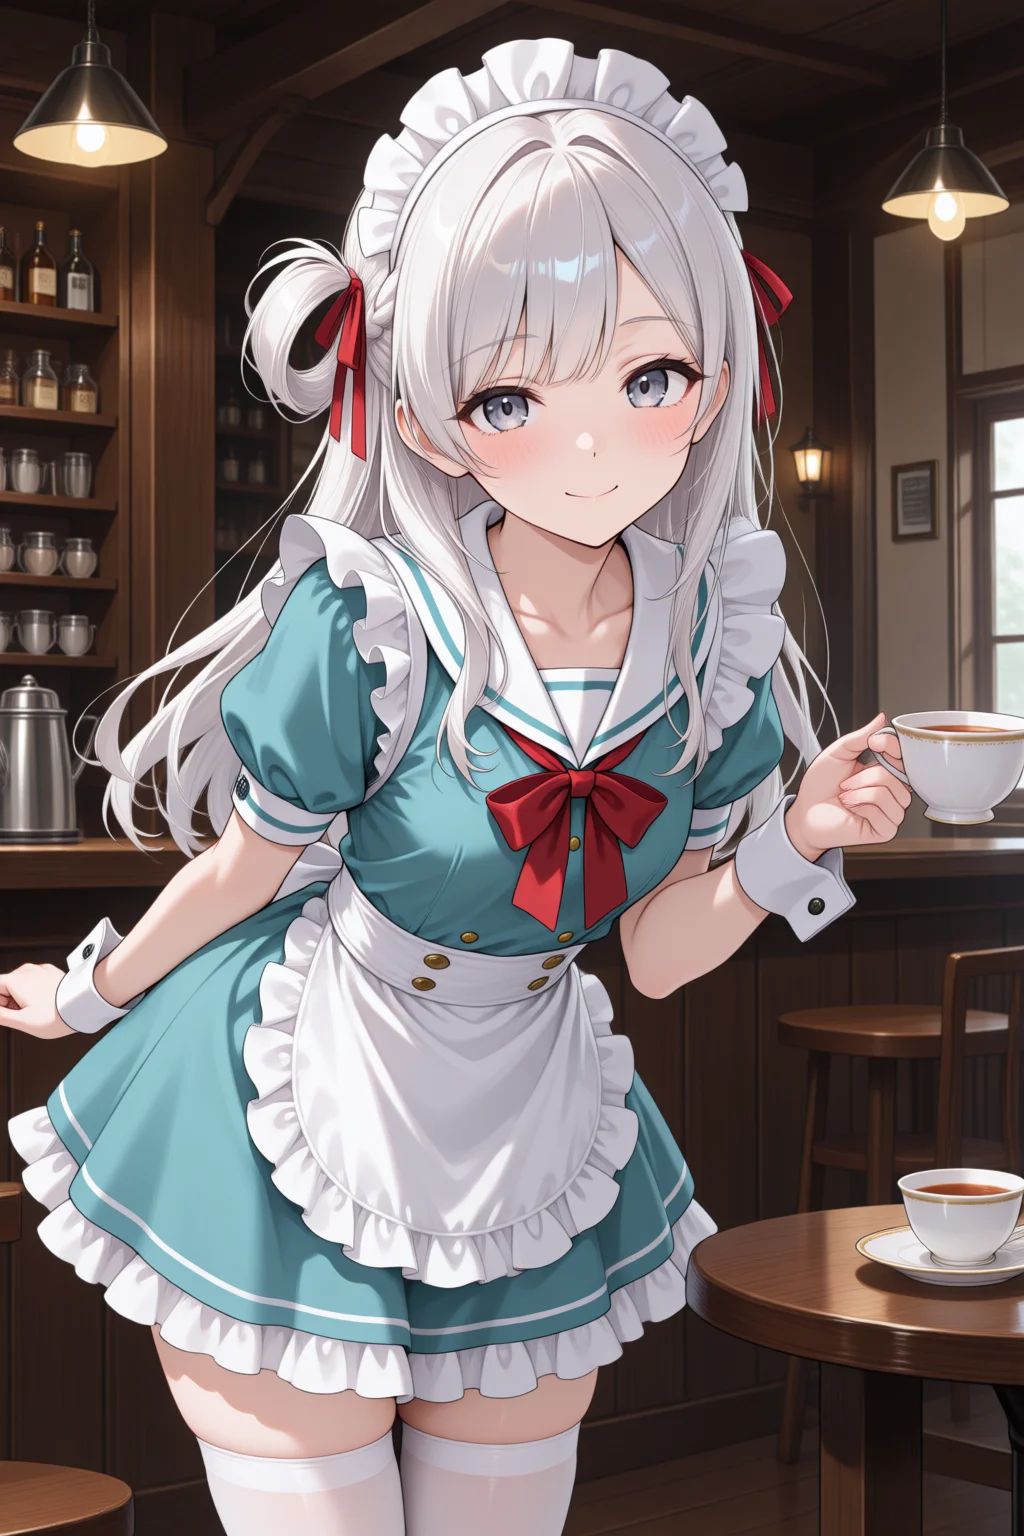
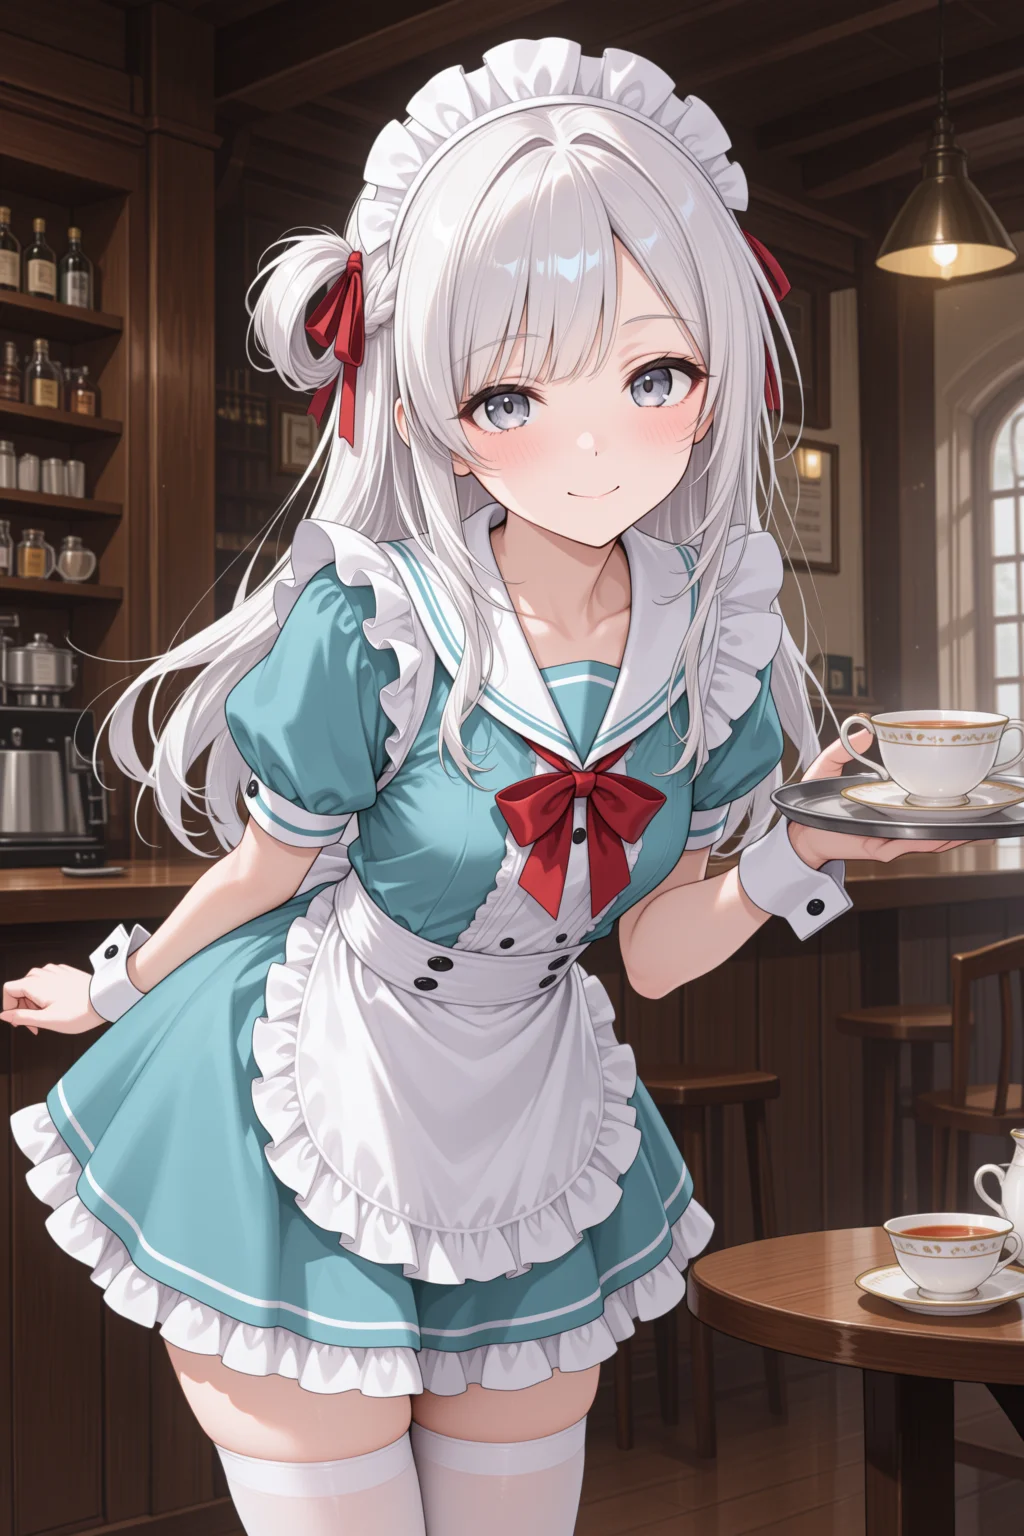
| Sample | Comparison with Author’s Sample Images |
|---|---|
| 148870975 | At both shift 3.0 and 1.0, hairstyle, ribbons, dress, belt, and smiling expression match the sample |
| 148870978 | Composition and bird placement match across both. Chest metal accents and waist belt align closer to the sample at shift 1.0 |
| 148872261 | Sample holds a tray in the right hand. Shift 1.0 holds the tray, whereas shift 3.0 changes to holding a teacup |
Across Forge Neo and ComfyUI, the same seeds produced nearly identical images.
Because shift 1.0 was closer to the author’s samples across all three, subsequent generations used shift 1.0.
At 1024×1536 4-step, each image took roughly 50 seconds on M1 Max.
Compared to the author’s ~5.5s on an RTX 3060 12GB, the lack of hardware INT8 matrix multiplication on MPS creates a significant performance gap.
Negative Prompt Behavior
Using the same conditions as sample 148870975, I tested the negative prompt listed in the description.
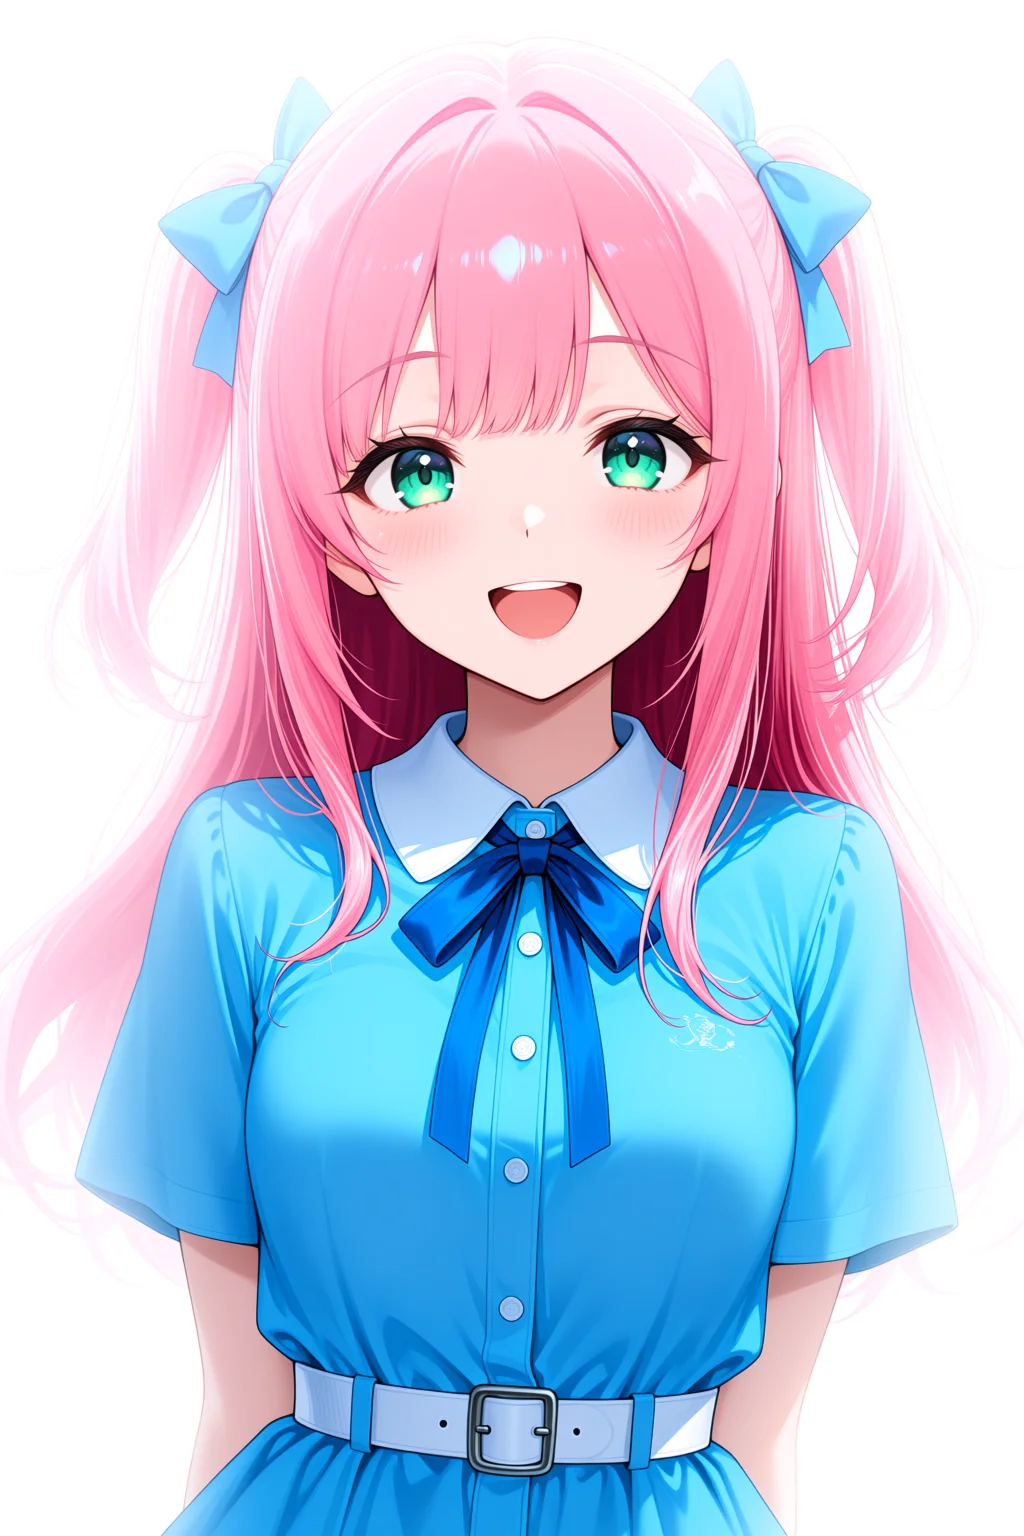
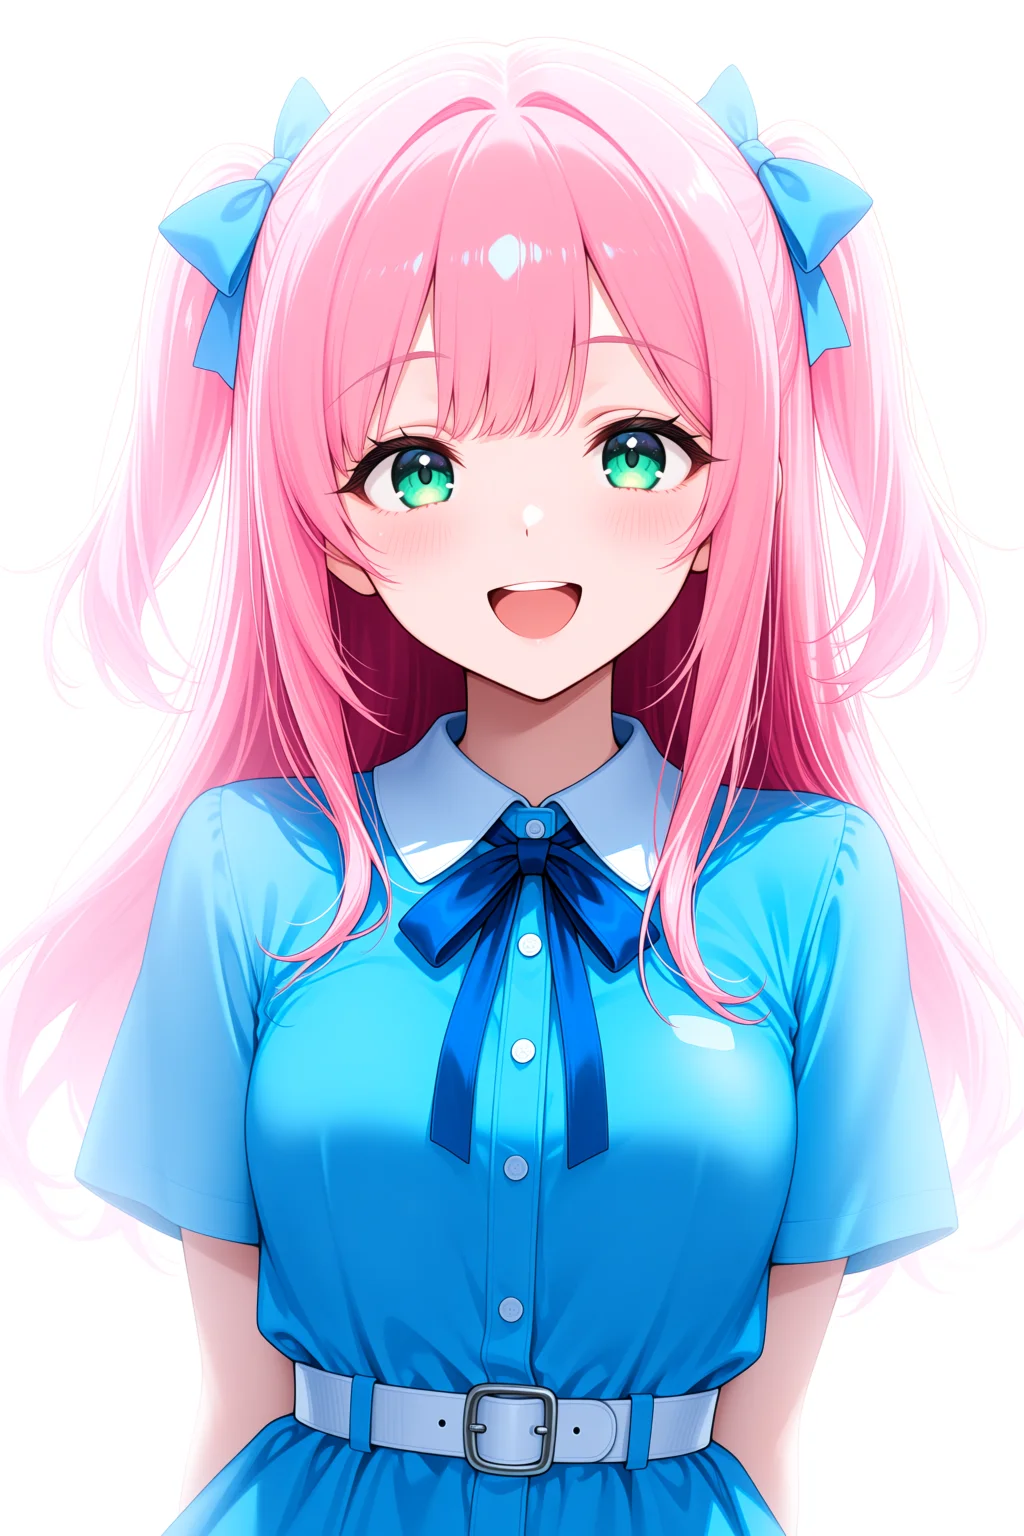
| Condition | Result | Time per Image |
|---|---|---|
| CFG 1 · No negative | Matches author’s sample image | 50.2s |
| CFG 1 · Author’s negative | Pixel-for-pixel identical to no negative (image omitted) | 50.2s |
| CFG 2 · No negative | Blue tones in dress and ribbons deepen, outer hair edges bleed | 92.4s |
| CFG 2 · Author’s negative | Nearly identical to CFG 2 without negative | 92.4s |
When CFG is 1, ComfyUI bypasses negative prompt conditioning passes entirely.
As long as the model is used at the recommended CFG 1, whatever is written in the negative prompt makes zero difference.
Increasing CFG to 2 forces negative evaluation passes, nearly doubling generation time.
In this test, CFG 2 only oversaturated colors without meaningful difference whether negative tags were present or not.
The complete absence of negative prompts across all of the author’s sample metadata aligns with this behavior.
Negative prompt from author's description
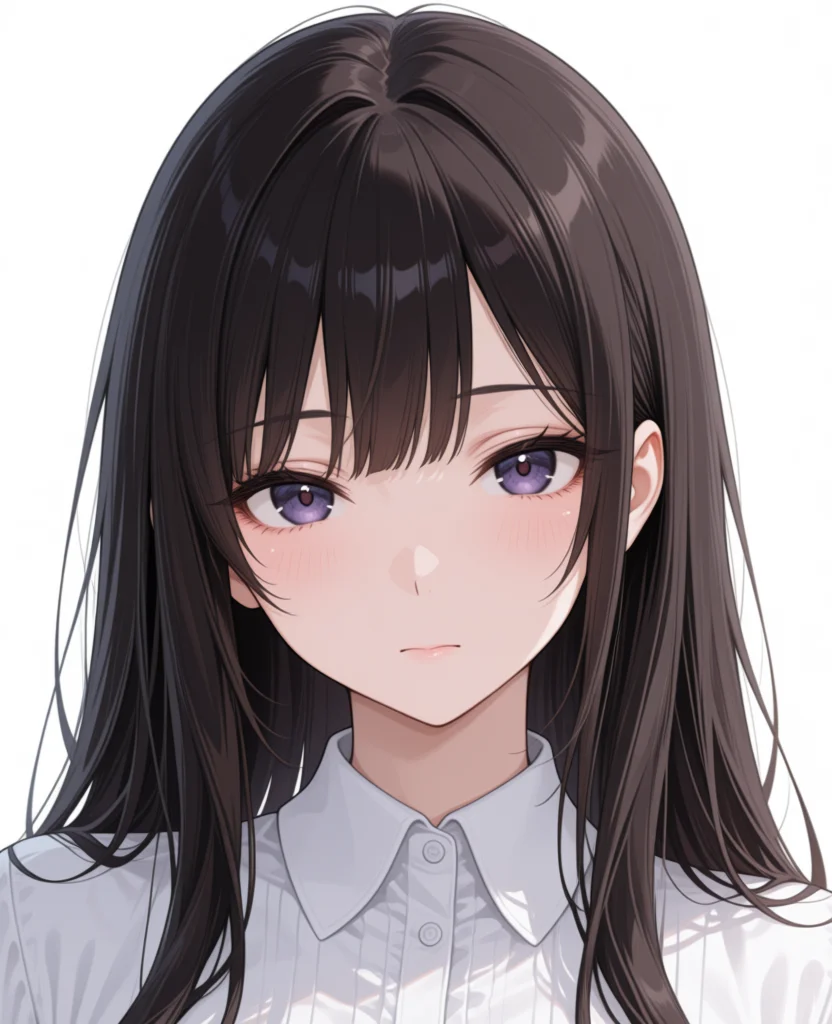
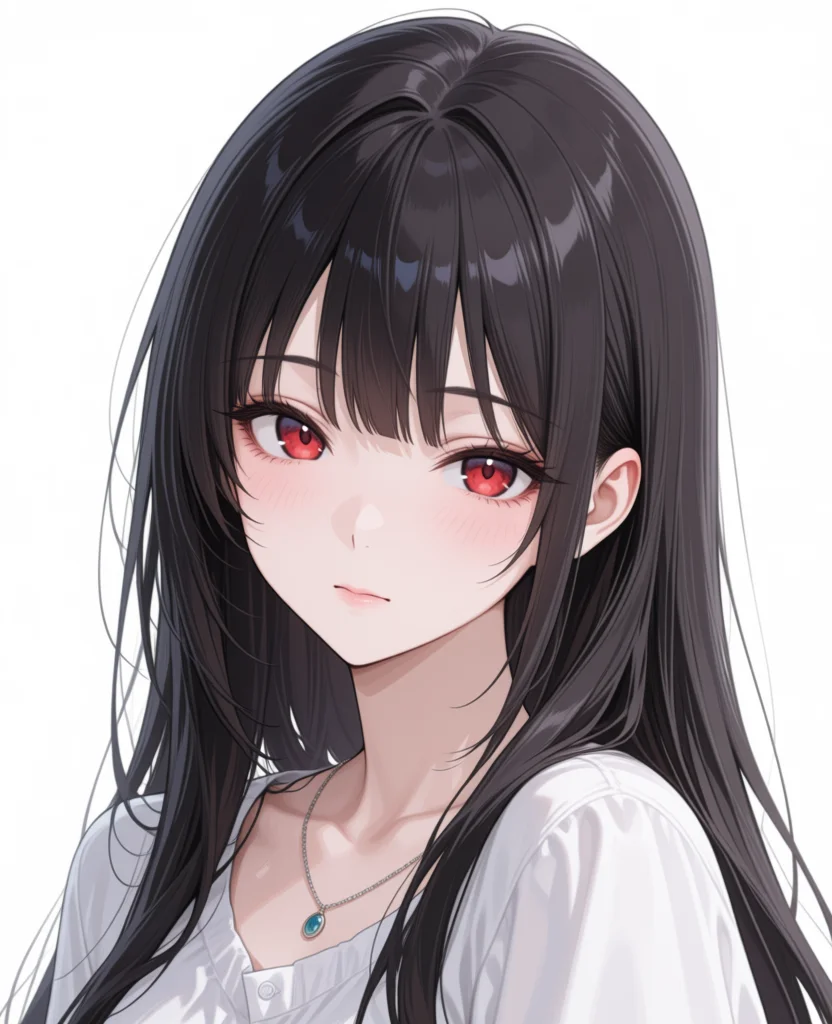
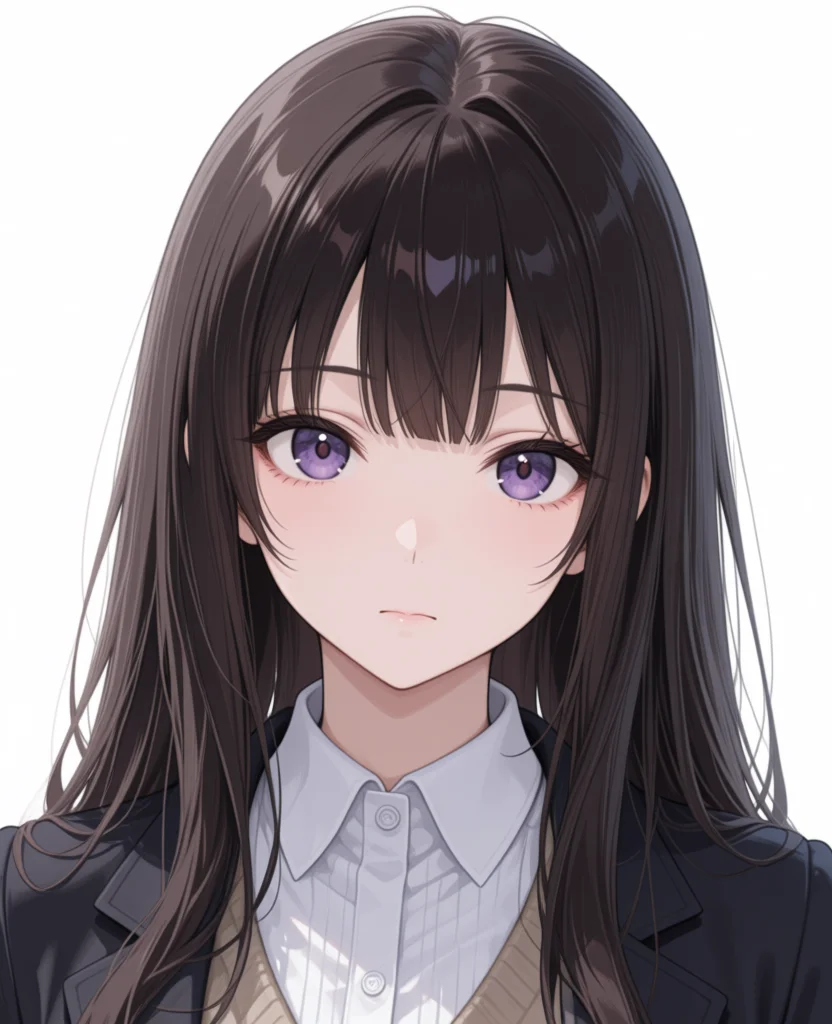
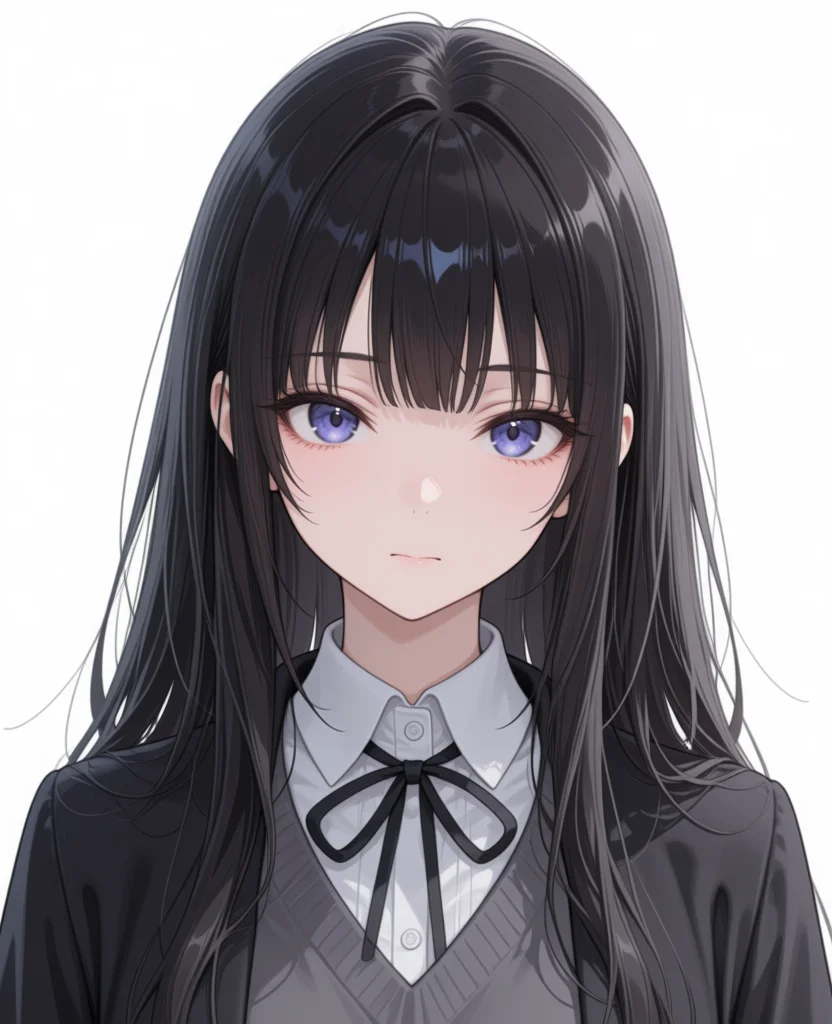
worst quality, low quality, score_1, score_2, score_3, artist nameDoes a Default Face Emerge Without Character Tags?
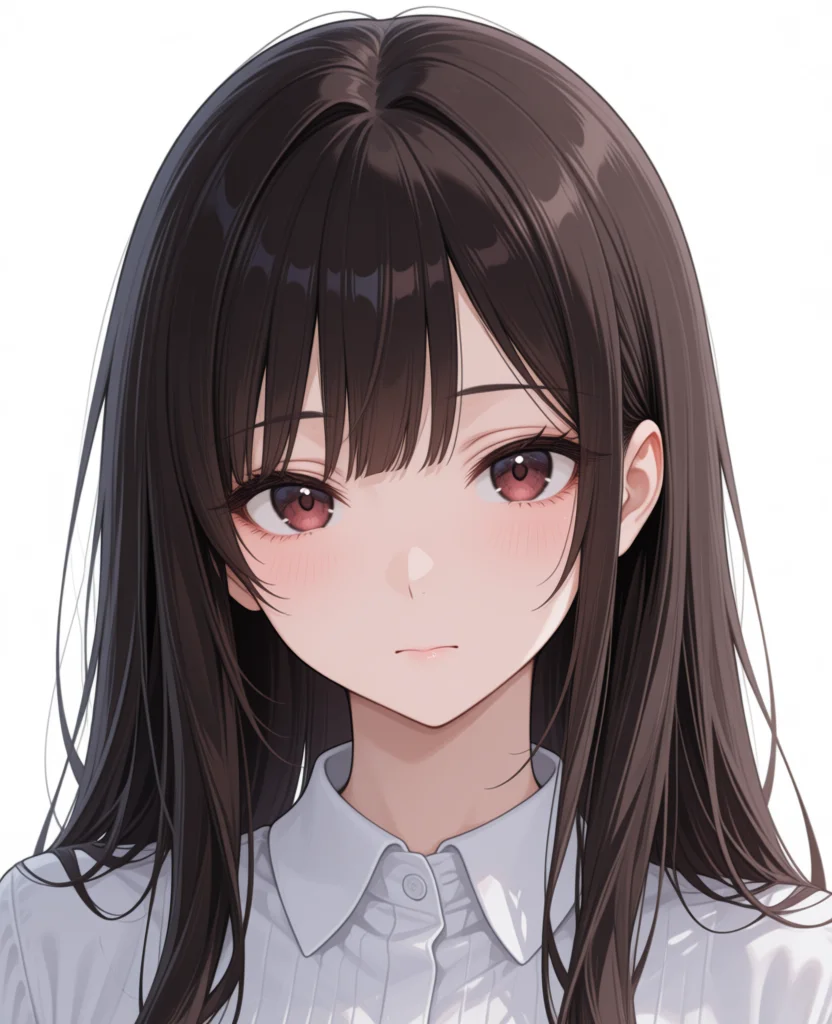
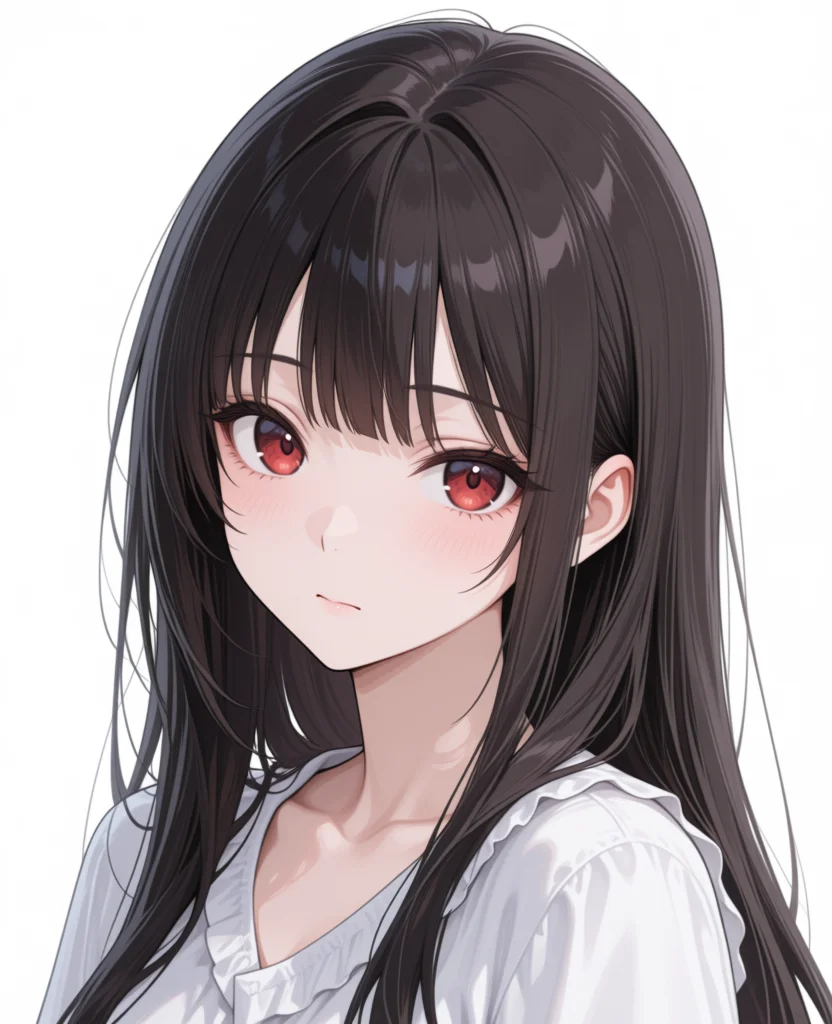
I tested seeds 1 through 4 with a minimal prompt containing no character names, hair colors, eye colors, or artist tags.
For comparison, I used stock Anima-2.9B and Anima-Base v1.0, both configured at 30 steps and CFG 4.5 matching the One obsession article.
I also compared with and without quality tags, and tested TinAnima with the author’s suggested natural language format.
Resolution was set to 832×1024; TinAnima used 4 steps, CFG 1, and shift 1.0.
| Label | Prompt |
|---|---|
| Tags | 1girl, solo, looking at viewer, upper body, white background |
| Quality Tags | masterpiece, best quality, 1girl, solo, looking at viewer, upper body, white background |
| Natural Language | A girl looking at the viewer. Upper body, plain white background. |
TinAnima
Tags (seeds 1–4)
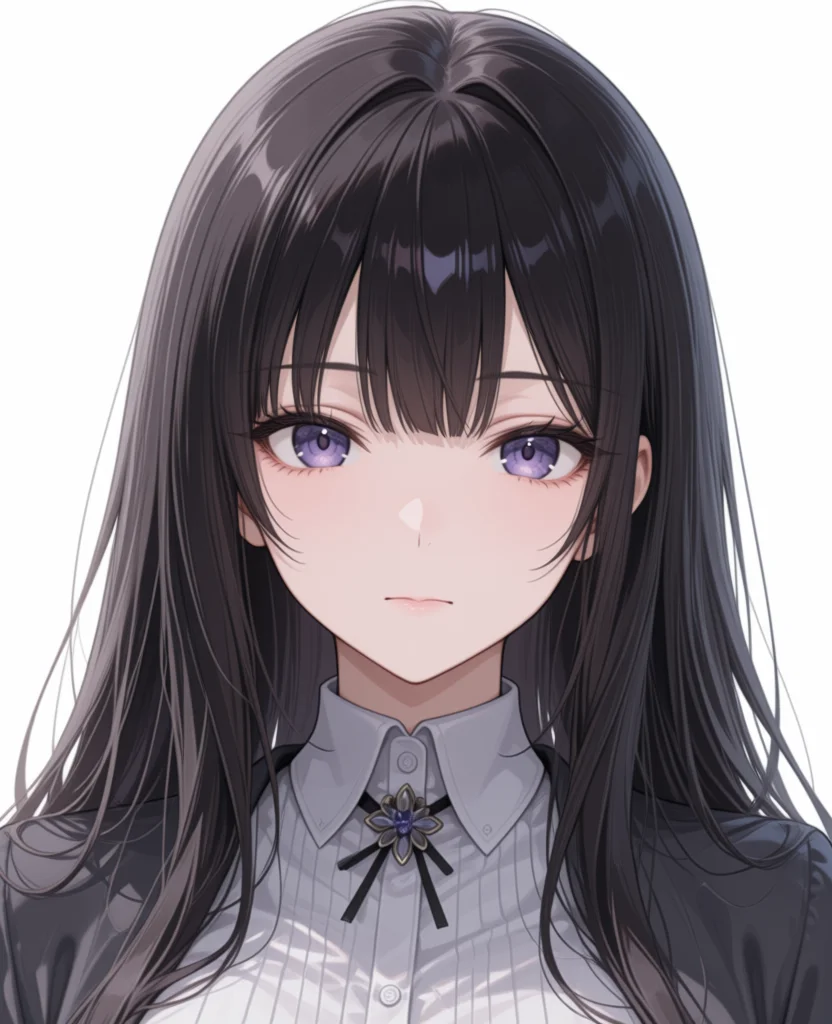
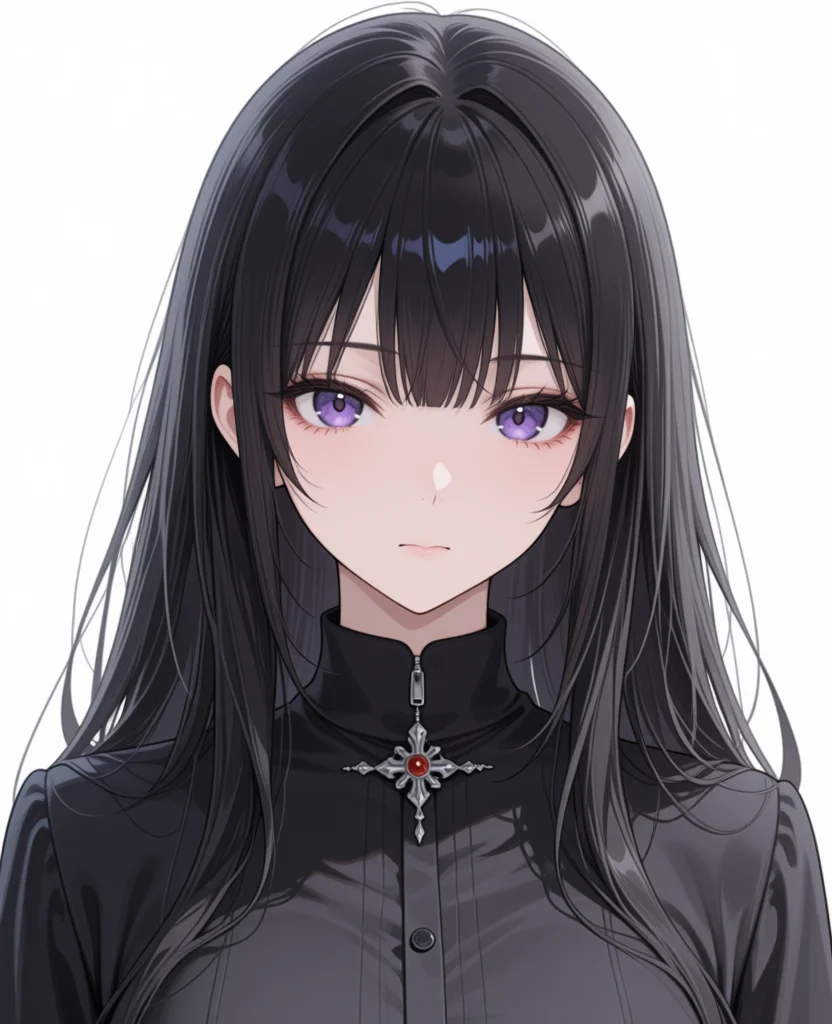
Natural Language (seeds 1–4)
Quality Tags (seeds 1–4, blurred for publication due to revealing clothing)
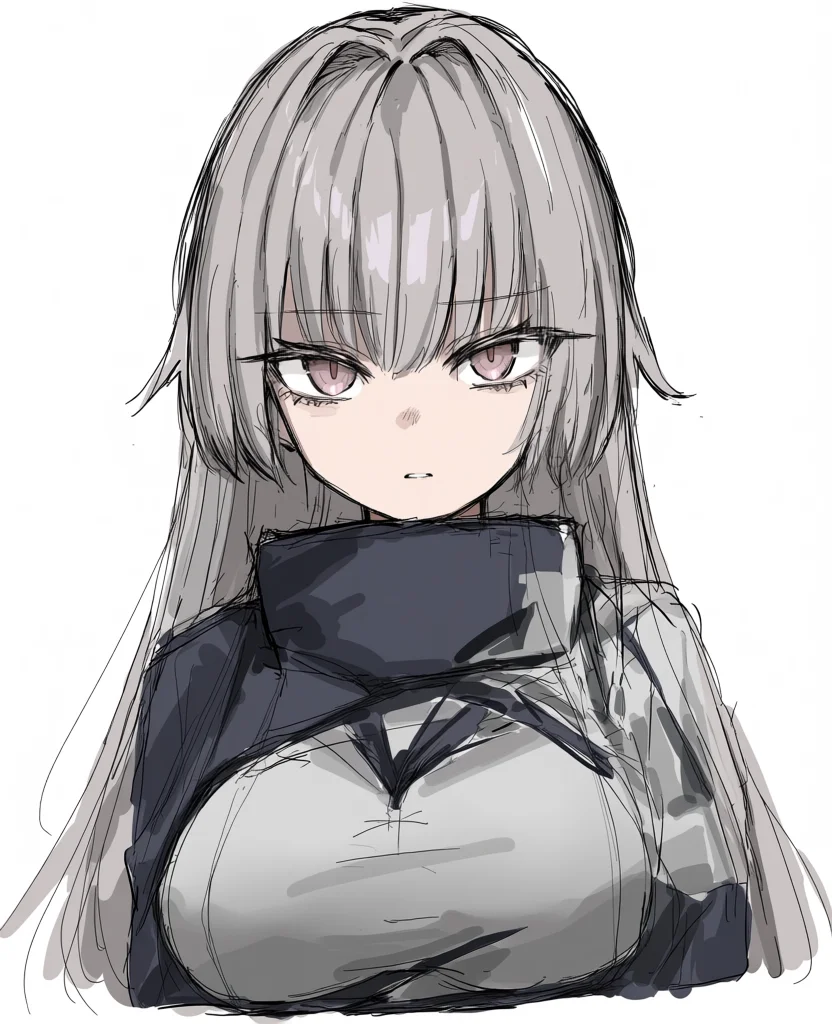
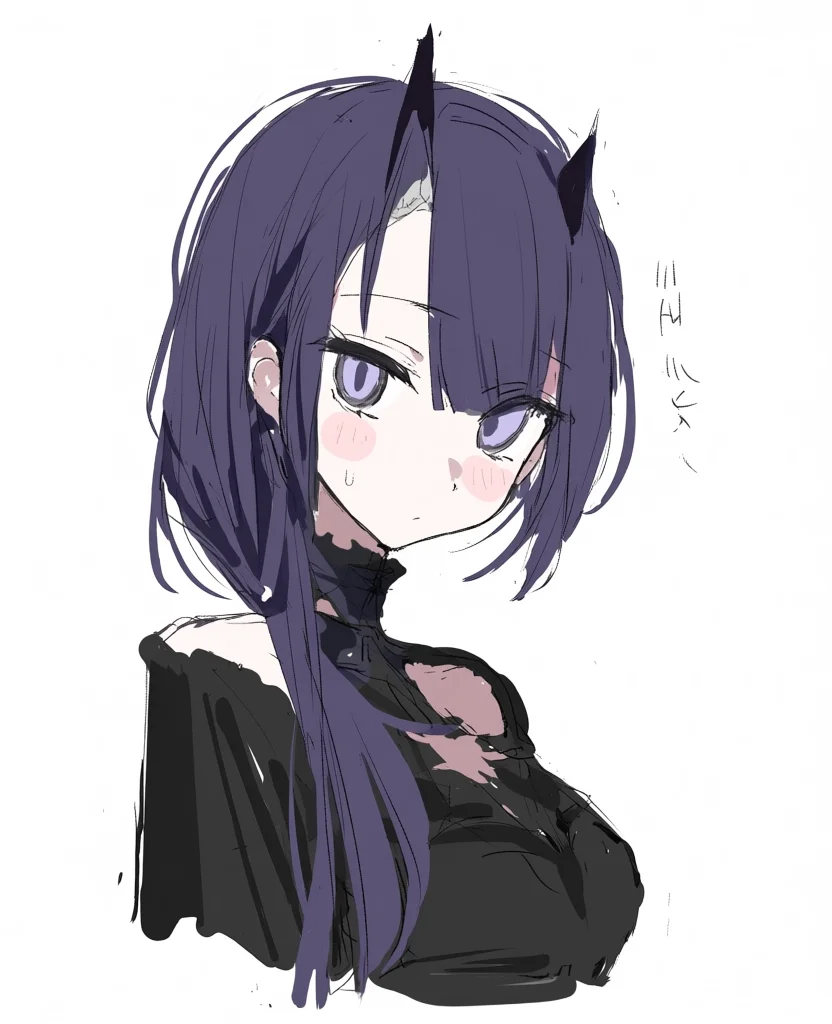
Stock Anima-2.9B
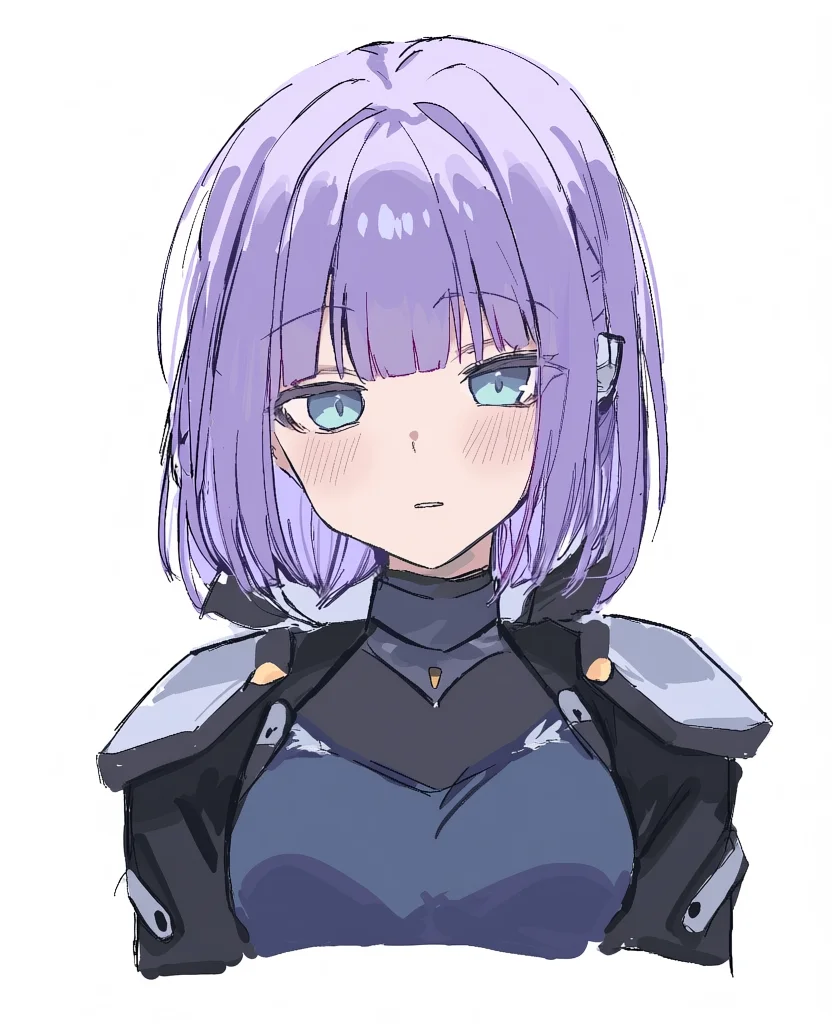
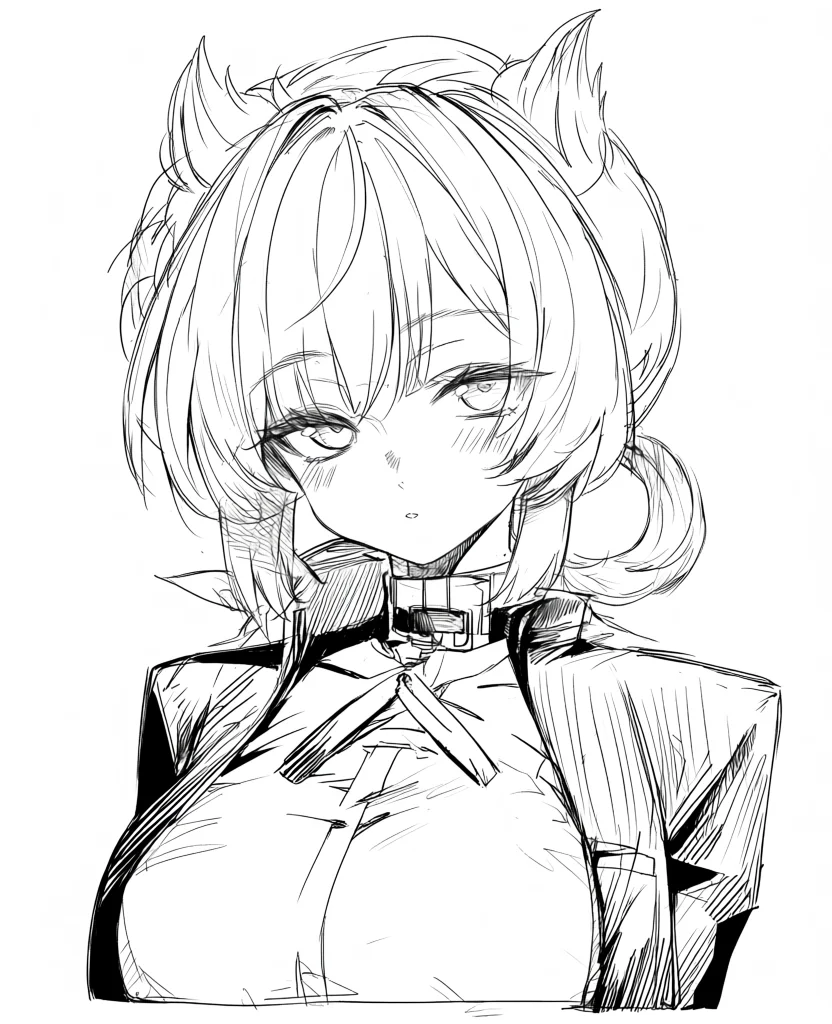
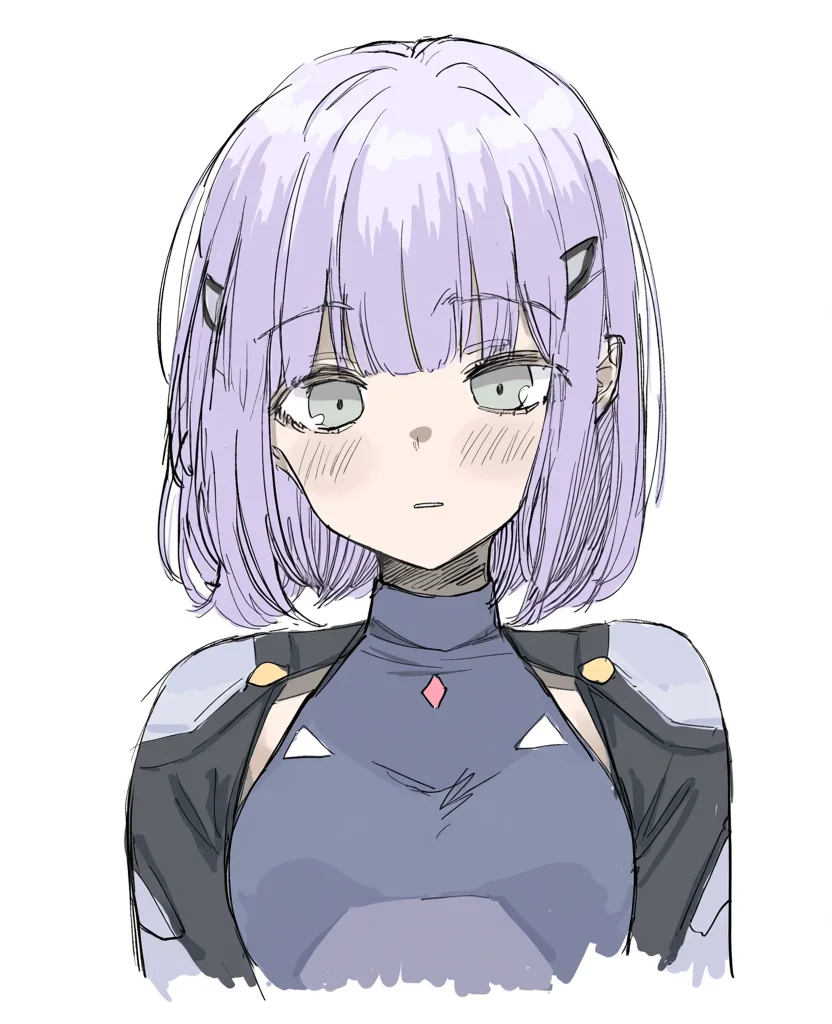
Tags (seeds 1–4)
Quality Tags (seeds 1–4, blurred for publication due to revealing clothing)
Anima-Base v1.0
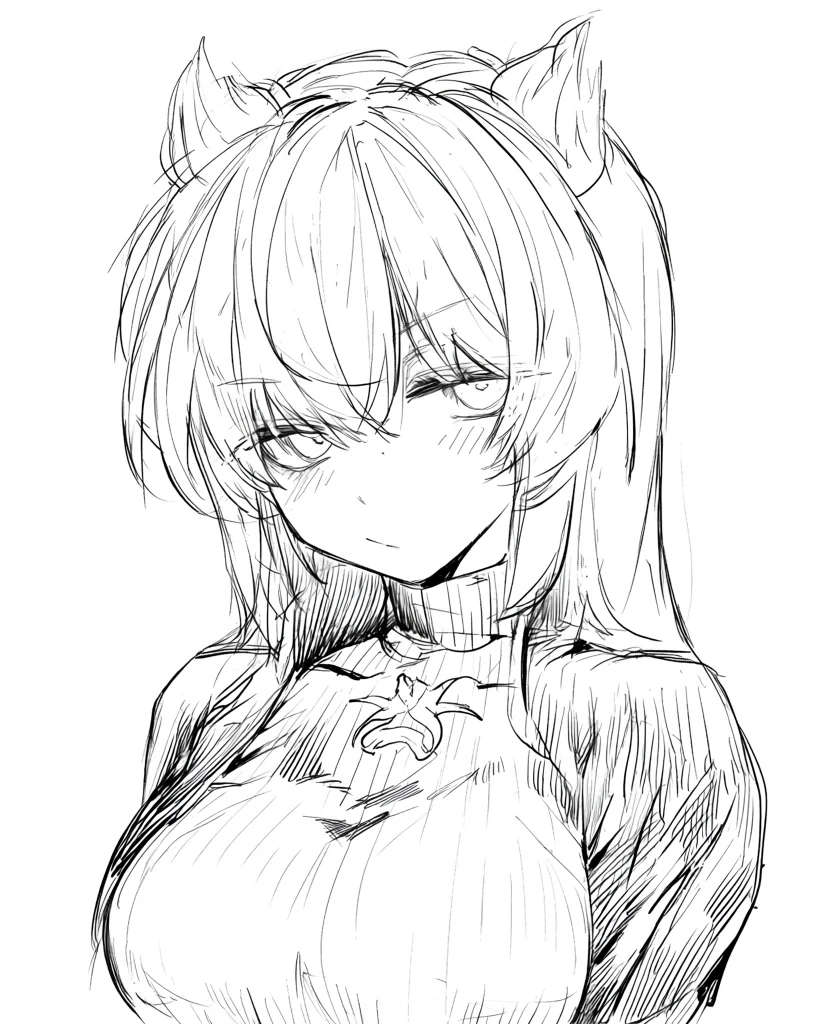
Tags (seeds 1–4)
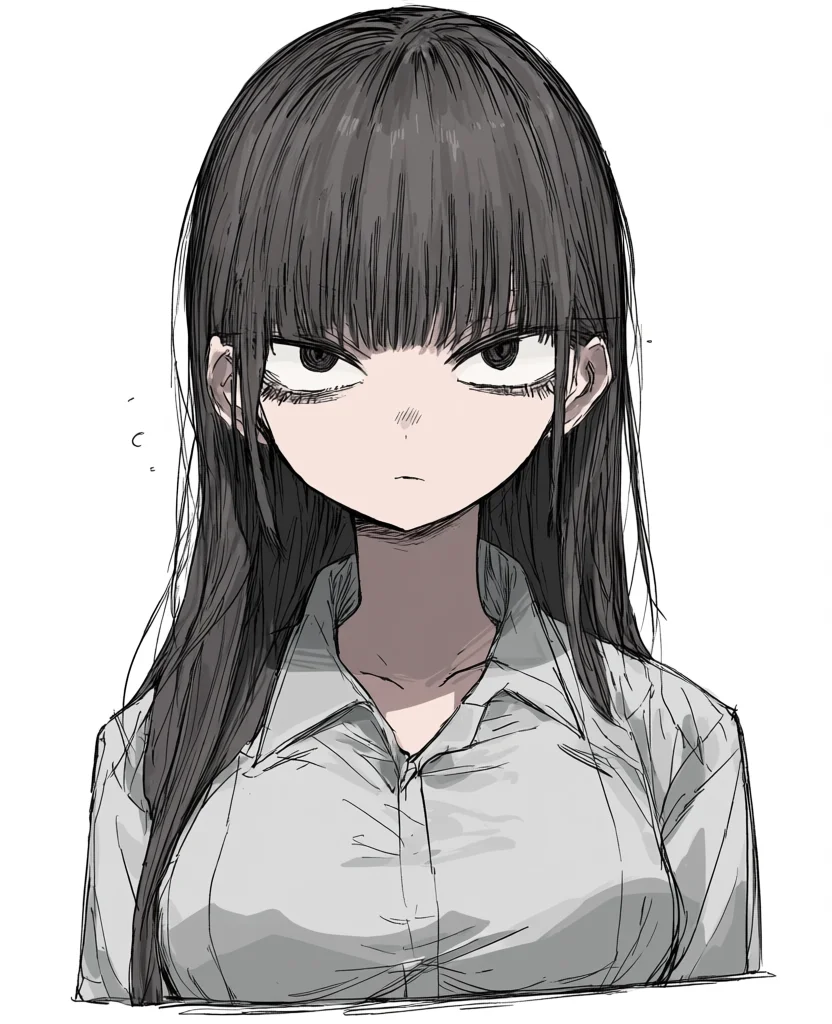
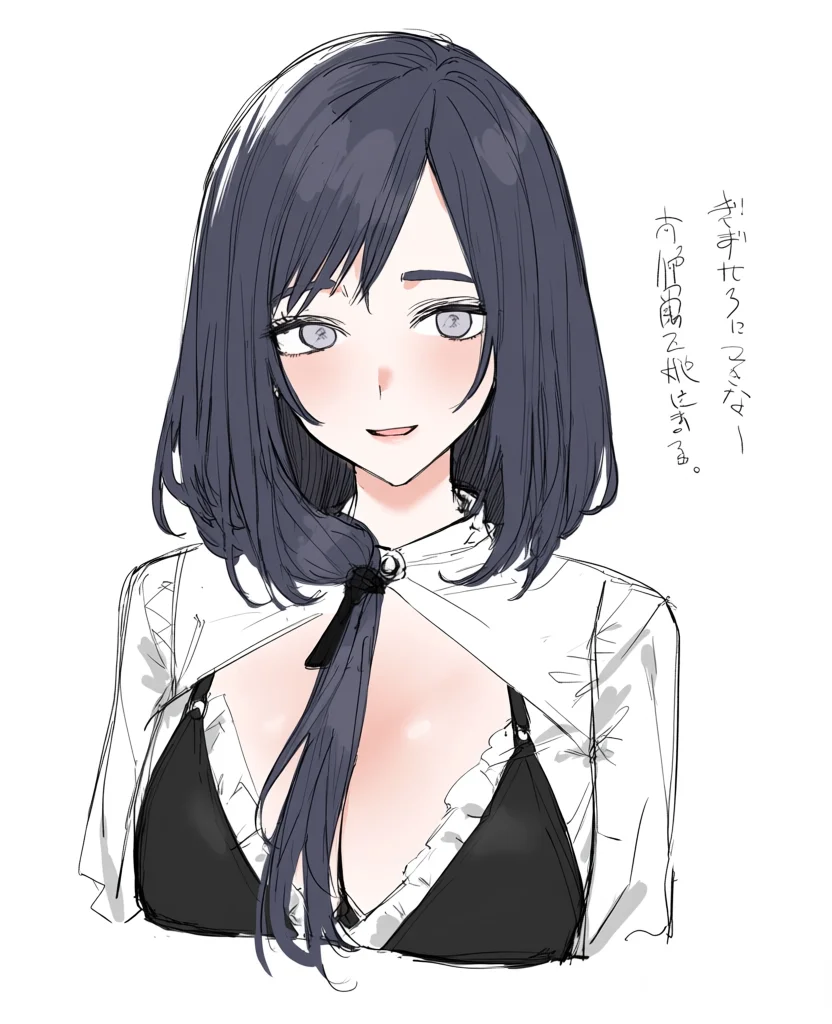
Quality Tags (seeds 1–4, blurred for publication due to revealing clothing)
| Model | Condition | Observations Across Seeds 1–4 |
|---|---|---|
| TinAnima | Tags | All 4 images show the exact same face: long black hair with straight blunt bangs. Eyes are purple in 3 and red in 1. Clothing is white shirt or black top |
| TinAnima | Natural Language | Nearly identical to tags. Face, hair, and clothing match per seed |
| TinAnima | Quality Tags | Face and hair identical to tags. 3 out of 4 show exposed cleavage, 1 wears black lingerie |
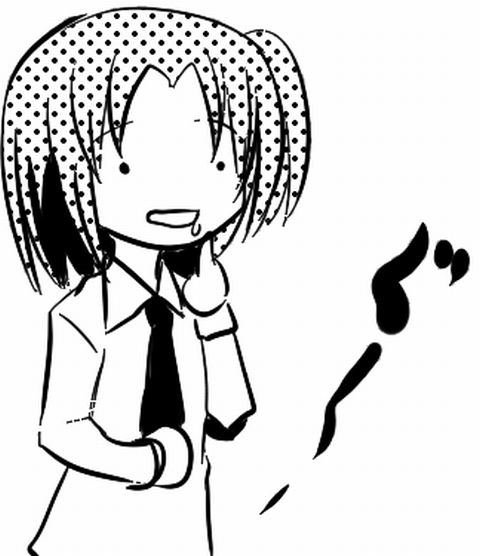
| Anima-2.9B | Tags | Purple bob, black-and-white sketch, grey long hair, dark blue hair with horns and handwritten text. Hair color and styles vary widely |
| Anima-2.9B | Quality Tags | All 4 are revealing compositions emphasizing bust. Hair colors: red, blue, black, black |
| Anima-Base v1.0 | Tags | Purple bob, monochrome line art, black long hair, dark blue hair with text. Compositions closely resemble 2.9B for matching seeds |
| Anima-Base v1.0 | Quality Tags | All 4 are revealing compositions |
Whether using tags, natural language, or quality tags, all 12 TinAnima images produced the exact same black-haired female character.
In contrast, stock Anima-2.9B and Anima-Base generated varied hair colors, styles, and faces across seeds 1–4 when unspecified.
Under these conditions, this single fixed face in TinAnima is not an inherited trait from base Anima, but appears to have been introduced during the fine-tuning/merge process.
Even in the author’s samples with pink or white hair, the eye shapes and nose structures share this exact facial geometry.
Adding quality tags to both base models resulted in revealing, bust-emphasizing outputs across all 4 seeds.
Without the safe tag, adding masterpiece, best quality frequently biases outputs toward NSFW.
TinAnima also trended toward open necklines with quality tags, though slightly less aggressively than the base models.
Specifying Hair and Eyes Only
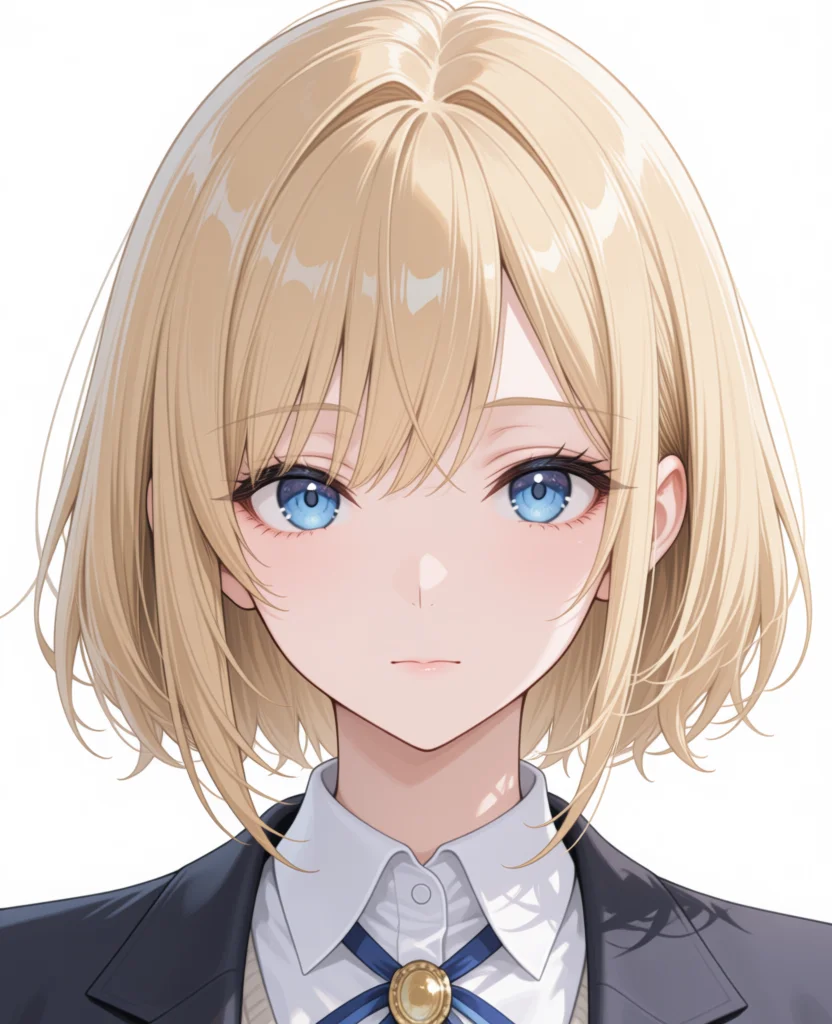
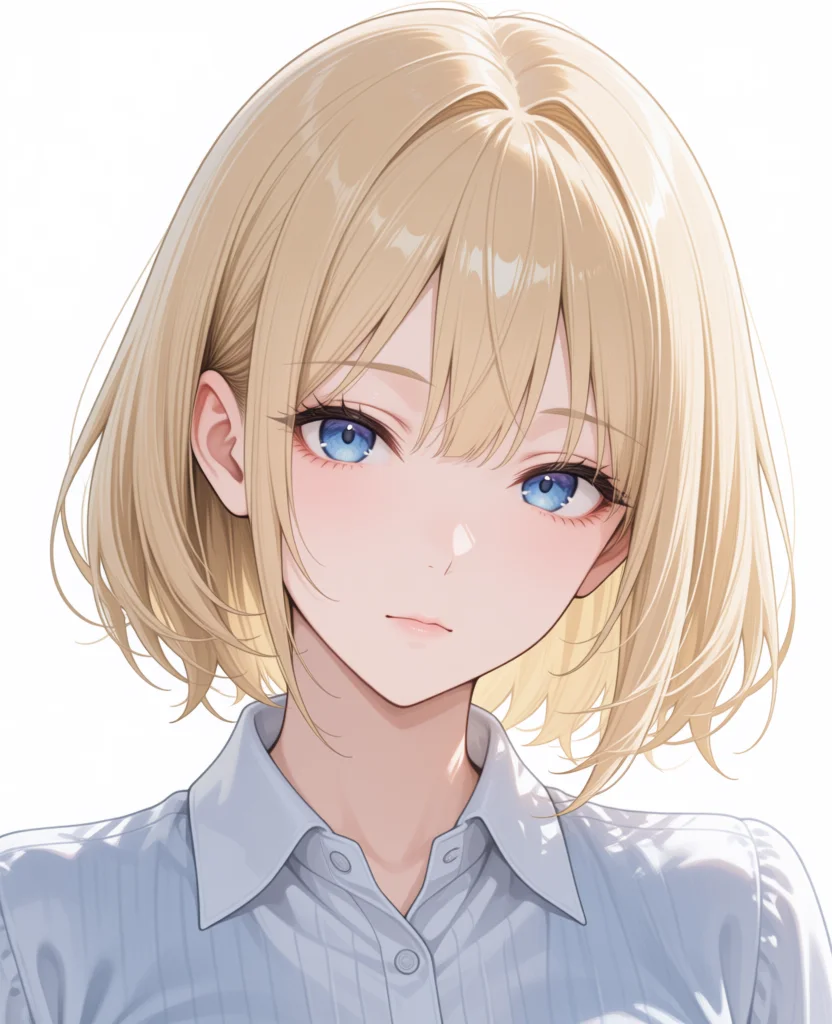
Next, I specified only hairstyle, hair color, and eye color without naming any character, generating seeds 1–4 in TinAnima.
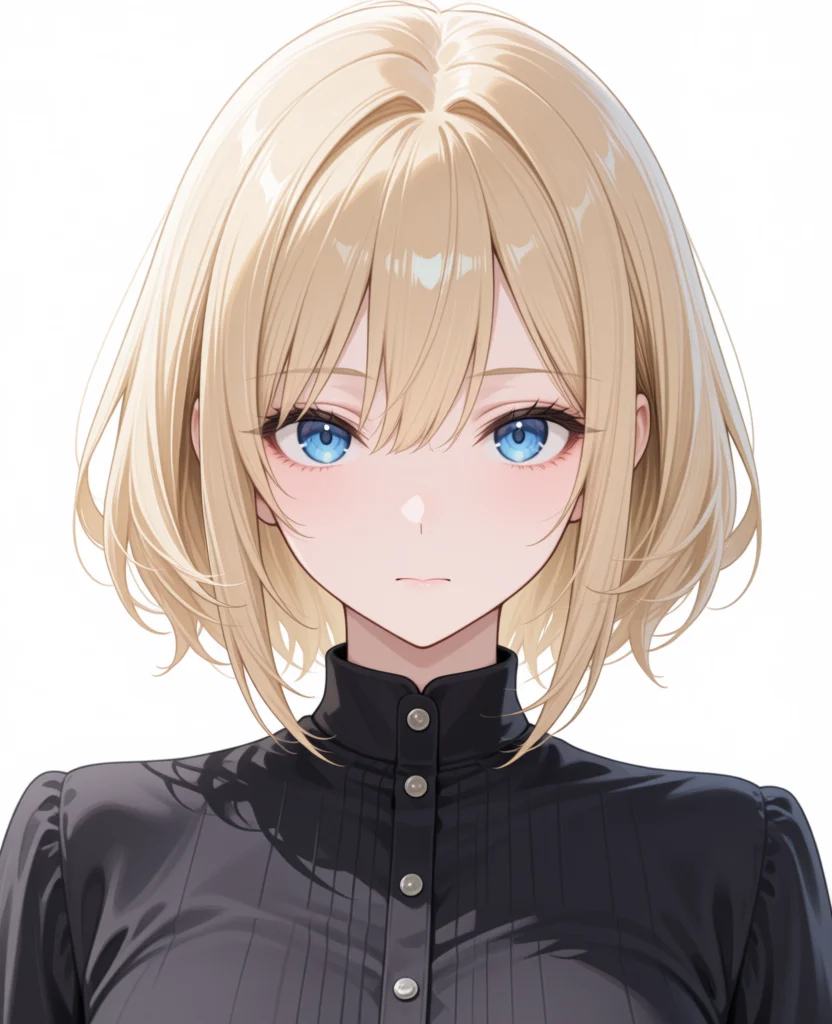
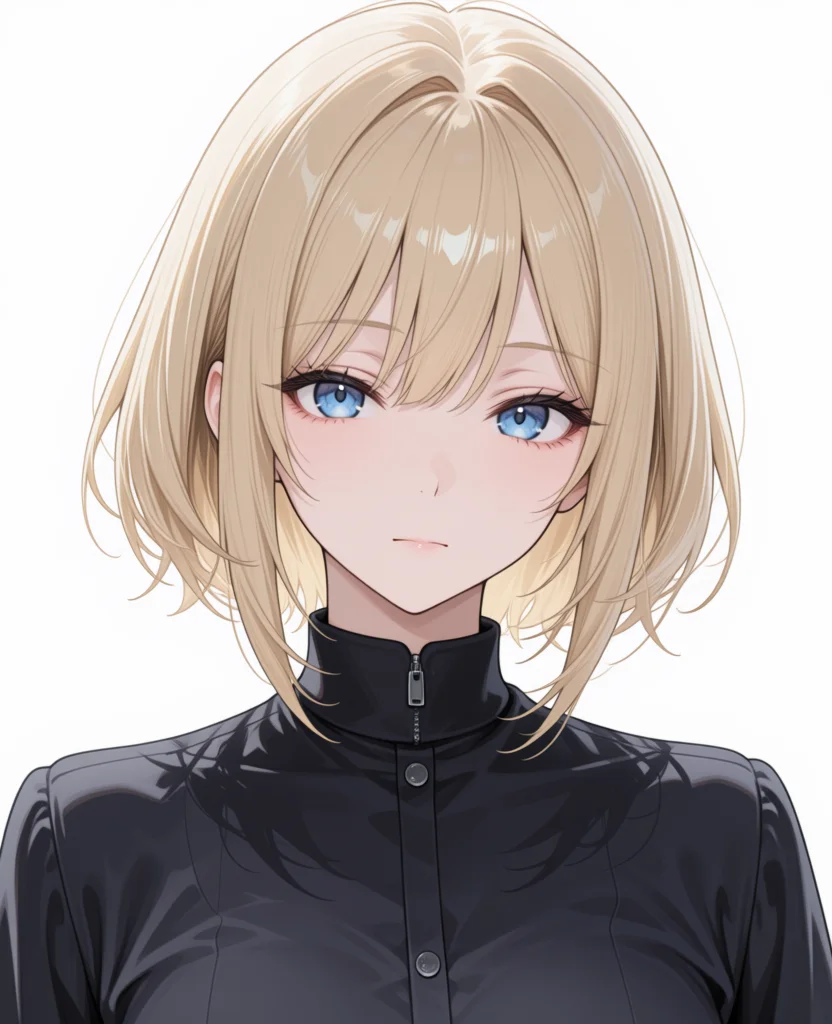
| Specification | Observations |
|---|---|
short hair, blonde hair, blue eyes | All 4 images produce a blonde bob with blue eyes. However, eye shape, nose, small mouth, and neutral expression remain identical to the unspecified black-haired character |
While hair and eye colors updated as prompted, the underlying facial structure did not change.
The TinAnimaCharactersLora_29B and TinAnimaWomanLora_29B baked into the model at strength 0.4 each represent primary candidates for this bias.
Because neither LoRA is publicly available, I cannot isolate their individual contributions locally.
Prompt and negative
Hair and color only:
1girl, solo, short hair, blonde hair, blue eyes, looking at viewer, upper body, white backgroundTinAnima runs at CFG 1, so no negative prompt is used. Anima-2.9B and Anima-Base used:
worst quality, low quality, artist name, blurry, jpeg artifacts, chromatic aberrationComparison Targets
From here on, I generated outputs using the same test scenarios as the One obsession article:
| Label | Model | Role |
|---|---|---|
| Base | Anima-Base v1.0 | 30-step baseline. Base model used for character LoRA training. Reused outputs from the Turbo v1.1 vs Aesthetic v1.1 comparison; not regenerated |
| Turbo v1.1 | Anima-Turbo v1.1 | 8-step baseline. Reused outputs from the same article; not regenerated |
| Anima-2.9B | Anima-2.9B-preview-v1 | 2.9B baseline. Reused outputs from the One obsession article; not regenerated |
| TinAnima | TinAnima29B_v1_4steps_INT8 | Newly generated in this test |
Generation Settings
| Item | Base / Anima-2.9B | Turbo v1.1 | TinAnima |
|---|---|---|---|
| Steps / CFG | 30 / 4.5 | 8 / 1.0 | 4 / 1.0 |
| Sampler / Scheduler | er_sde / simple | er_sde / simple | er_sde / simple |
| shift | Default (3.0) | Default (3.0) | 1.0 |
| Resolution | 832×1216 (bust portraits: 832×1024, two characters: 1216×832) | Same | Same |
| Seed | 42 | 42 | 42 |
| Character LoRA | Base uses keikana-animabase-v2_epoch140; Anima-2.9B uses the same LoRA remapped to 40 blocks. Both at strength 1.0 | keikana-animabase-v2_epoch140 at strength 1.0 | 40-block remapped version at strength 1.0 |
| Positive Prompt Prefix | masterpiece, best quality, safe | Same | safe |
| ComfyUI | Base on v0.30.1, Anima-2.9B on v0.33.3 | v0.30.1 | v0.33.3 (with MPS INT8 patch) |
Tests were conducted on an Apple Silicon M1 Max 64GB.
For TinAnima, matching the author’s samples, I dropped only masterpiece, best quality from the previous articles’ prompts.
safe was retained because it governs image content rather than acting as a generic quality booster.
The negative prompt used the same string as prior articles, though at CFG 1 it has no effect.
Resolution was aligned to 832×1216 matching prior articles rather than the author’s recommended 1024×1536.
Character LoRA Strength
The character LoRAs used were the 40-block remapped versions of Kei-chan and Kana-chan originally trained on Anima-Base—the identical files used in the 2.9B One obsession article.
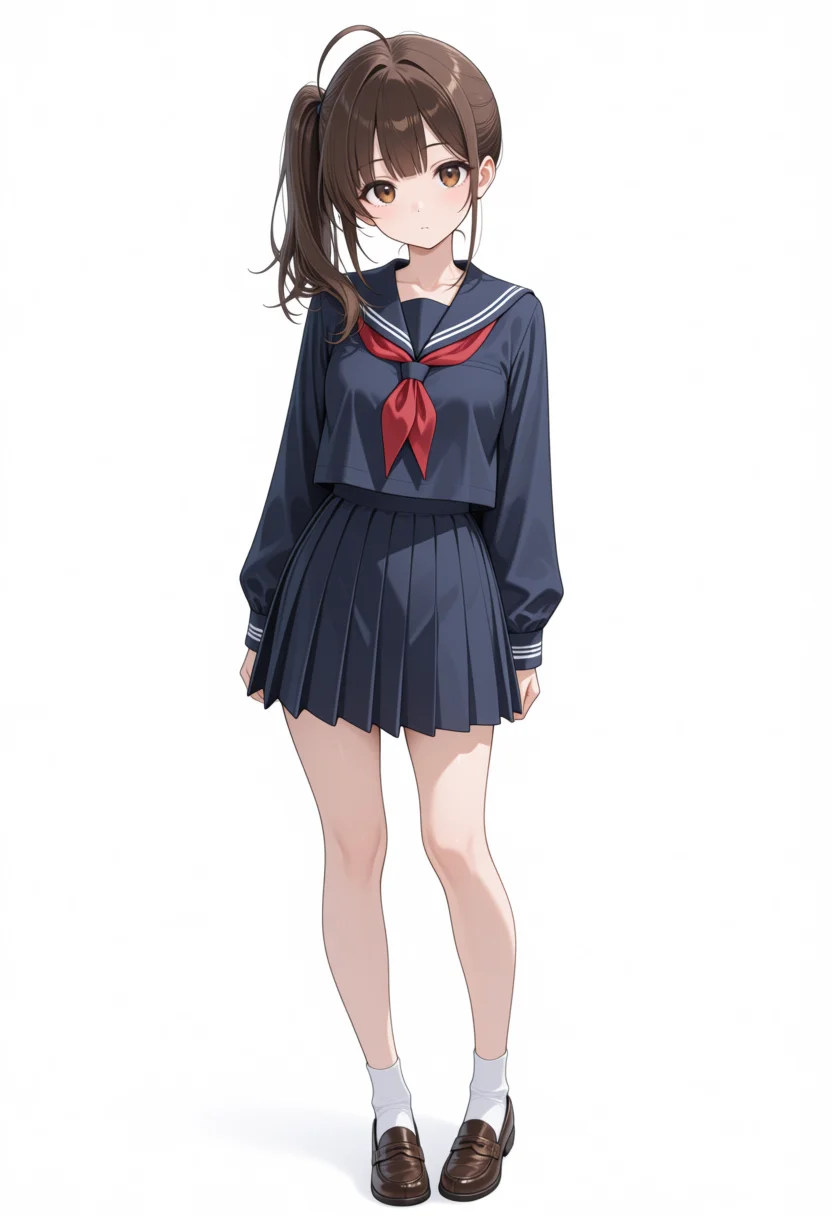
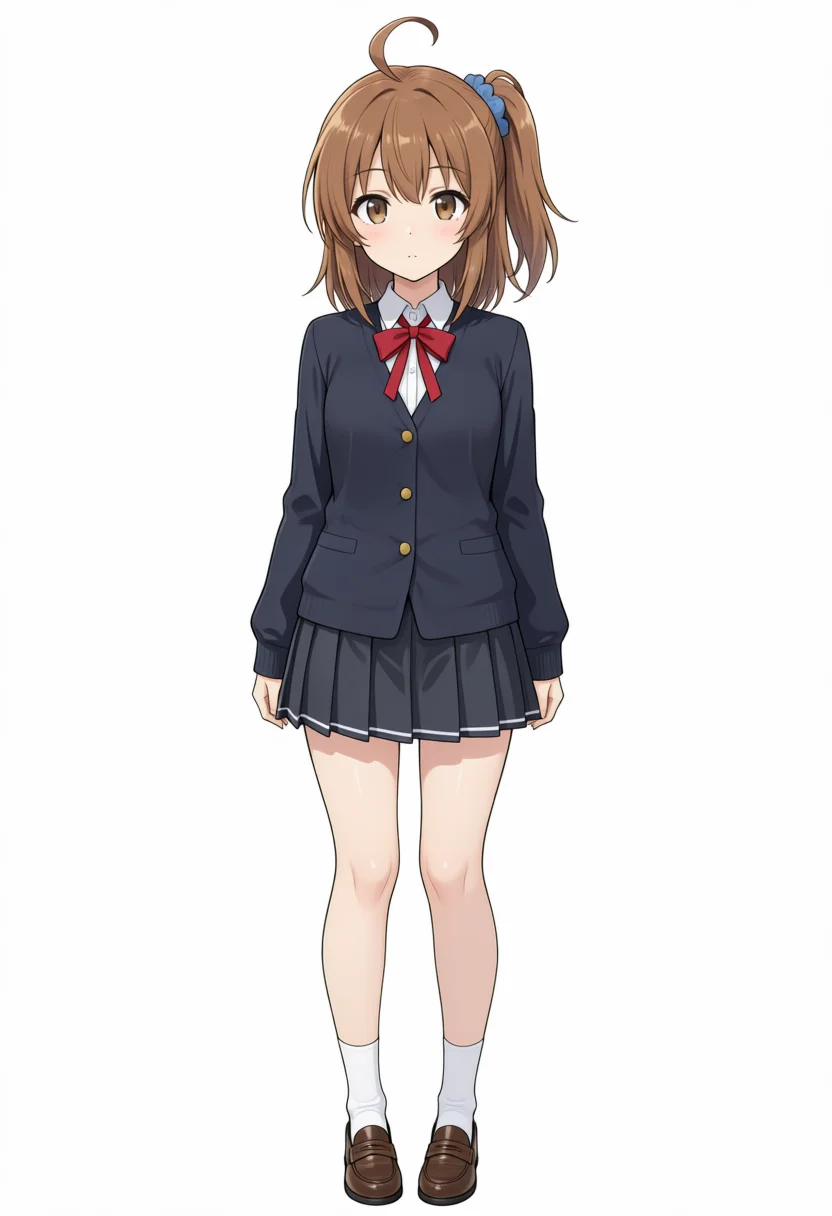
To verify whether applying LoRA at 4 steps caused distortion, I first evaluated Kana-chan’s full-body generation across different strengths.
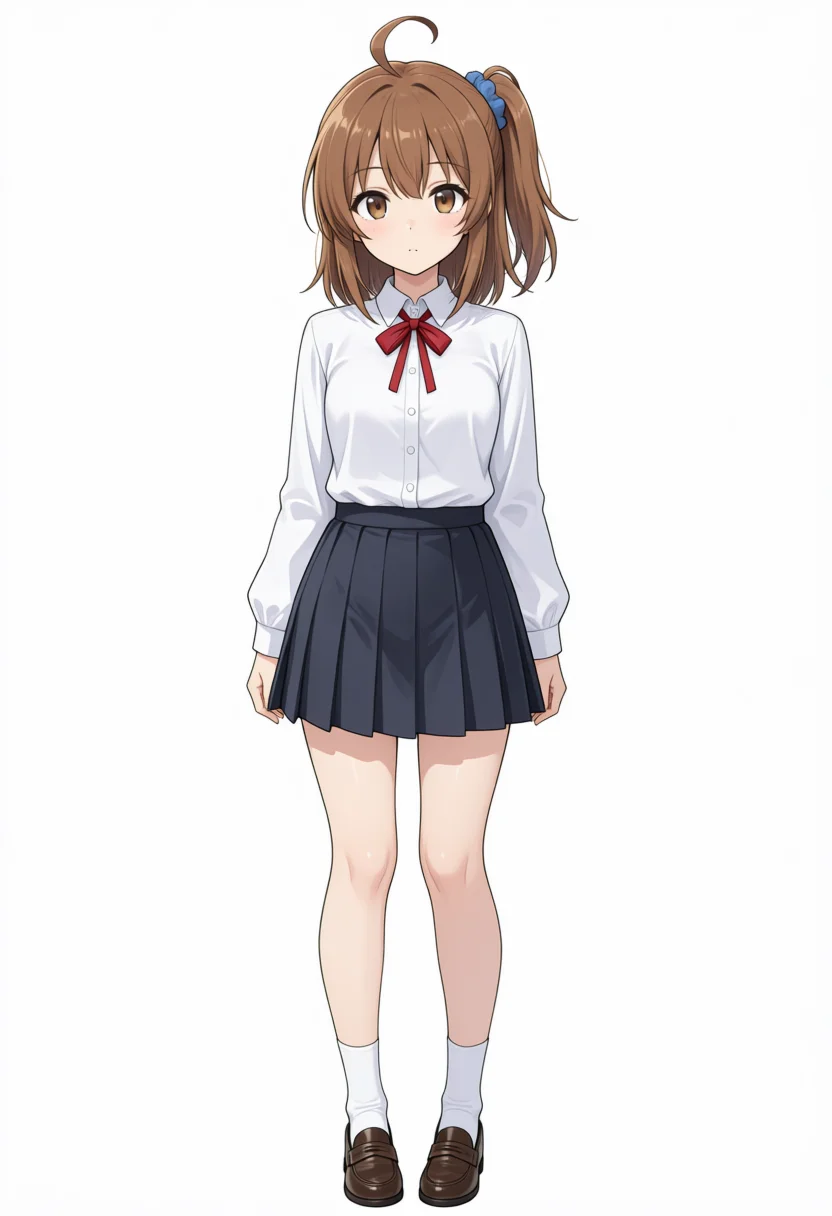
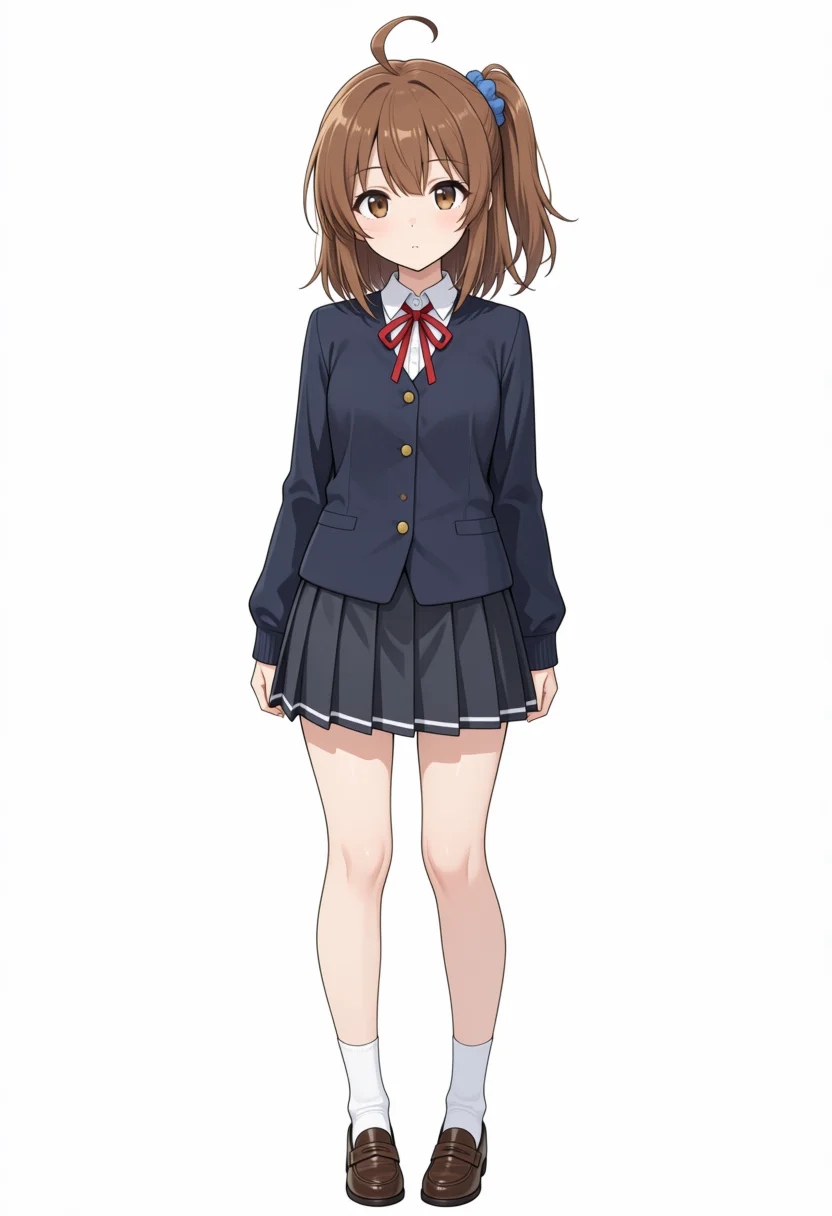
| Strength | Observations |
|---|---|
| No LoRA | Brown side ponytail and ahoge appear from tags, but clothing is navy sailor uniform and face is not Kana-chan |
| 1.0 | Ahoge, blue scrunchie side ponytail, navy blazer, and red ribbon all appear. Distinctly Kana-chan |
| 0.8 | White shirt with red ribbon, no blazer |
| 0.6 | Navy blazer with red ribbon. Nearly identical to 1.0 |
Because strength 1.0 showed no signs of degradation, I proceeded with strength 1.0 matching previous articles.
Base Art Style
Testing without any character LoRA using a blonde hair + white robe prompt.
White Background Full Body
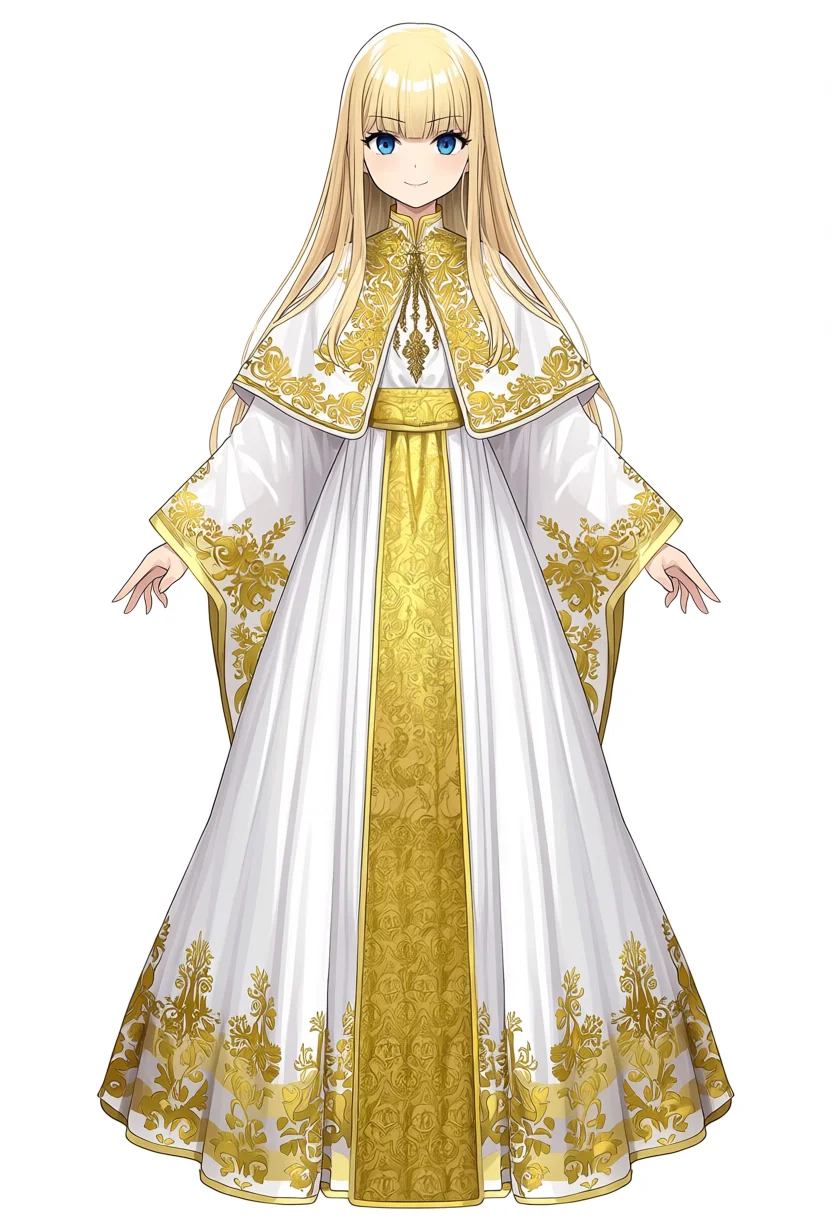
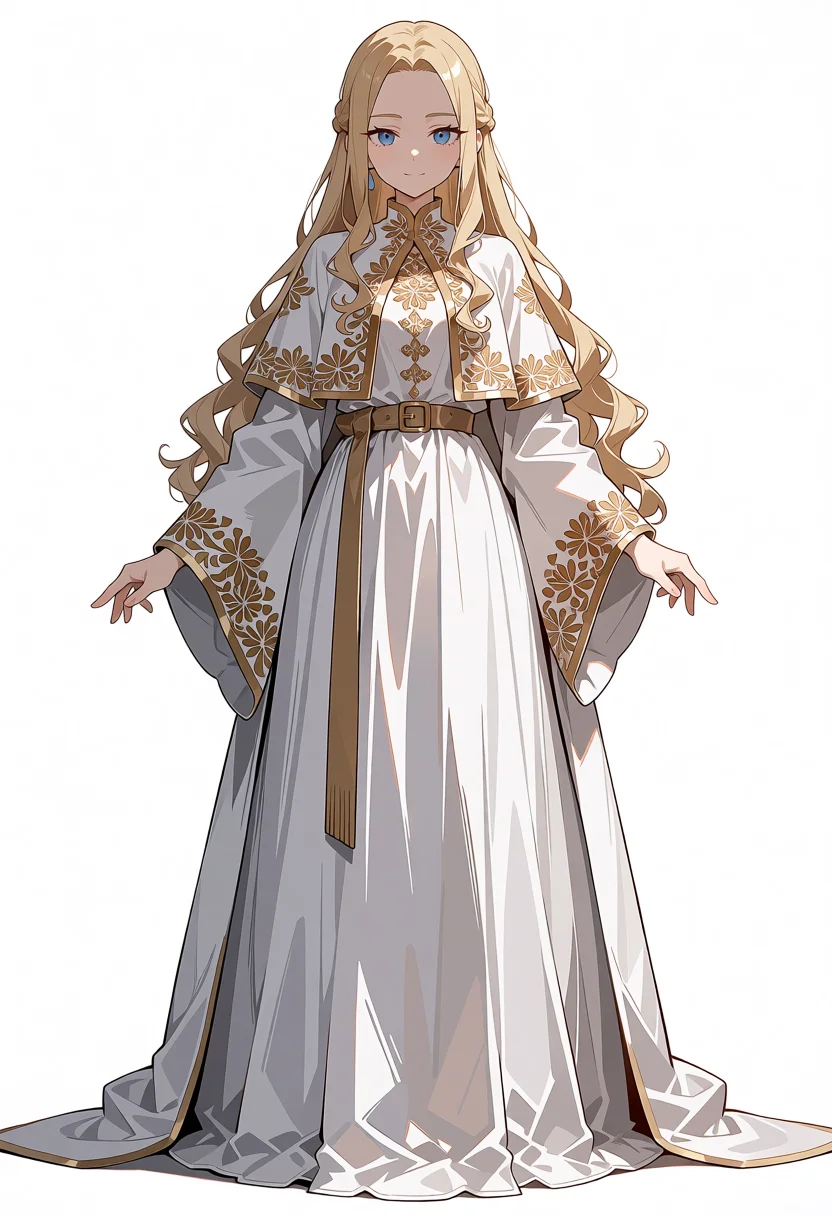
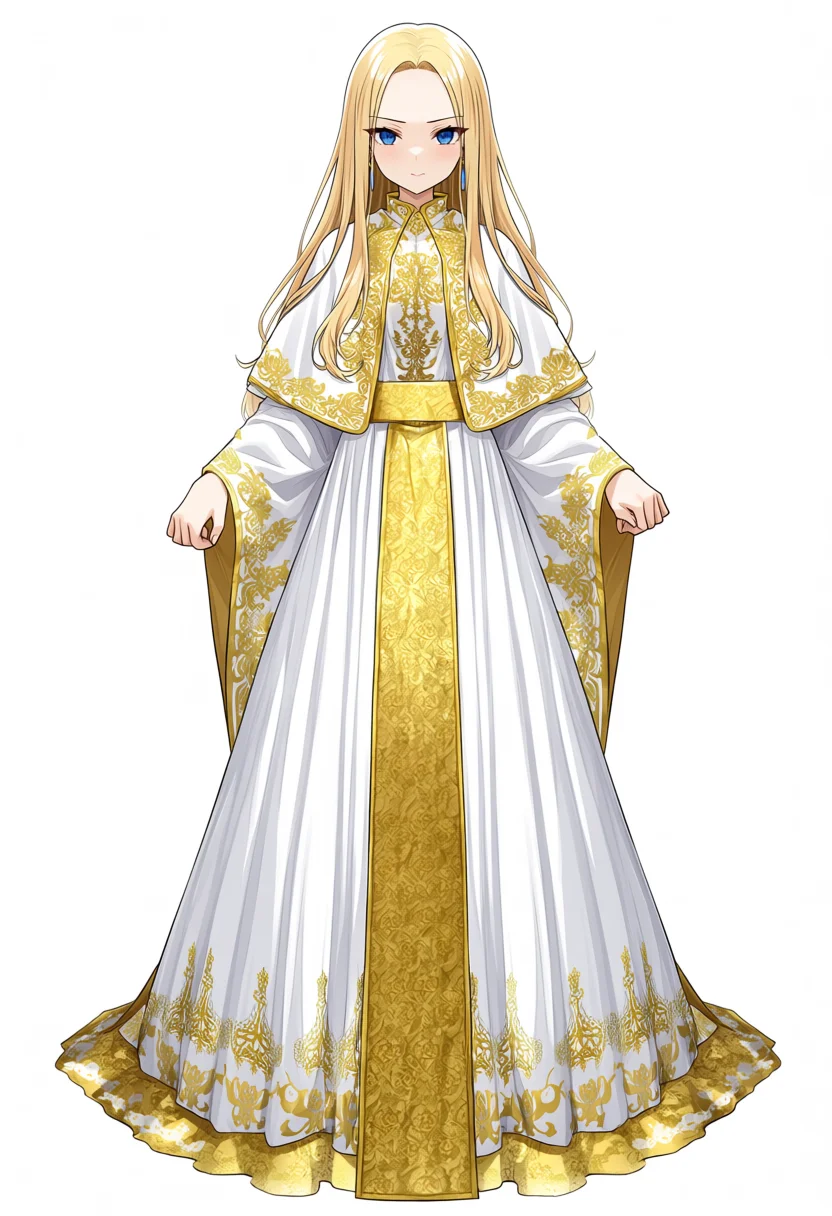
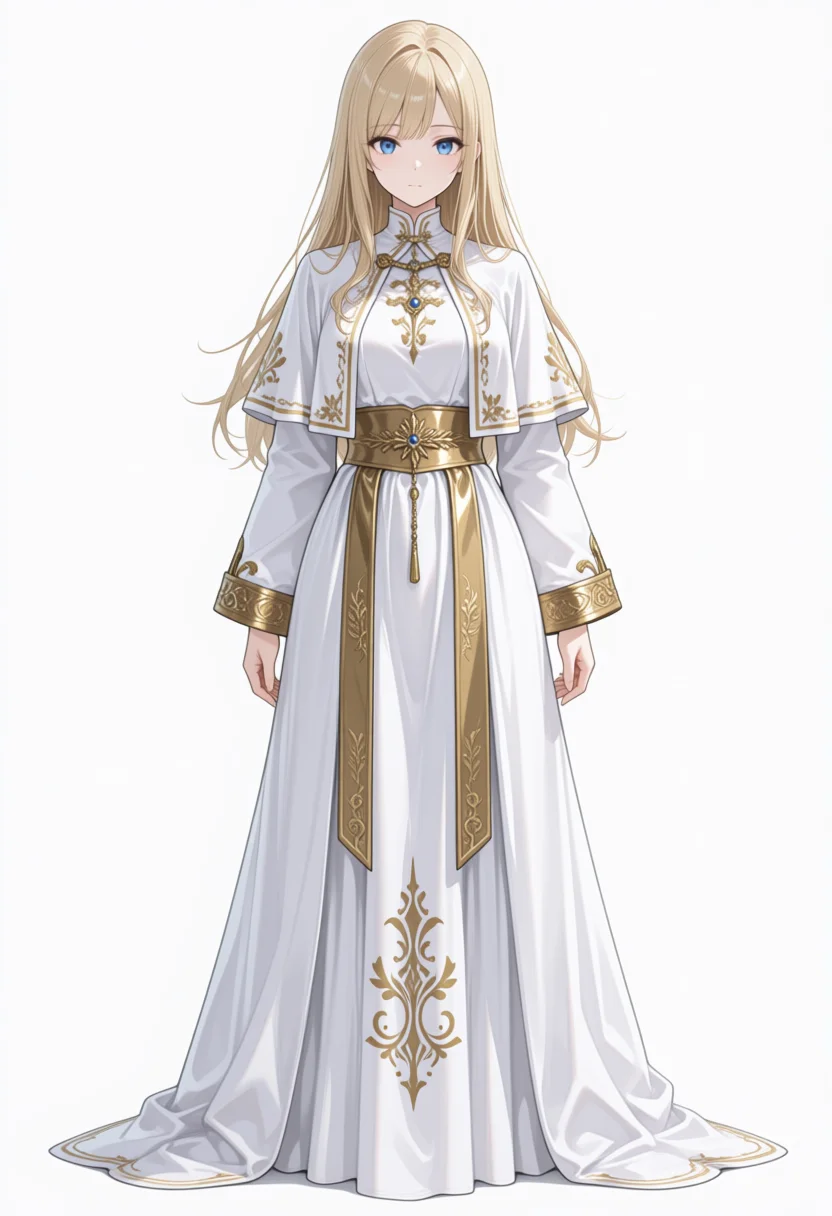
| Model | Observations |
|---|---|
| Base | Vivid gold apron and hem decoration. Straight blunt bangs, flat coloring |
| Turbo v1.1 | Wavy hair, brownish-gold sash and embroidery. Robe takes on grayish tones |
| Anima-2.9B | Straight hair with blunt bangs. Vivid gold apron and hem, close to Base |
| TinAnima | Forehead exposed, straight hair. Gold accents confined to sash, cuffs, and a single hem ornament, leaving more white robe surface. Shoulder capelet is smaller |
TinAnima rendered gold ornaments more conservatively than the other three models.
Linework is delicate, and color shading is softer.
Prompt
Base / Turbo v1.1 / Anima-2.9B:
masterpiece, best quality, safe, 1girl, solo, long blonde hair, blue eyes, white robe, gold embroidery, capelet, gold sash, long sleeves, long dress, standing, looking at viewer, full body, white backgroundTinAnima:
safe, 1girl, solo, long blonde hair, blue eyes, white robe, gold embroidery, capelet, gold sash, long sleeves, long dress, standing, looking at viewer, full body, white backgroundNegative prompt (ineffective on TinAnima at CFG 1):
worst quality, low quality, artist name, blurry, jpeg artifacts, chromatic aberrationRunning Across a Grass Field
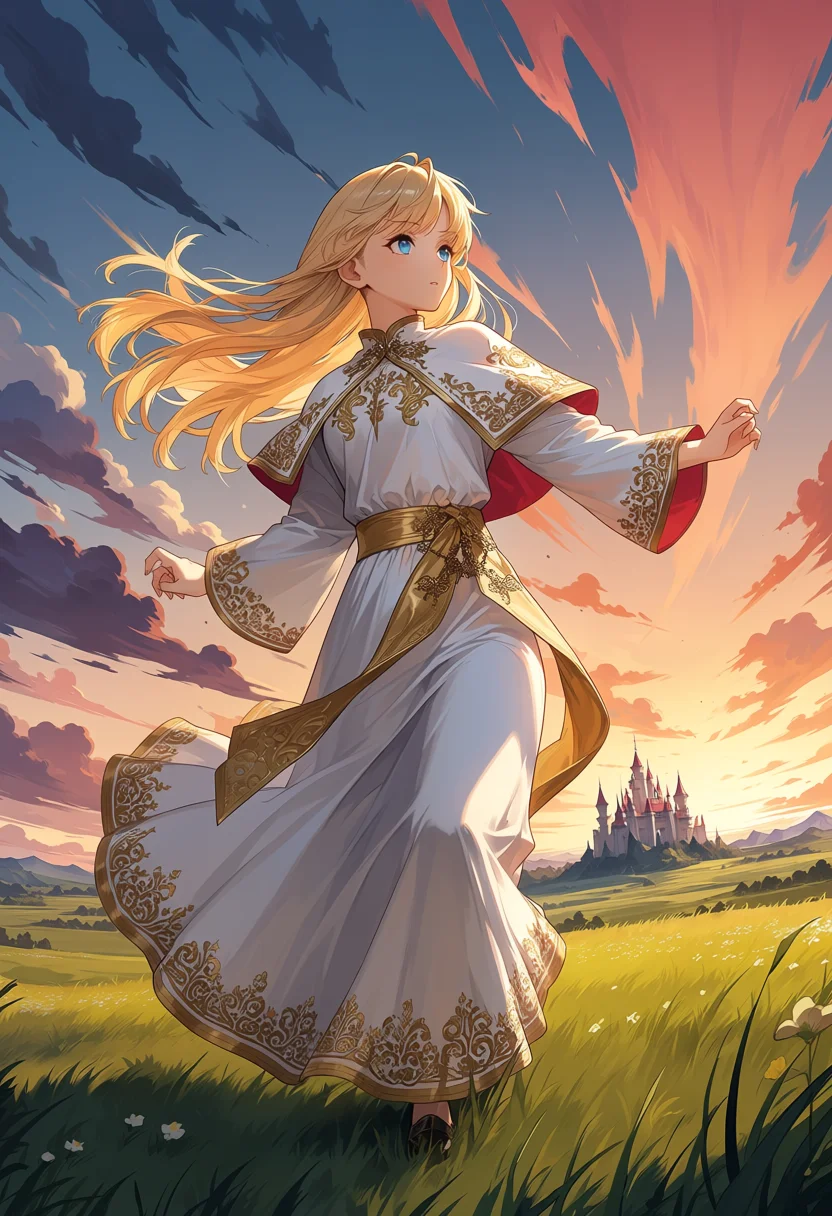
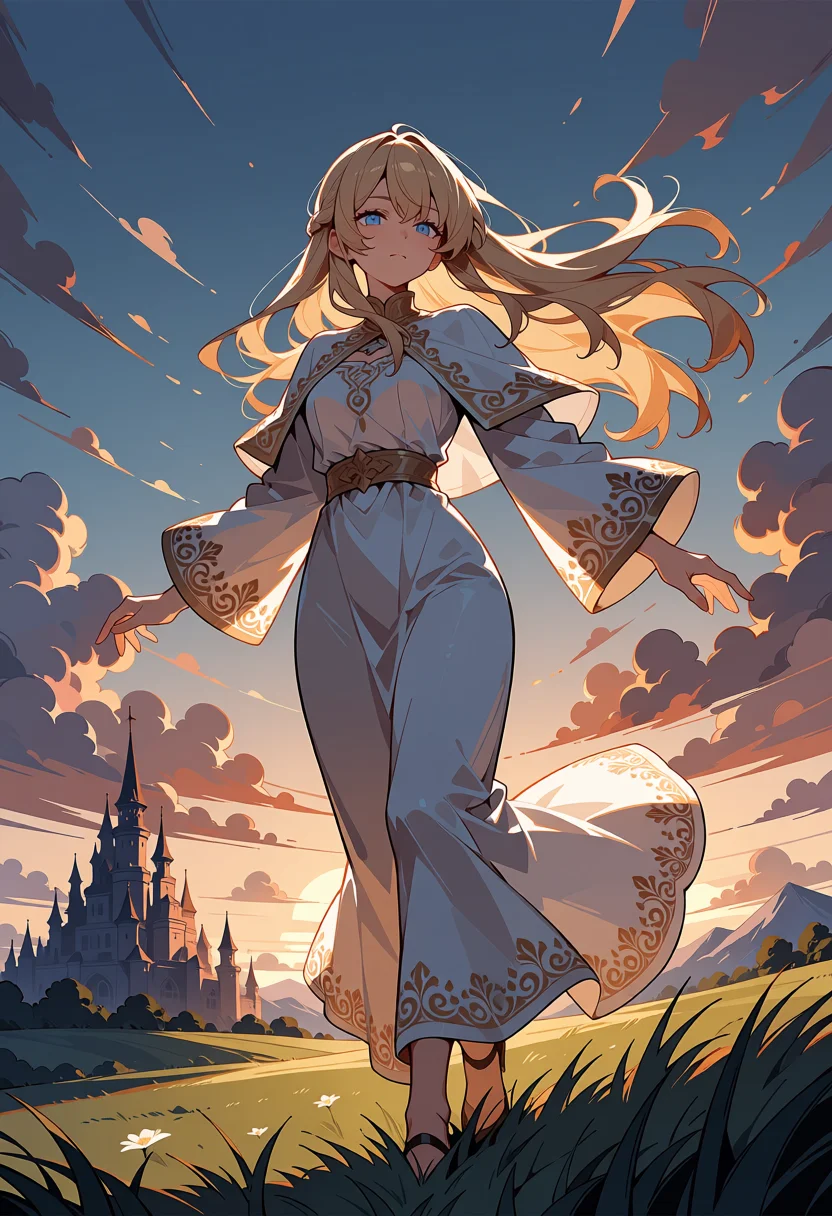
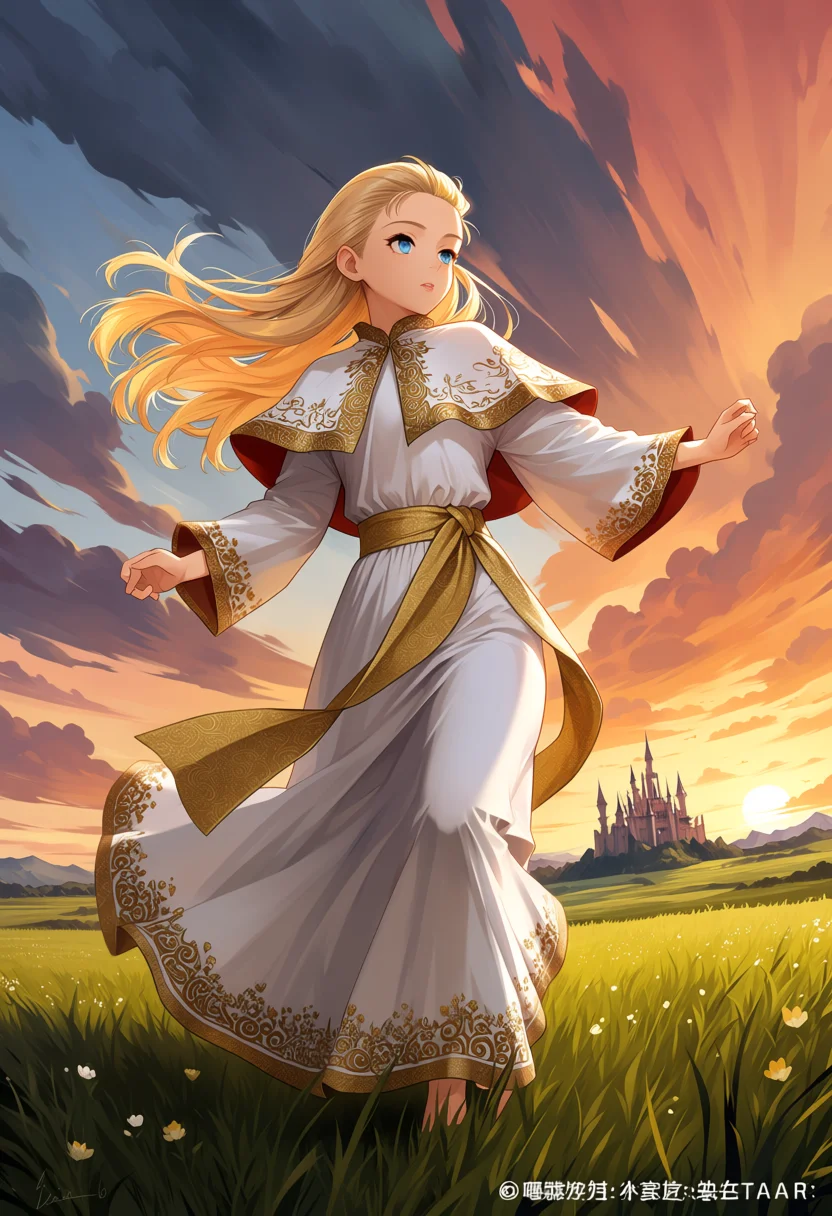
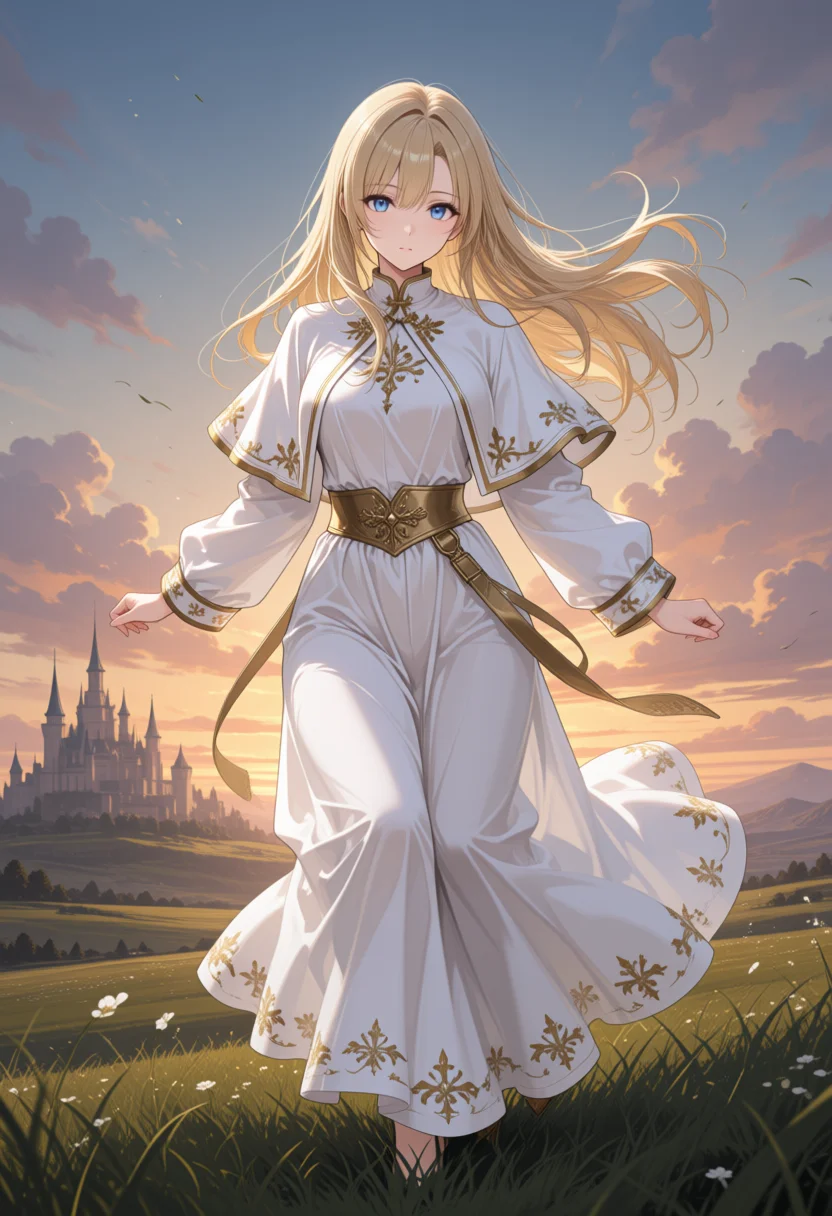
| Model | Observations |
|---|---|
| Base | Cloak lining turns red. Castle is distant and small |
| Turbo v1.1 | Silhouette of dark castle on left. Character walks facing forward |
| Anima-2.9B | Cloak lining is red. Distant castle on right. Text-like artifacts appear in lower right |
| TinAnima | Castle in background left, sky has soft sunset colors. Character stands with open arms facing forward. No text-like artifacts |
TinAnima rendered a softer sunset palette compared to the deep reddish skies of the other three.
The character stands facing forward rather than exhibiting a dynamic running motion.
Prompt
Base / Turbo v1.1 / Anima-2.9B:
masterpiece, best quality, safe, 1girl, solo, long blonde hair, blue eyes, white robe, gold embroidery, capelet, gold sash, long sleeves, long dress, running, wind, hair blowing, dynamic pose, fantasy landscape, castle in background, sunset sky, dramatic clouds, grass fieldTinAnima omitted the leading masterpiece, best quality, . Negative prompt was identical to the white background test.
Character LoRA Evaluation
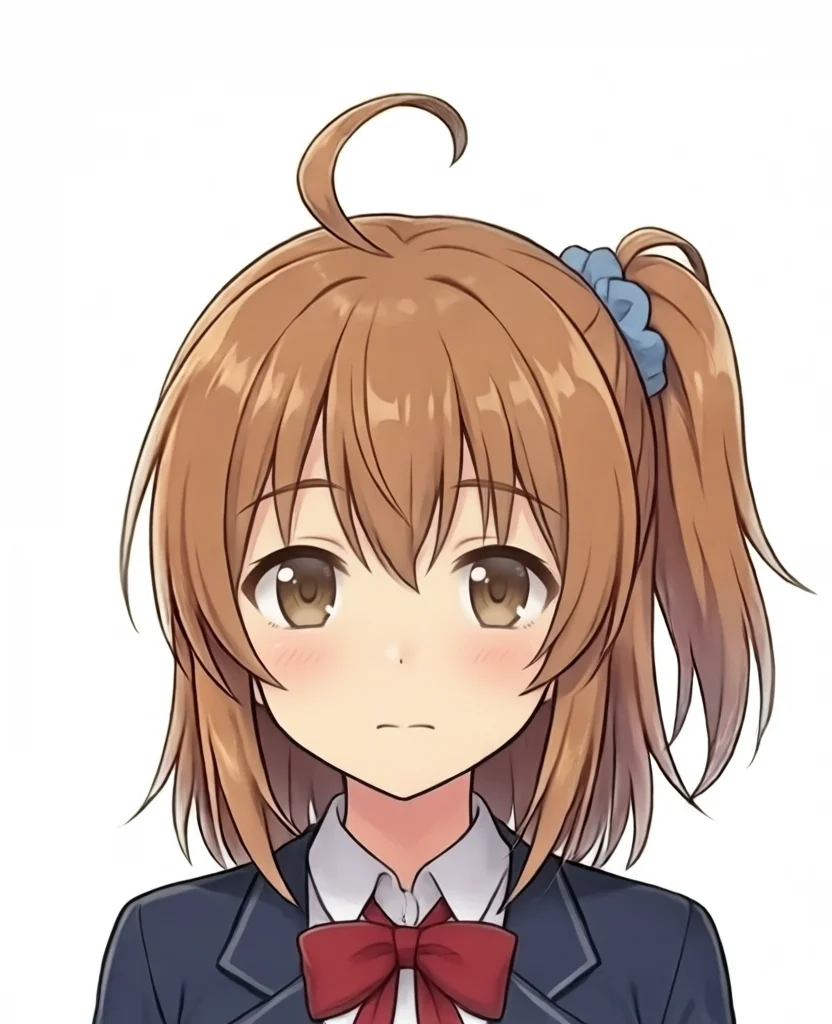
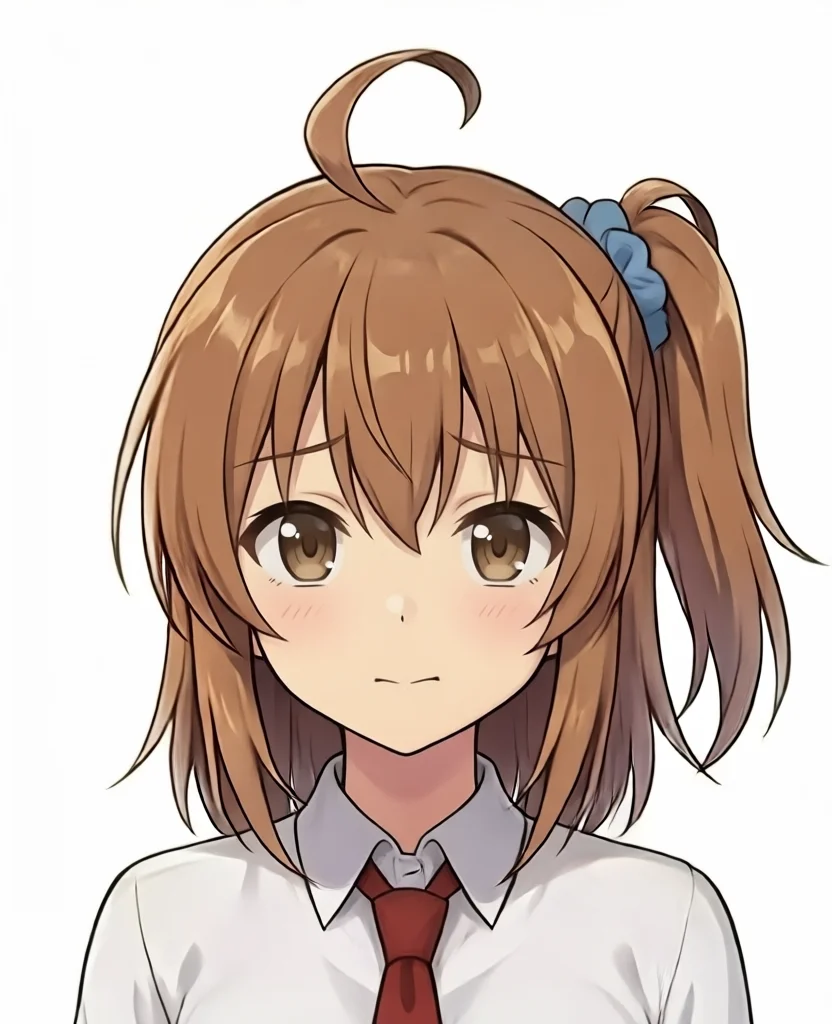
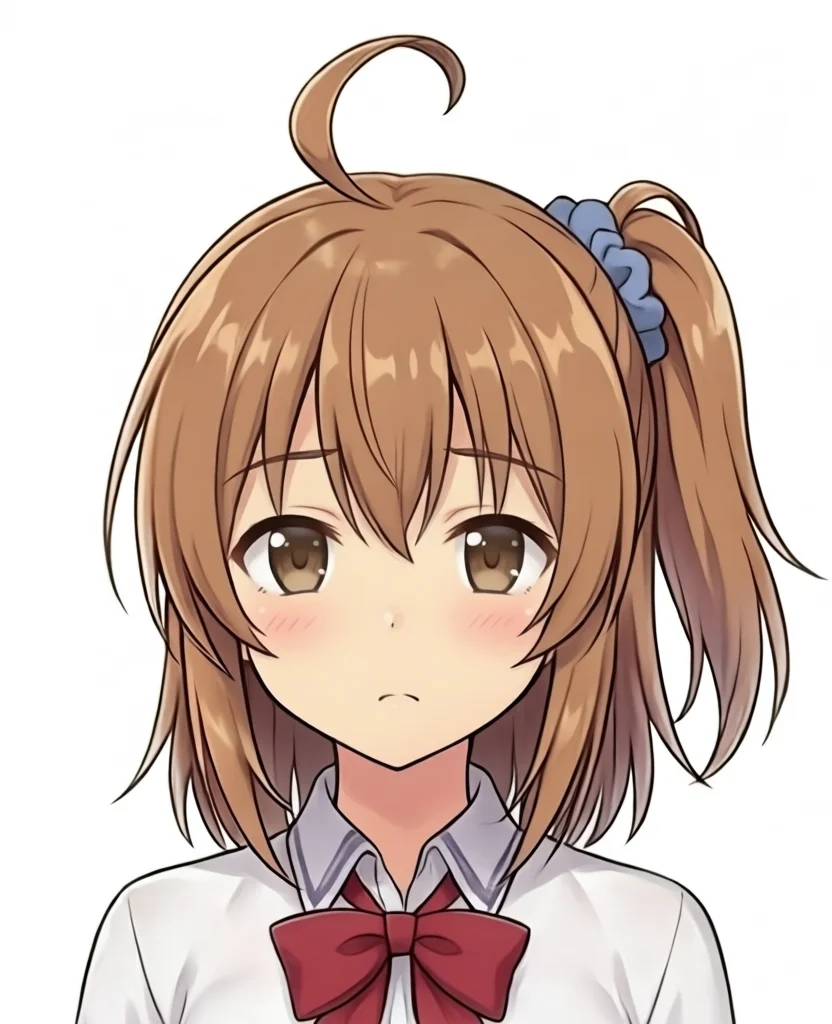
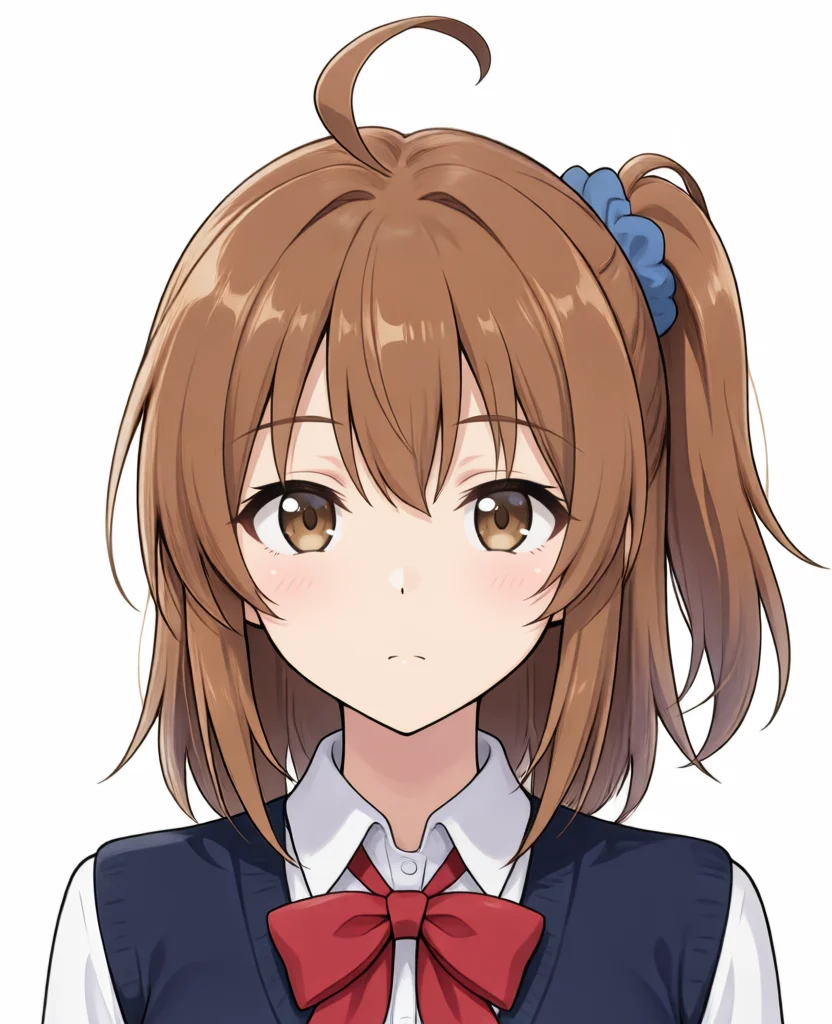
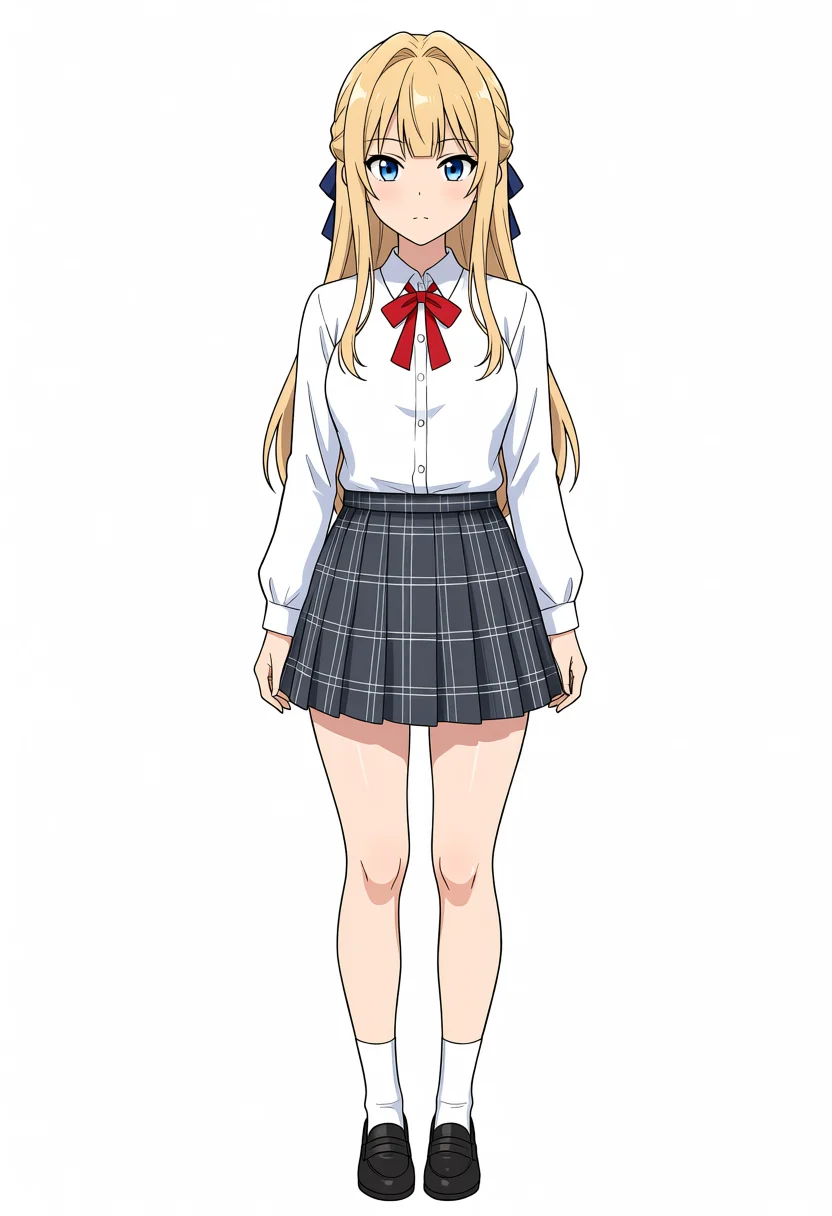
Testing reproduction using Kana-chan (brown side ponytail) and Kei-chan (blonde long hair).
Kana-chan
Full body:
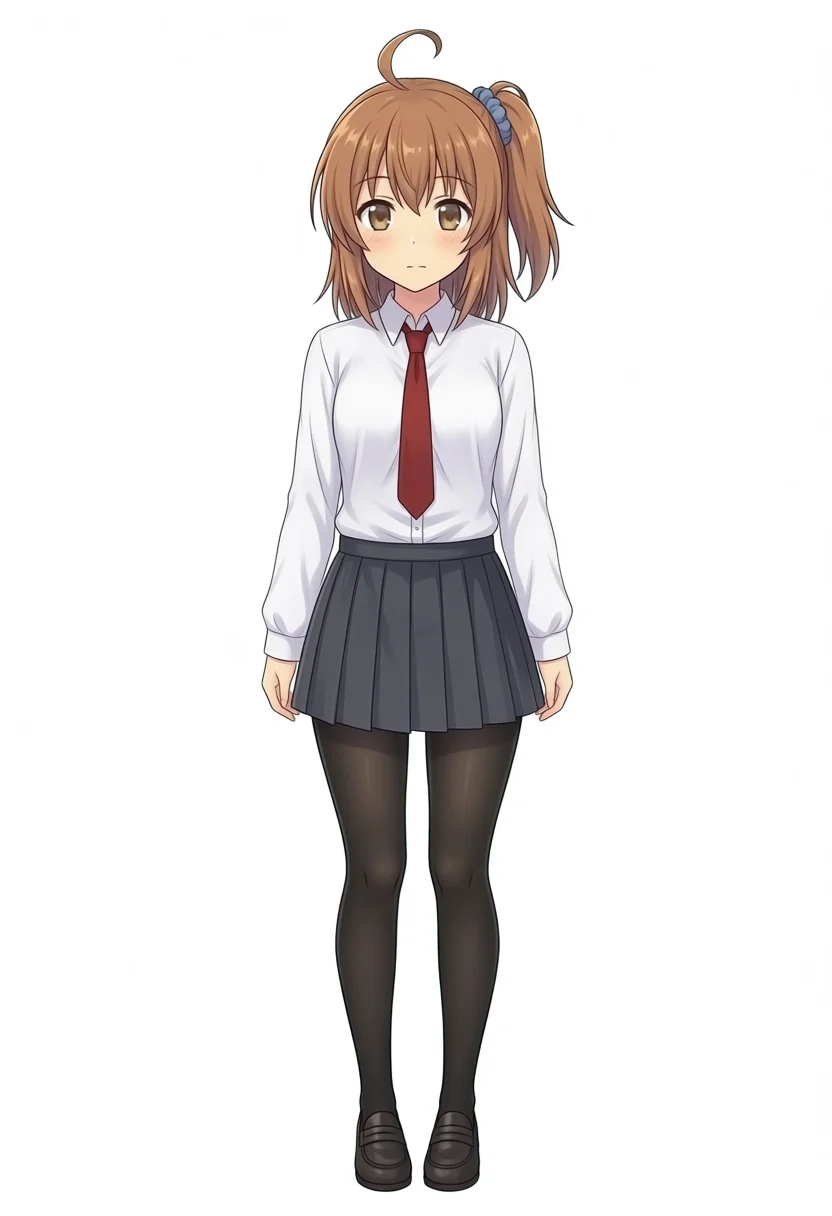
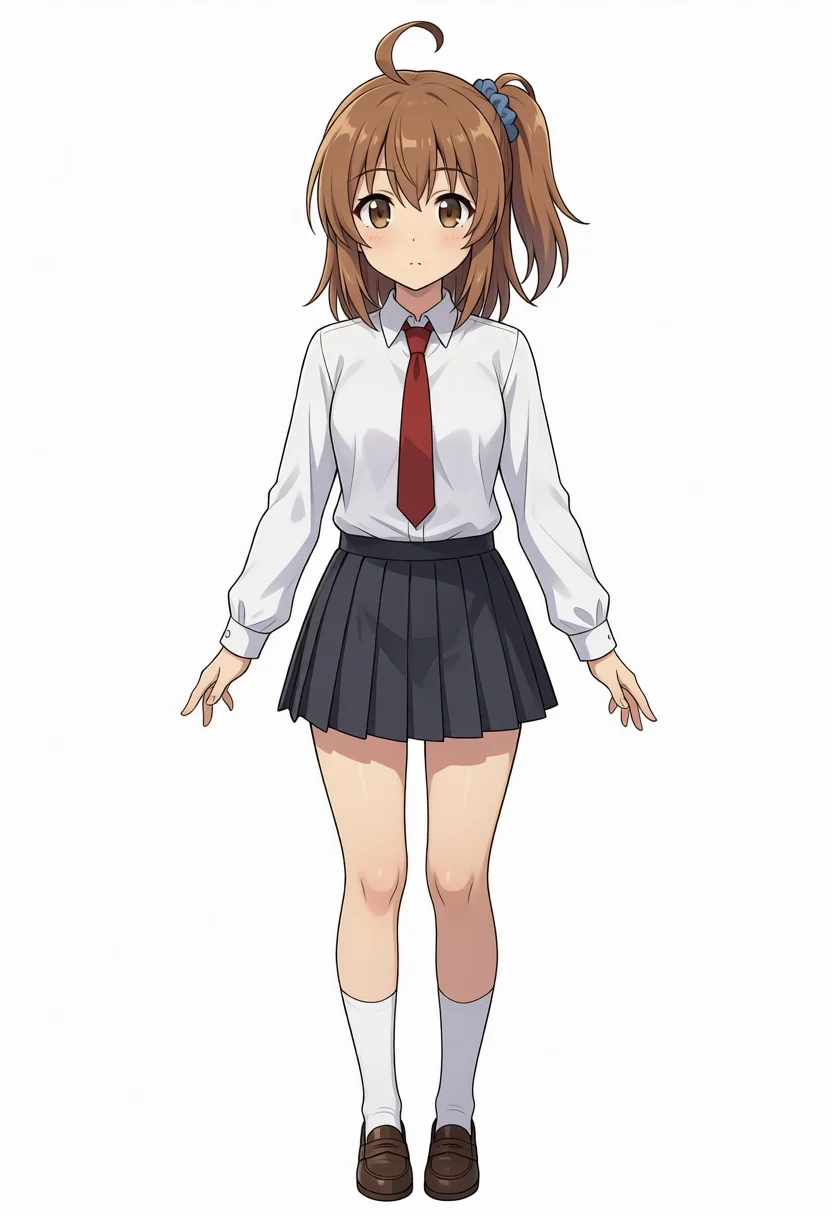
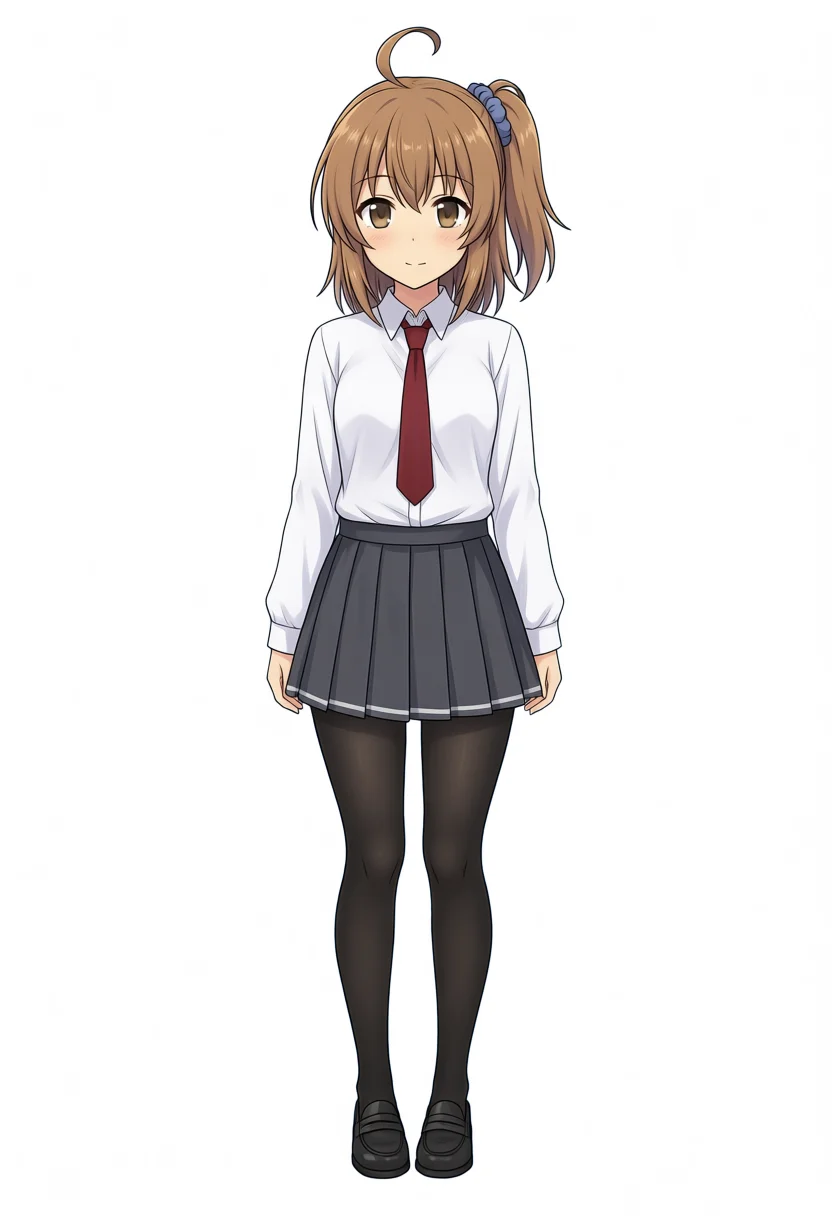
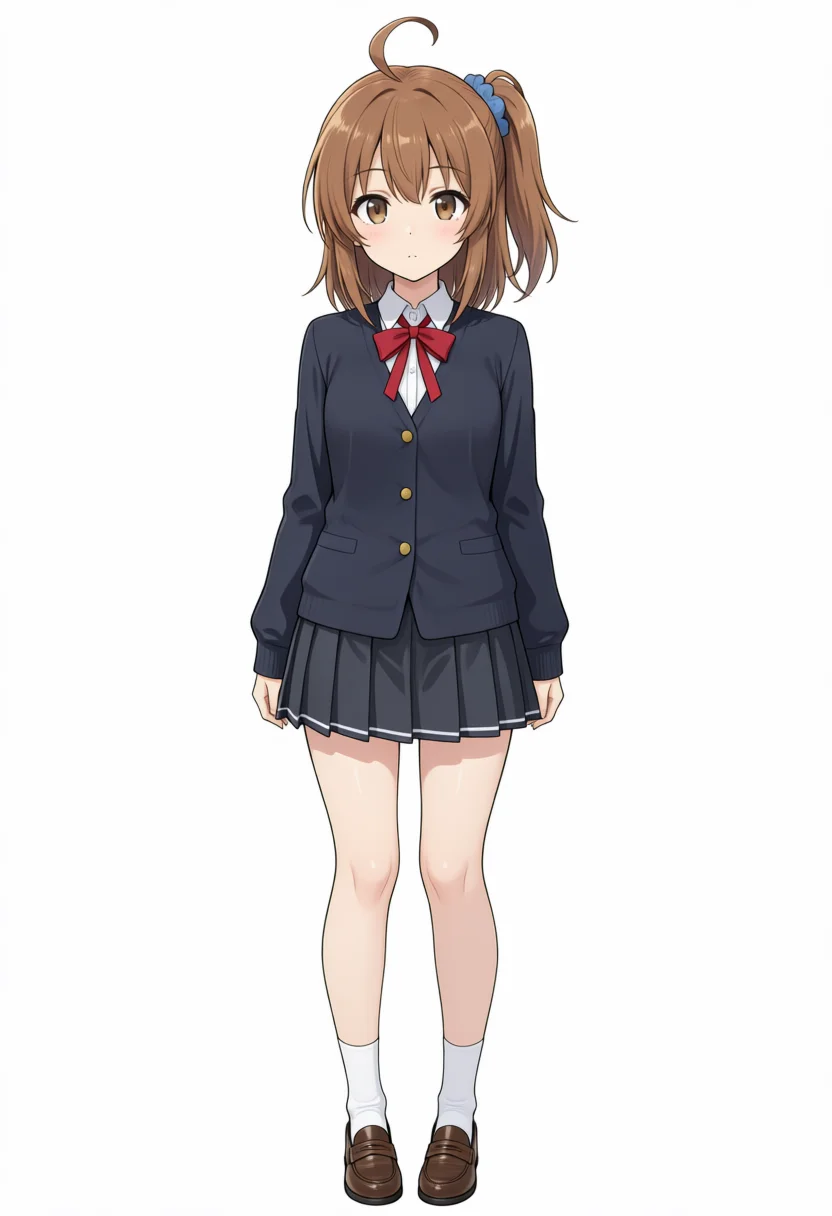
Bust portrait (prompt changed to upper body, portrait):
| Model | Observations |
|---|---|
| Base | All traits present. Full body wears black tights; bust portrait wears navy blazer with large red ribbon |
| Turbo v1.1 | All traits present. Full body wears knee-high socks |
| Anima-2.9B | All traits present. Full body wears red tie + black tights; bust portrait wears red butterfly ribbon |
| TinAnima | Hairstyle and eyes match. Full body wears navy blazer + red butterfly ribbon; bust portrait wears navy vest + red butterfly ribbon. No necktie |
TinAnima accurately reproduced Kana-chan’s ahoge, scrunchie side ponytail, and brown eyes.
Where the other three produced white shirts for full-body, TinAnima rendered a navy blazer.
Eyes are somewhat wider horizontally with thicker eyelashes compared to the other models.
Kei-chan
Full body:
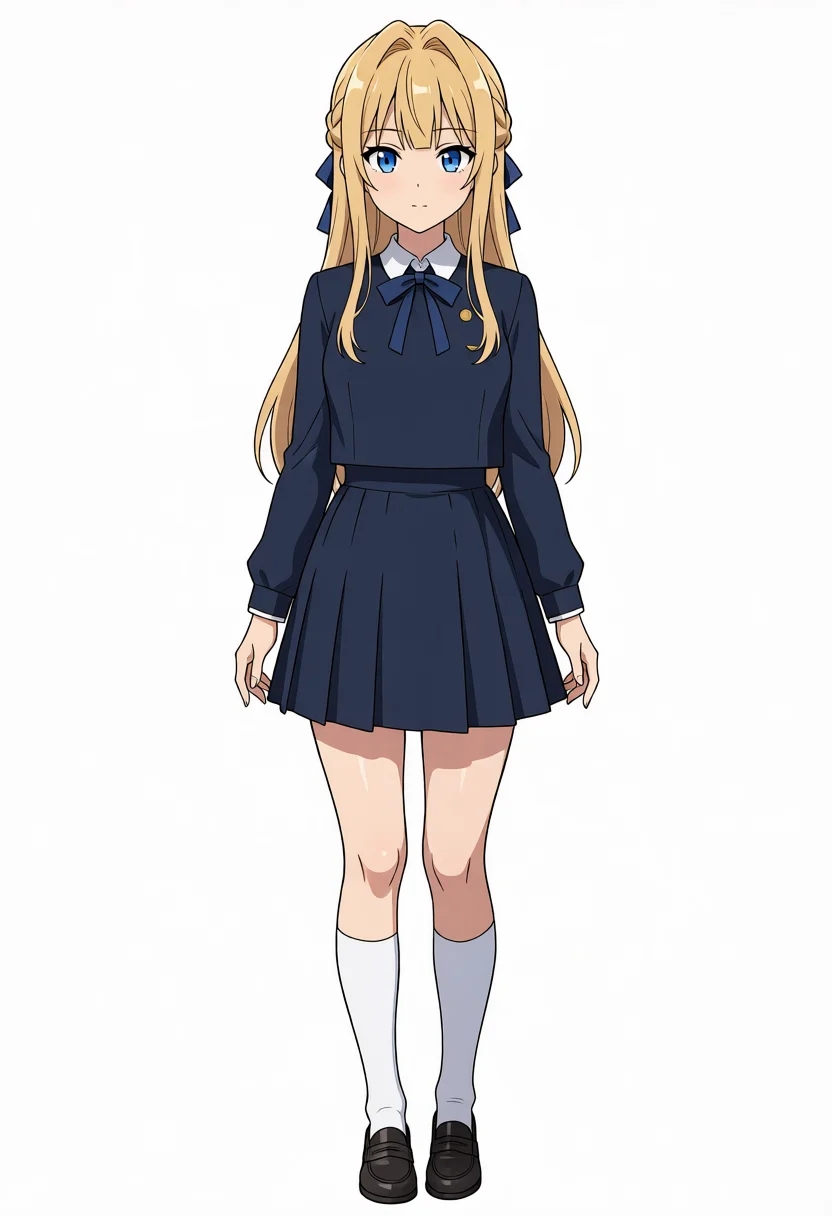
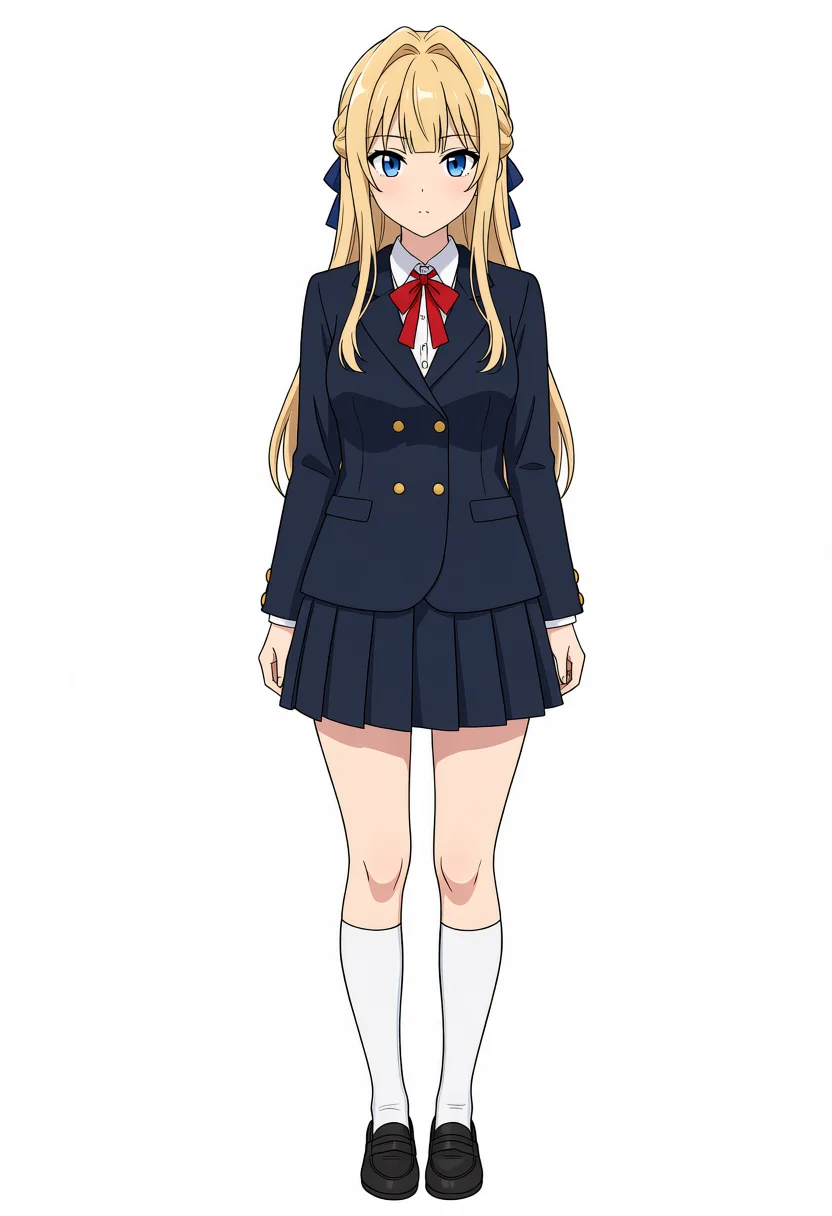
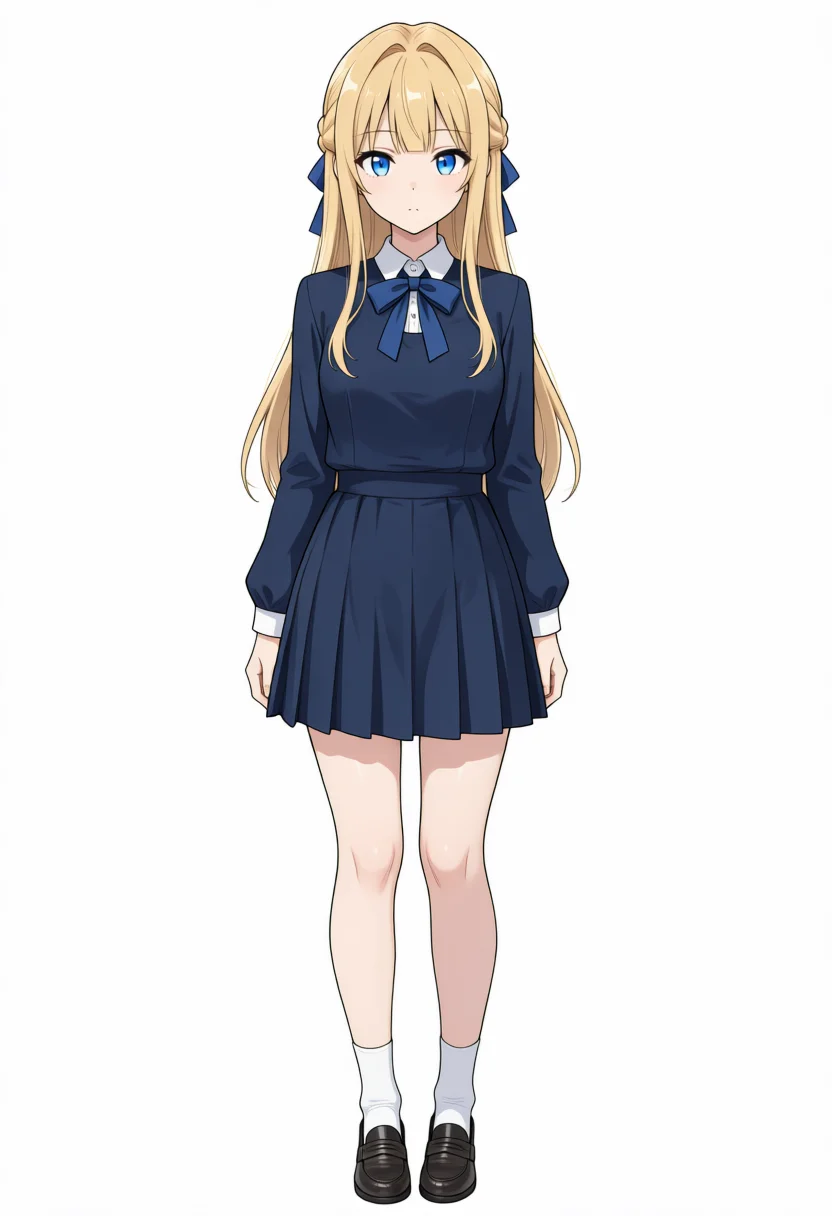
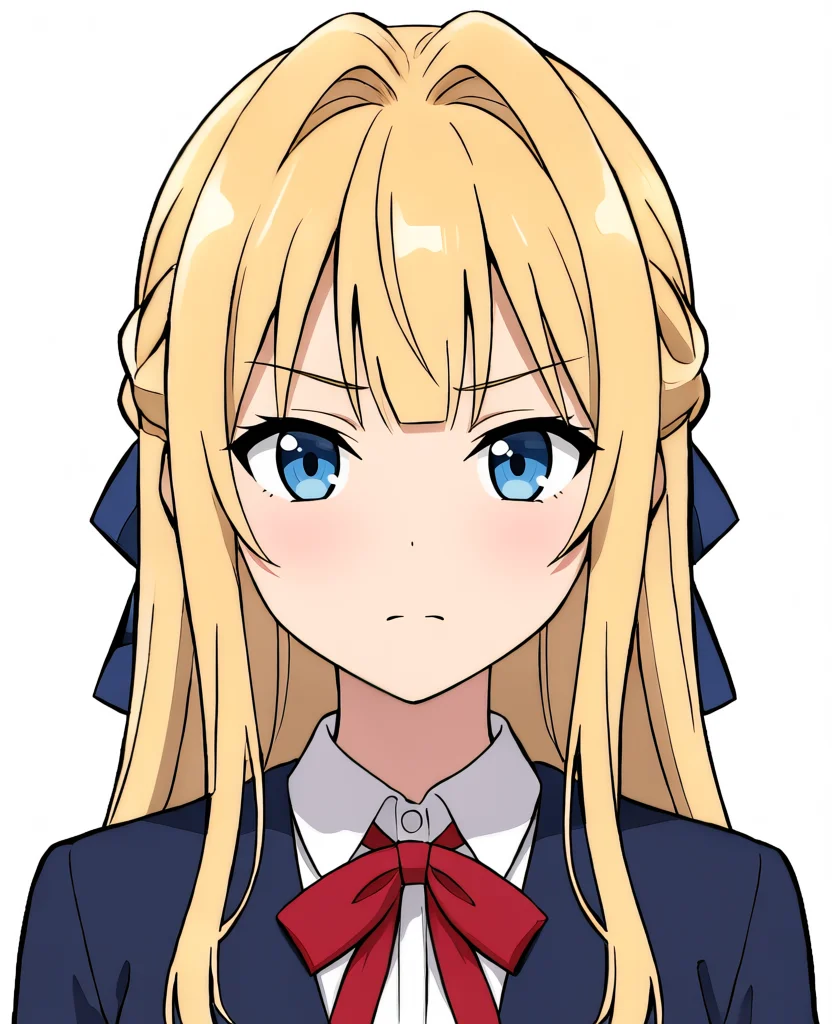
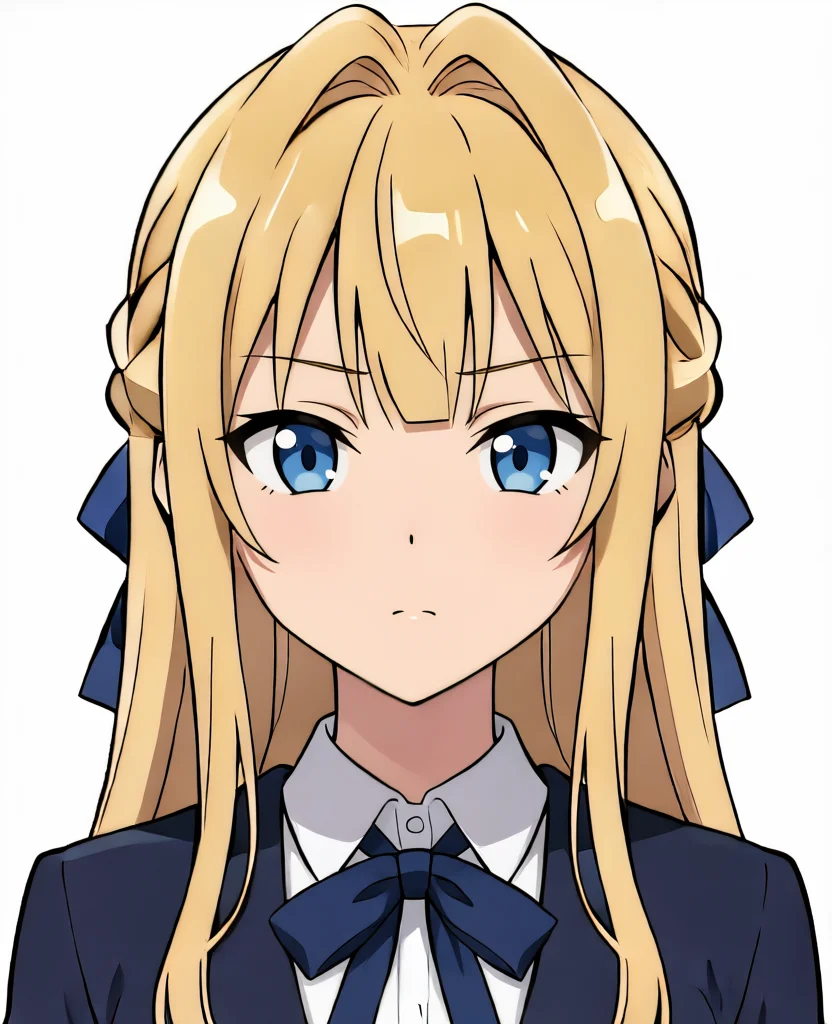
Bust portrait (prompt changed to upper body, portrait):
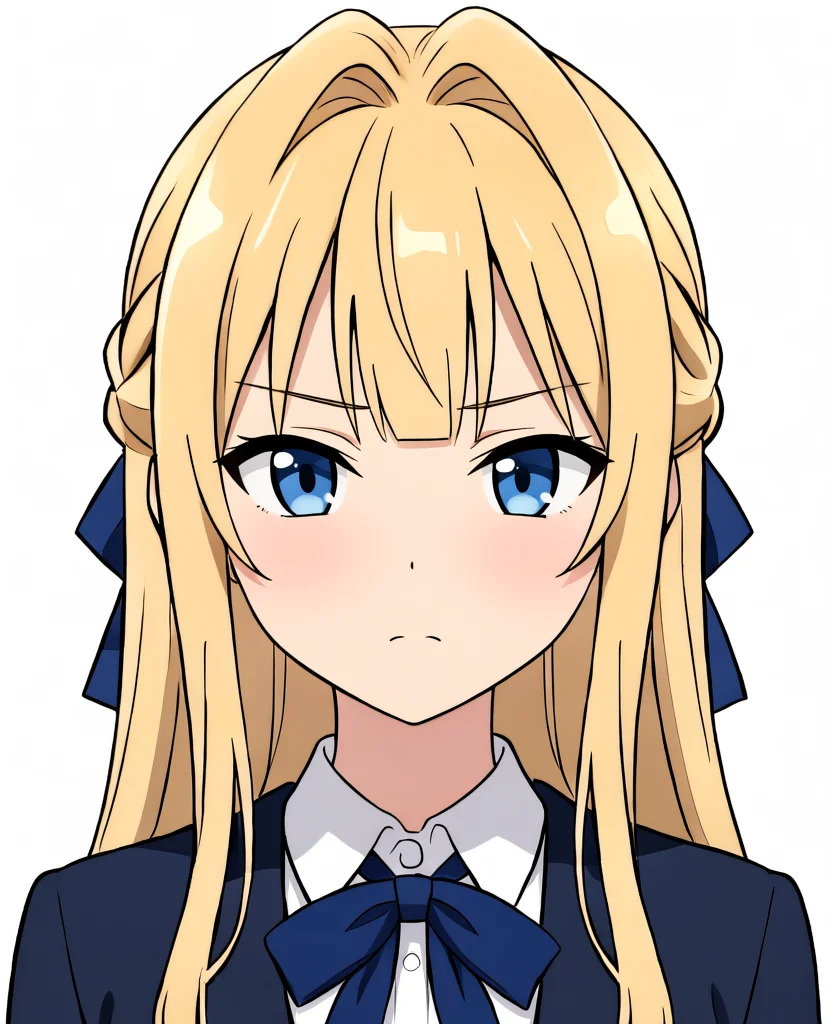
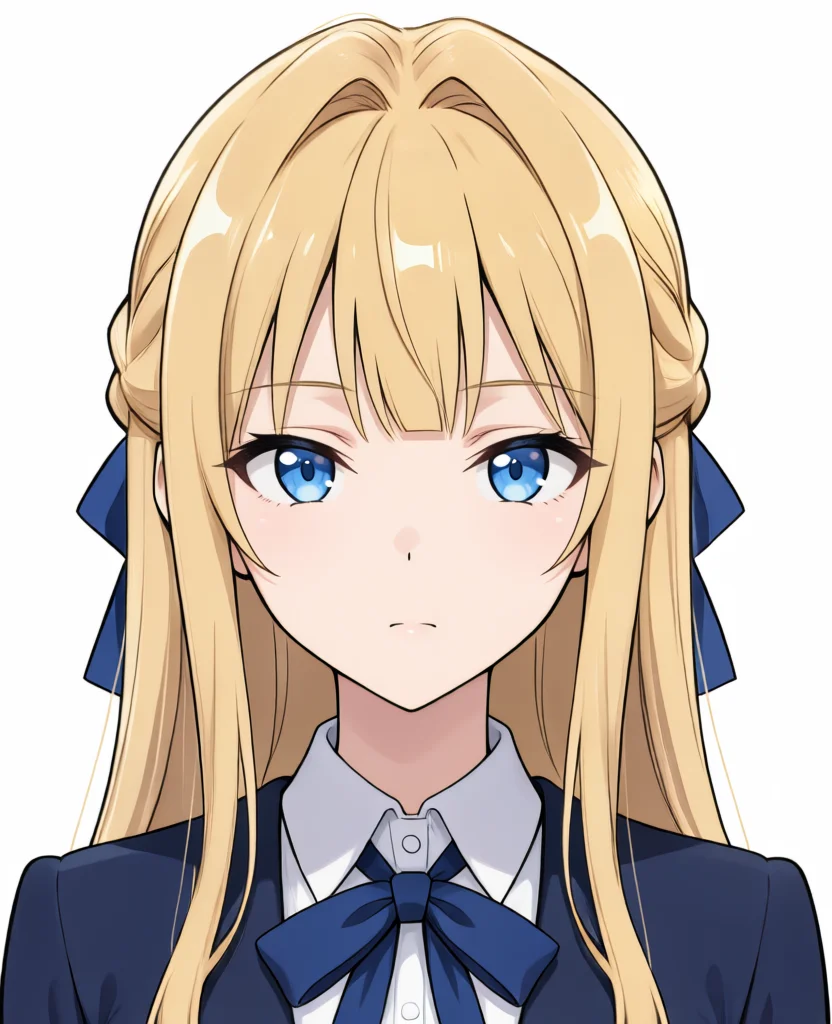
| Model | Observations |
|---|---|
| Base | Hair features and red ribbon tie present. Plaid skirt |
| Turbo v1.1 | Hair features present, but neck ribbon turns navy. Full body jacket is also navy |
| Anima-2.9B | Hair features present. Neck ribbon is red on full body, navy on bust. Full body wears double-breasted navy blazer |
| TinAnima | Hair features present. Neck ribbon is navy on both full body and bust. Full body wears one-piece style navy uniform |
TinAnima captured Kei-chan’s braid, blunt bangs, and blue hair ribbon.
The neck ribbon rendered as navy in both full body and bust, as blue ribbon in the prompt bled into the collar ribbon.
Her gaze in the bust portrait appears gentler than the sharper upturned eyes in the other models.
Prompts (Kana / Kei)
Kana full body (TinAnima):
safe, 1girl, solo, kanachan, brown hair, side ponytail, ahoge, brown eyes, school uniform, full body, standing, looking at viewer, white background, simple backgroundKei full body (TinAnima):
safe, 1girl, solo, keichan, blonde hair, long hair, blunt bangs, blue ribbon, blue eyes, school uniform, full body, standing, looking at viewer, white background, simple backgroundBase, Turbo v1.1, and Anima-2.9B included masterpiece, best quality, at the beginning.
For bust portraits, full body, standing was replaced with upper body, portrait, and full body, knees, feet, lower body was added to negative prompts.
Negative prompt:
worst quality, low quality, blurry, lowres, jpeg artifacts, bad hands, bad anatomy, fused fingers, fused legs, fused limbs, extra arms, extra legs, conjoined twins, deformed faceTwo Characters Standing Side by Side
Specifying standing side by side, full body with left/right positions and individual character traits:
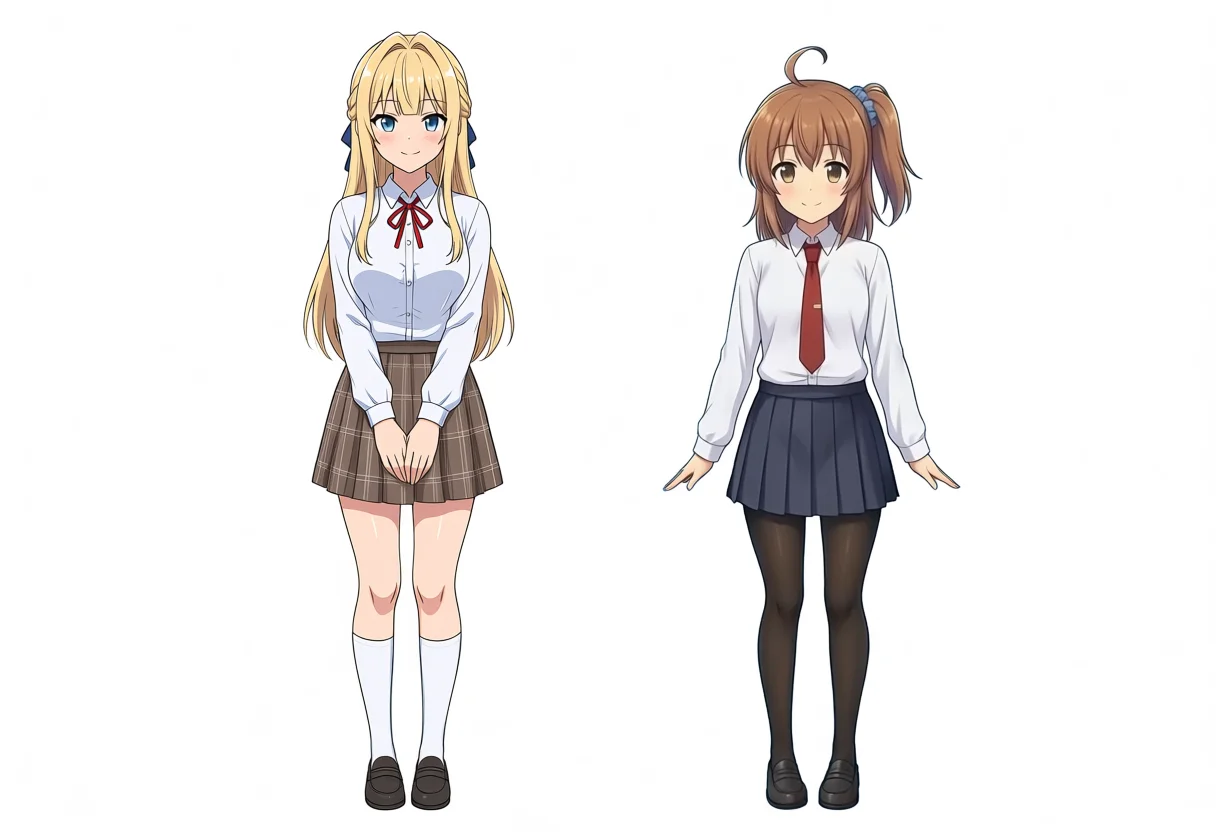
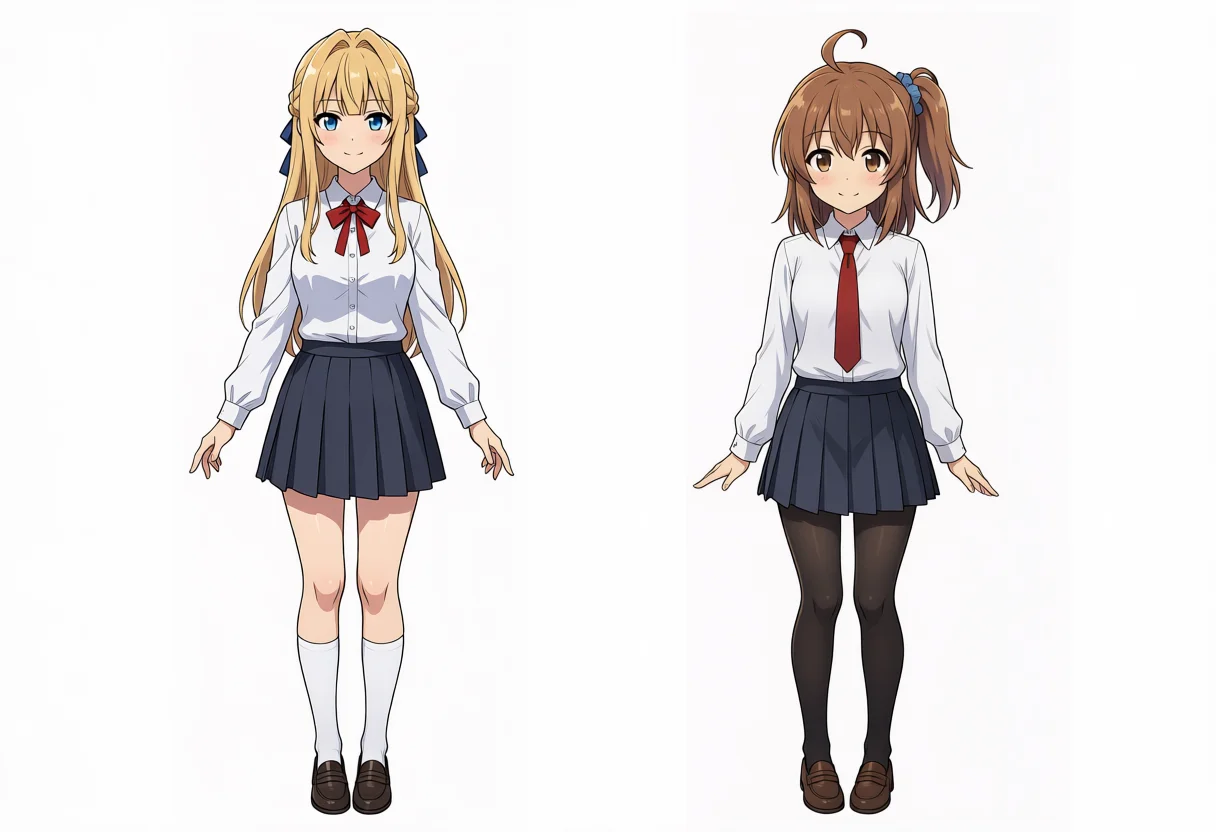
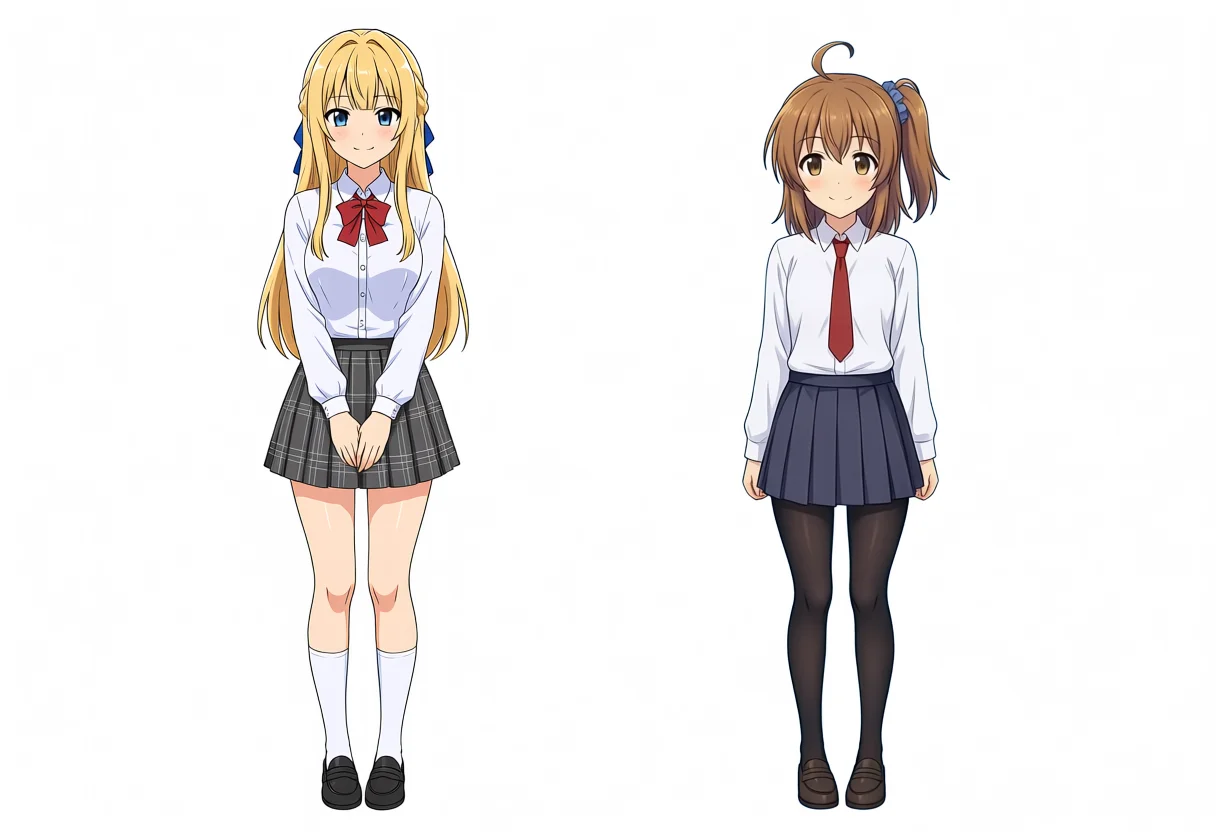
| Model | Observations |
|---|---|
| Base | Kei on left, Kana on right, no ahoge leakage. Kei has red ribbon, Kana wears black tights |
| Turbo v1.1 | Trait separation and ahoge identical. Kei has red ribbon, Kana wears red tie + black tights |
| Anima-2.9B | Trait separation and ahoge identical. Kei has red ribbon + grey plaid, Kana wears red tie + black tights |
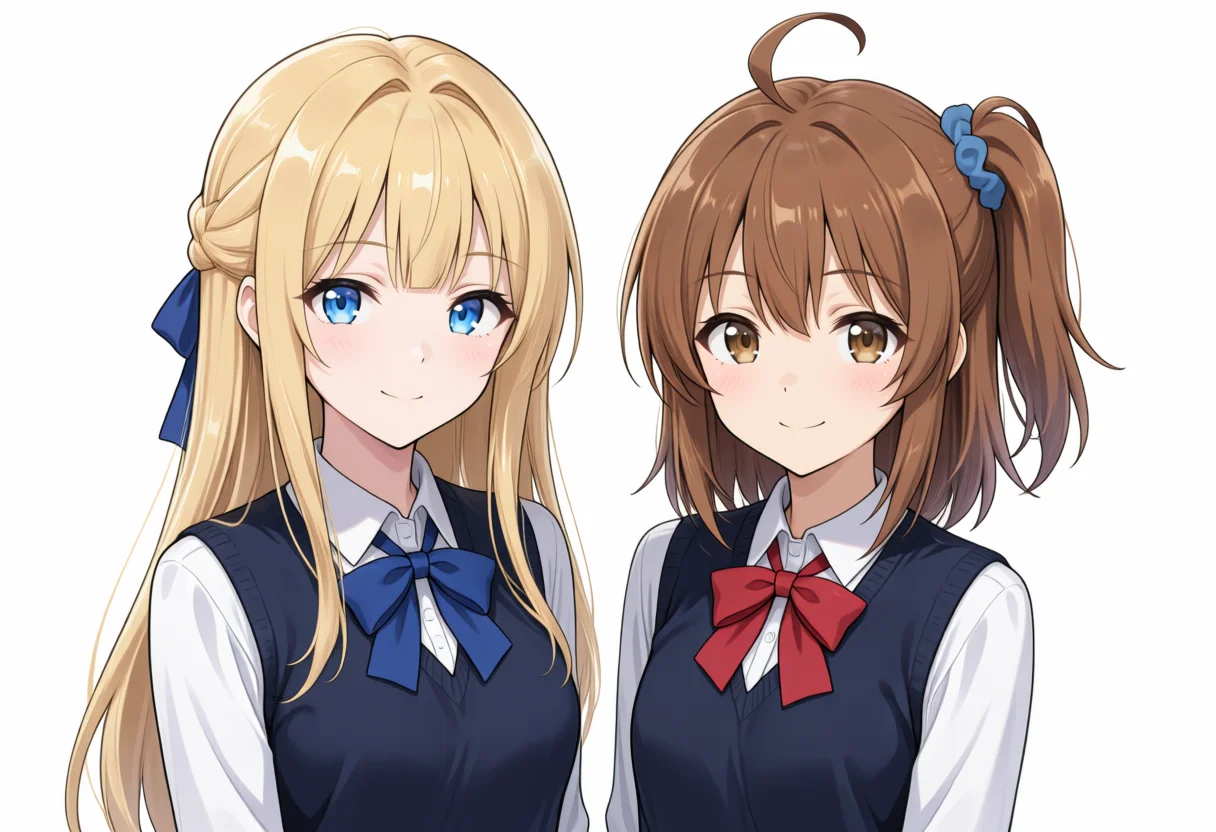
| TinAnima | Kei on left, Kana on right, no ahoge leakage. Ignores full body, framing from chest up. Kei wears navy ribbon, Kana wears red butterfly ribbon; both wear navy vests |
TinAnima was the only model that framed the composition from the chest up despite explicit full body prompts.
However, character differentiation was completely successful, with no trait blending between hairstyles or eye colors.
Prompt
TinAnima:
safe, 2girls, multiple girls, two different girls, kanachan, keichan, standing side by side, full body, looking at viewer, smile, school uniform, keichan on the left has long blonde hair with blunt bangs and a blue ribbon, kanachan on the right has brown hair with a side ponytail and an ahoge, white background, simple backgroundBase / Turbo v1.1 / Anima-2.9B added masterpiece, best quality, at start. Negative prompt added 1girl, solo to the character negative.
Background Detailing
Kana-chan seated by the window in a cafe:
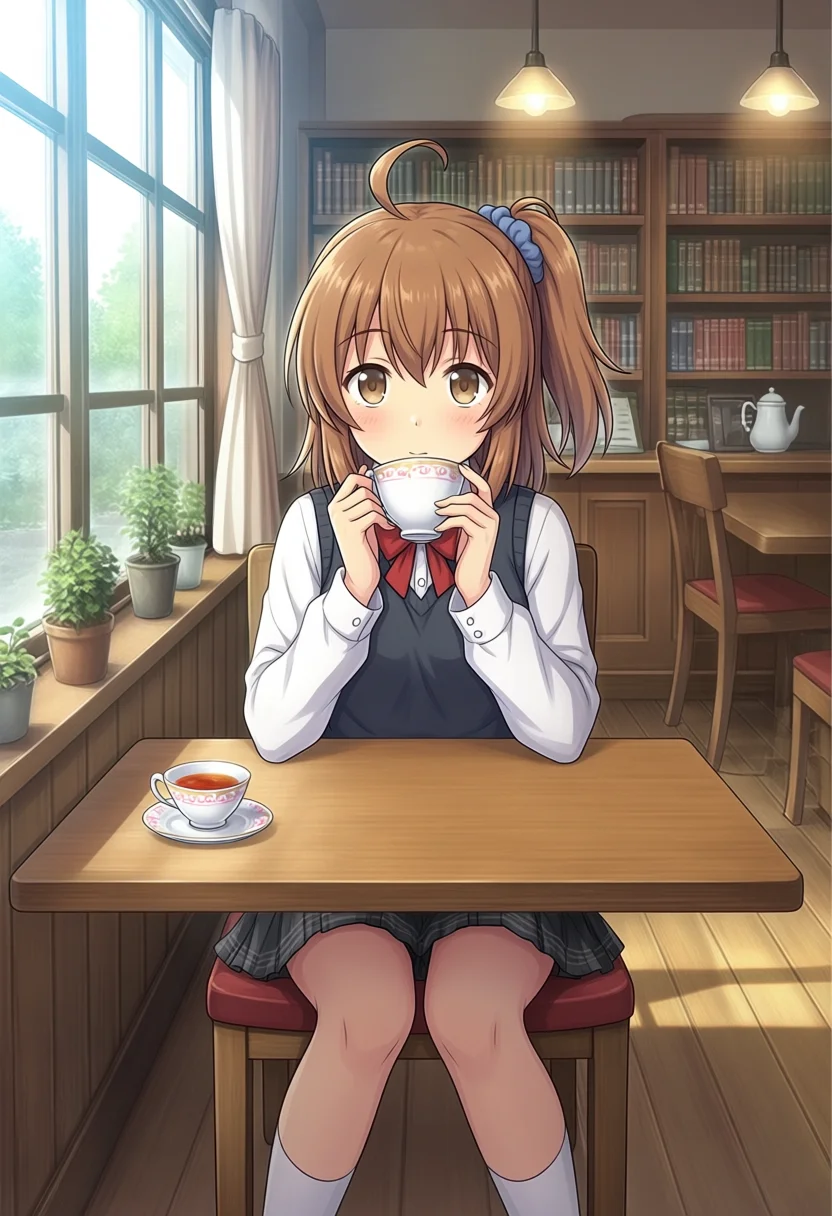
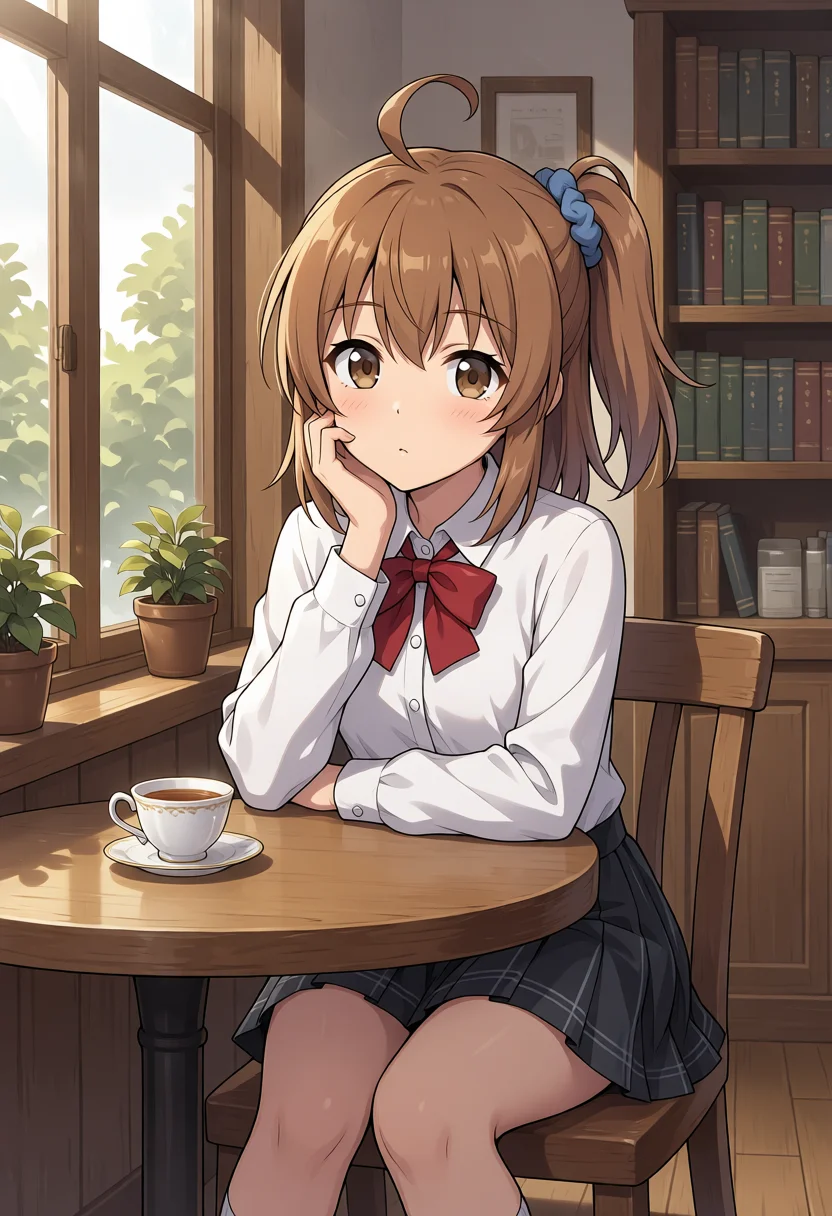
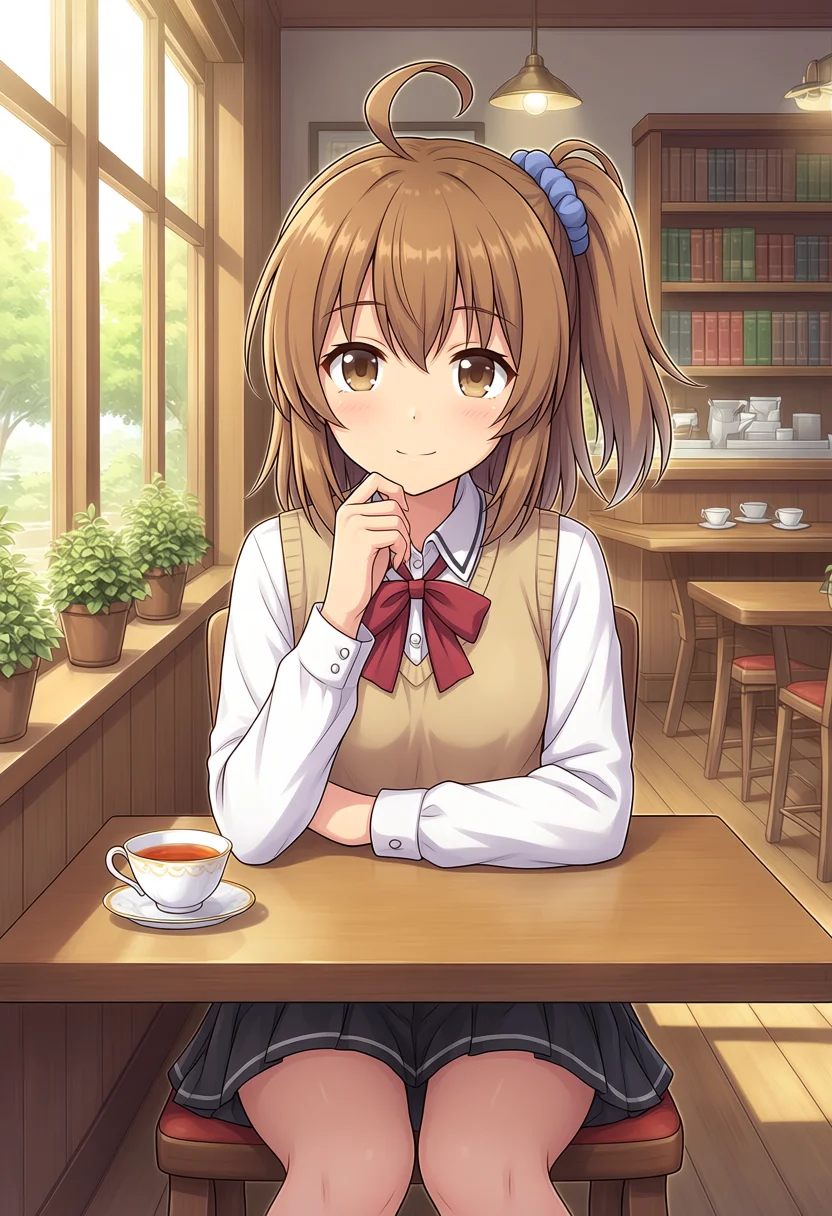
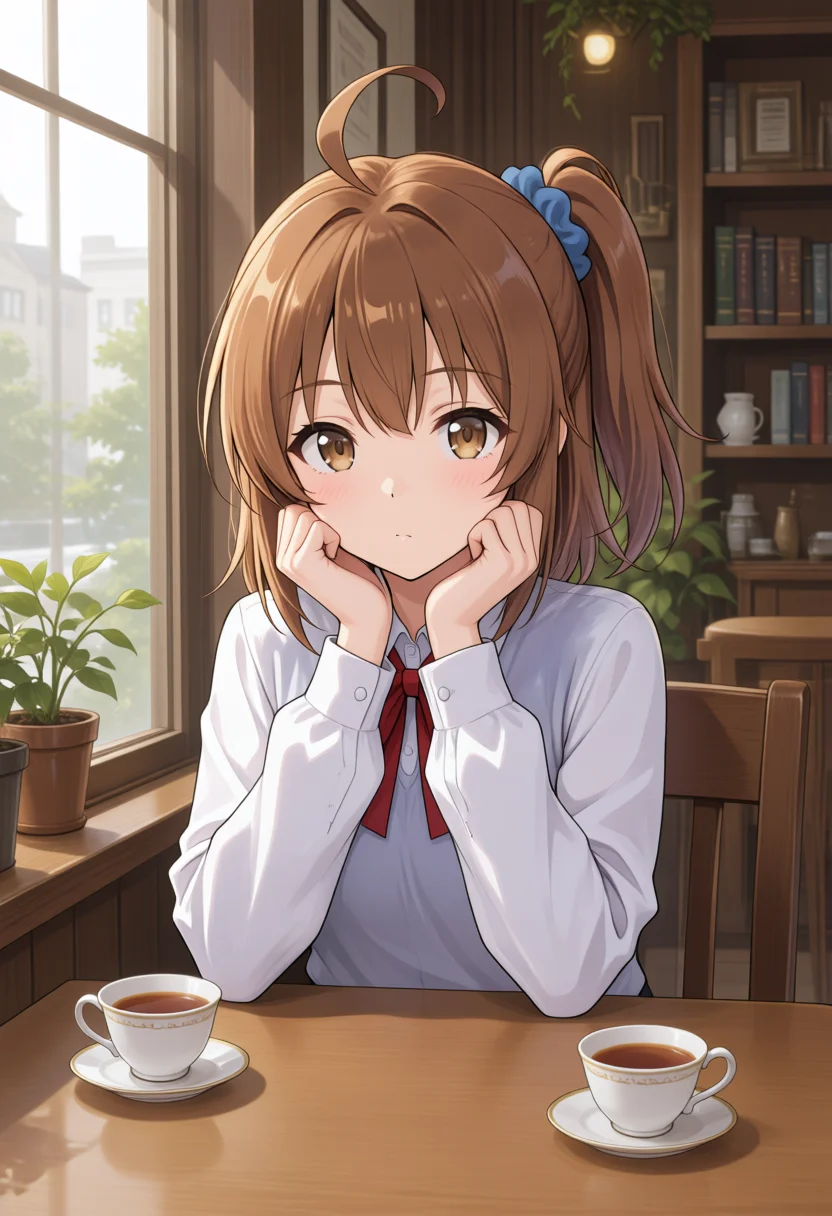
| Model | Observations |
|---|---|
| Base | Facing forward holding teacup with both hands. Two ceiling lamps, curtains, background chair |
| Turbo v1.1 | Resting chin on hand, round table with cup. Window, two potted plants, bookshelf |
| Anima-2.9B | Resting chin on hand, table with cup. Beige vest. Ceiling lamp, bookshelf, counter cups |
| TinAnima | Resting chin on both hands. Two cups on table. Outside building, potted plant, bookshelf, ceiling lamp |
TinAnima accurately rendered background elements including books on shelves and outdoor architecture.
Framing is closer than the others, showing from the tabletop upward.
Mirroring what appeared with 2.9B v2 in the One obsession article, an extra teacup appeared on the table.
Prompt
TinAnima:
safe, 1girl, solo, kanachan, brown hair, side ponytail, ahoge, brown eyes, school uniform, sitting at a cafe table by the window, potted plants, bookshelf, teacup, warm afternoon sunlight, detailed background, intricate details, looking at viewerBase / Turbo v1.1 / Anima-2.9B included masterpiece, best quality, at start.
Negative prompt:
worst quality, low quality, blurry, lowres, jpeg artifacts, bad hands, bad anatomy, deformed faceImage-to-Image (i2i)
As in my WAI-Anima article, I used a source image generated by WAI-Illustrious v160 with Kana-chan LoRA, running i2i at denoise 0.5 without any character LoRA.
Because TinAnima runs in 4 steps, denoise 0.5 executes only the final 2 denoising steps.
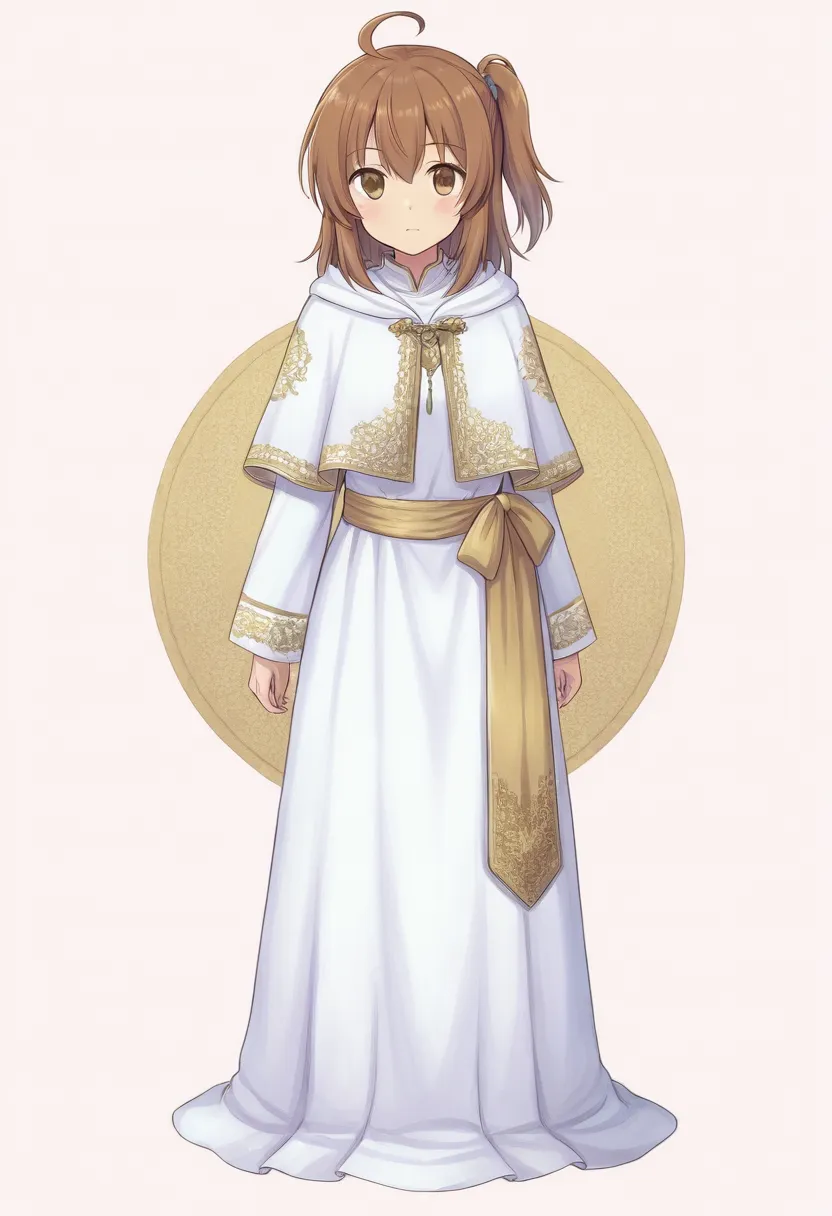
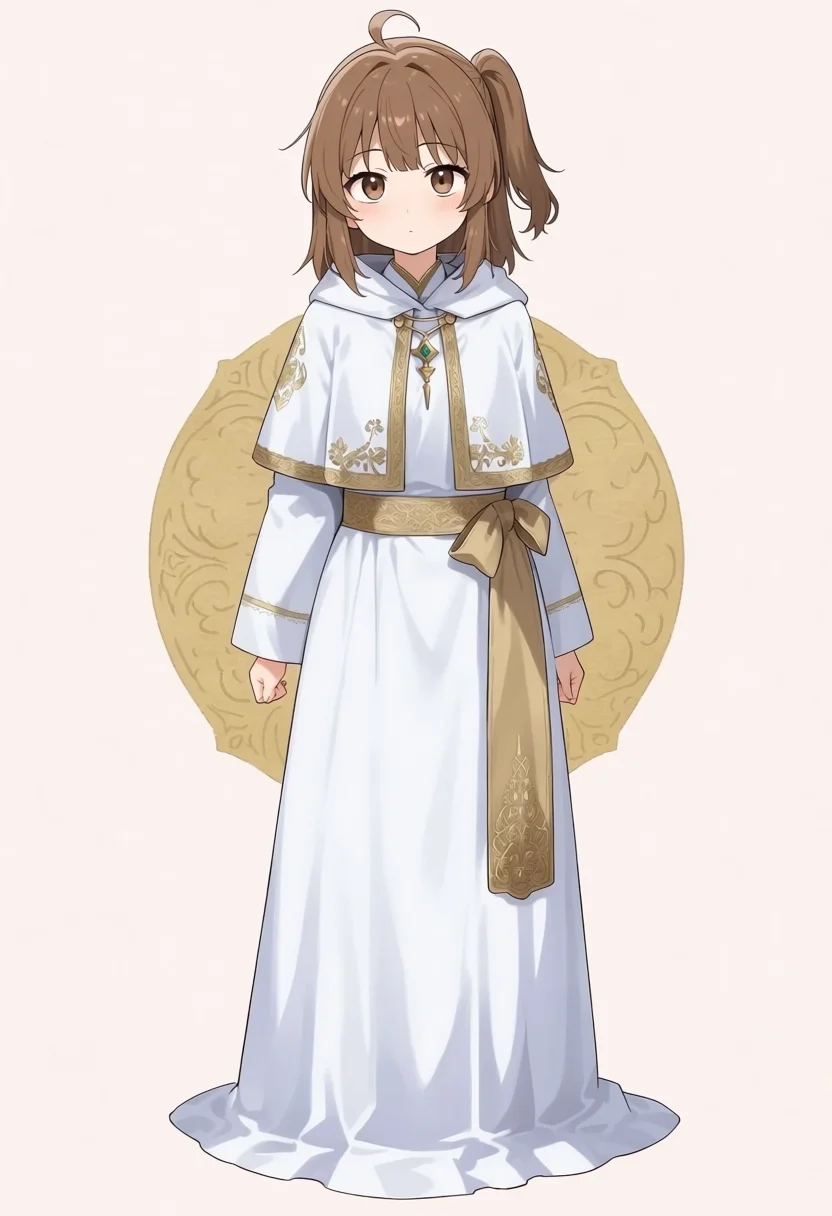
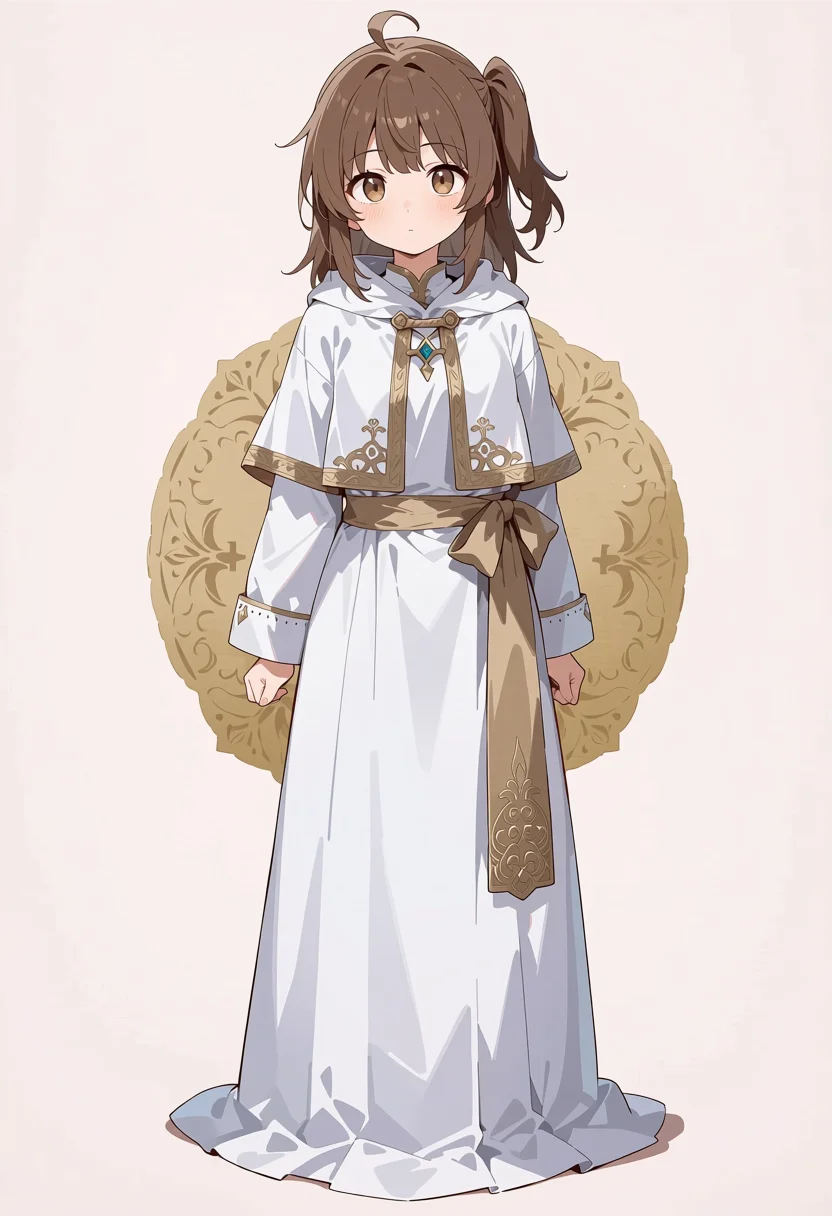
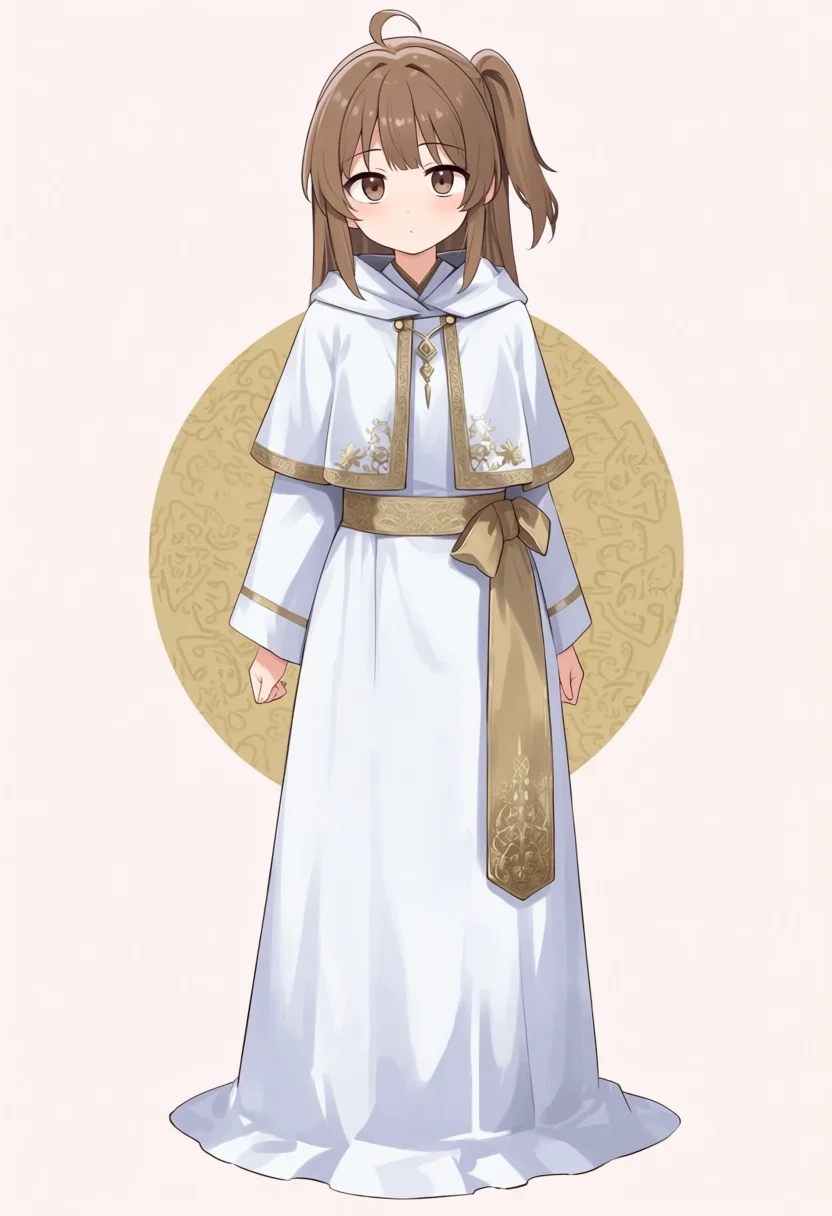
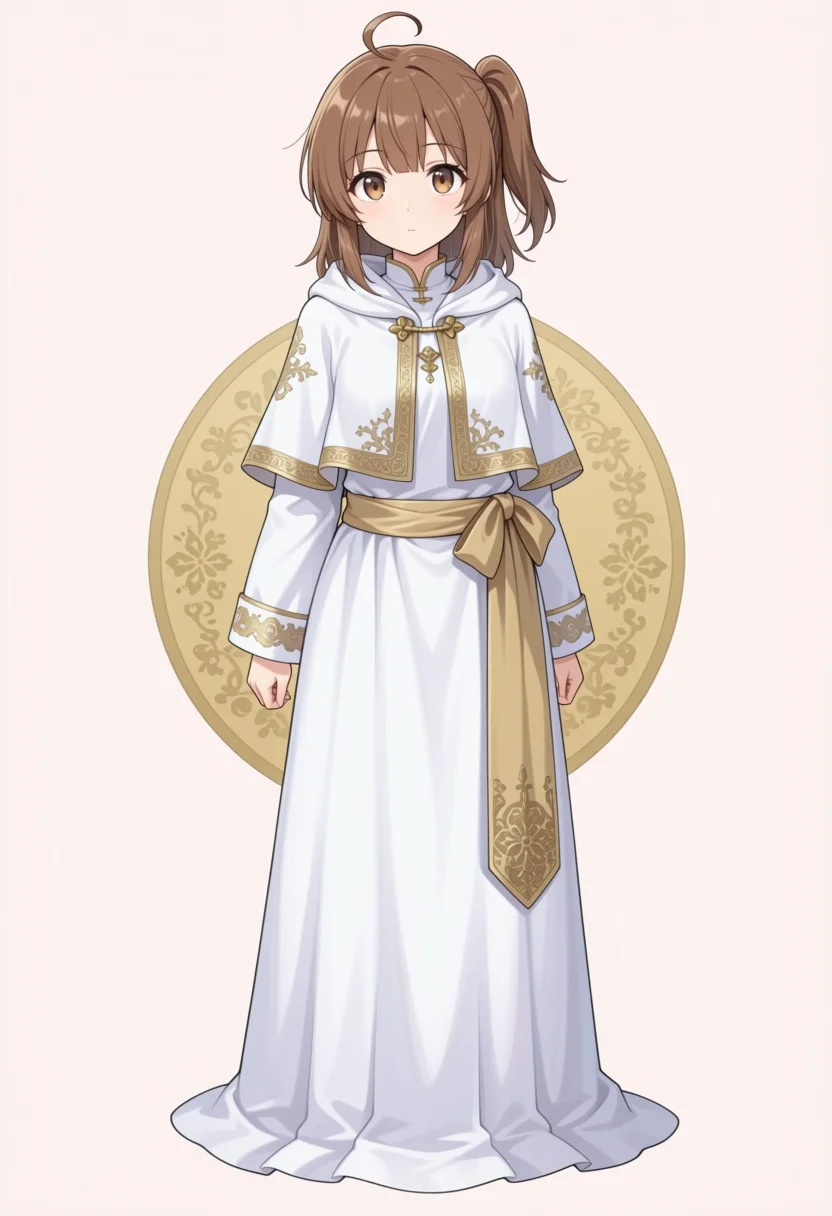
| Model | Observations |
|---|---|
| Base | Composition, gold halo, and sash knot maintained; patterned detailing inside halo |
| Turbo v1.1 | Composition maintained, white hood added. Patterned detailing inside halo breaks outline |
| Anima-2.9B | Composition maintained, white hood added |
| TinAnima | Composition, halo, and sash knot maintained; white hood added. Patterned detailing inside halo |
All four models preserved the overall composition, golden halo, and sash knot from the source image.
TinAnima rendered a slightly more mature gaze compared to Kana-chan’s rounder eyes in the source.
Prompt
TinAnima:
safe, 1girl, solo, brown hair, side ponytail, ahoge, brown eyes, white robe, gold embroidery, capelet, gold sash, long sleeves, long dress, standing, looking at viewer, full bodyBase / Turbo v1.1 / Anima-2.9B included masterpiece, best quality, at start. Negative prompt identical to white background test.
Generation Speed
Measured on an Apple Silicon M1 Max 64GB from job start to image return.
Base, Turbo v1.1, and Anima-2.9B reflect measurements from prior articles; Test 1 includes initial model load time.
Because TinAnima was evaluated directly after the LoRA strength tests, Test 1 does not include cold-load overhead.
TinAnima computed via the MPS patch dequantizing back to bf16 rather than native INT8 matrix multiplications.
| Model | Steps | Test 1 | Test 2 | Bust Portrait (832×1024) |
|---|---|---|---|---|
| Base | 30 | 262.8s | 258.7s | 210.7s |
| Turbo v1.1 | 8 | 40.2s | 38.2s | 30.2s |
| Anima-2.9B | 30 | 374.2s | 368.1s | 293.6s |
| TinAnima | 4 | 32.1s | 30.2s | 26.1s |
TinAnima generated images roughly 12 times faster in Test 2 compared to 30-step Anima-2.9B on the same 40-block architecture.
It is slightly faster than 8-step 2B Turbo v1.1.
At the author’s recommended 1024×1536 resolution, each image took approximately 50 seconds.
Recommendations by Use Case
| Use Case | Recommended Model | Observed Characteristics |
|---|---|---|
| Fast character LoRA inference on 2.9B | TinAnima | ~30s per 832×1216 image. Remapped LoRAs work without artifacts at strength 1.0, accurately capturing Kana and Kei traits |
| Diverse facial generation without character prompts | Anima-Base, Anima-2.9B | Hair colors and art styles varied across seeds 1–4 without prompt constraints. TinAnima produced the exact same face across all 12 test images |
| Full-body compositions with two characters | Base, Turbo v1.1, Anima-2.9B | TinAnima cropped from chest up despite explicit full body prompts |
| Fine control via negative prompts | Models other than TinAnima | Recommended CFG 1 skips negative prompt passes entirely. CFG 2 nearly doubles generation time with heavier saturation |
References
- TinAnima29B_v1_4steps_INT8 (Civitai)
- Anima (Hugging Face)
- Anima-2.9B (Hugging Face)
- NVIDIA Open Model License
- Testing One obsession Anima, 2.9B, and Illustrious with Identical Prompts and Seeds
- Can Existing Character LoRAs Run on 40-Layer Anima-2.9B via Layer Expansion?
- Testing Official Anima Turbo v1.1 and Aesthetic v1.1 on M1 Max: Can Base-Trained Character LoRAs Be Used?
- Tracking the Evolution of the Anima Ecosystem with WAI-Anima
Bonus: NSFW Output Test
Images beyond this point are blurred because outputs from this test may be sensitive. If you wish to see unblurred results, please test in your local environment.
Tested without character LoRA across two conditions: without nsfw tag and with nsfw tag (using straight-on framing). safe was removed from prompt prefixes.
Without nsfw Tag
With nsfw Tag (straight-on)
TinAnima rendered unclothed figures regardless of whether the nsfw tag was included.
Without the tag, the character sat on a rock dipping feet into water, mirroring other Anima models.
With the tag, the character stood before a white curtain.
Prompt
Without tag (TinAnima):
1girl, solo, long blonde hair, blue eyes, completely nude, naked, bare skin, sitting on edge of spring, feet in water, forest, natural light, serene, full body, looking at viewerWith tag (TinAnima):
1girl, solo, long blonde hair, blue eyes, completely nude, naked, bare skin, nsfw, straight-on, full body, standing, white backgroundBase, Turbo v1.1, and Anima-2.9B included masterpiece, best quality, at start. Negative prompt identical to white background test.