Tested on CoreS3 + StackChan Body: replaced 128x128 pixel art with 320x240 character art using Qwen-Image 2.1 diffs, layered in PSRAM for 5-emotion tap switching.
Tested on CoreS3 + StackChan Body: the 3-zone head pad works as a talk button, strokes need a 30–400 ms gap between zones, and servo motion leaves touch stuck until recalibrate().
ESP32-S3 CoreS3 joined Tailscale and fetched a WAV without the VPS relay. Tokyo DERP downloads took about 9 seconds after enrollment, stack, and TLS fixes.
Tested on M1 Max: Diffusers stretches an 832×1216 reference to 832×1248, making figures 2.7% narrower. Setting output_resolution=1006 cut whole-image drift to about 0.1px.
Tested on M1 Max 64GB: the training-free TaylorSeer cache in Diffusers made Qwen-Image 2.1 about 2.7x faster. It crashes with the default KV cache; a small patch fixes it.
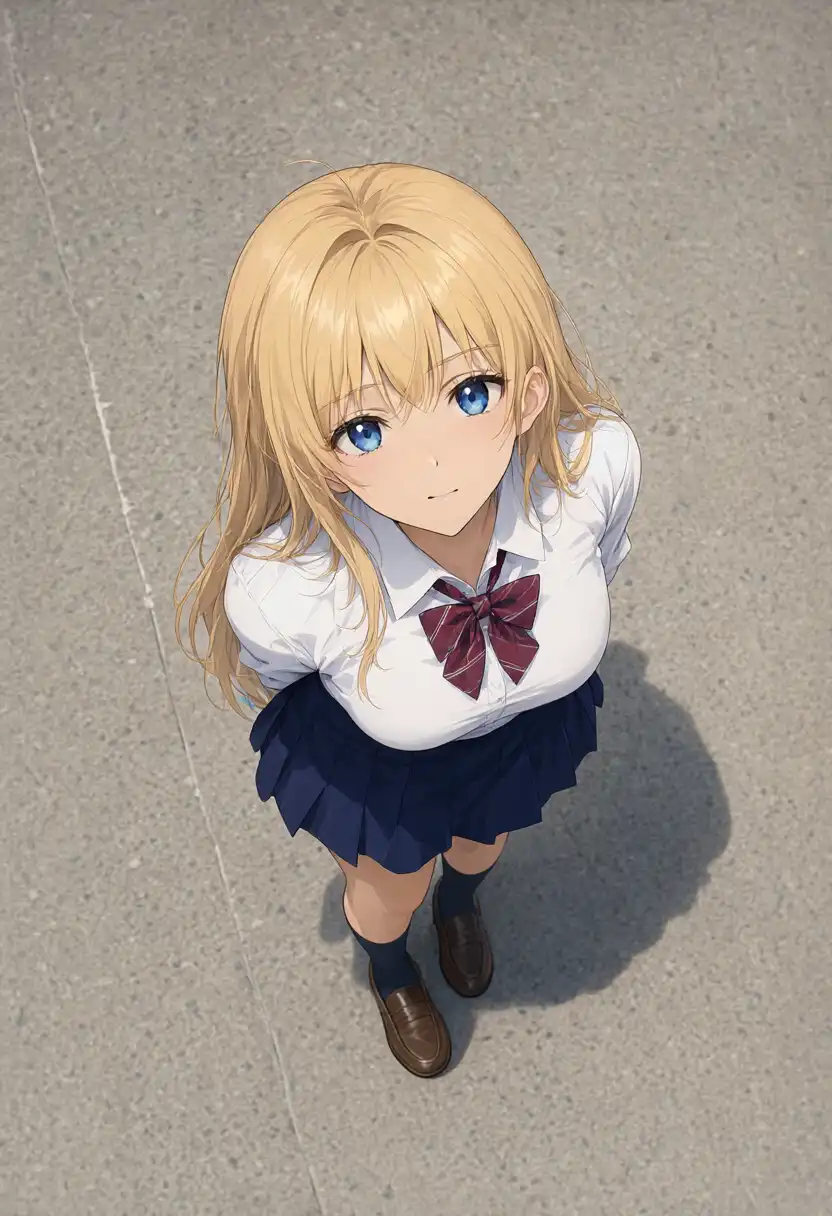
Tested Qwen-Image 2.1 open weights on M1 Max 64GB: overhead shots work locally, ~10 min per 832×1216 image (2x+ Anima), and i2i kept the face. Same prompts as my Anima/WAI tests.
A 100-yen junk ACS ACR1251U-M3 from Akihabara showed up in Windows 11 but refused to detect cards. Step-by-step troubleshooting from drivers and registry to firmware patching and updating a Santek EZ Sign.
Step-by-step physical assembly guide for transplanting an M5Stack CoreS3 into the official StackChan Body. Detaching DIN Base, 4-pin wiring, and initial boot test.
How do 6 open-source Jev clones compare under code inspection? We examine implementations using ModernBERT, Qwen, and diffusion models across state sharing, question isolation, and scoring trade-offs.
Claiming the $100 cloud credit from the AMD AI Developer Program involves a two-stage signup, a confusing DigitalOcean email loop, and non-obvious Credit balances. Here is the exact path through the UI.
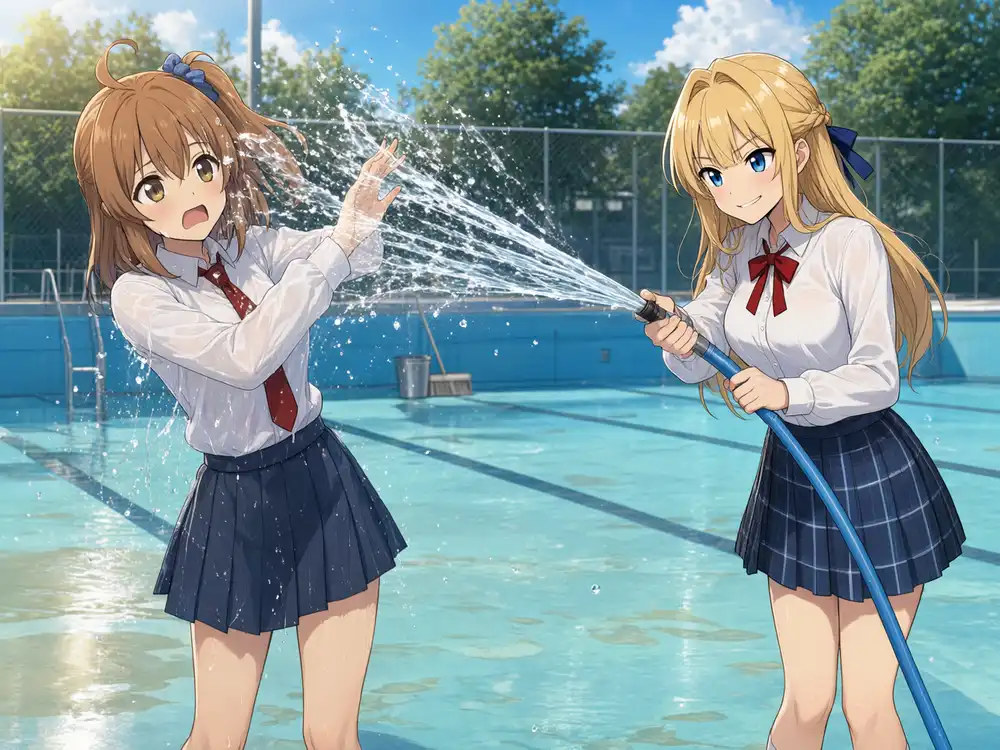
Hands-on evaluation of Qwen-Image 2.1 early access on ModelScope Studio. Testing 10 camera composition presets, 4-member band role assignments, I2I orientation and outfit changes, and where multi-character consistency breaks down.
Tested on an RTX 3050 Ti Laptop: Qwen3.8-Omni-Flash handles audio input directly, shrinking our voice chat server RSS from 1,327MB to 118MB with zero idle warmup lag.