Comparing Anima Ref Adapter v2 and Role-Ref-KV on M1 Max: v2 Ran 3x Faster Than Pilot on Turbo and Avoided 4koma Collapse
 Contents
On the day I published testing the Base-only Anima Ref Adapter on Turbo, Aesthetic, and 2.9B, Ref Adapter v2 was released.
Ref Adapter is an adapter for Anima designed to preserve character features from a single reference image while changing compositions. In the pilot version, running Turbo models with cfg 1.0 and ref_guidance 4.5 collapsed outputs into 4koma-style comic panels, and Base took 13 minutes per image.
v2 changed its architecture to process the reference image only once, and the README claims roughly twice the speed of pilot.
Around the same time, another adapter designed for single-image character consistency in Anima appeared: AnticPan’s Anima Role Ref KV, which also processes the reference image once and caches the result.
Additionally, ComfyUI-Anima-CharRef-LLLite was released to enable using Ref Adapter concurrently with toyxyz’s 3D pose ControlNet-LLLite.
CharRef-LLLite is built on the assumption of pairing with Ref Adapter.
If the workflow separates duties—using the reference adapter for character features and LLLite for posing—the reference side should conceptually work with either Ref Adapter or Role-Ref-KV.
I tested v2 and Role-Ref-KV under the same conditions as the previous benchmark, and checked whether CharRef-LLLite’s reference side could be replaced with Role-Ref-KV, running ComfyUI on a 64GB M1 Max MacBook Pro.
Overview of Each Node
| Item | Anima Ref Adapter v2 | Anima Role Ref KV v1.0 | ComfyUI-Anima-CharRef-LLLite |
|---|---|---|---|
| Author | ElectronGirl | AnticPan | quinteroac |
| Release | October 29, 2026 (v2 commit de90631) | October 27, 2026 (Initial Hugging Face release) | October 29, 2026 (Initial GitHub commit) |
| Contents | 1 node (Anima Ref Adapter), rank 64 LoRA (183,605,032 bytes) | 1 node (Anima Role Ref KV), rank 128 LoRA (528,546,184 bytes, fp32) | 3 nodes. No model weights |
| Training | 15,600 images, 2,300 characters, 1,952 styles. Anima Base v1.0 | Not specified in README. NSFW excluded from training data | — |
| License | Node: Apache-2.0, Weights: CircleStone Non-Commercial License | Derivative following CircleStone Non-Commercial License | Apache-2.0 |
| Source | GitHub, Hugging Face | Hugging Face | GitHub |
Both reference adapters pass the reference image through the VAE into latent representation, feeding it into the model as a separate sequence of tokens from the generated image.
The reference side is processed at a pristine, noise-free state (timestep 0). Attention key/values across all blocks are computed once and reused across every sampling step.
Because the pilot recalculated the reference image as a second frame on every step, this caching mechanism drives the substantial speed difference.
The differences lie in how reference tokens are handled and where the LoRA patches apply.
| Item | Ref Adapter v2 | Role-Ref-KV |
|---|---|---|
| Reference RoPE Position | Shifted outside the generated image grid | Aligned with generated image center in X/Y, separated along temporal coordinate |
| Reference Cross-Attention (Text) | Bypassed | Positive prompt is applied |
| LoRA Target Layers | self_attn, cross_attn, mlp (840 keys) | self_attn (q/k/v/out) and mlp (layer1/2) (504 keys). cross_attn excluded |
| Reference Image Size | Downscaled to ref_megapixels (default 1.0) | Downscaled to 768×768 equivalent or lower |
| Sampler | Standard ComfyUI samplers (KSampler, etc.) | Built into custom node (Euler, shift 3). Outputs LATENT |
| Reference Strength | Tuned via ref_guidance | No tuning argument exposed |
Role-Ref-KV’s node explicitly rejects patched models (such as models with LoRA or LLLite applied) and models with block counts other than 28.
The error messages are Use an unpatched Anima Base v1.0 MODEL and Expected Anima Base v1.0 (28 blocks), meaning neither Base + Turbo LoRA nor 2.9B runs out of the box.
Recommended settings from their respective READMEs:
| Item | Ref Adapter v2 | Role-Ref-KV |
|---|---|---|
| Base Model | Anima Base v1.0 (Turbo LoRA also supported) | Anima Base v1.0 |
| Sampler | er_sde or Euler, 30 steps, simple | 28 steps (built-in) |
cfg | 4.5 (1 for Turbo LoRA) | 4 |
| Reference Strength | ref_guidance 4.5, APG correction | — |
| Resolution | Unspecified (author examples use 832×1216) | ~1MP (1024×1024, 832×1216, 1216×832) |
| Prompting | Quality tags + 1girl + solo + scene tags. Avoid character name, artist, or clothing tags | Specify desired pose, clothing, and scene |
| Untested | Full Turbo / Aesthetic models untested by author | Other base models, quantization, and additional adapters untested |
In Ref Adapter v2’s README, the validated Turbo LoRA is listed as anima-turbo-lora-v0.2.
On October 29, the author of Role-Ref-KV released a demo on Hugging Face Space running Turbo v1.0 / v1.1 (8 steps, CFG 1) and Aesthetic variants, though the released model weights remain v1.0.
Test Environment
| Item | Specification |
|---|---|
| Machine | MacBook Pro M1 Max 64GB (MPS) |
| UI | ComfyUI v0.33.3 |
| Ref Adapter | Node commit fb587d2, weights anima_ref_adapter_v2_r64.safetensors |
| Role-Ref-KV | Hugging Face commit 259a0dc node and anima-role-ref-kv-v1.0.safetensors |
| CharRef-LLLite | Commit b3a8cb0. LLLite weights: toyxyz/Anima_ControlNet-LLLite anima_3dpose_6200.safetensors |
| Resolution | 896×1152 (same as previous benchmark). LLLite section tested at 768×1152 |
| Sampler | v2: euler / simple; Role-Ref-KV: built-in Euler |
| Seed | 20261027 (seeds 20261028 and 20261029 added in the seed comparison section) |
| Reference Images | Identical to previous benchmark: author sample ref_girl.jpg and Kana-chan full-body portrait |
| Previous Comparison Baseline | Ref Adapter pilot (anima_ref_adapter_pilot_r32), reusing images and recorded times from previous post without regeneration |
For Ref Adapter’s APG correction, I changed two .double() calls that crash on Apple Silicon MPS to .float(), exactly as in the previous test.
Even with identical seeds, v2 generates initial noise using ComfyUI’s random generator while Role-Ref-KV uses its own internal generator, so the initial noise does not match between the two adapters.
Tested against the same 8 model conditions as last time:
| Label | Model | v2 Steps / cfg / ref_guidance | Role-Ref-KV Steps / cfg | Role-Ref-KV Node Type |
|---|---|---|---|---|
| Base | anima-base-v1.0 | 30 / 4.5 / 4.5 | 28 / 4 | Official |
| Aesthetic v1.1 | anima-aesthetic-v1.1 | 30 / 4.5 / 4.5 | 28 / 4 | Official |
| 2.9B (Remapped) | Anima-2.9B-preview-v1 | 30 / 4.5 / 4.5 | 28 / 4 | Patched alias node without checks |
| 2.9B (Raw) | Anima-2.9B-preview-v1 | 30 / 4.5 / 4.5 | — | — |
| Turbo v1.1 | anima-turbo-v1.1 | 8 / 1.0 / 1.0 | 8 / 1 | Official |
| Turbo v1.0 | anima-turbo-v1.0 | 8 / 1.0 / 1.0 | 8 / 1 | Official |
| Base + Turbo LoRA | anima-base-v1.0 + anima-turbo-lora-v0.1 (1.0) | 8 / 1.0 / 1.0 | 8 / 1 | Patched alias node without checks |
| 2.9B Unofficial Turbo | anima29b-p1-turbo1.1 | 8 / 1.0 / 1.0 | 8 / 1 | Patched alias node without checks |
For v2 on Turbo models, I adopted ref_guidance 1.0 as the baseline, which previously prevented 4koma collapse on the pilot.
Because Turbo v1.0 and v1.1 are full standalone models, they pass the official Role-Ref-KV node checks.
For Role-Ref-KV’s 3 unsupported setups, I created an alias node solely to bypass the rejection assertions.
The underlying model logic was untouched.
For Base + Turbo LoRA, the Turbo LoRA loaded via ComfyUI’s standard LoRA loader is applied to the model weights before Role-Ref-KV’s internal forward pass executes, allowing it to take effect directly.
For 2.9B, I remapped v2’s LoRA keys to target 40 blocks using the same script as last time.
Since Role-Ref-KV requires LoRA keys for every block, I remapped the existing weights and padded the 12 inserted layers with zeroed LoRA weights.
Running with Official Recommended Settings
First, I tested Anima Base using the author’s sample reference image and prompt from the v2 repository.
Role-Ref-KV used the same reference image, configured at its recommended 28 steps and cfg 4.
| Adapter | Time | Result |
|---|---|---|
| v2 | 479.9s | Blonde hair with red streaks, black and white outfit. Sitting on a red sofa, bringing a fork to her mouth. Near-identical composition to pilot (785.8s) |
| Role-Ref-KV | 299.3s | Same character eating cake on a red sofa |
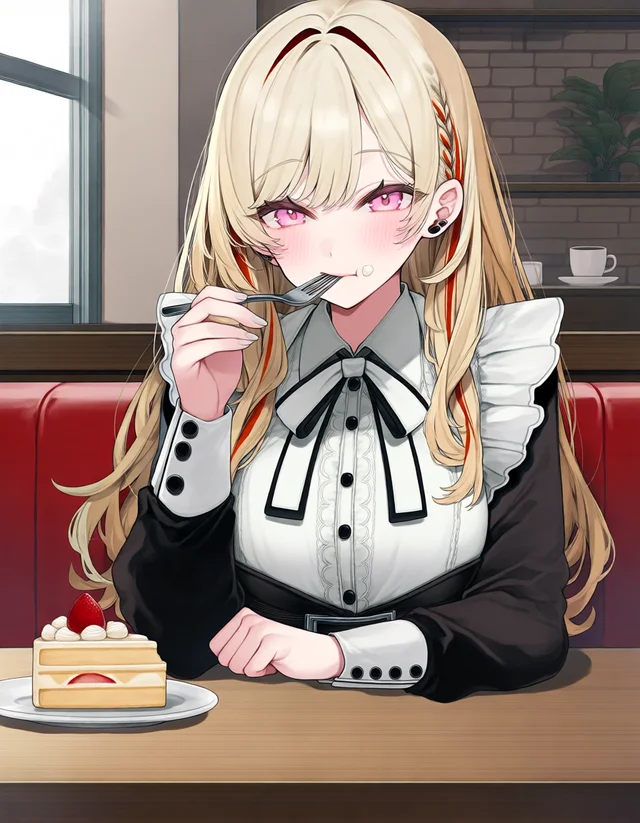
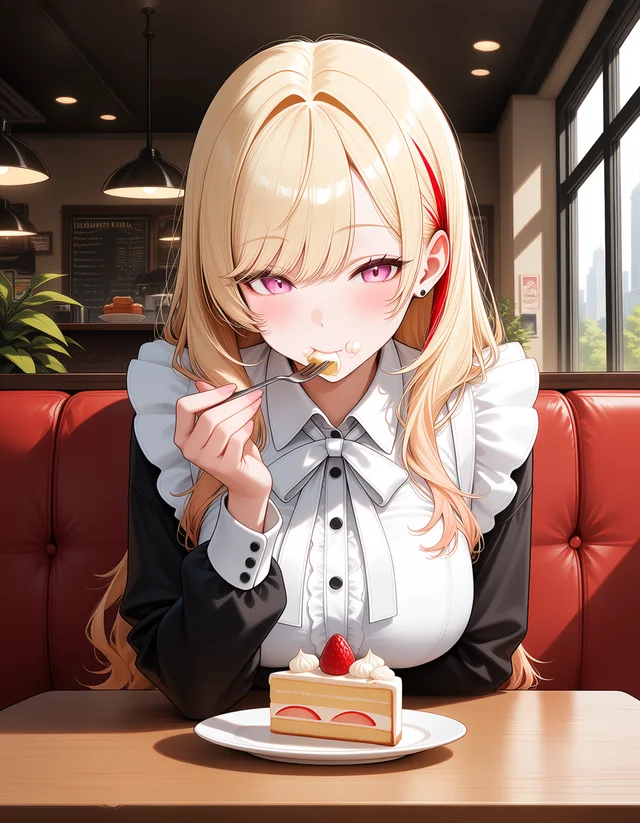
Both adapters preserved hair color, red streaks, and outfit from the reference image, faithfully rendering the scene requested in the prompt.
On the same Base model, v2 took roughly 8 minutes while Role-Ref-KV finished in around 5 minutes.
Prompt
masterpiece, best quality, score_7, newest, highres, absurdres, safe, 1girl, solo, upper body, sitting, eating, cake, cafe, indoorsNegative prompt (shared across all setups):
worst quality, low quality, score_1, score_2, score_3, blurry, jpeg artifacts, chromatic aberration, bad anatomy, bad hands, extra arms, extra fingers, missing fingers, text, watermark, signature, artist name, multiple views, split screen, comic, 2koma, 4komaTesting Base, Aesthetic v1.1, and 2.9B with Recommended Settings
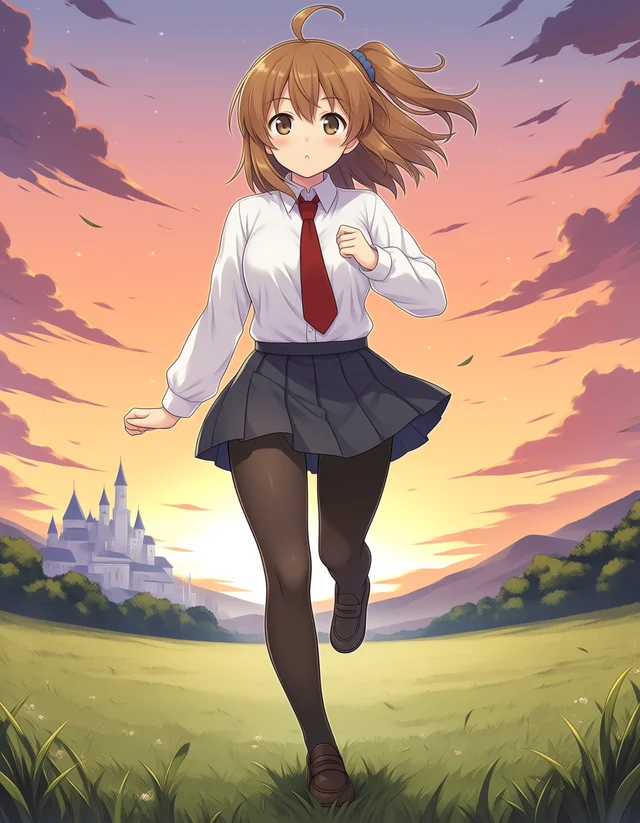
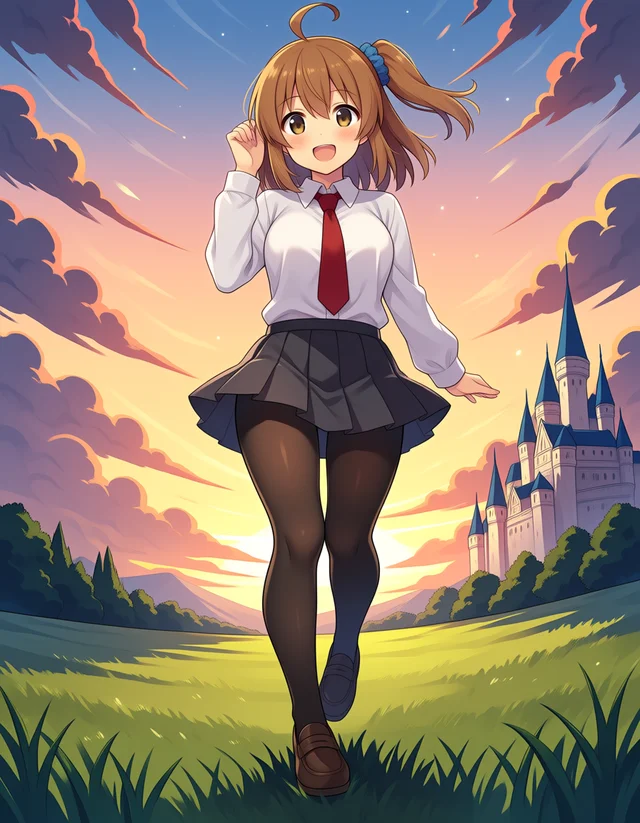
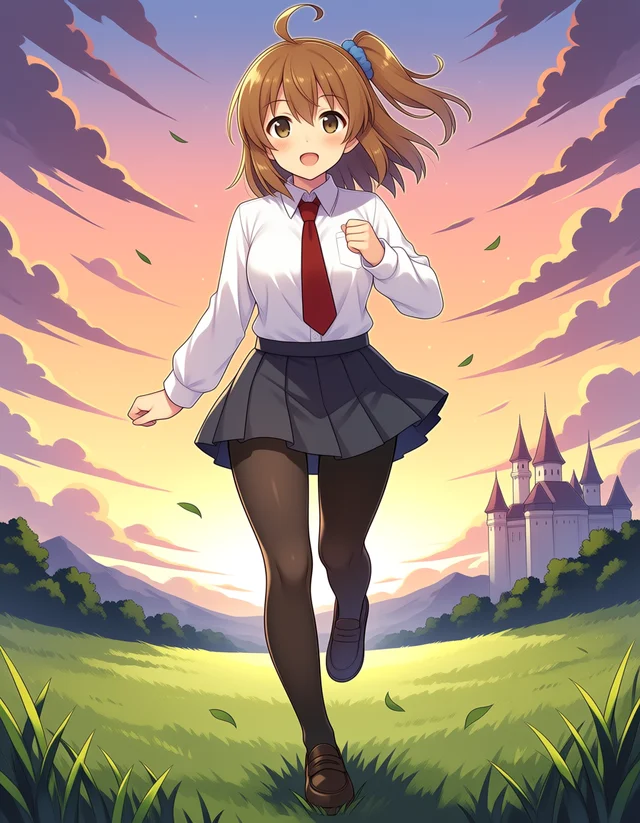
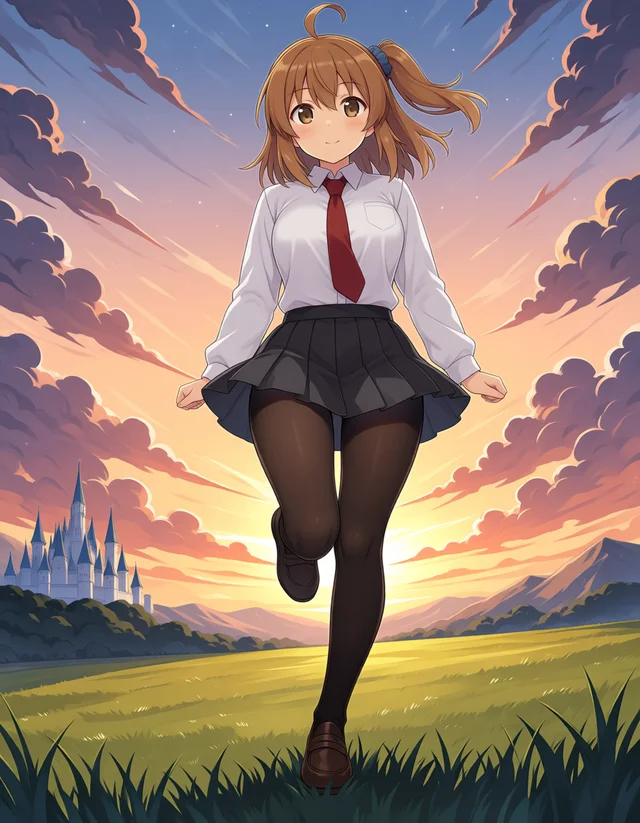
Switching the reference image to the Kana-chan full-body illustration, I generated running and cake scenes.
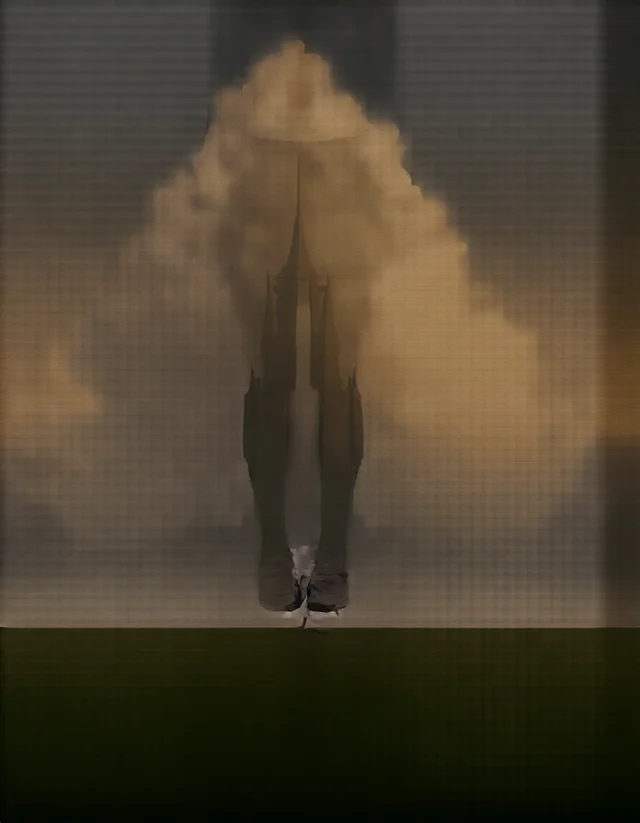
| Setup | v2 Running | Role-Ref-KV Running | v2 Cake | Role-Ref-KV Cake |
|---|---|---|---|---|
| Base | Full-body facing forward running, filling frame. Two white castles and grassy plain | Facing mostly forward running, character smaller, massive cumulonimbus cloud and hilltop castle | Sitting on red sofa with fork. Matches reference | Same scene. Hair shifts toward vivid orange |
| Aesthetic v1.1 | Near-identical composition to Base | Near-identical composition to Base | Near-identical composition to Base | Indoor cafe lighting. Hair is orange-tinted brown |
| 2.9B (Remapped) | Near-identical composition to Base. Floating leaves | Cumulonimbus cloud and castle, running forward | Near-identical composition to Base | Near-identical composition to Base, hair is vivid orange |
| 2.9B (Raw) | Collapsed. Brown smoke-like blob and grid noise | — | Collapsed. Dark translucent silhouette and grid noise | — |
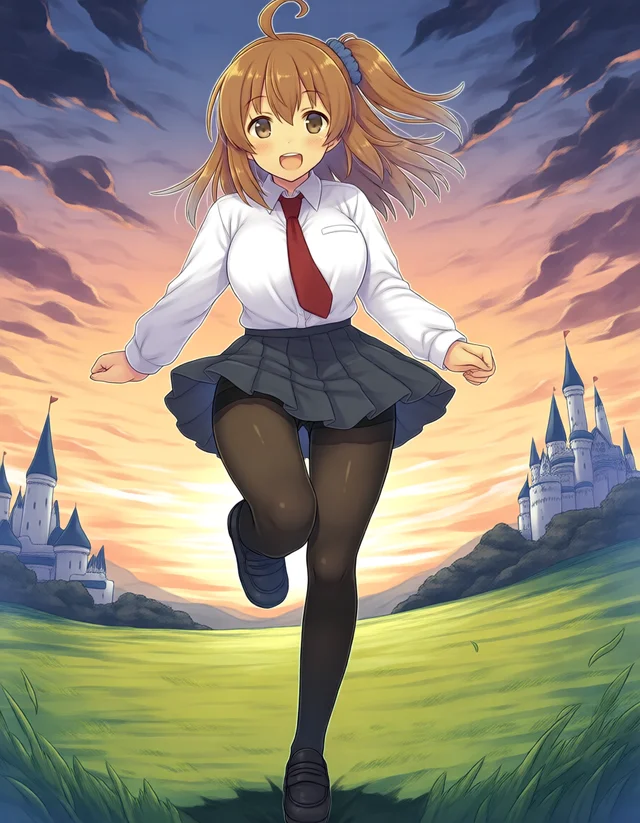
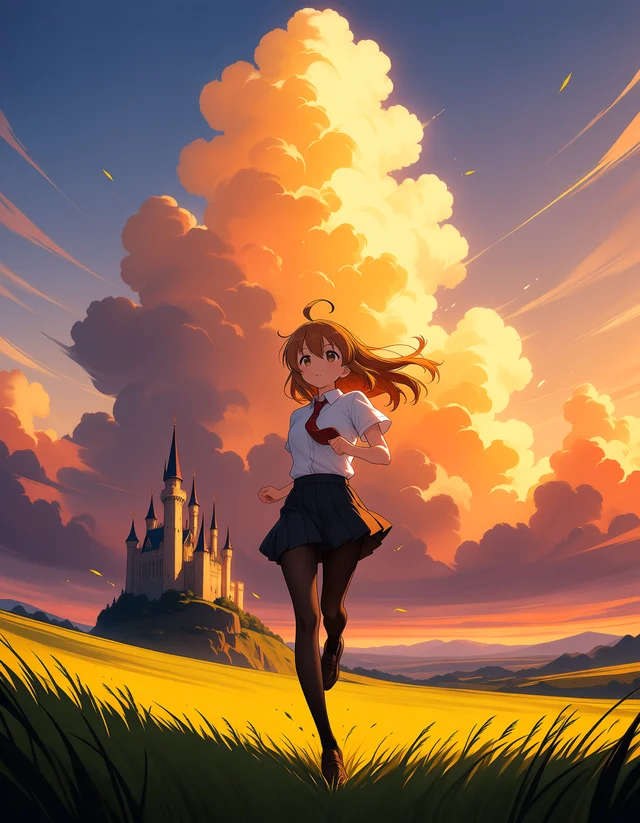
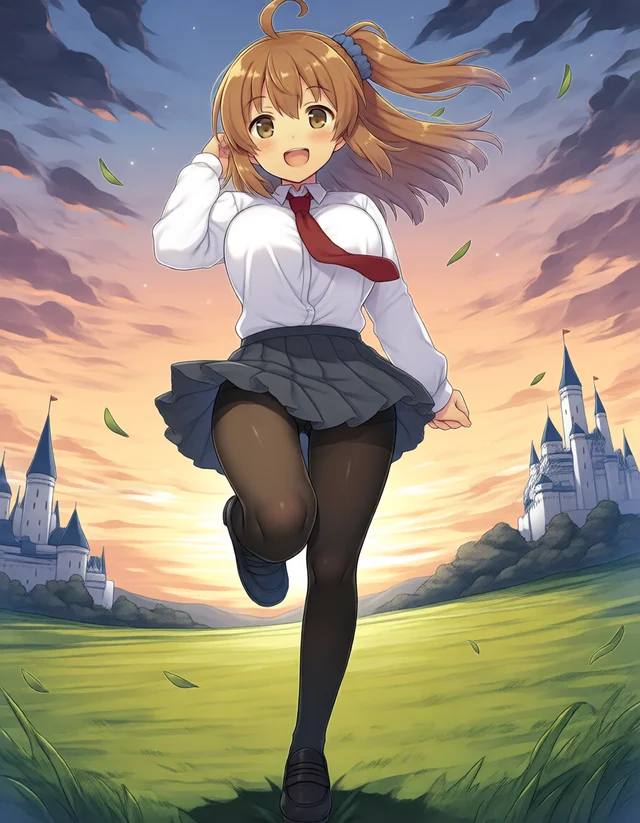
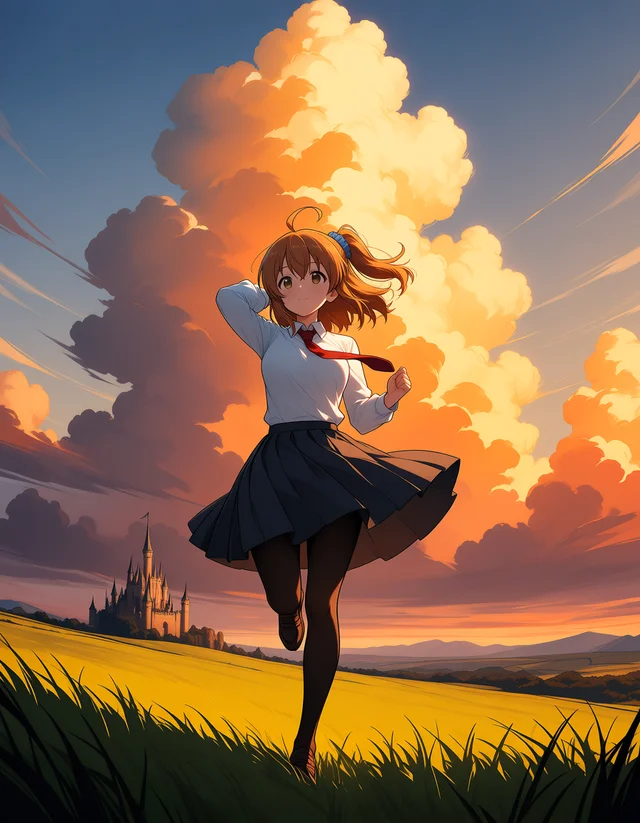
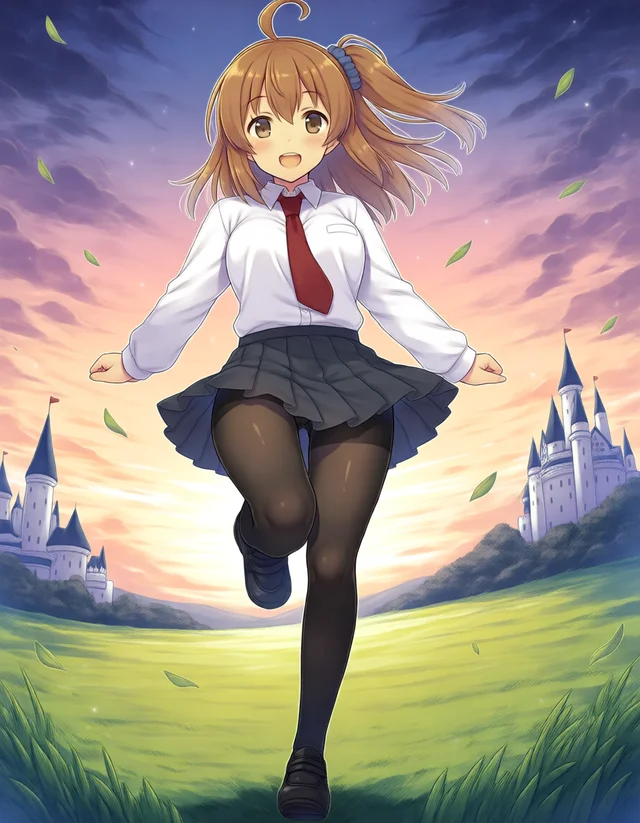
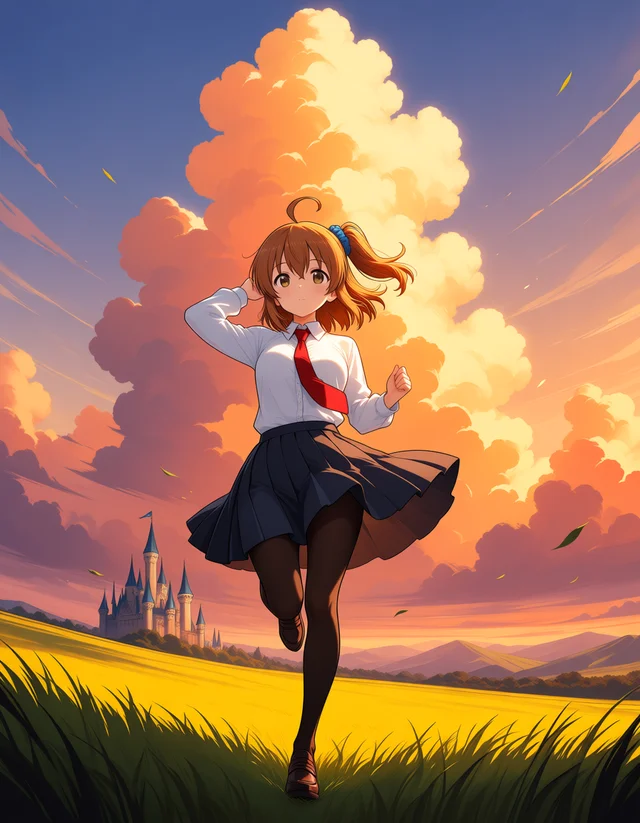
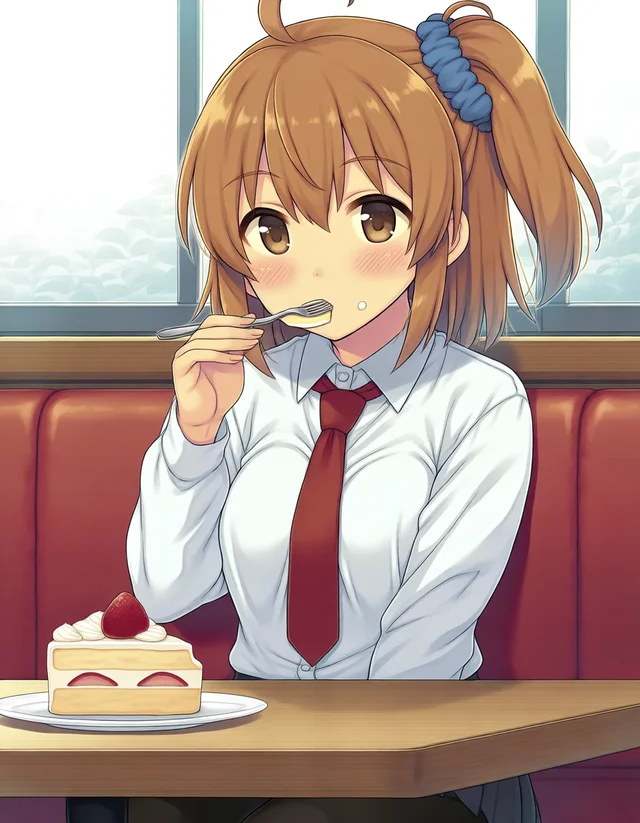
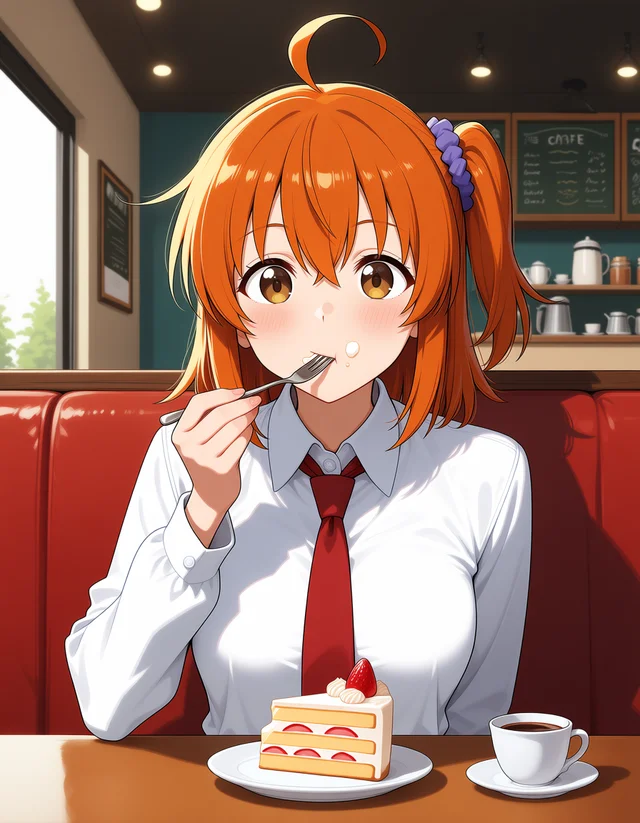
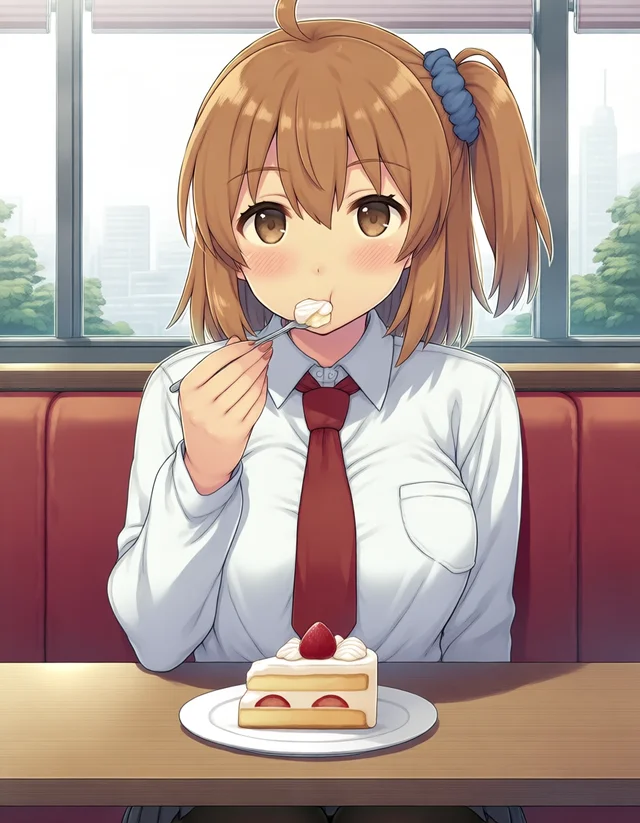
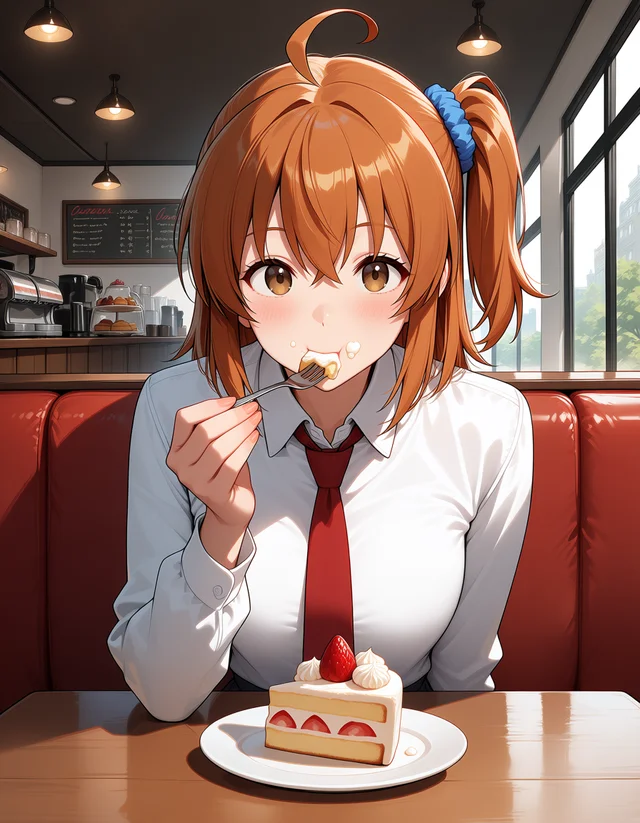
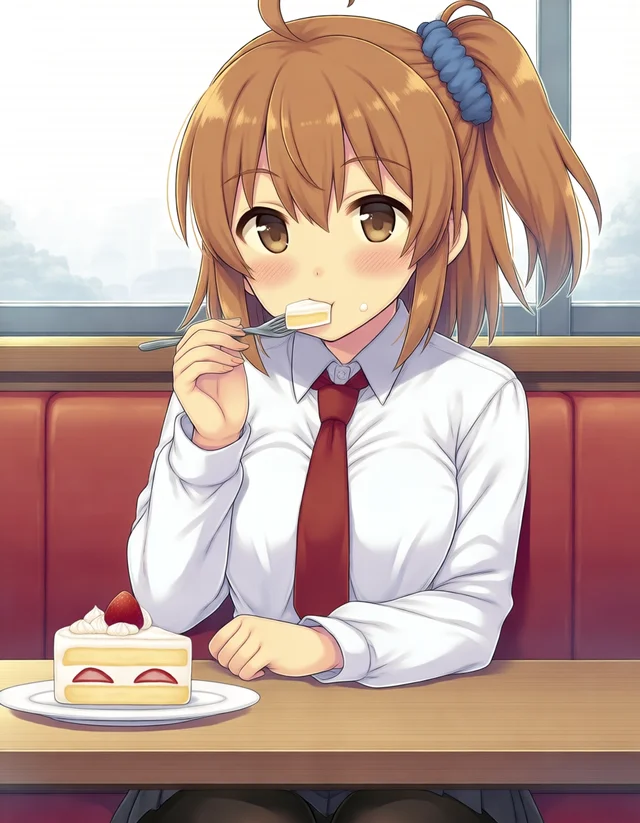
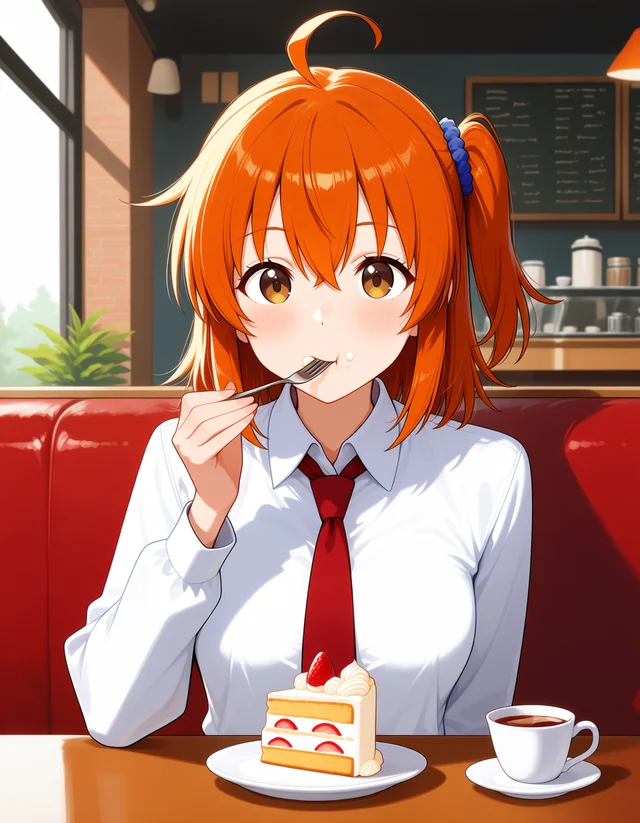
Both adapters retained key reference details: the ahoge, side ponytail with a blue scrunchie on the image-right side, white collared shirt, red necktie, black tights, and loafers.
On this seed with Base, the pilot version ended up drawing her from behind; here, both adapters successfully generated her running forward.
v2 framed the character large and front-center, whereas Role-Ref-KV framed her smaller, leaving more space for expansive backgrounds.
Role-Ref-KV showed a distinct tendency in the cake scene: across Base, Aesthetic, and 2.9B, her light brown hair shifted toward bright orange.
In the running scene with the exact same Role-Ref-KV setup, her hair remained light brown, indicating this drift varies depending on scene context.
v2 maintained consistent light brown hair across all tested setups.
2.9B ran successfully on both v2 and Role-Ref-KV once block keys were remapped.
Applying v2 without remapping failed completely, mirroring the pilot’s behavior.
Prompt
Running scene:
masterpiece, best quality, score_7, newest, highres, absurdres, safe, 1girl, solo, full body, running, wind, hair blowing, dynamic pose, fantasy landscape, castle in background, sunset sky, dramatic clouds, grass fieldCake scene:
masterpiece, best quality, score_7, newest, highres, absurdres, safe, 1girl, solo, upper body, sitting, eating, cake, cafe, indoorsResults on Turbo Variants
All 4 Turbo conditions were tested at 8 steps with cfg 1.0; v2 was set to ref_guidance 1.0.
| Setup | v2 Running | Role-Ref-KV Running | v2 Cake | Role-Ref-KV Cake |
|---|---|---|---|---|
| Turbo v1.1 | Running forward, castle and dusk sky. Matches reference | Running forward, right hand to head. Matches reference | Red sofa seat by window. Matches reference | Matches reference. Hair slightly reddish |
| Turbo v1.0 | Near-identical composition to Turbo v1.1 | Castle on hill, running forward | Left hand to cheek. Matches reference | Matches reference. Hair slightly reddish |
| Base + Turbo LoRA | Matches reference | Right hand raised in fist. Matches reference | Matches reference | Hair orange, mouth wide open |
| 2.9B Unofficial Turbo | Matches reference | Matches reference | Matches reference | Matches reference. Hair slightly reddish |
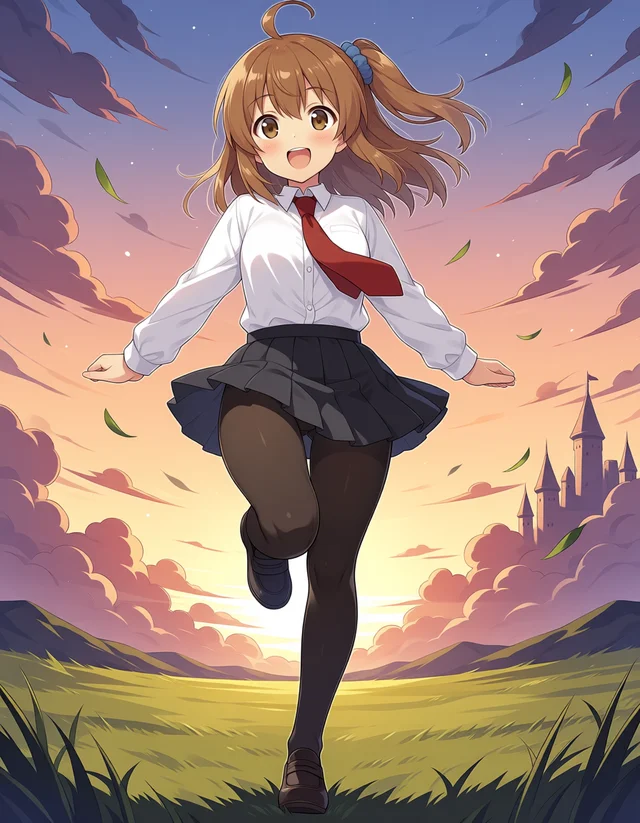
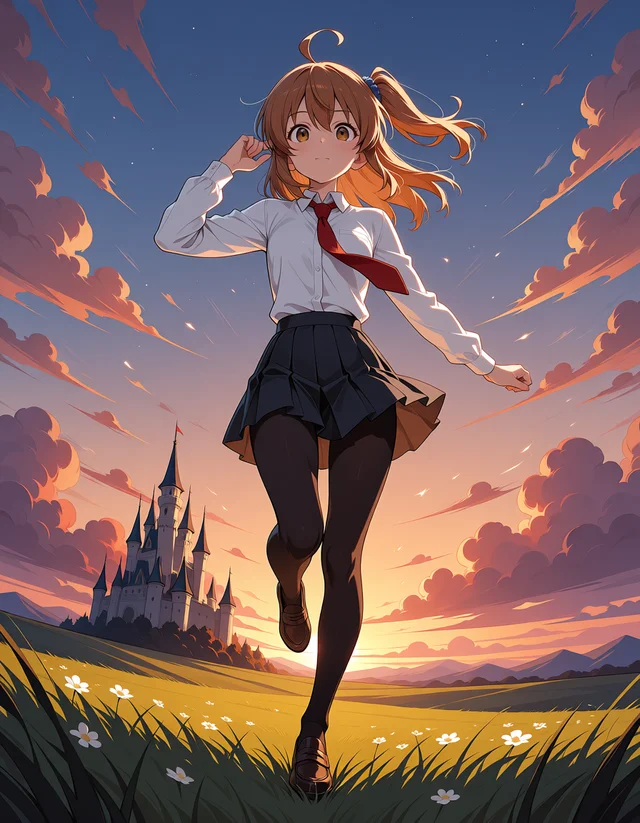
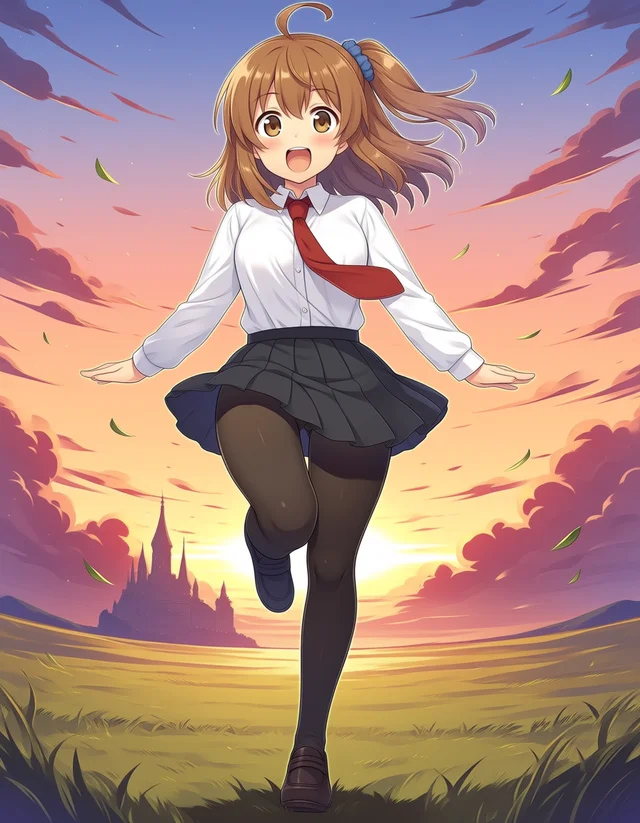
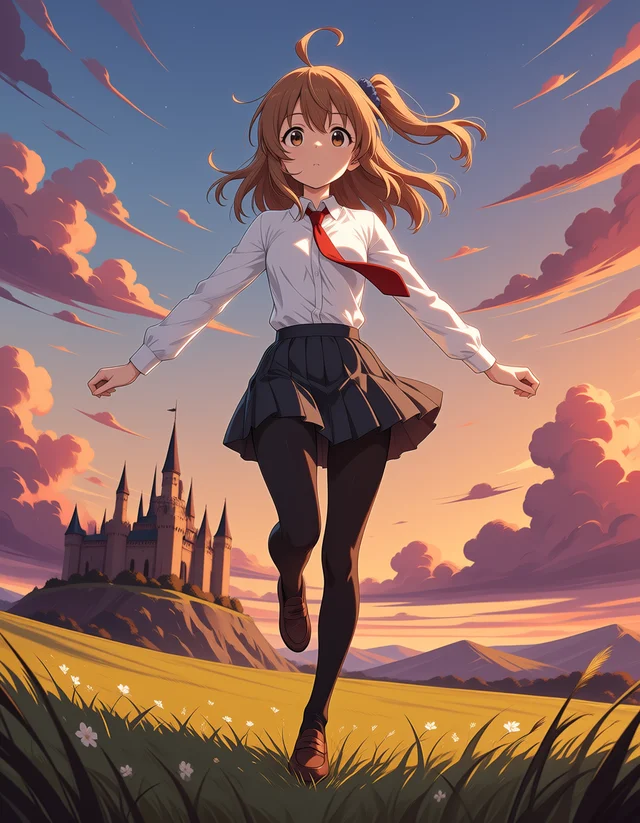
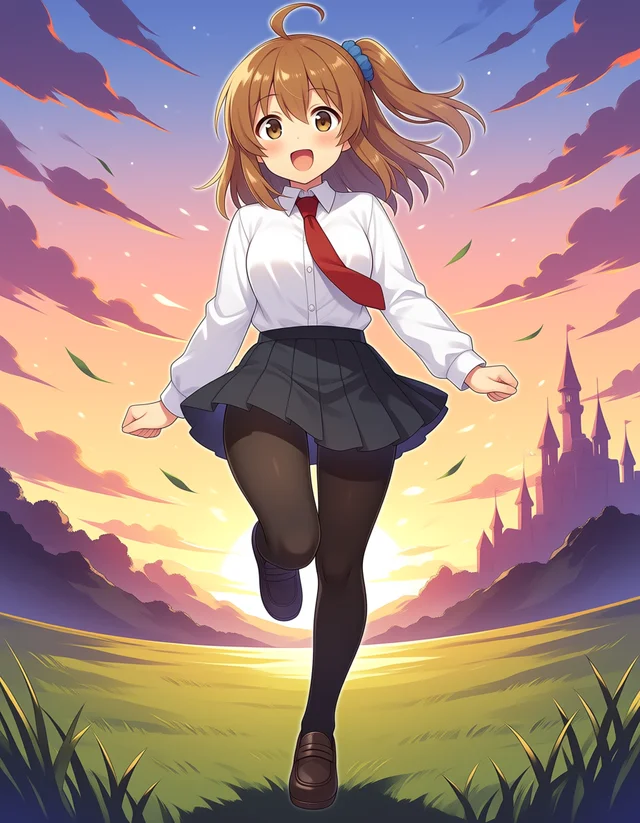
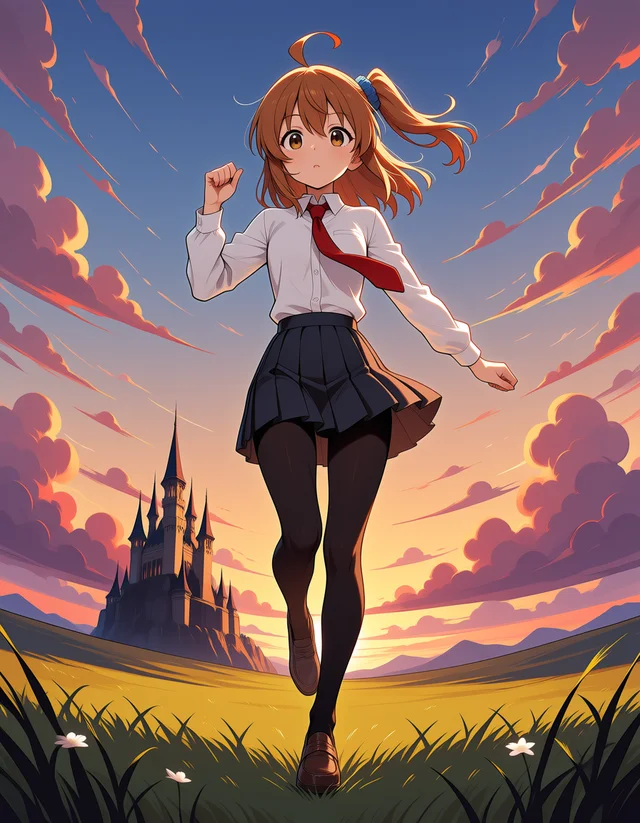
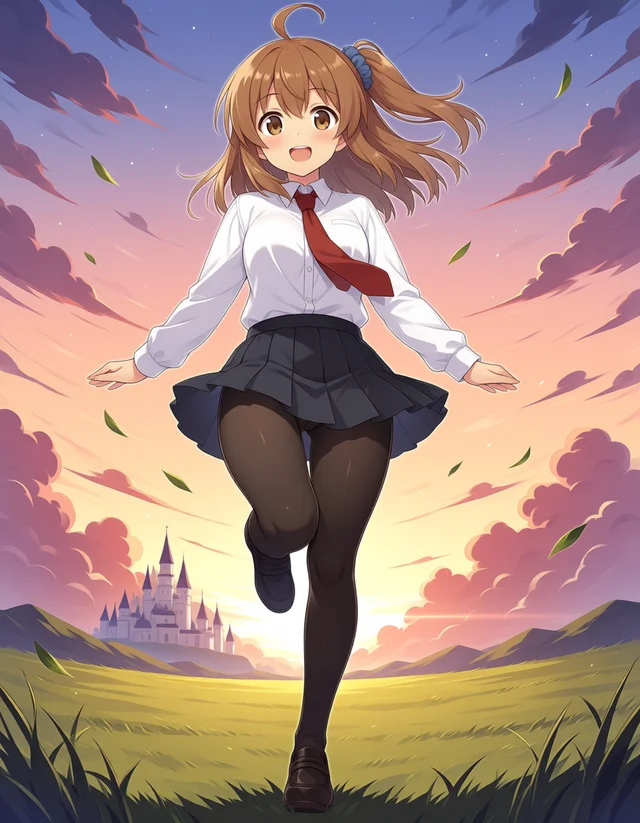
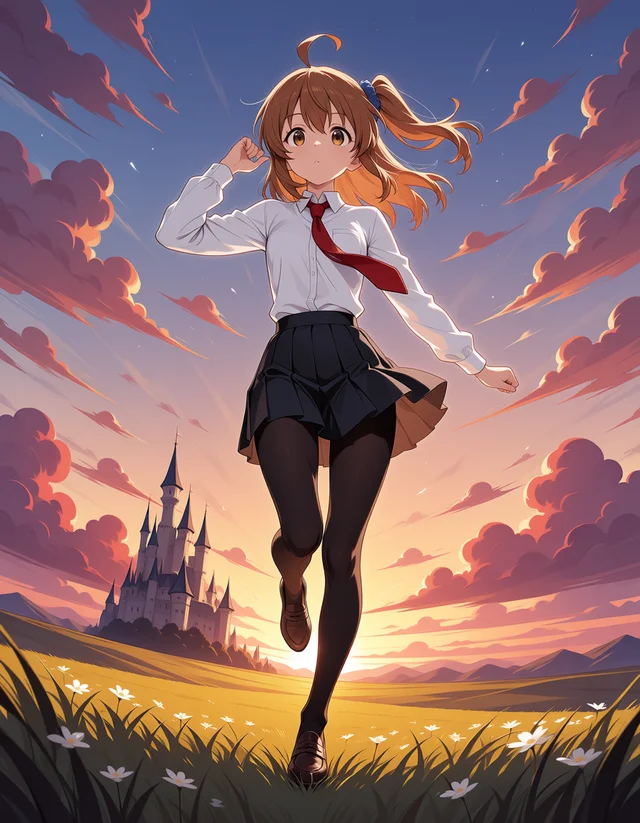
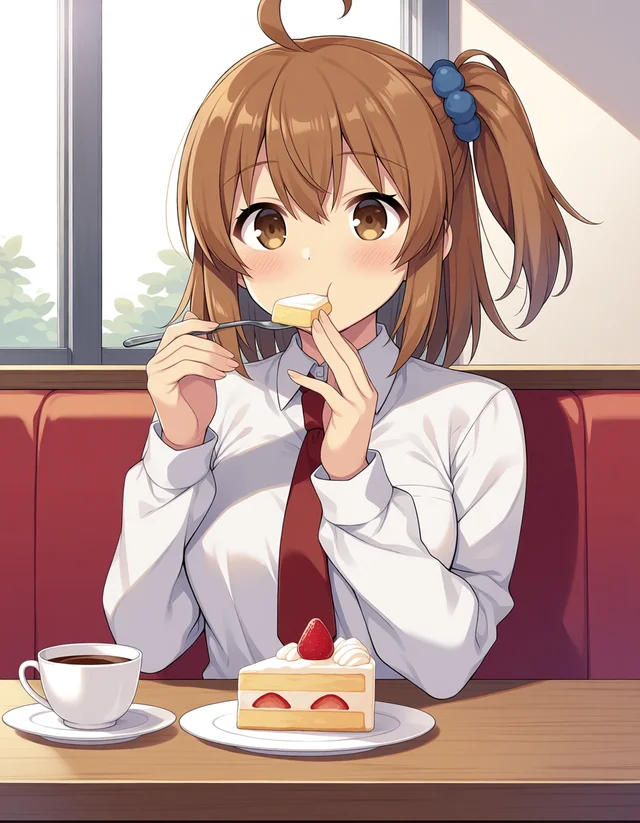
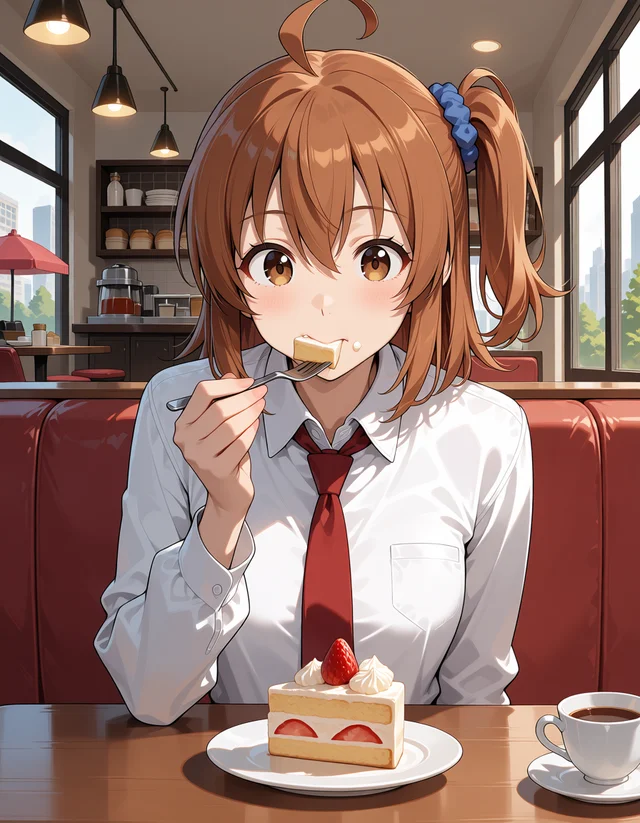
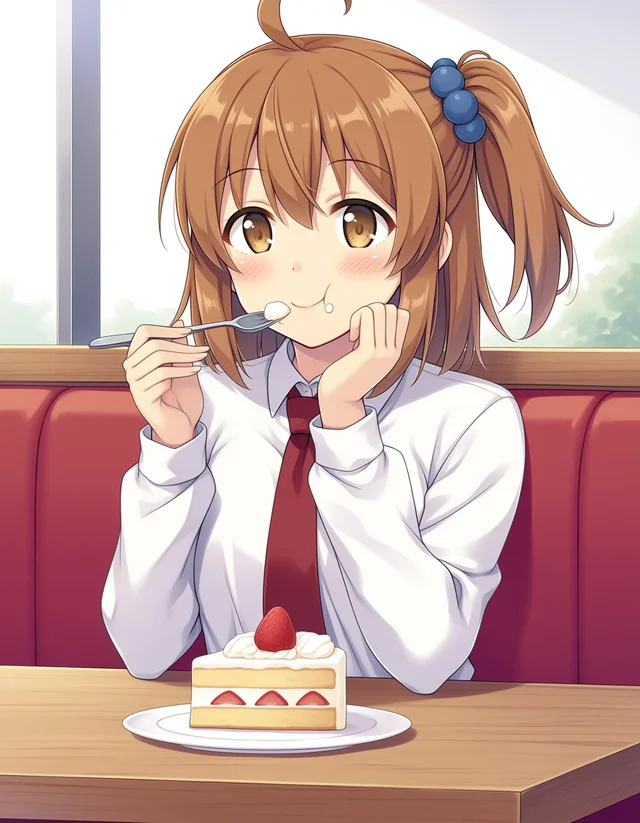
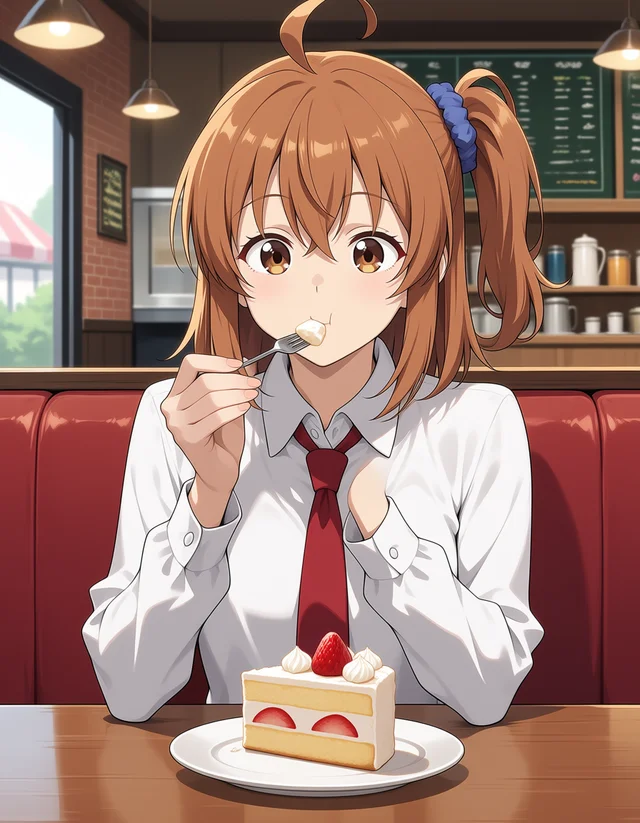
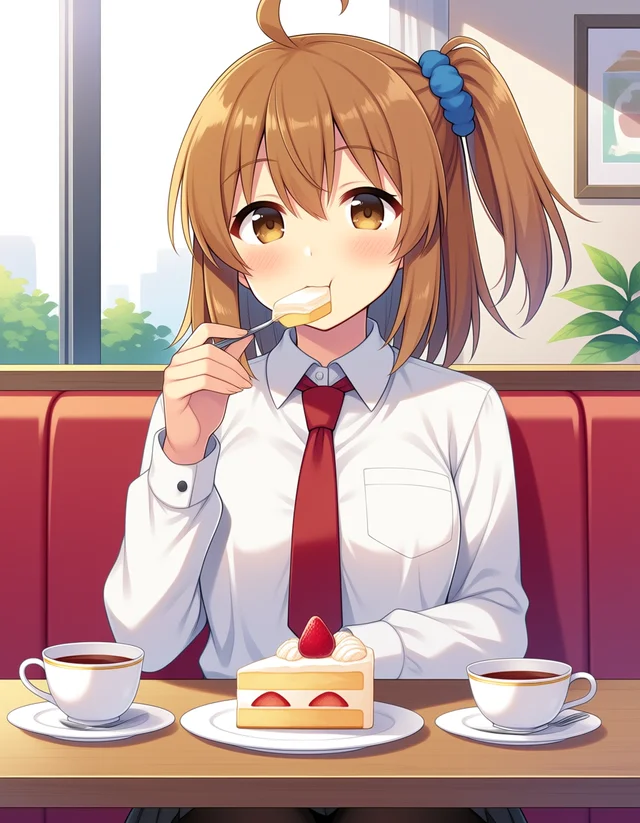
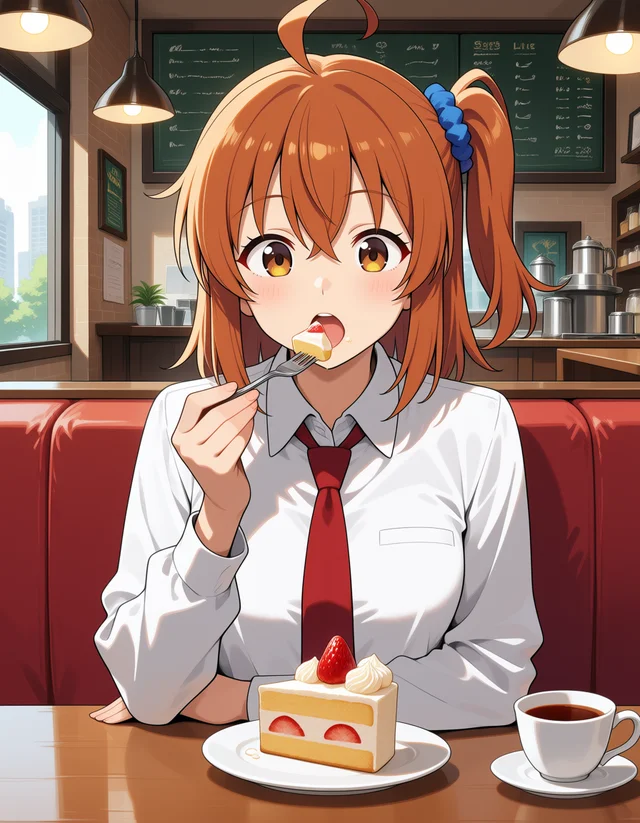
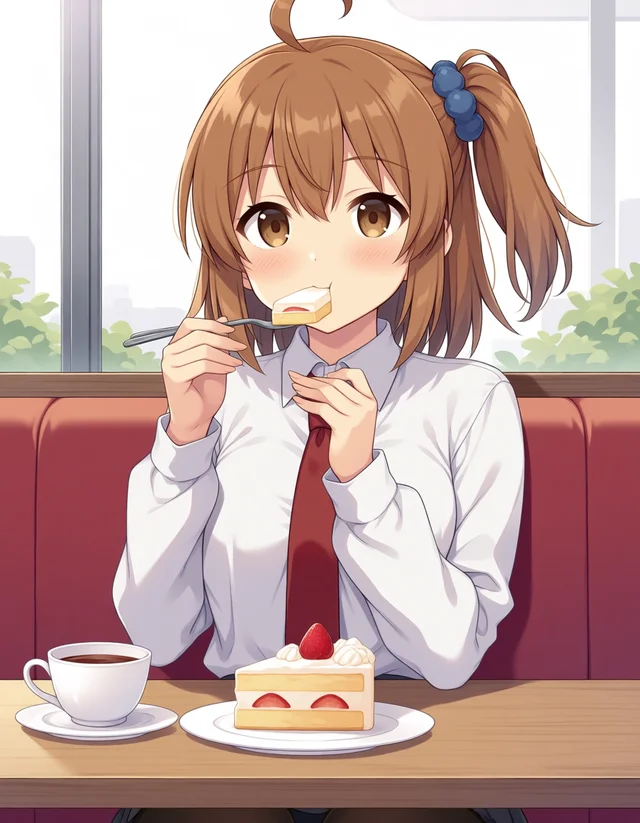
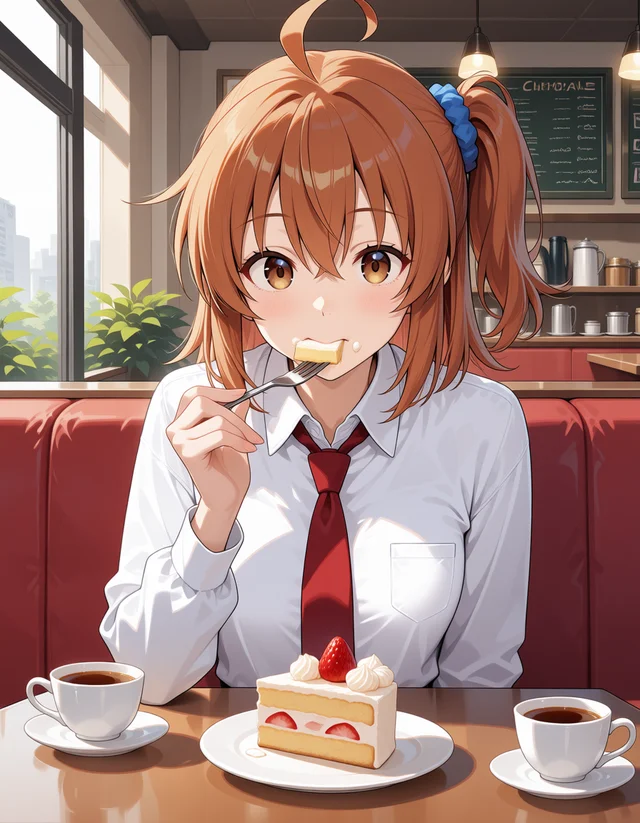
Across all 4 Turbo setups, both adapters produced proper running and cake scenes as instructed.
In the pilot test on this seed, Turbo v1.1 flipped the scrunchie to the left side, while Turbo v1.0 and Base + Turbo LoRA mutated her hairstyle into twin tails.
In this benchmark, both v2 and Role-Ref-KV consistently kept the single side ponytail on image-right across all 4 setups.
Although Role-Ref-KV’s README marks other base models as untested, it functioned properly on both full Turbo models, as well as on Base + Turbo LoRA and 2.9B Unofficial Turbo via the assertion-bypassing alias node.
The reddish hair tendency in the cake scene persisted across Turbo models as well.
Testing if ref_guidance 4.5 Causes 4koma Collapse
In the pilot test, running Turbo models with cfg 1.0 and ref_guidance 4.5 caused all 4 setups to fragment into 4koma comic layouts or completely collapse.
I re-tested the cake scene on v2 with those exact parameters.
| Setup | Time | Result |
|---|---|---|
| Turbo v1.1 | 92.5s | Single illustration. Saturation dropped/dull, line art thicker |
| Turbo v1.0 | 92.5s | Single illustration. Shirt tinted light blue, sweat drops |
| Base + Turbo LoRA | 90.5s | Single illustration. Beige vest-like overlay appears over shirt |
| 2.9B Unofficial Turbo | 124.6s | Single illustration. Shirt tinted light cyan |
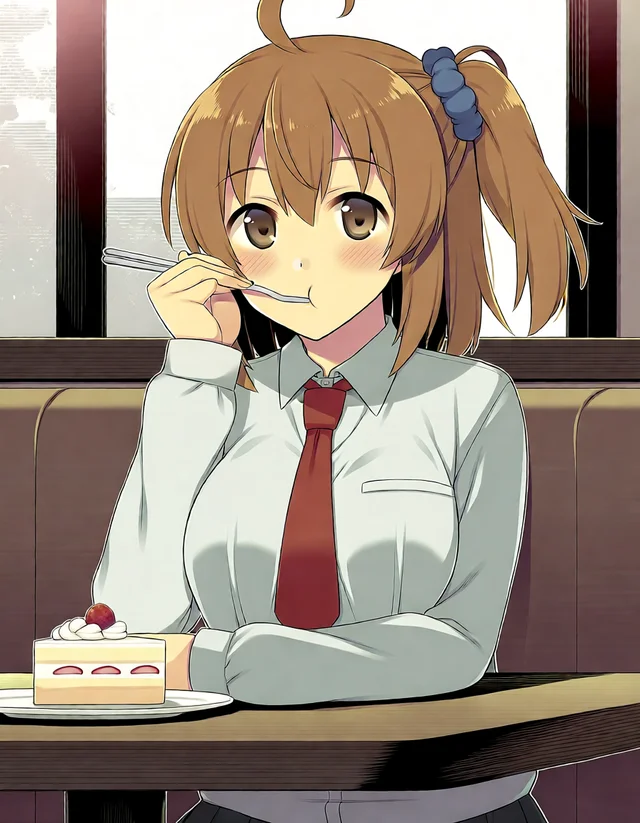
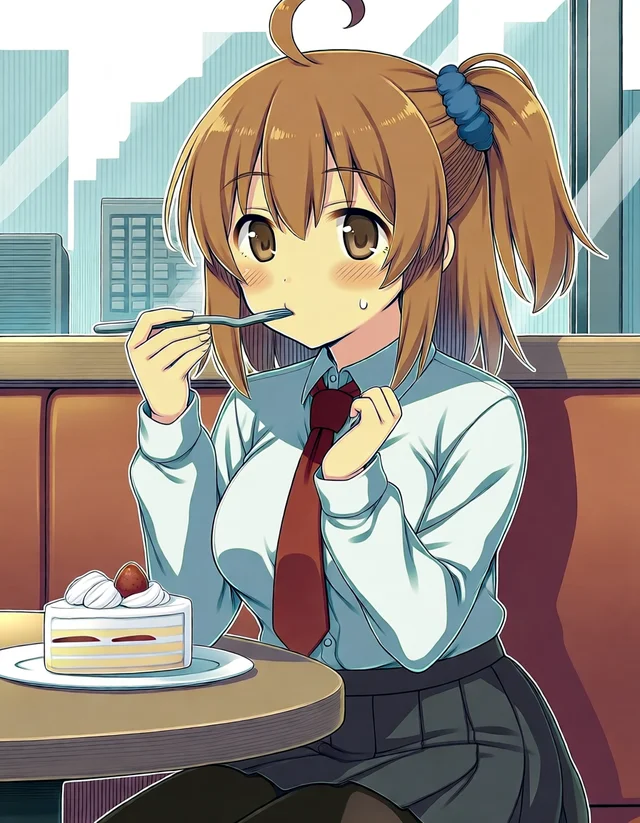
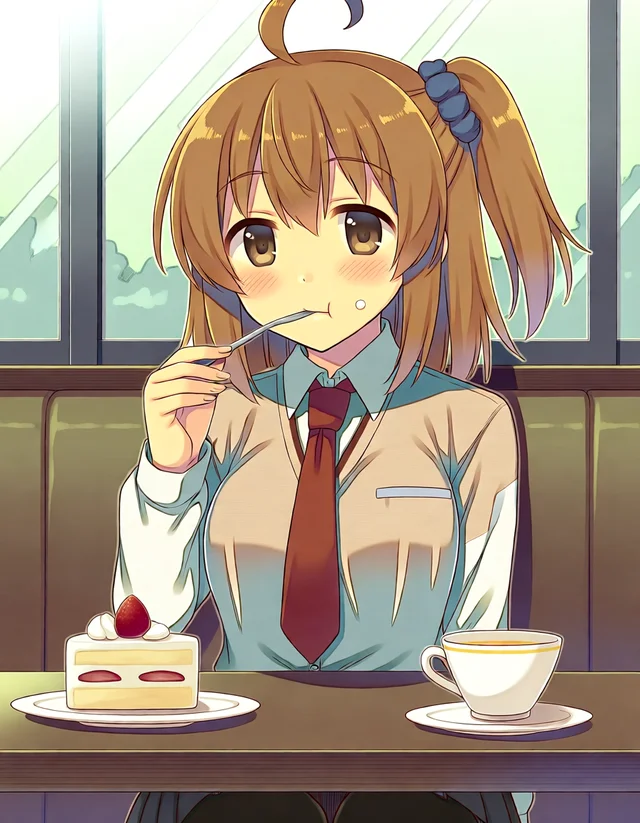
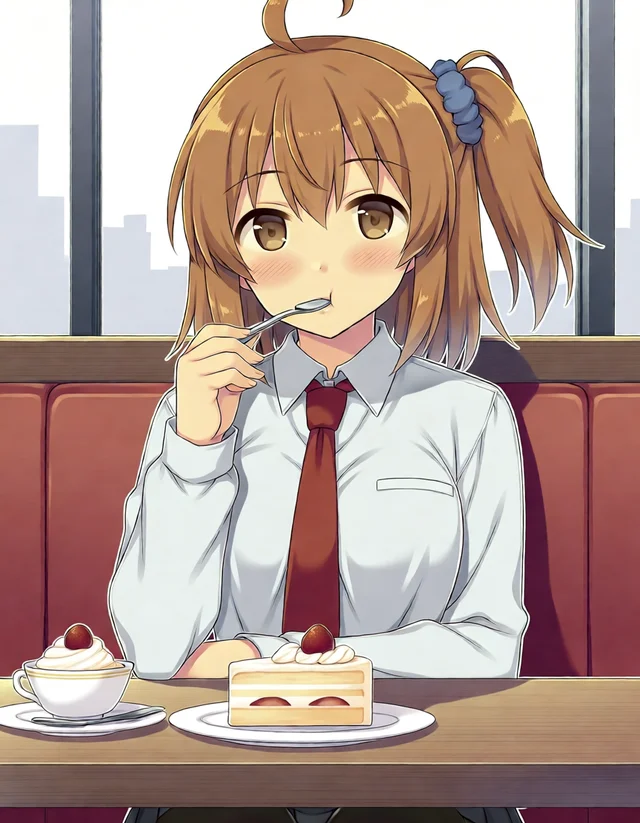
None of the 4 setups split into 4koma panels; each produced a cohesive single-frame scene.
However, the visual side effects—dulled colors and blue-tinted shirts—exhibit the same underlying distortion patterns that preceded the pilot’s panel fragmentation.
When ref_guidance != 1.0, v2 evaluates an extra unreferenced model pass at each step, adding the difference scaled by ref_guidance - 1.
At cfg 1.0, this disproportionately amplifies reference guidance alone, exactly as it did in the pilot.
In v2, the composition held intact while the impact manifested primarily in color shifts.
When running Turbo models at cfg 1.0, sticking to ref_guidance 1.0 delivers far more accurate colors faithful to the reference image.
Testing Lying-Down Overhead Perspective
Replicating the previous prompt, I tested an overhead perspective of the character lying supine on a grassy field.
| Setup | Time | Result |
|---|---|---|
| v2 Turbo v1.1 | 58.3s | Lying on back in grassy field with white flowers, knees bent toward foreground. Loafers intact |
| Role-Ref-KV Turbo v1.1 | 92.4s | Head at bottom of frame, feet at top. Purple and pink flowers |
| v2 Base | 476.4s | Lying on back with knees bent, near-identical composition to v2 Turbo v1.1. Loafers intact |
| Role-Ref-KV Base | 297.6s | Angled body on back with knees bent. Loafers intact. Hair leans orange |
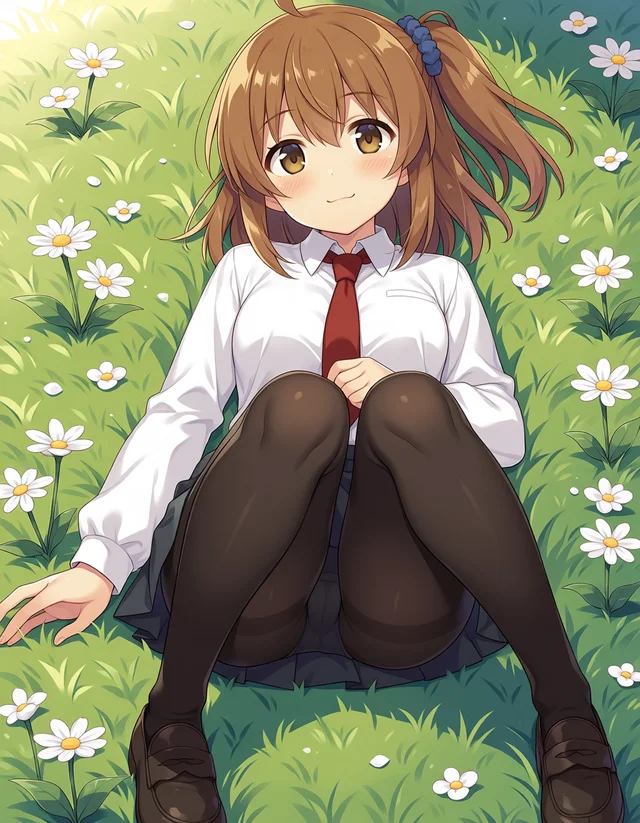
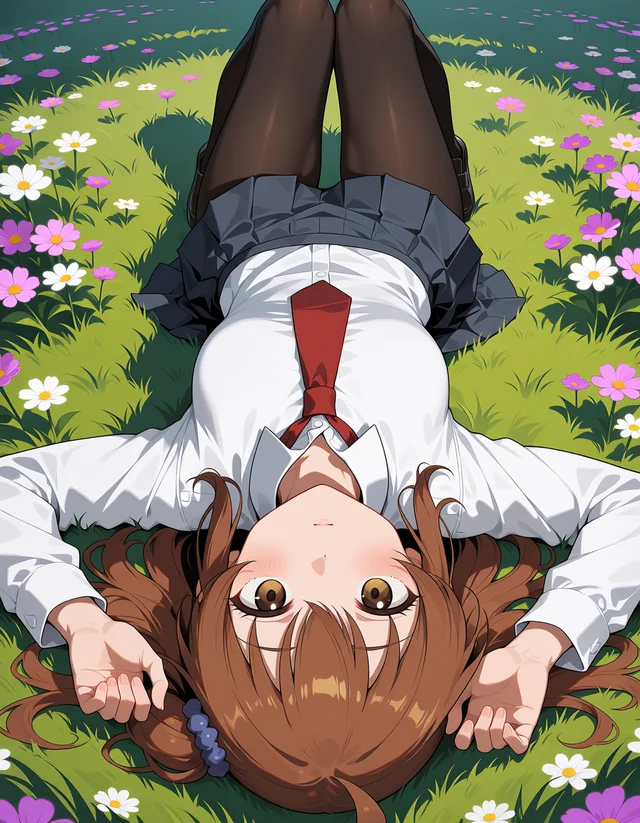
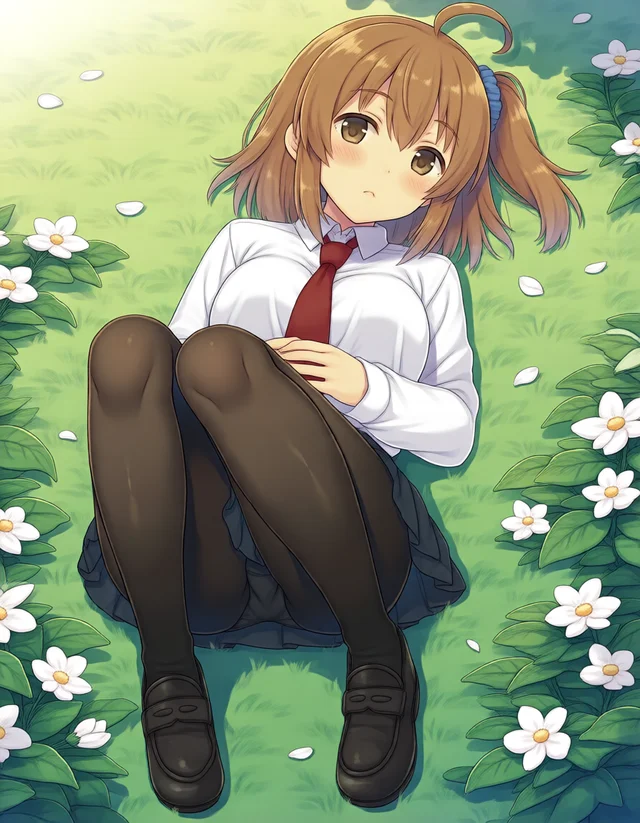
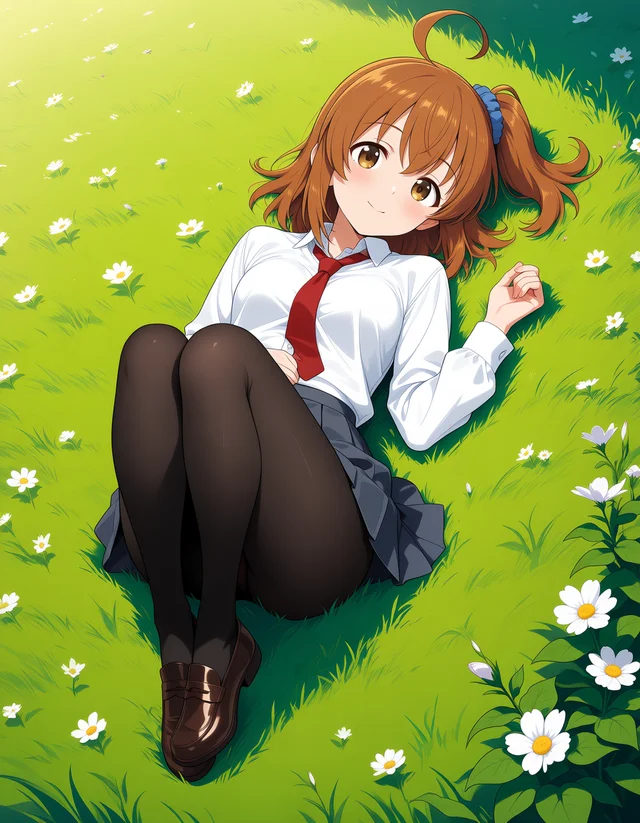
All 4 outputs successfully translated the standing front portrait into a supine overhead perspective while preserving character identity.
Role-Ref-KV on Turbo v1.1 oriented her inverted with her head at the bottom of the frame, but generating Turbo v1.1 without any adapter in the previous post also produced an inverted orientation.
Even with inverted framing, the ahoge, scrunchie, and tie remained true to the reference.
Prompt
masterpiece, best quality, score_7, newest, highres, absurdres, safe, 1girl, solo, full body, lying on back, on grass, from above, looking at viewer, flowers, daytimeRunning Scene Across Different Seeds
In the pilot test, hair consistency broke only on seed 20261027, staying stable across two additional seeds.
Here, I tested seeds 20261028 and 20261029 across the 4 Turbo setups, plus recommended-setting Base and 2.9B (remapped).
| Setup | v2 s20261028 | v2 s20261029 | Role-Ref-KV s20261028 | Role-Ref-KV s20261029 |
|---|---|---|---|---|
| Turbo v1.1 | Side ponytail | Side ponytail | Side ponytail. Black tights become thigh-highs. Hair tips orange | Side ponytail |
| Turbo v1.0 | Side ponytail | Side ponytail | Side ponytail | Side ponytail |
| Base + Turbo LoRA | Side ponytail | Side ponytail | Side ponytail. Black tights become thigh-highs | Side ponytail |
| 2.9B Unofficial Turbo | Side ponytail | Side ponytail | Side ponytail. Smaller character. Hair tips orange | Side ponytail |
| Base | Side ponytail | Side ponytail | Ponytail and scrunchie lost, shoulder-length hair. Character small | Ponytail, scrunchie, and tie lost; black jumper skirt. Hair leans orange |
| 2.9B (Remapped) | Side ponytail | Side ponytail | Side ponytail. Smaller character | Near-identical to Base s20261029. Jumper skirt without tie |
“Side ponytail” in the table denotes visual confirmation of the side ponytail with blue scrunchie on image-right under close magnification.
The backward-facing pose that appeared twice out of three seeds on pilot Base did not occur once on either v2 or Role-Ref-KV.
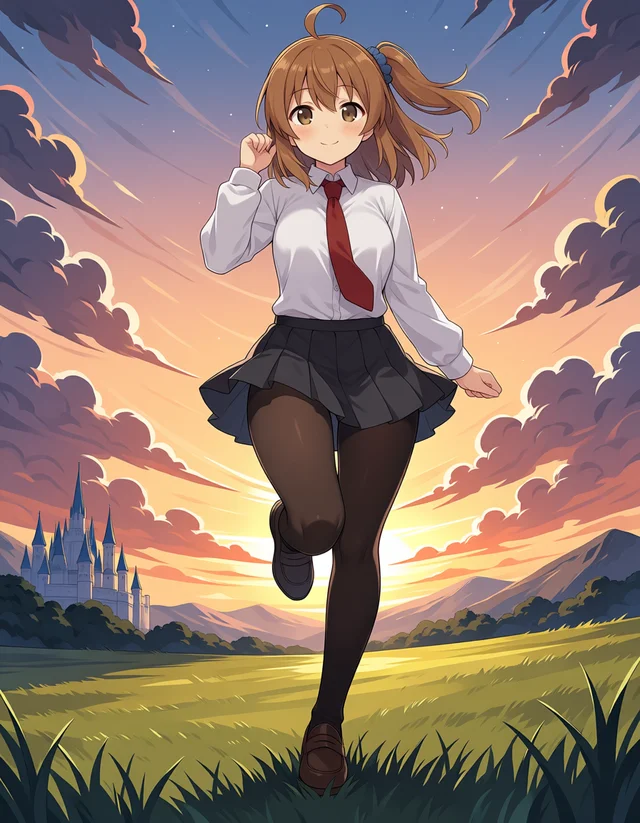
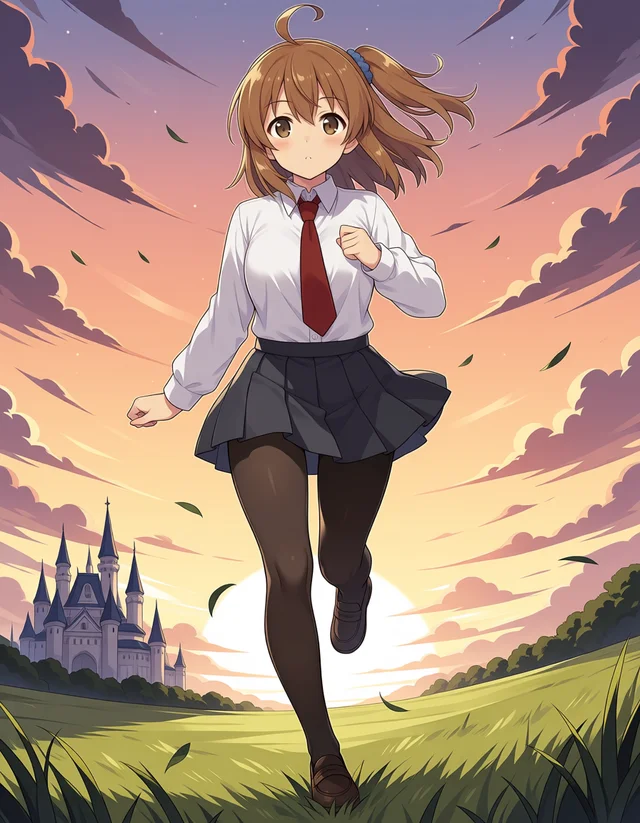
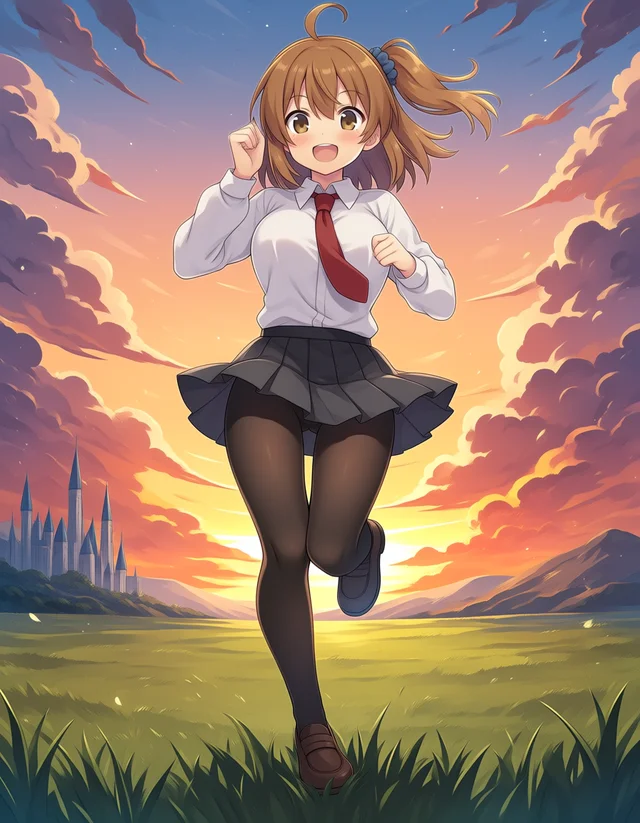
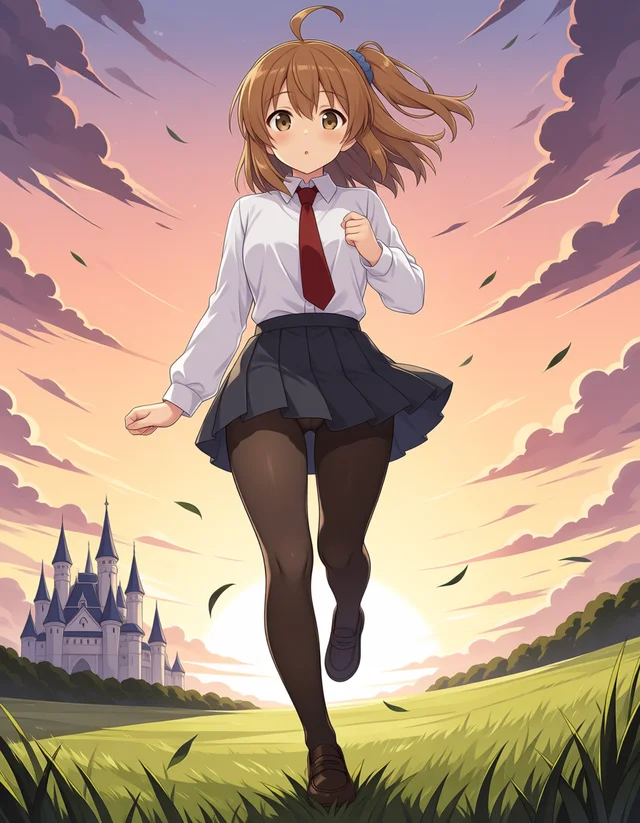
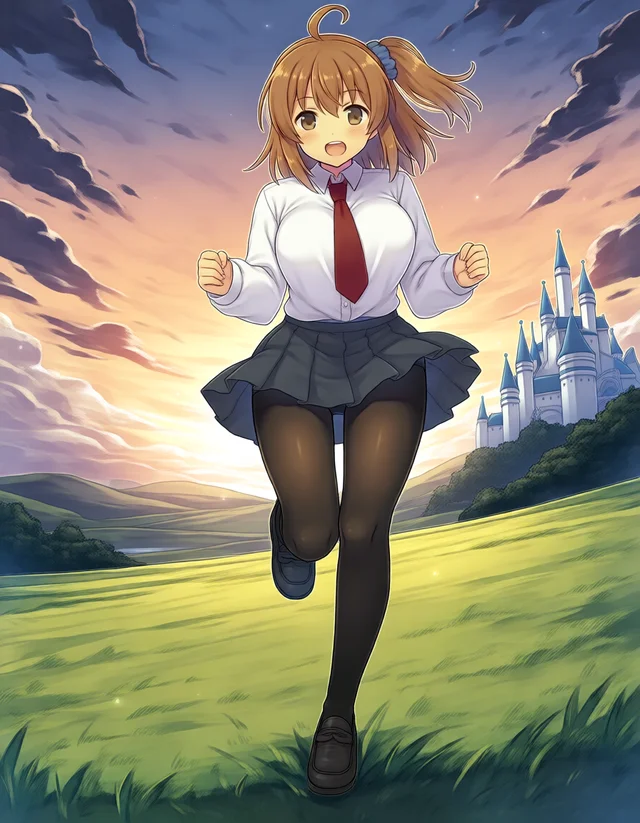
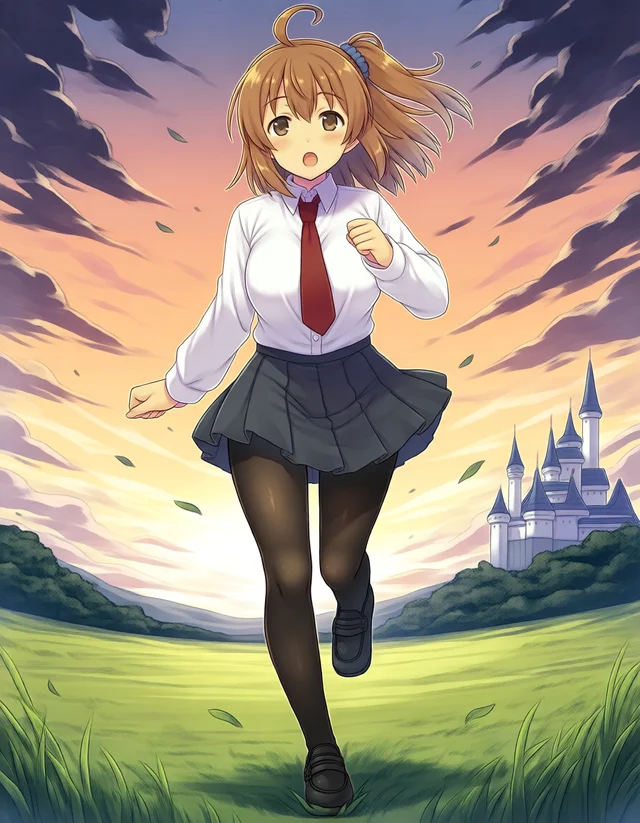
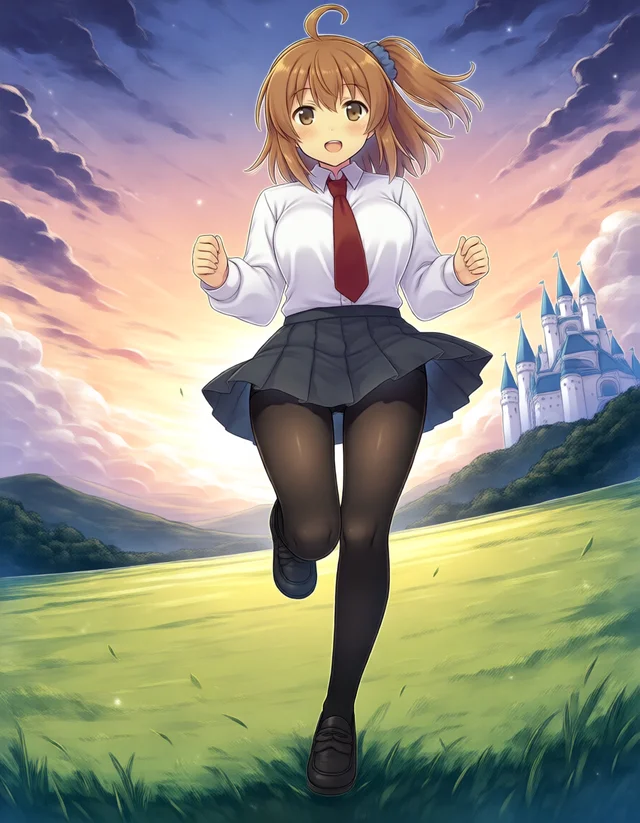
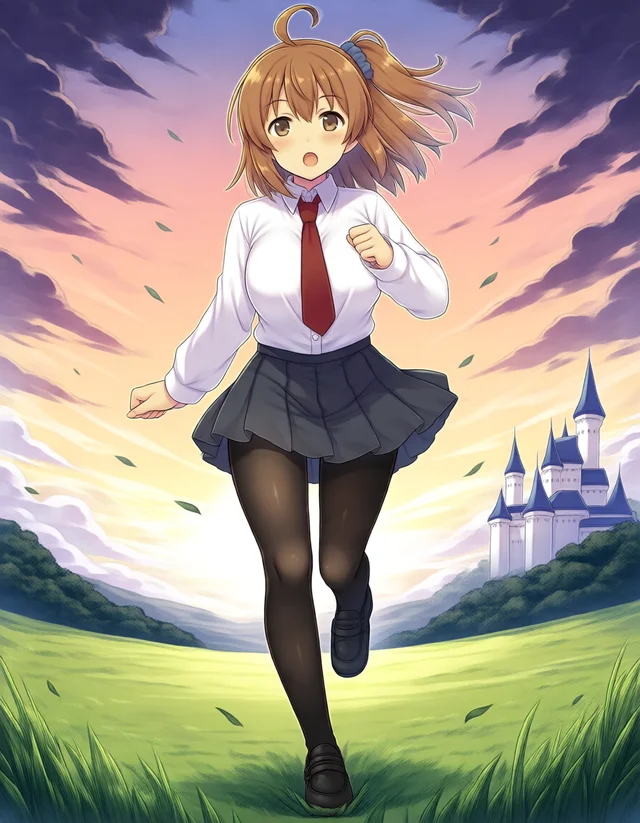
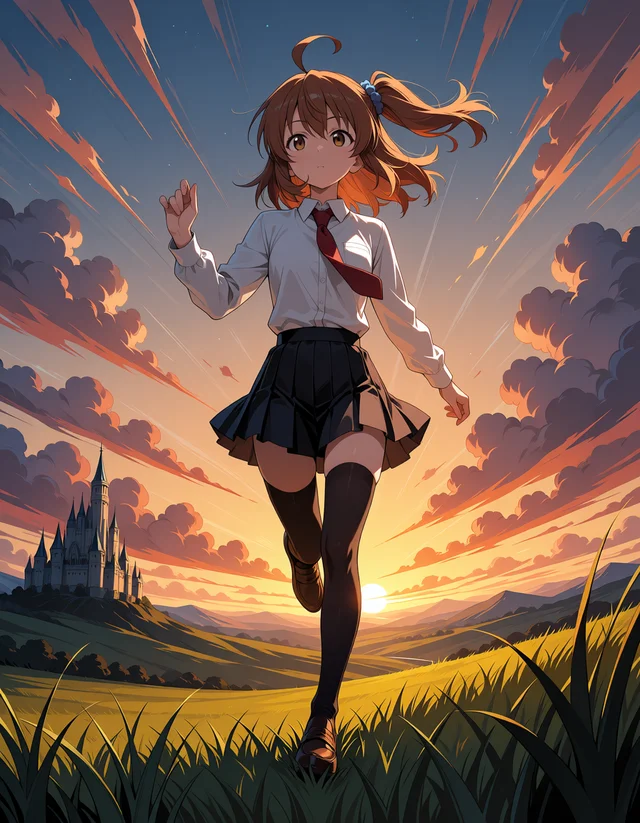
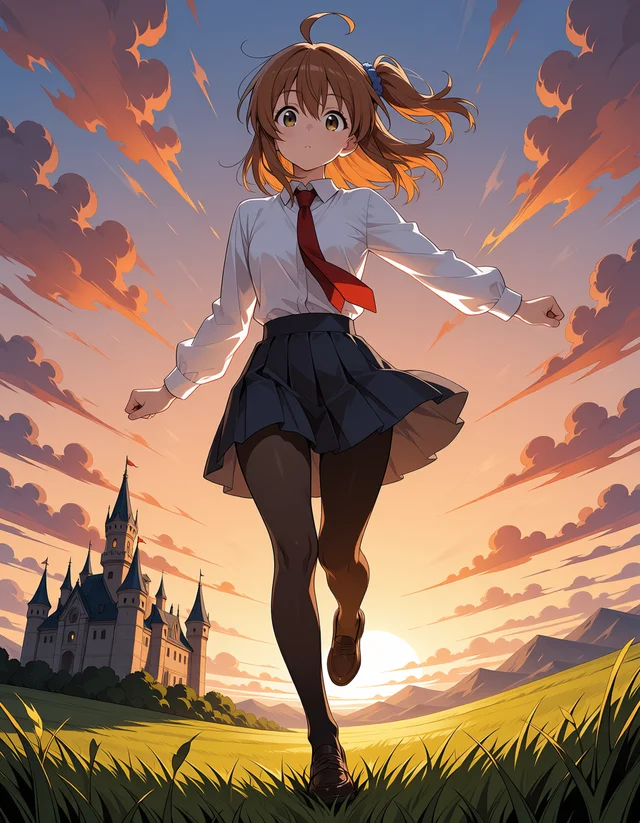
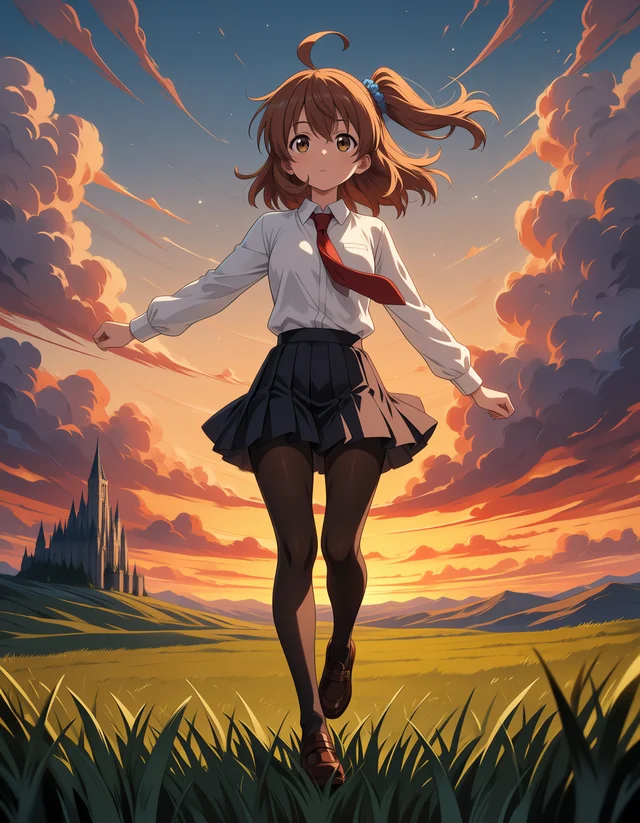
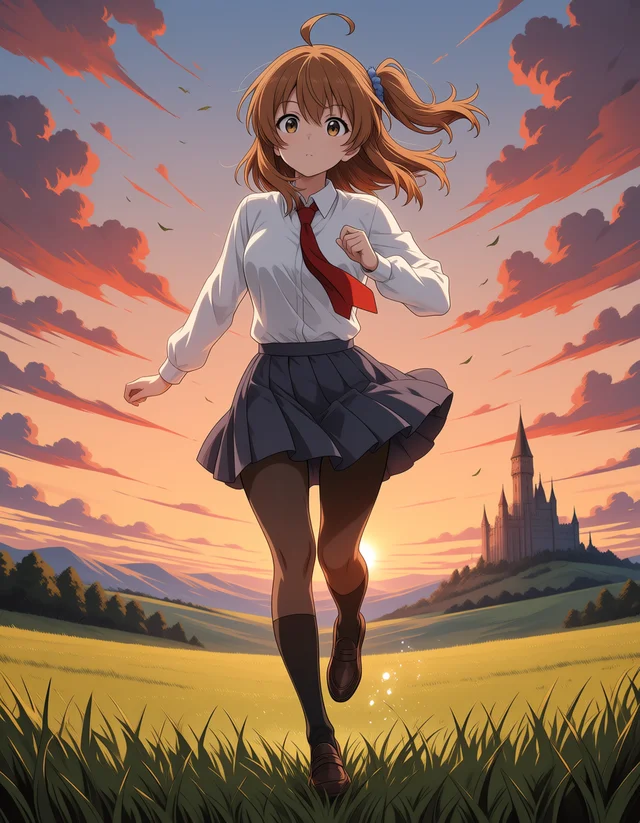
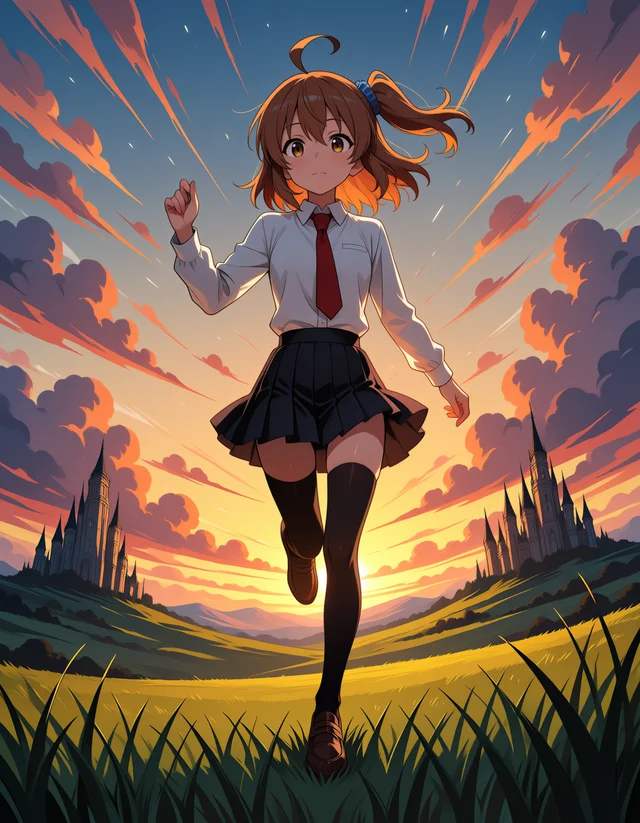
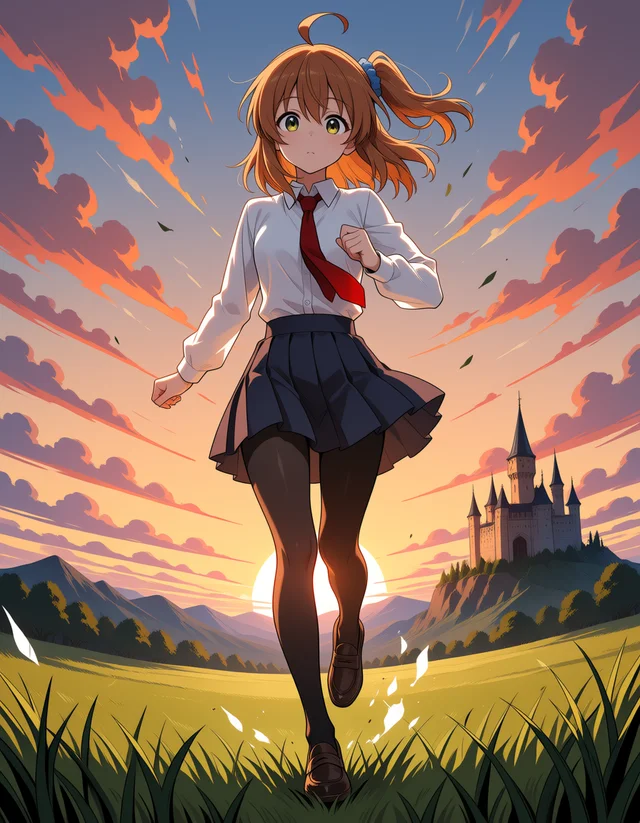
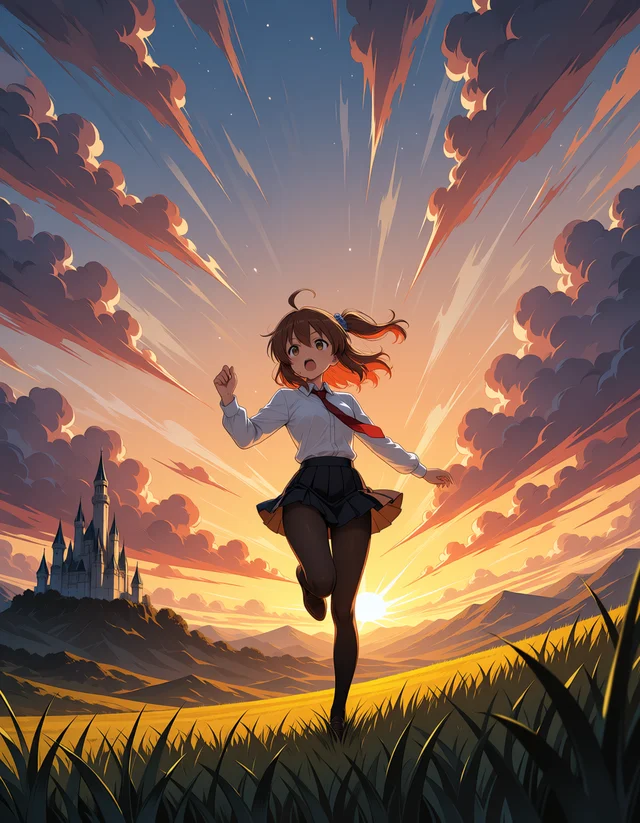
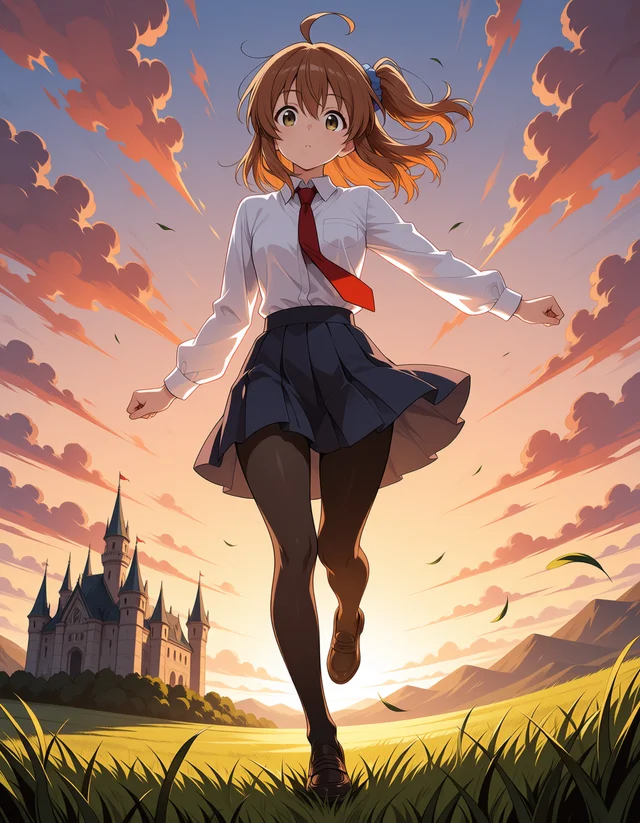
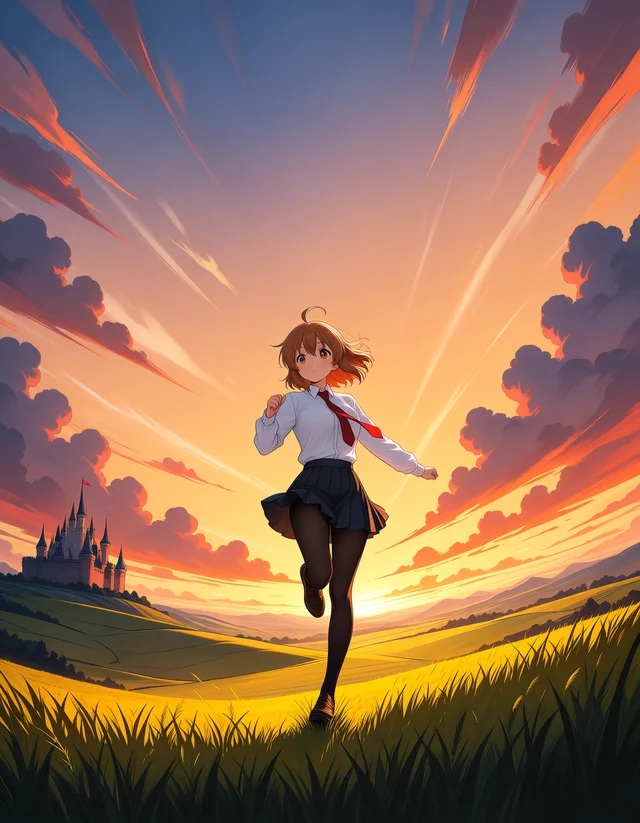
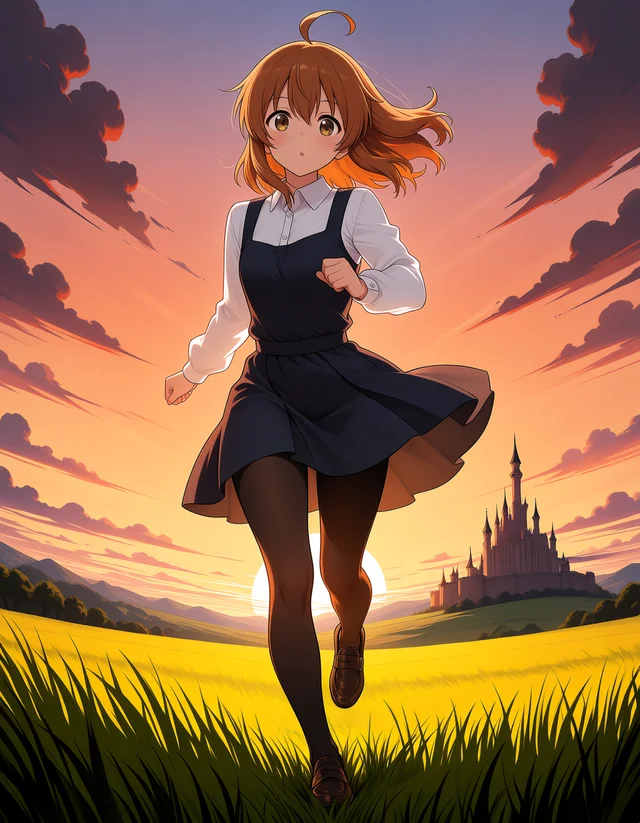
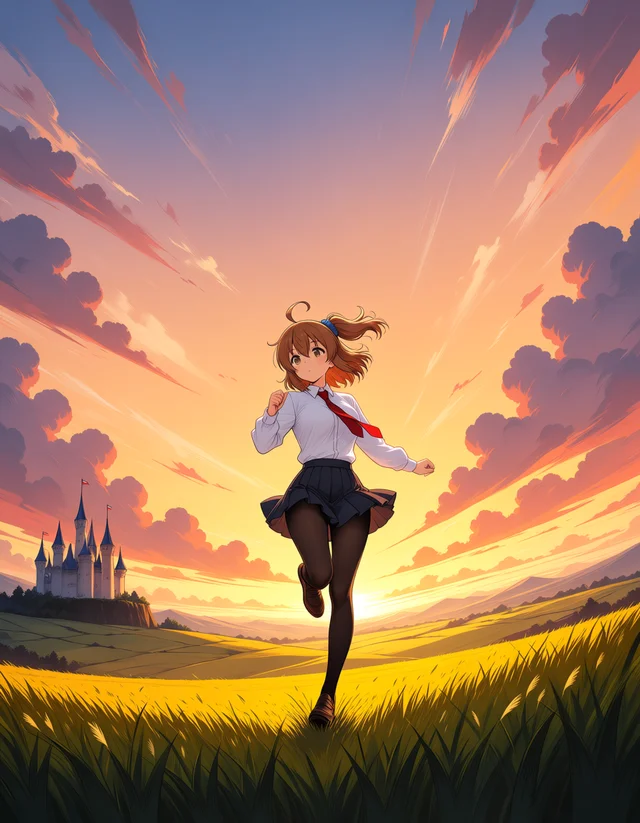
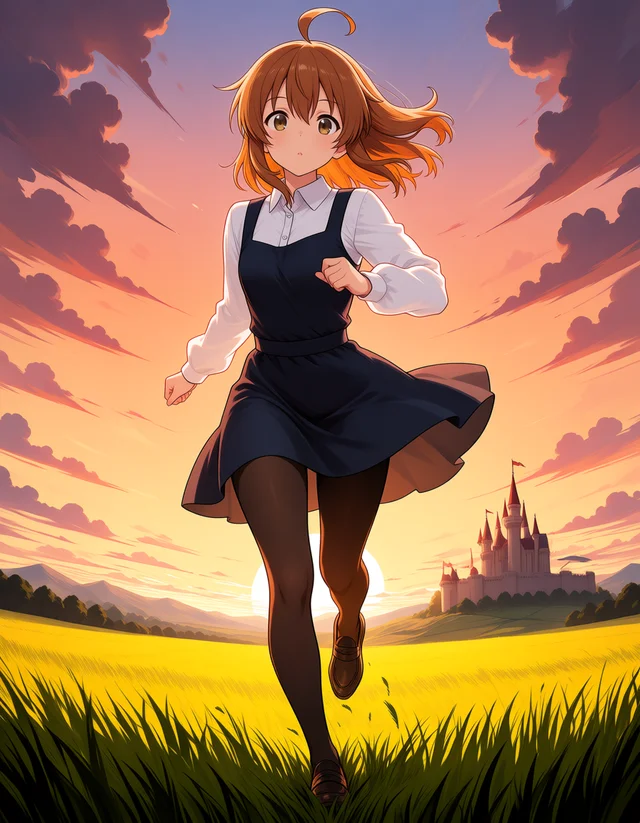
Across all 18 images (6 setups × 3 seeds), v2 maintained the side ponytail, white shirt, red necktie, and black tights exactly as specified in the reference.
Even across different seeds, v2 yielded near-identical framing for any given seed regardless of model variant, consistently placing the character large within the frame.
Out of 18 images with Role-Ref-KV, the hairstyle was lost on 2 Base images and 1 2.9B image, and clothing deviated completely to a jumper skirt on Base and 2.9B on seed 20261029.
With Role-Ref-KV, character sizing and background composition varied by condition even on identical seeds, occasionally introducing localized mutations such as orange-tipped hair or thigh-high stockings.
Swapping Reference Adapters with CharRef-LLLite
CharRef-LLLite is a custom node enabling concurrent use of toyxyz’s 3D pose LLLite (a lightweight ControlNet variant) and Ref Adapter.
While standard LLLite injects residuals into block inputs to guide poses, ComfyUI’s standard LLLite patching assumes only generated image tokens.
When Ref Adapter introduces reference tokens, standard patching fails; CharRef-LLLite resolves this by applying LLLite residuals exclusively to the generated image tokens, as noted in its README.
It supports both v2 and pilot.
For pose input, I used 3dpose_example.png from toyxyz’s repository: a 768×1152 image of a flesh-toned mannequin sitting with one knee raised against a black background.
The reference was Kana-chan’s portrait on Turbo v1.1, 8 steps, cfg 1.0, ref_guidance 1.0 for v2 and pilot, with LLLite strength at 1.0 throughout sampling.
Role-Ref-KV’s official node rejects LLLite-patched models.
Even when routed through the assertion-bypassing alias node, Role-Ref-KV bypasses ComfyUI’s standard forward pass to execute its internal loop, skipping the LLLite patches entirely.
To test this, I wrote an experimental connector node that injects LLLite residuals exclusively into the generated image tokens inside Role-Ref-KV’s internal forward pass.
Mirroring CharRef-LLLite, the residuals are added to self_attn (q/k/v), cross_attn (q), and mlp (layer1 inputs), completely omitting the reference key/value pipeline.
| Setup | Time | Result |
|---|---|---|
| Pose Only (No Reference) | 36.1s | Sitting on round stool, one knee raised, right hand on seat. Faithful to mannequin pose. Different character with cat ears, black hair, pink highlights, barefoot |
| v2 Reference Only (No Pose) | 50.2s | Kana-chan. Sitting on floor with both knees hugged up. Loafers intact |
| Role-Ref-KV Reference Only (No Pose) | 80.4s | Kana-chan. Sitting on floor hugging knees with hands and chin on knees. Loafers intact |
| CharRef-LLLite + v2 | 86.4s | Kana-chan. One knee raised, right hand on floor. Matches pose. Shoes missing, showing black-tights feet |
| CharRef-LLLite + pilot | 148.6s | Kana-chan. Sitting on stone block, one knee raised, right hand on block. Matches pose. Loafers intact |
| Official Role-Ref-KV + LLLite | Error | Use an unpatched Anima Base v1.0 MODEL; this node loads the Anima Role Ref KV adapter itself |
| Alias Node + LLLite | 80.2s | Hugging knees on floor. Pose ignored, composition near-identical to reference-only |
| Connector Node + Role-Ref-KV | 80.3s | Kana-chan. Sitting on stone block, one knee raised, right hand on block. Matches pose. Loafers intact |
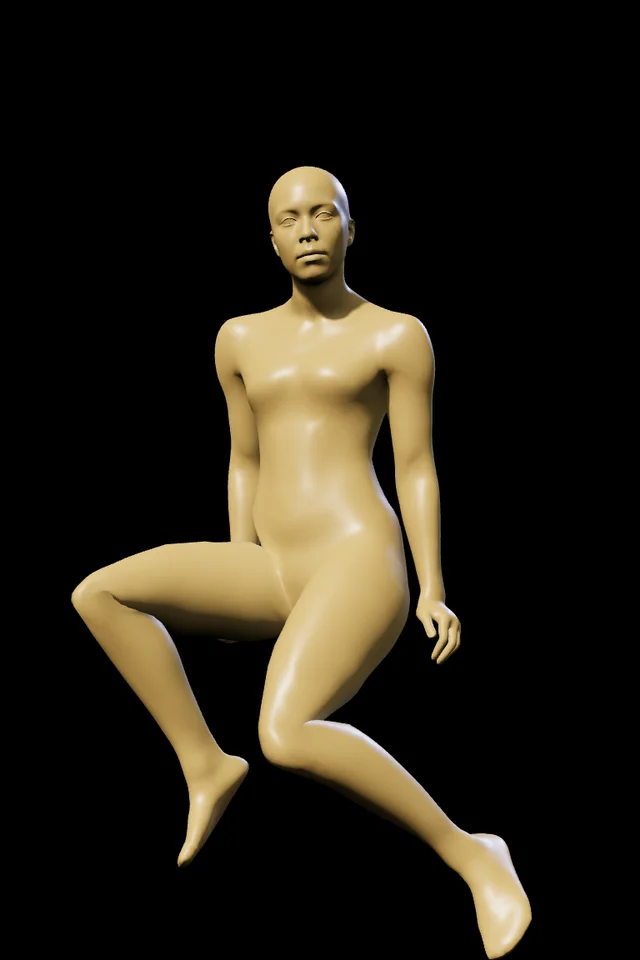
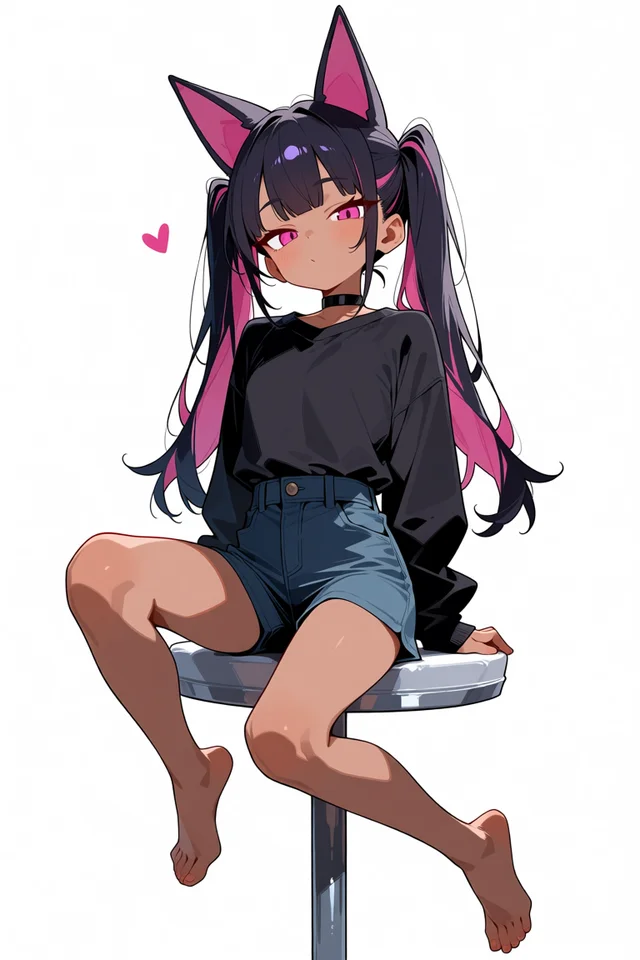
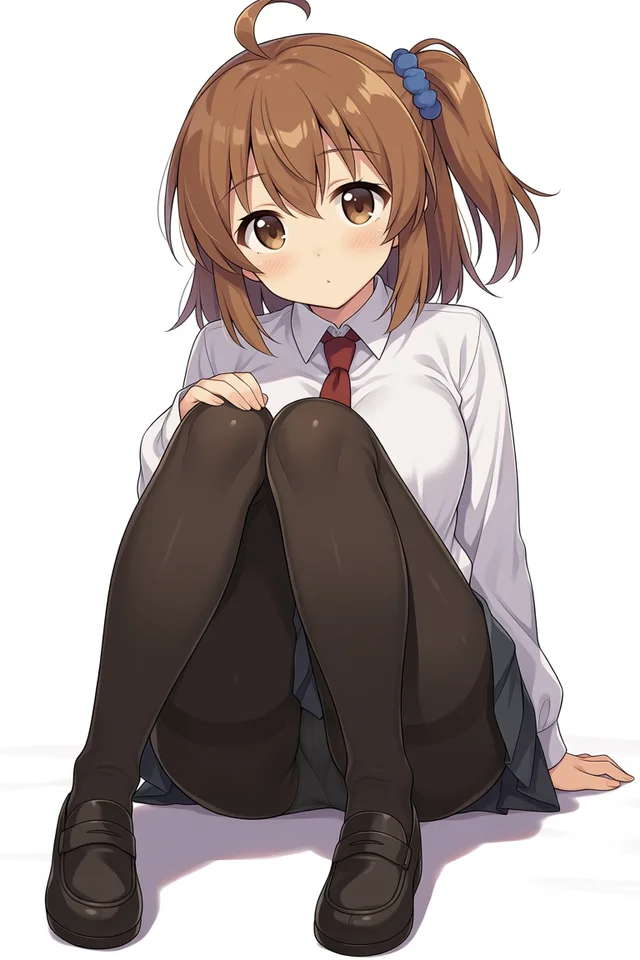
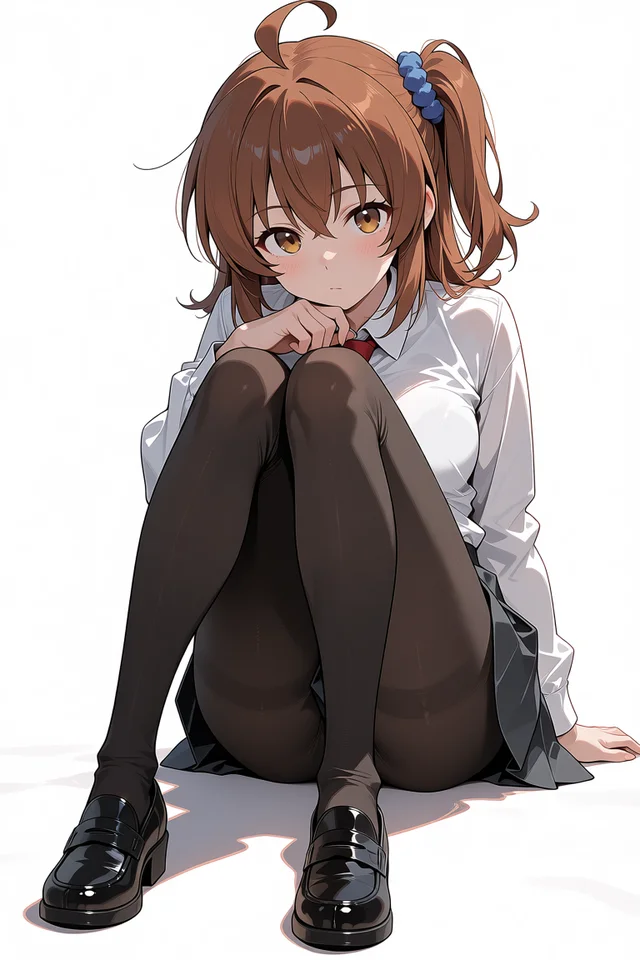
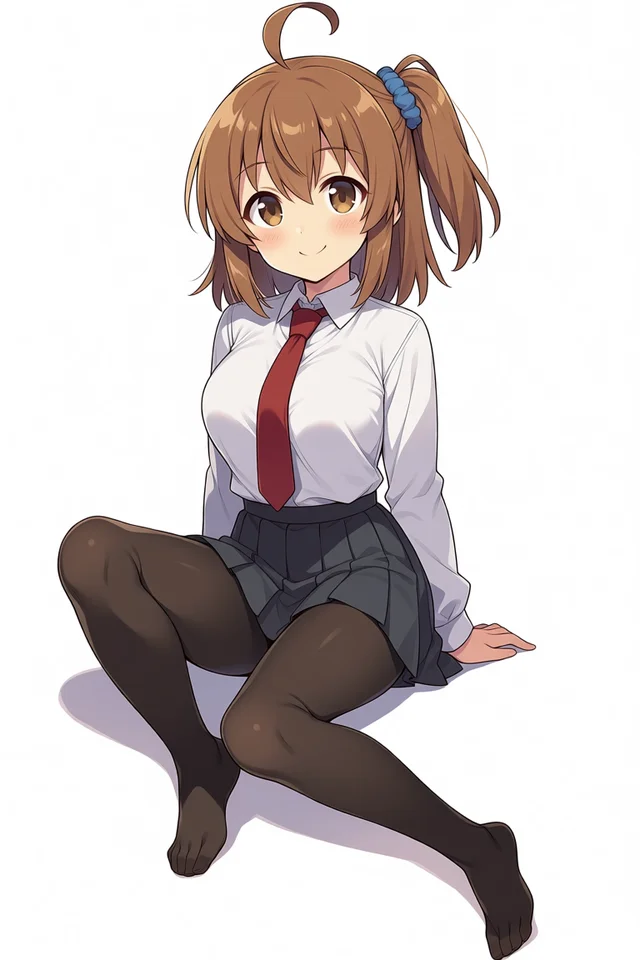
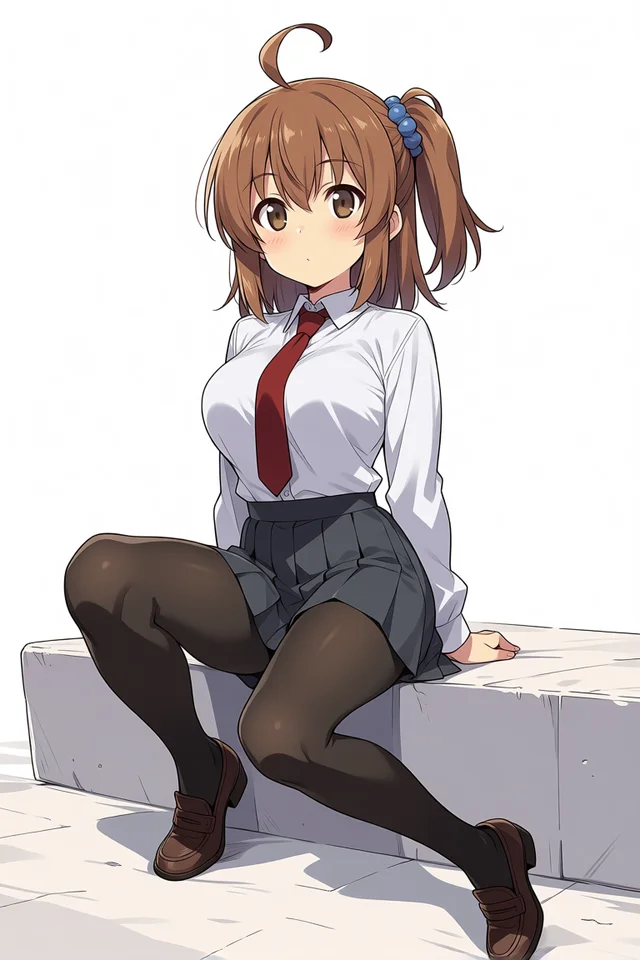
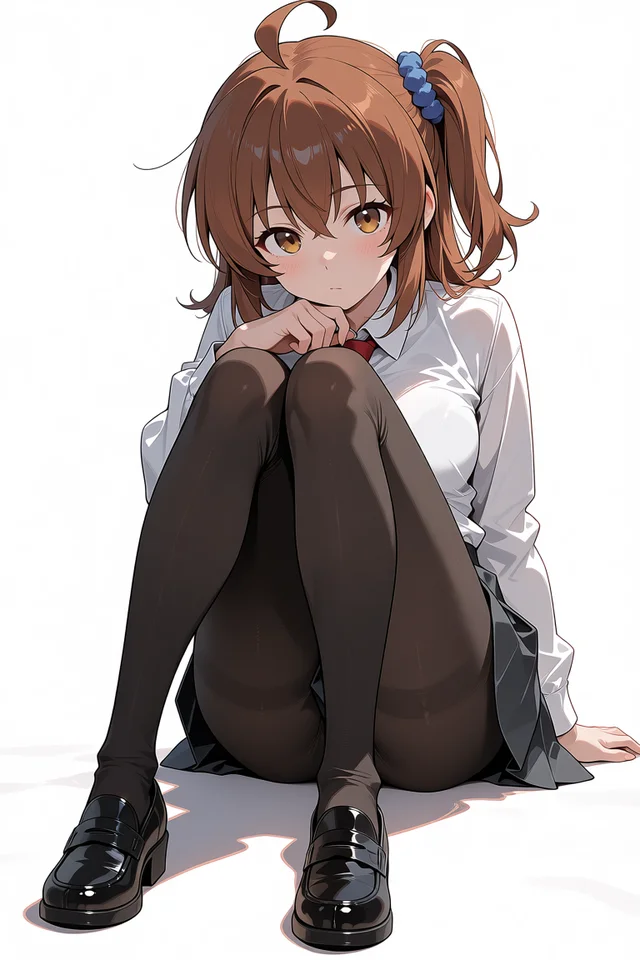
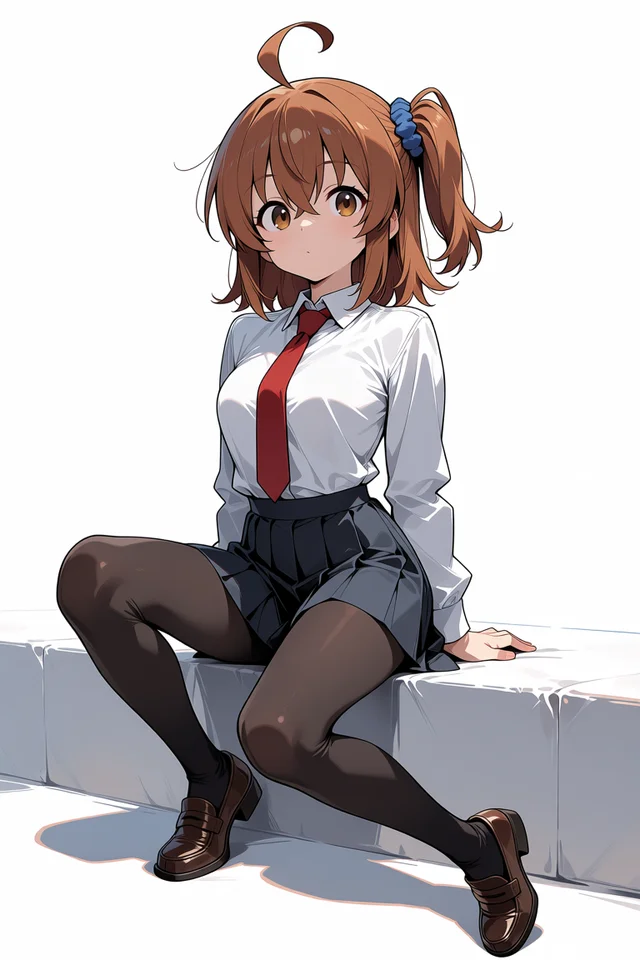
Pose-only produced a different character, while reference-only defaulted to sitting hugging knees.
In all 3 successful joint setups, Kana-chan adopted the mannequin’s exact posture.
Role-Ref-KV also achieved the same separation of duties once LLLite residuals were restricted to the generated token stream via the connector node.
Only the v2 pairing lost her loafers, rendering bare black-tights feet instead.
Under v2 reference-only without LLLite, loafers were present.
To check whether this was coincidence, I tested seeds 20261028 and 20261029 across the 4 combinations on Turbo v1.1.
| Setup | s20261027 | s20261028 | s20261029 |
|---|---|---|---|
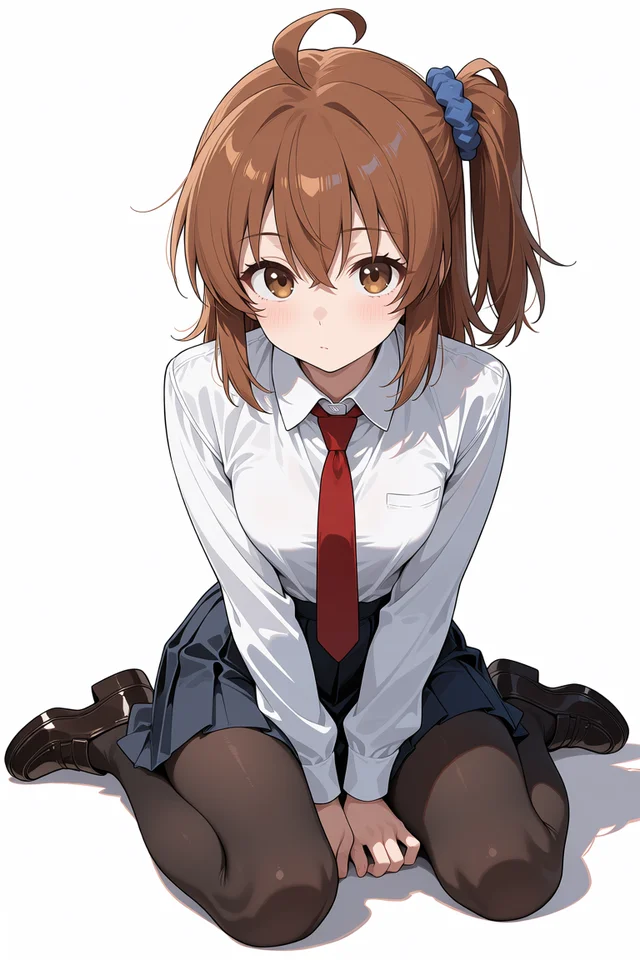
| CharRef-LLLite + v2 | Sitting on floor. Bare feet | Sitting on white bench. Loafers intact | Sitting on green bench. White sneakers |
| CharRef-LLLite + pilot | Sitting on stone block. Loafers intact | Sitting on white bench. Loafers intact | Sitting on green bench. Loafers intact |
| Connector Node + Role-Ref-KV | Sitting on stone block. Loafers intact | Sitting on white bench. Loafers intact | Sitting on stone bench. Loafers intact |
| Alias Node + LLLite | Hugging knees | Sitting flat on floor (w-sitting) | W-sitting. Heart shape |
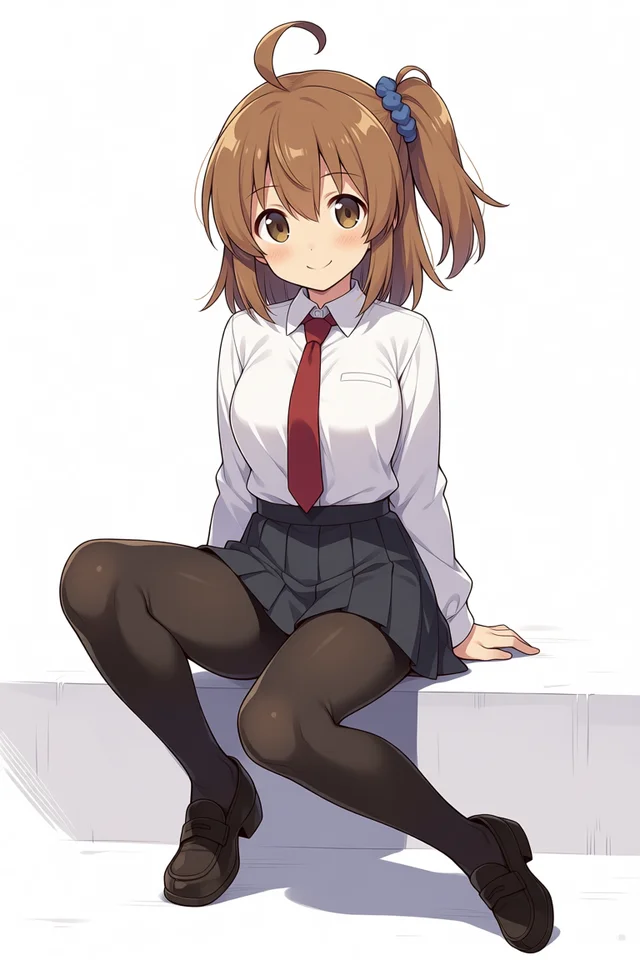
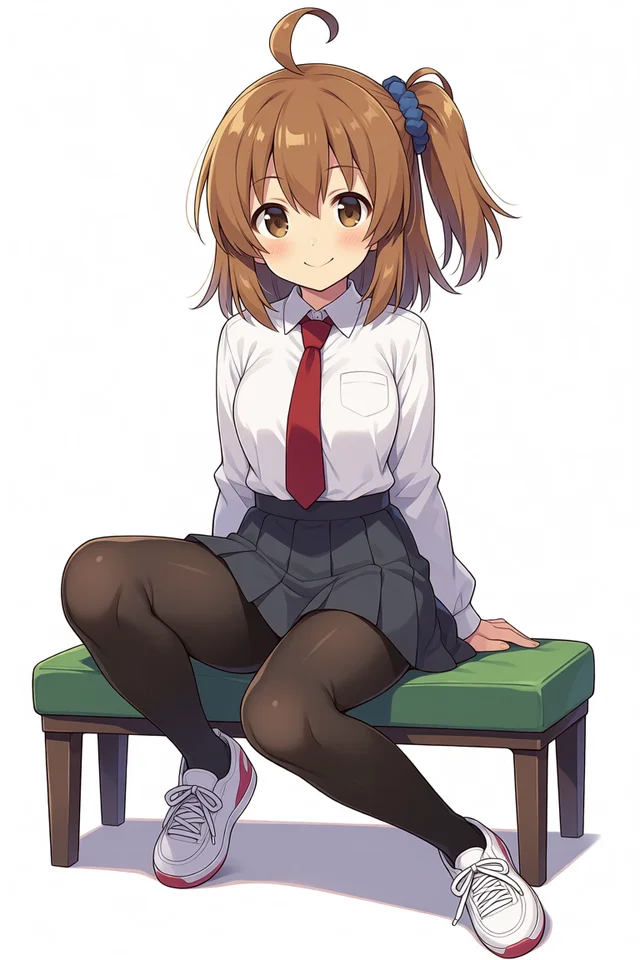
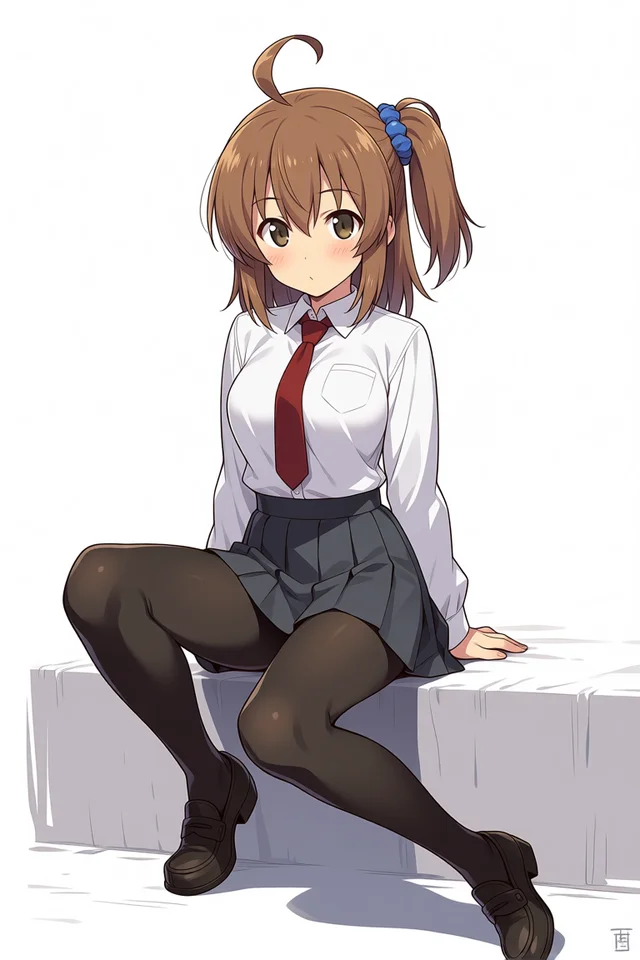
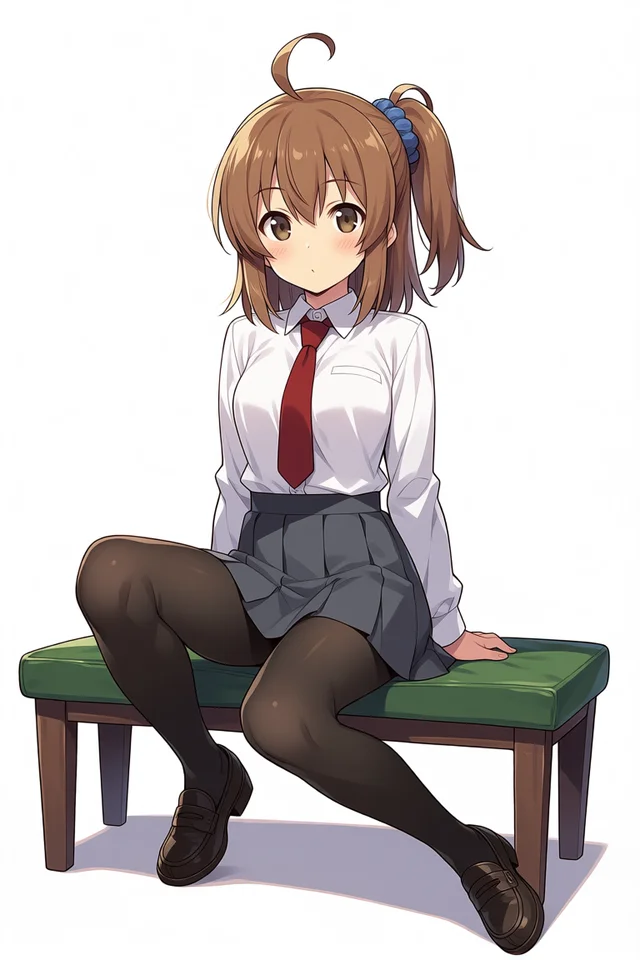
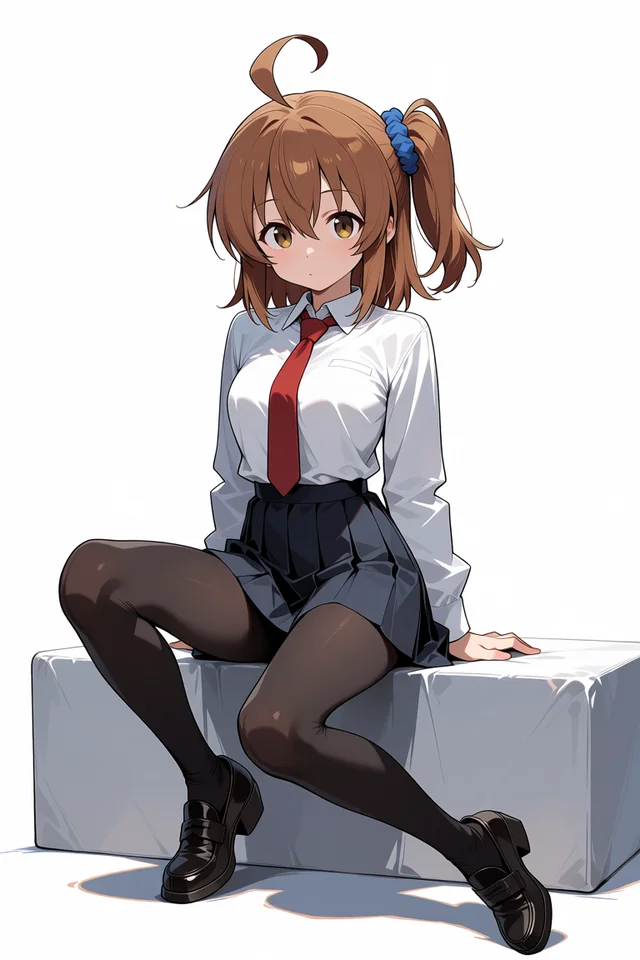
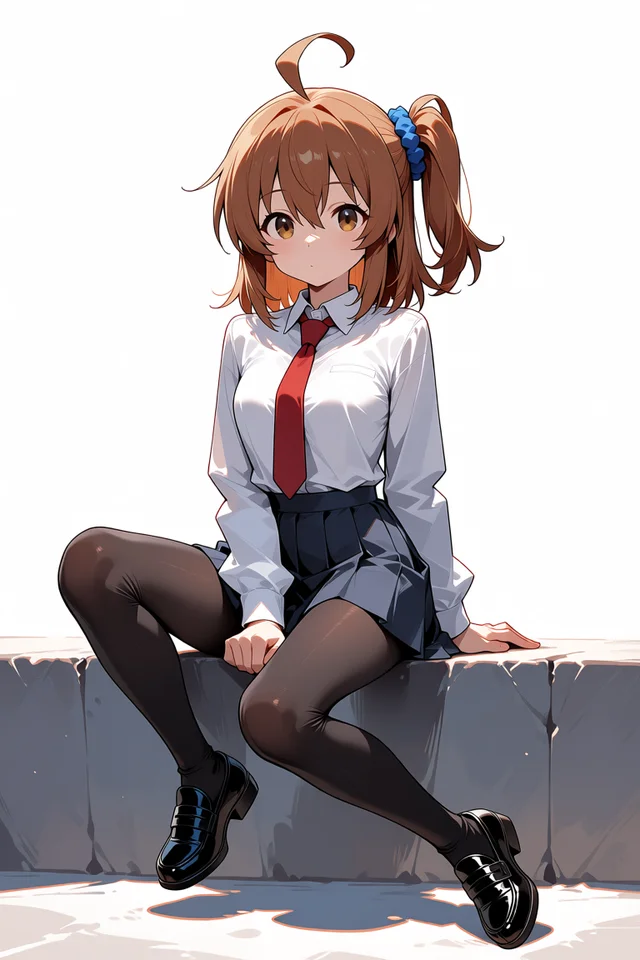
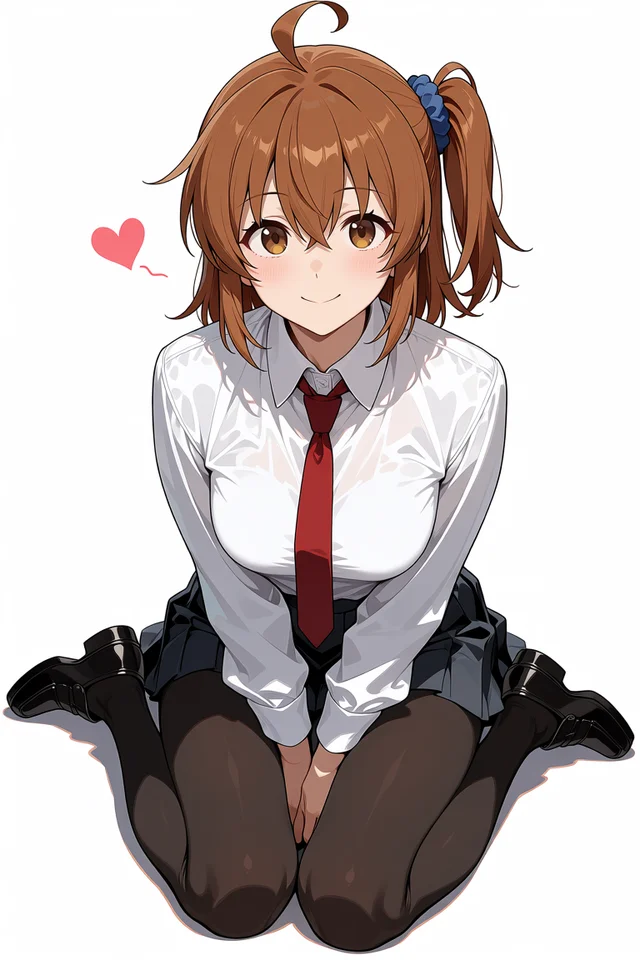
Across all 3 seeds, the 3 functioning combinations sat with one knee raised and hands placed behind, matching the mannequin.
The unpatched alias node ignored the mannequin across all 3 seeds.
v2’s footwear varied on every seed—bare feet, loafers, and white sneakers—rendering loafers on only 1 out of 3 runs.
pilot and Role-Ref-KV preserved loafers across all 3 seeds.
Because LLLite was trained on Base, I also tested the pose on Base.
v2 ran at 30 steps, cfg 4.5, ref_guidance 4.5; Role-Ref-KV ran at 28 steps, cfg 4.
| Setup | Time | Result |
|---|---|---|
| CharRef-LLLite + v2 | 403.3s | One knee raised, right hand on floor. Matches pose. Shoes missing, black-tights feet |
| Connector Node + Role-Ref-KV | 261.1s | Sitting on white bench, one knee raised, right hand on bench. Matches pose. Loafers intact |
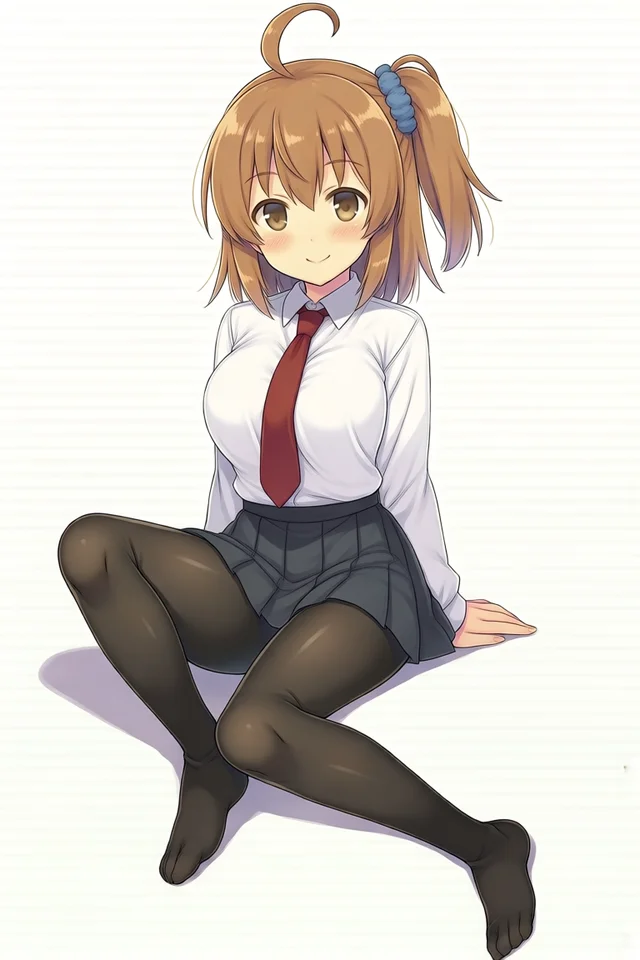
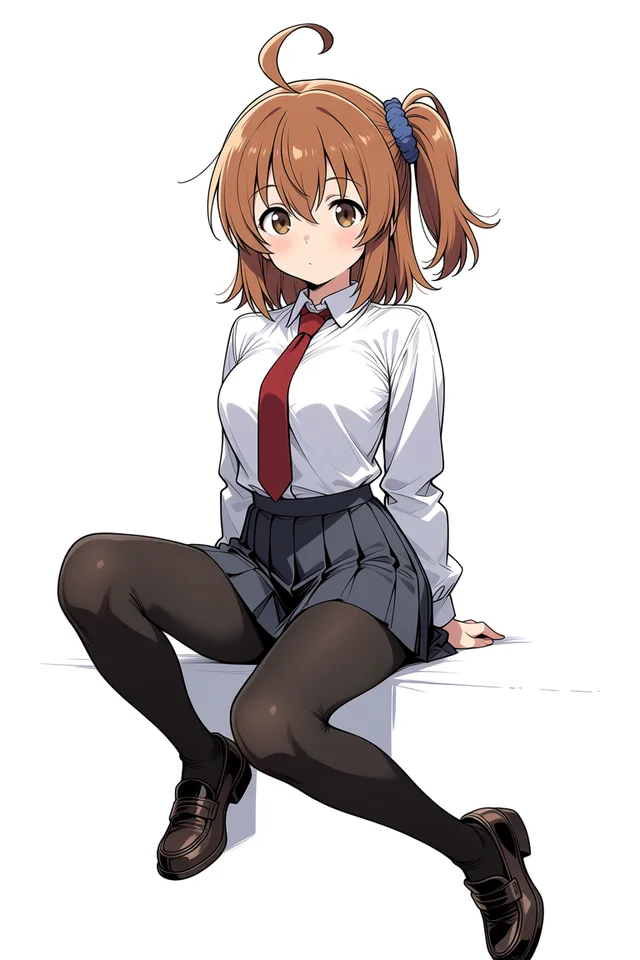
On Base as well, v2 dropped the loafers while Role-Ref-KV retained them.
Prompt
masterpiece, best quality, score_7, newest, highres, absurdres, safe, 1girl, solo, full body, sitting, looking at viewer, simple backgroundGeneration Speed Benchmarks
Measured generation times for 896×1152 images on M1 Max 64GB.
v2 computes reference key/values once; subsequent per-step model passes evaluate 1 time for cfg 1.0, ref_guidance 1.0, 2 times for cfg 1.0, ref_guidance 4.5, and 3 times for cfg 4.5, ref_guidance 4.5.
Role-Ref-KV evaluates an unreferenced negative pass on every step even at cfg 1, maintaining 2 passes per step.
The pilot column shows figures from the previous post, where Turbo ref_guidance 1.0 also ran 2 passes per step.
| Setup | Steps | v2 | Role-Ref-KV | pilot (Previous) |
|---|---|---|---|---|
| Base | v2: 30, Role-Ref-KV: 28 | 476.2–480.0s | 297.5–300.8s | ~772s |
| Aesthetic v1.1 | v2: 30, Role-Ref-KV: 28 | 478.5–482.1s | 297.5s | ~771s |
| 2.9B (Remapped) | v2: 30, Role-Ref-KV: 28 | 673.5–675.5s | 422.1–422.2s | ~1,085–1,095s |
| Turbo (3 setups), ref_guidance 1.0 | 8 | 56.3–60.3s | 92.4–92.5s | 174.7–182.8s |
| Turbo (3 setups), ref_guidance 4.5 | 8 | 90.5–92.5s | — | ~209–219s |
| 2.9B Unofficial Turbo, ref_guidance 1.0 | 8 | 80.5–82.4s | 128.7–130.7s | 245.1–255.1s |
| 2.9B Unofficial Turbo, ref_guidance 4.5 | 8 | 124.6s | — | ~293–301s |
The 3 Turbo setups encompass Turbo v1.1, Turbo v1.0, and Base + Turbo LoRA.
Since Role-Ref-KV lacks ref_guidance, its Turbo rows reflect cfg 1.
In the previous post, generating without any reference adapter took 262.7s on Base and roughly 38–40s on Turbo.
Compared to pilot, v2 ran roughly 1.6x faster on Base and 3x faster on Turbo with ref_guidance 1.0.
Because the pilot times were recorded on a different day, I re-ran the Turbo v1.1 ref_guidance 1.0 running scene consecutively in the order pilot, v2, and pilot on the same day.
Pilot clocked 184.5s and 178.5s, while v2 clocked 56.2s, confirming the ~3x acceleration held within the same session.
Running v2 on Turbo v1.1 takes about 1 minute, only ~20s slower than generating without any reference adapter.
Under recommended settings, Role-Ref-KV ran faster than v2, completing Base in roughly 5 minutes.
On Turbo, however, because Role-Ref-KV evaluates 2 passes per step even at cfg 1, it ran slower than v2 at ref_guidance 1.0.
Which One to Choose
| Goal | Recommendation |
|---|---|
| Fastest generation on Turbo models | Ref Adapter v2 (cfg 1.0, ref_guidance 1.0) |
| Generation on Base / Aesthetic with recommended settings | Speed favors Role-Ref-KV. However, hair color, hair style, and clothing drifted on certain seeds; v2 yielded higher overall fidelity to the reference image |
| Pairing with standard ComfyUI samplers, other LoRAs, or custom nodes | Ref Adapter v2. Official Role-Ref-KV nodes reject patched models |
| 2.9B models | Both require LoRA key remapping for 40 blocks. Role-Ref-KV additionally requires bypassing node checks |
| Combining with 3D pose control | CharRef-LLLite with v2 or pilot. v2 occasionally shifted footwear. Role-Ref-KV cannot be combined out of the box with the distributed nodes |
References
- ComfyUI-Anima-Ref-Adapter (GitHub)
- anima-ref-adapter (Hugging Face)
- Anima-Role-Ref-KV (Hugging Face)
- Anima-Role-Ref-KV Demo (Hugging Face Space)
- ComfyUI-Anima-CharRef-LLLite (GitHub)
- Anima_ControlNet-LLLite (Hugging Face)
- Anima (Hugging Face)
- Anima-2.9B (Hugging Face)
- anima29b-turbo-unofficial (Hugging Face)
- Testing the Base-only Anima Ref Adapter on Turbo, Aesthetic, and 2.9B
- Does Existing Character LoRA Run Directly on 40-Layer Anima-2.9B?